Qwen 4 vs Gemini 4 Carbon, GPT-6 Astra, and Claude Fable 5.2: What You Can Actually Compare Today
15 Nov preview comparison. Update 16 Nov 2026: Qwen4-Max is GA with public PAYG and a SandBase card. See the new comparison.
Update (16 Nov 2026): Qwen4-Max is officially generally available with pay-as-you-go, and it is live on SandBase as
alibaba/qwen4-max. This page keeps the 15 November preview comparison. The current four-way comparison, now that a public price exists, is Qwen4-Max vs Gemini 4 Carbon, GPT-6 Astra, and Claude Fable 5.2. How to call the GA model is Qwen4-Max Is Generally Available. The Qwen switch is Qwen4-Max vs Qwen3.8 Max.
“Qwen 4 vs Gemini 4 Carbon vs GPT-6 Astra vs Claude Fable 5.2” is a search, not a ranking. On the evening of 15 November 2026, Asia/Shanghai, the only official Qwen 4 product in the docs was Qwen4-Max-Preview (qwen4-max-preview): Token Plan only, no public pay-as-you-go price yet, and scheduled to be retired after 24:00 on 25 November 2026 (UTC+8). The three flagships you could already call were Gemini 4 Carbon, GPT-6 Astra, and Claude Fable 5.2. That evening, a Qwen job opened Qwen3.8 Max. As of 16 November, a Qwen flagship job opens alibaba/qwen4-max.
The wider record of what Alibaba has and has not published is Is Qwen 4 Out?. This page fills only the columns that survive a side-by-side: access, context, output limits, and price, each labeled with its source. It does not invent a score for the empty Qwen4 cell.
Key takeaway
- Update, 16 Nov 2026: Qwen4-Max has a public pay-as-you-go price and a SandBase card at
alibaba/qwen4-max. This is still not a “who is smarter” ranking. The 15 November check of Qwen4-Max-Preview found no benchmark table and no public unit price, and SandBase had no Qwen4 card that evening.- Compare access and limits. The preview is Token Plan only until 24:00 on 25 November 2026 (UTC+8), then scheduled to retire. Carbon, Astra, and Fable 5.2 have generally available APIs and live SandBase cards.
- Do not flatten context. Official Qwen4 is 1,000,000 / 393,216 (thinking plus answer). Official Carbon is a unified 1,048,576 window, with a 65,536 single-segment streaming cap and a long-decode path. Official Astra is 1,050,000 context and 128,000 max output; the SandBase card prints 1.1M / 128K. Official Fable 5.2 and the SandBase card agree on 1M / 128K.
- Price has to stay split by source. Google’s Global intro is $2 / $10 (cache read $0.10) through 30 November 2026, then $4 / $20. The SandBase Carbon hero already shows $4 / $20 and cache read $0.20. Astra’s card is $9 / $45, 10% off the official $10 / $50 list. Fable 5.2 is $8 / $40 on both the official list and the SandBase hero.
- As of 16 November 2026 the Qwen flagship to call is
alibaba/qwen4-max. Qwen3.8 Max remains $1.80 / $5.40 (10% off $2 / $6), cache read $0.23 and cache write $2.25. Route:POST https://api.sandbase.ai/v1/chat/completions. Astra also listsPOST https://api.sandbase.ai/v1/responses.
What is actually out
Qwen4-Max-Preview is out as a preview. The QwenCloud latest-model page names the ID qwen4-max-preview, restricts it to Token Plan, and says pay-as-you-go is not supported. The preview runs from 10:00 on 11 November 2026 to 24:00 on 25 November 2026 (UTC+8). Official text says the model will be retired after the preview ends. Request-shape notes and the Token Plan base URLs live in the 13 November access guide. Whether you should move a Qwen production ID is the separate note Qwen4-Max-Preview vs Qwen3.8 Max.
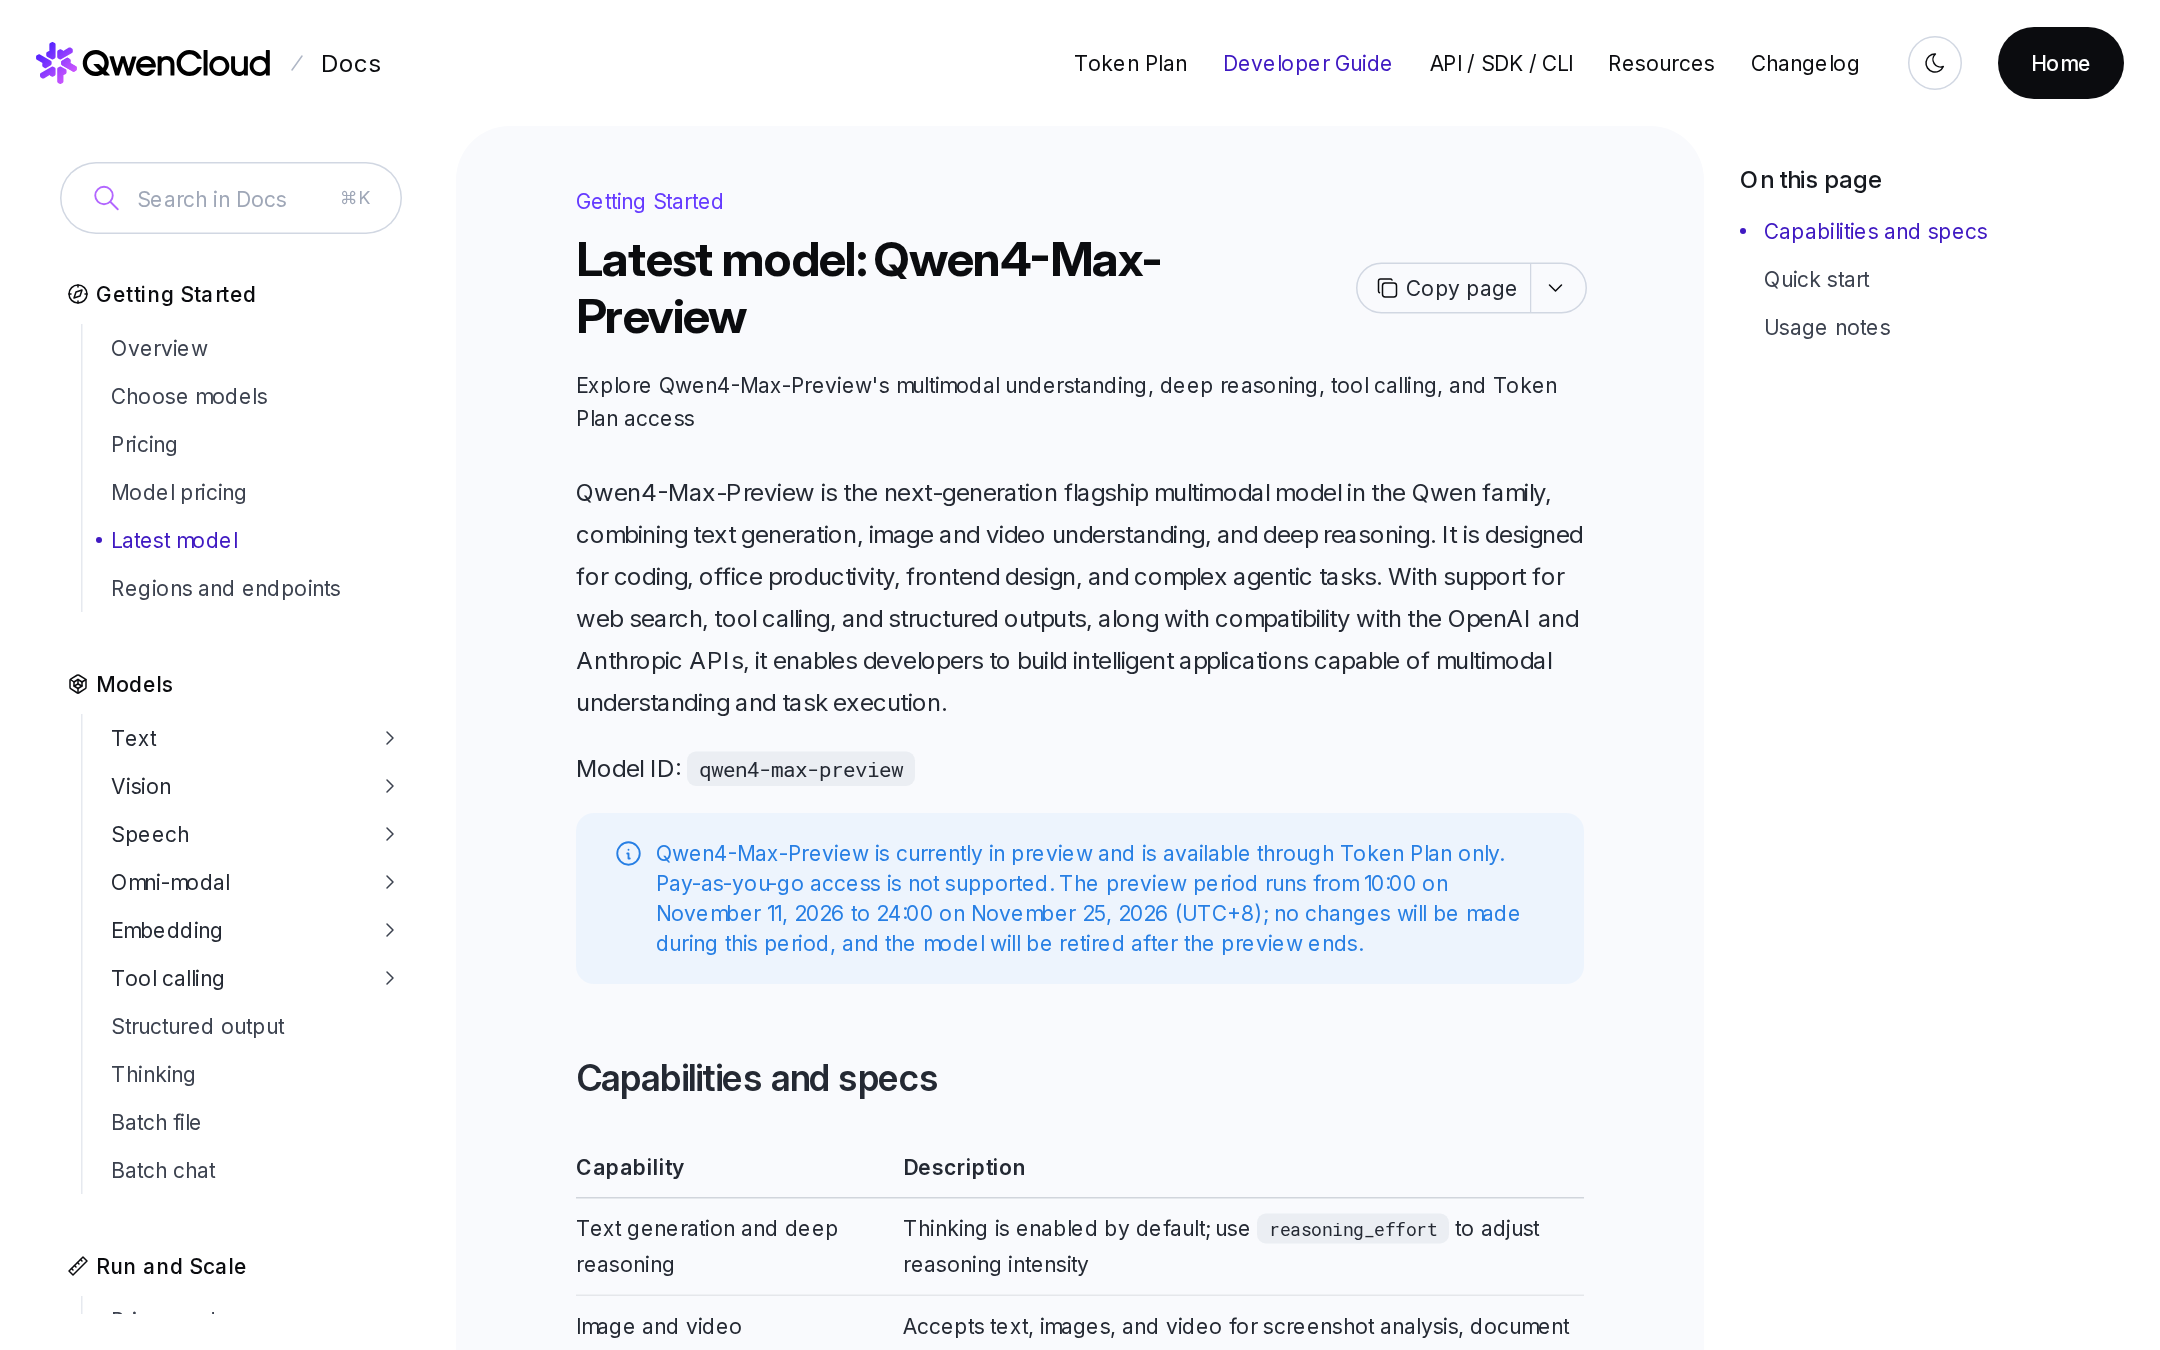
Official QwenCloud latest-model page as of 15 Nov 2026, Asia/Shanghai. It names Qwen4-Max-Preview (qwen4-max-preview), restricts access to Token Plan, and states the preview ends at 24:00 on 25 Nov 2026 (UTC+8), after which the model will be retired.
The other three are past that kind of preview gate.
| Model | What you can call on 15 Nov 2026 | ID to send on SandBase |
|---|---|---|
| Qwen4-Max-Preview | Token Plan preview. Retired after 25 Nov 2026, 24:00 UTC+8, per official text. No SandBase card. | None. Do not invent one. |
| Gemini 4 Carbon | Generally available API. Released 10 Nov 2026. Official ID gemini-4-carbon. SandBase card was live the same evening. | google/gemini-4-carbon |
| GPT-6 Astra | Generally available API. Official ID gpt-6-astra. SandBase card lists POST /v1/responses and POST /v1/chat/completions. | openai/gpt-6-astra |
| Claude Fable 5.2 | Generally available API. Released 9 Nov 2026. Official ID claude-fable-5-2 (hyphens). SandBase card lists chat completions and /v1/messages. | anthropic/claude-fable-5.2 (a dot, not a hyphen, before the 2) |
Send the ID that belongs to the host. Anthropic’s API ID and the SandBase ID are not interchangeable strings. claude-fable-5-2 is the official ID. anthropic/claude-fable-5.2 is the SandBase ID.
Google’s own Gemini 4 Carbon docs describe enterprise-region limits on Google’s Agent Platform surface. That caveat belongs to Google’s docs. It does not mean the SandBase card was down: google/gemini-4-carbon returned a live hero on the 15 November 2026 check. The longer availability note is Gemini 4 Carbon Is Now Available.
Context and output, without a fake 1M row
A single “1M context” row would hide the part a client actually hits: how much of that window can come back as output, and whether thinking shares the budget.
| Model | Context | Max output, with the caveat that matters |
|---|---|---|
| Qwen4-Max-Preview | Official 1,000,000. | Official 393,216, shared by thinking and the final answer. |
| Gemini 4 Carbon | Official unified limit 1,048,576, covering input and output. Output includes thinking, function calls, and the final response. SandBase prints 1M. | A single foreground segment generates up to 65,536 tokens when streaming, or 32,768 non-streaming. Long decodes via continuation_token can extend output up to 1,048,576 minus input. SandBase prints 65.5K, which matches the official single-segment streaming cap. That 65.5K figure is not the official maximum output. |
| GPT-6 Astra | Official 1,050,000 (1.05M). Max input 922,000. SandBase prints 1.1M. | Official and SandBase max output: 128,000 / 128K. Keep the context labels apart. |
| Claude Fable 5.2 | Official and SandBase: 1M. | Official and SandBase: 128K. |
Carbon is the row people mis-quote. The card’s 65.5K is a real label, and it lines up with the streaming segment cap in Google’s docs, updated 13 November 2026 UTC. The same docs allow a longer decode inside the unified window. Quote the card as the card, and quote the long-decode path as official, or you will tell a reader the model stops at 65.5K when the vendor page says otherwise.
Astra’s gap is the other direction. Official context is 1,050,000 tokens. The SandBase hero prints 1.1M. Those strings are not the same number. Max output does agree at 128K.
In this 15 November table, the preview’s 393,216 is the largest official output ceiling, and that preview row was the one you could not buy as pay-as-you-go. A bigger output budget on a retiring preview was not a production default. Qwen3.8 Max is a different row: official max output 128k, SandBase card 131.1K. That pair is spelled out in the Qwen3.8 Max comparison. The 16 November GA caps are 131,072 and 262,144, on qwen4-max, and they are not this table.
Price, with the source sitting next to the number
On the 15 November 2026 check there was no public Qwen4 pay-as-you-go unit price. Credits on Token Plan, as low as 20% of an unpublished standard rate, are not a dollar row, so they are not in the table below. The 16 November GA price belongs to qwen4-max and is not copied into this preview table.
| Model | Official price, 15 Nov 2026 | SandBase hero, 15 Nov 2026 |
|---|---|---|
| Qwen4-Max-Preview | No public pay-as-you-go unit price. Token Plan only. | No card. |
| Gemini 4 Carbon | Agent Platform pricing: standard Global $2 / $10 per 1M input/output, cache read $0.10, through 30 Nov 2026. Footnote: promotional pricing via 50% credits back on net spend. From 1 Dec 2026: $4 / $20, cache read $0.20. | $4.00 / $20.00. Cache read $0.20. No cache-write figure on the hero. The card shows the post-intro list while Google’s intro window is still open. |
| GPT-6 Astra | OpenAI pricing and the GPT-6 Astra model page: $10 / $50 per 1M. Cached input $1. Cache writes $12.50. Prompts above 272K input tokens are priced at 2x input and cache, and 1.5x output, for the whole request. Batch and Flex are 50% off. Fast mode is 2x. | $9 / $45, 10% off the $10 / $50 list. Cache read $0.90 (list $1.00). Cache write $11.25 (list $12.50). |
| Claude Fable 5.2 | Fable 5.2 overview and Anthropic pricing: $8 / $40. Cache read $0.20. 5-minute cache write $10. 1-hour cache write $16. Batch 50% off. Fast mode $16 / $80. | $8 / $40. Cache read $0.20. Cache write $10.00, which matches the official 5-minute rate. The official 1-hour $16 is not printed on the card. Do not quote $16 as a SandBase price. |
As of 16 November 2026, a callable Qwen4-Max unit price exists on Qwen4 Max. In this 15 November table the callable Qwen price is still Qwen3.8 Max at $1.80 / $5.40 per 1M, 10% off the $2 / $6 list, with cache read $0.23 and cache write $2.25. That discount is the Qwen3.8 Max hero. It is not a Qwen4-Max price.
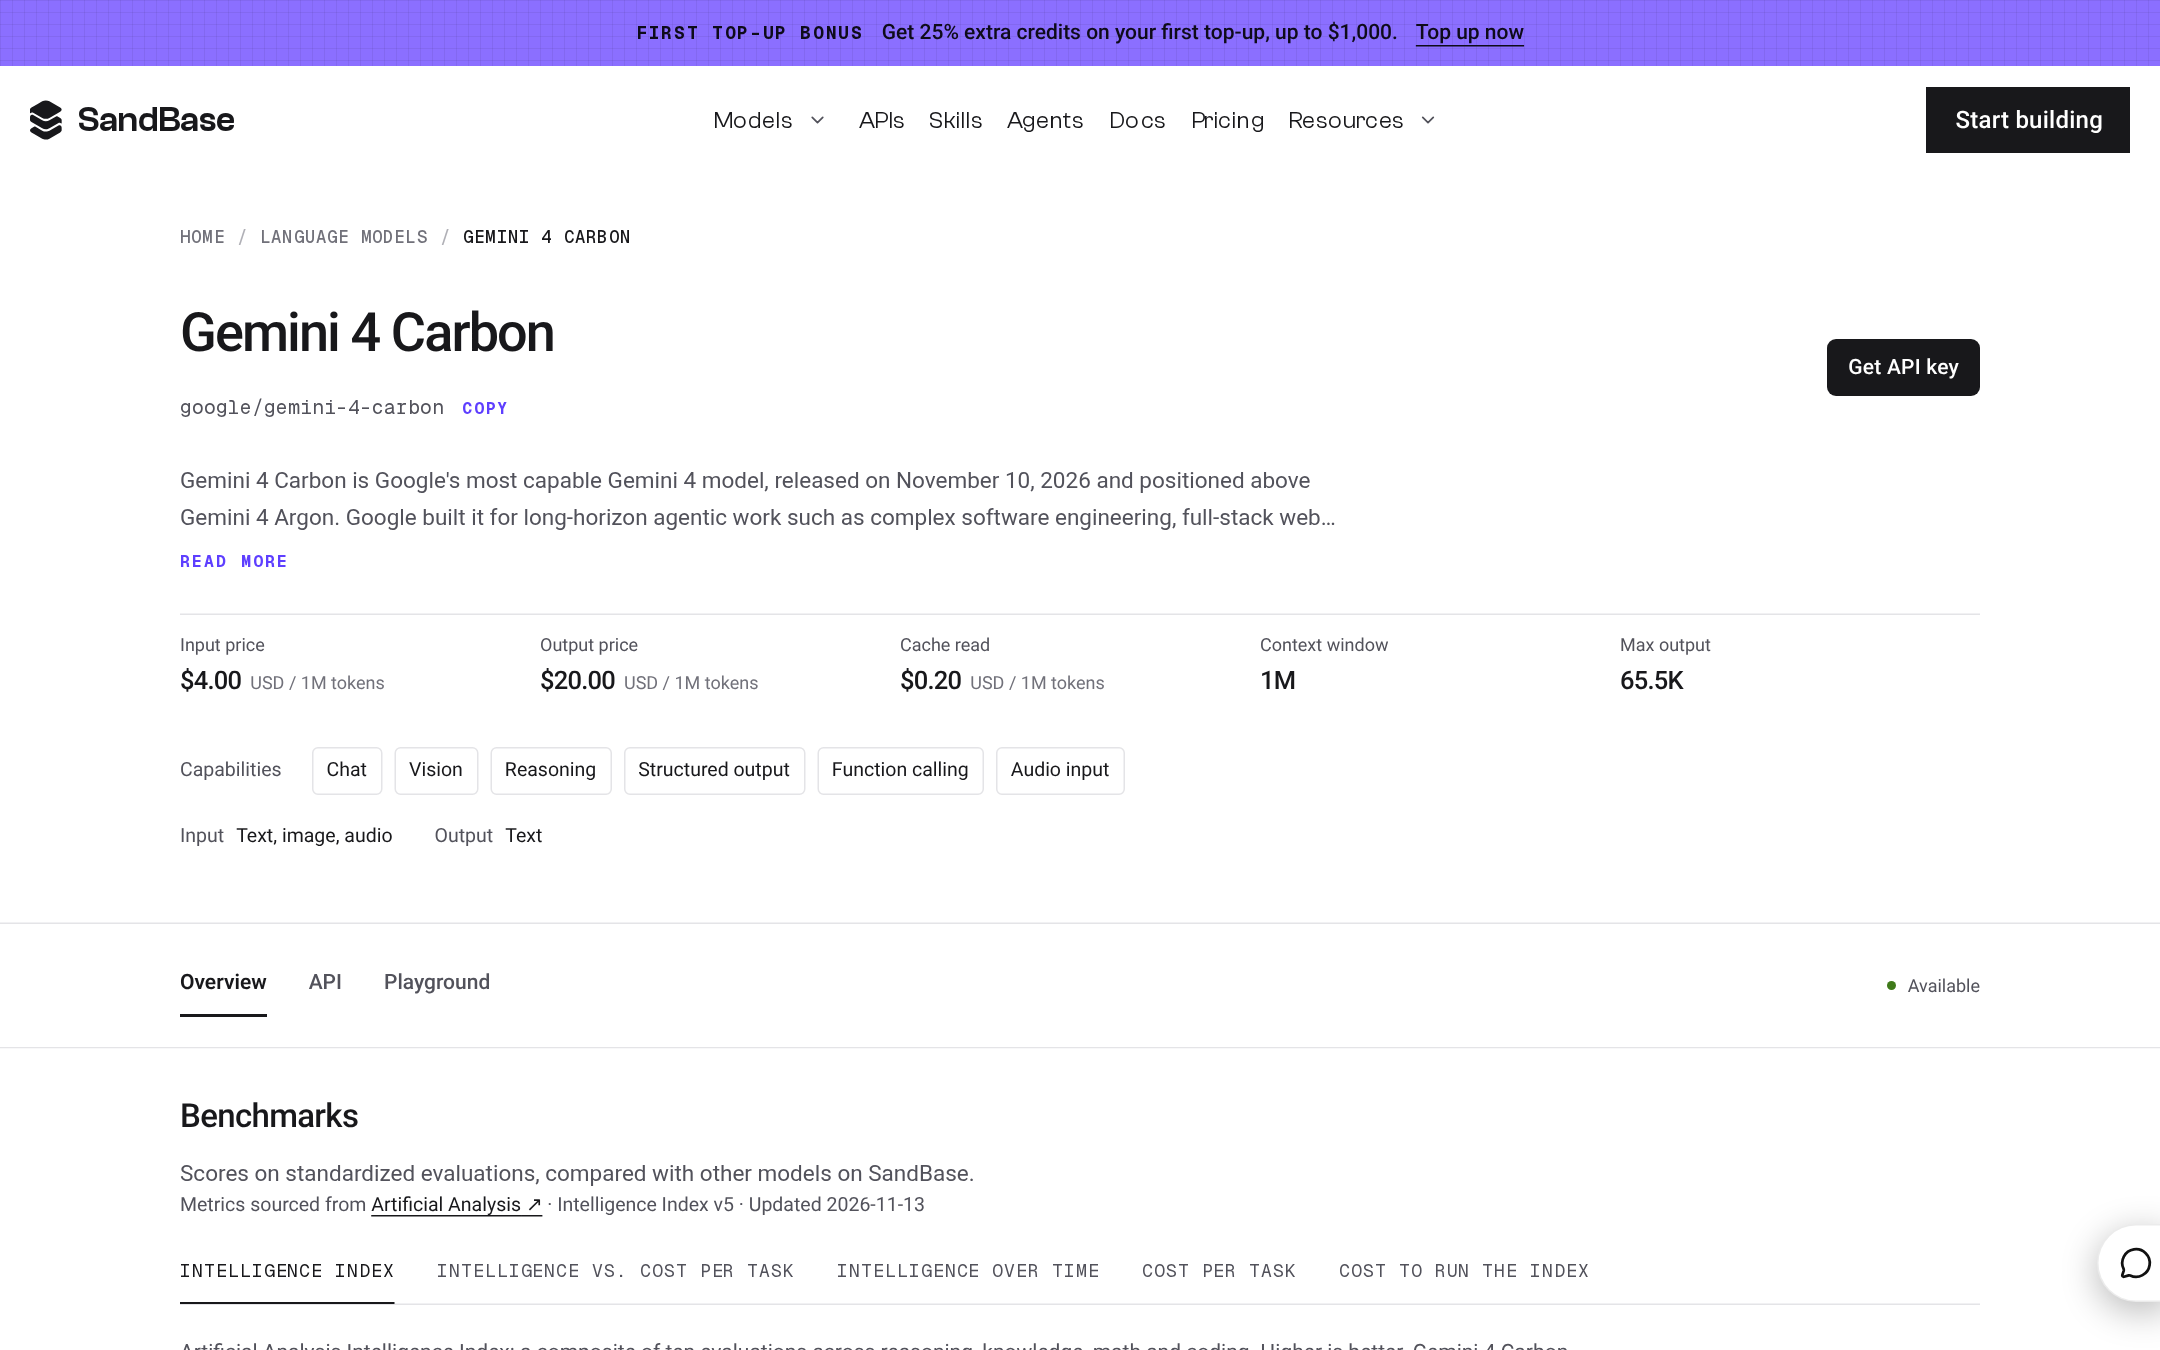
Live SandBase Gemini 4 Carbon card at /models/google/gemini-4-carbon, captured 15 Nov 2026, Asia/Shanghai. The hero is $4.00 / $20.00 with cache read $0.20, 1M context, and 65.5K max output. Official Google Global intro pricing is still $2 / $10 (cache read $0.10) through 30 Nov 2026, then $4 / $20; the card currently shows the post-intro list. Official docs also allow long-decode output up to the unified 1,048,576-token window; the 65.5K figure matches the official single-segment streaming cap.
The Carbon hero is what a SandBase call bills on this check. Google’s $2 / $10 intro, through 30 November 2026, is a vendor price on Google’s pricing page, including the credits-back footnote. Quote the bill you will actually receive. A reader who copies $2 / $10 into a SandBase budget is using the wrong surface.
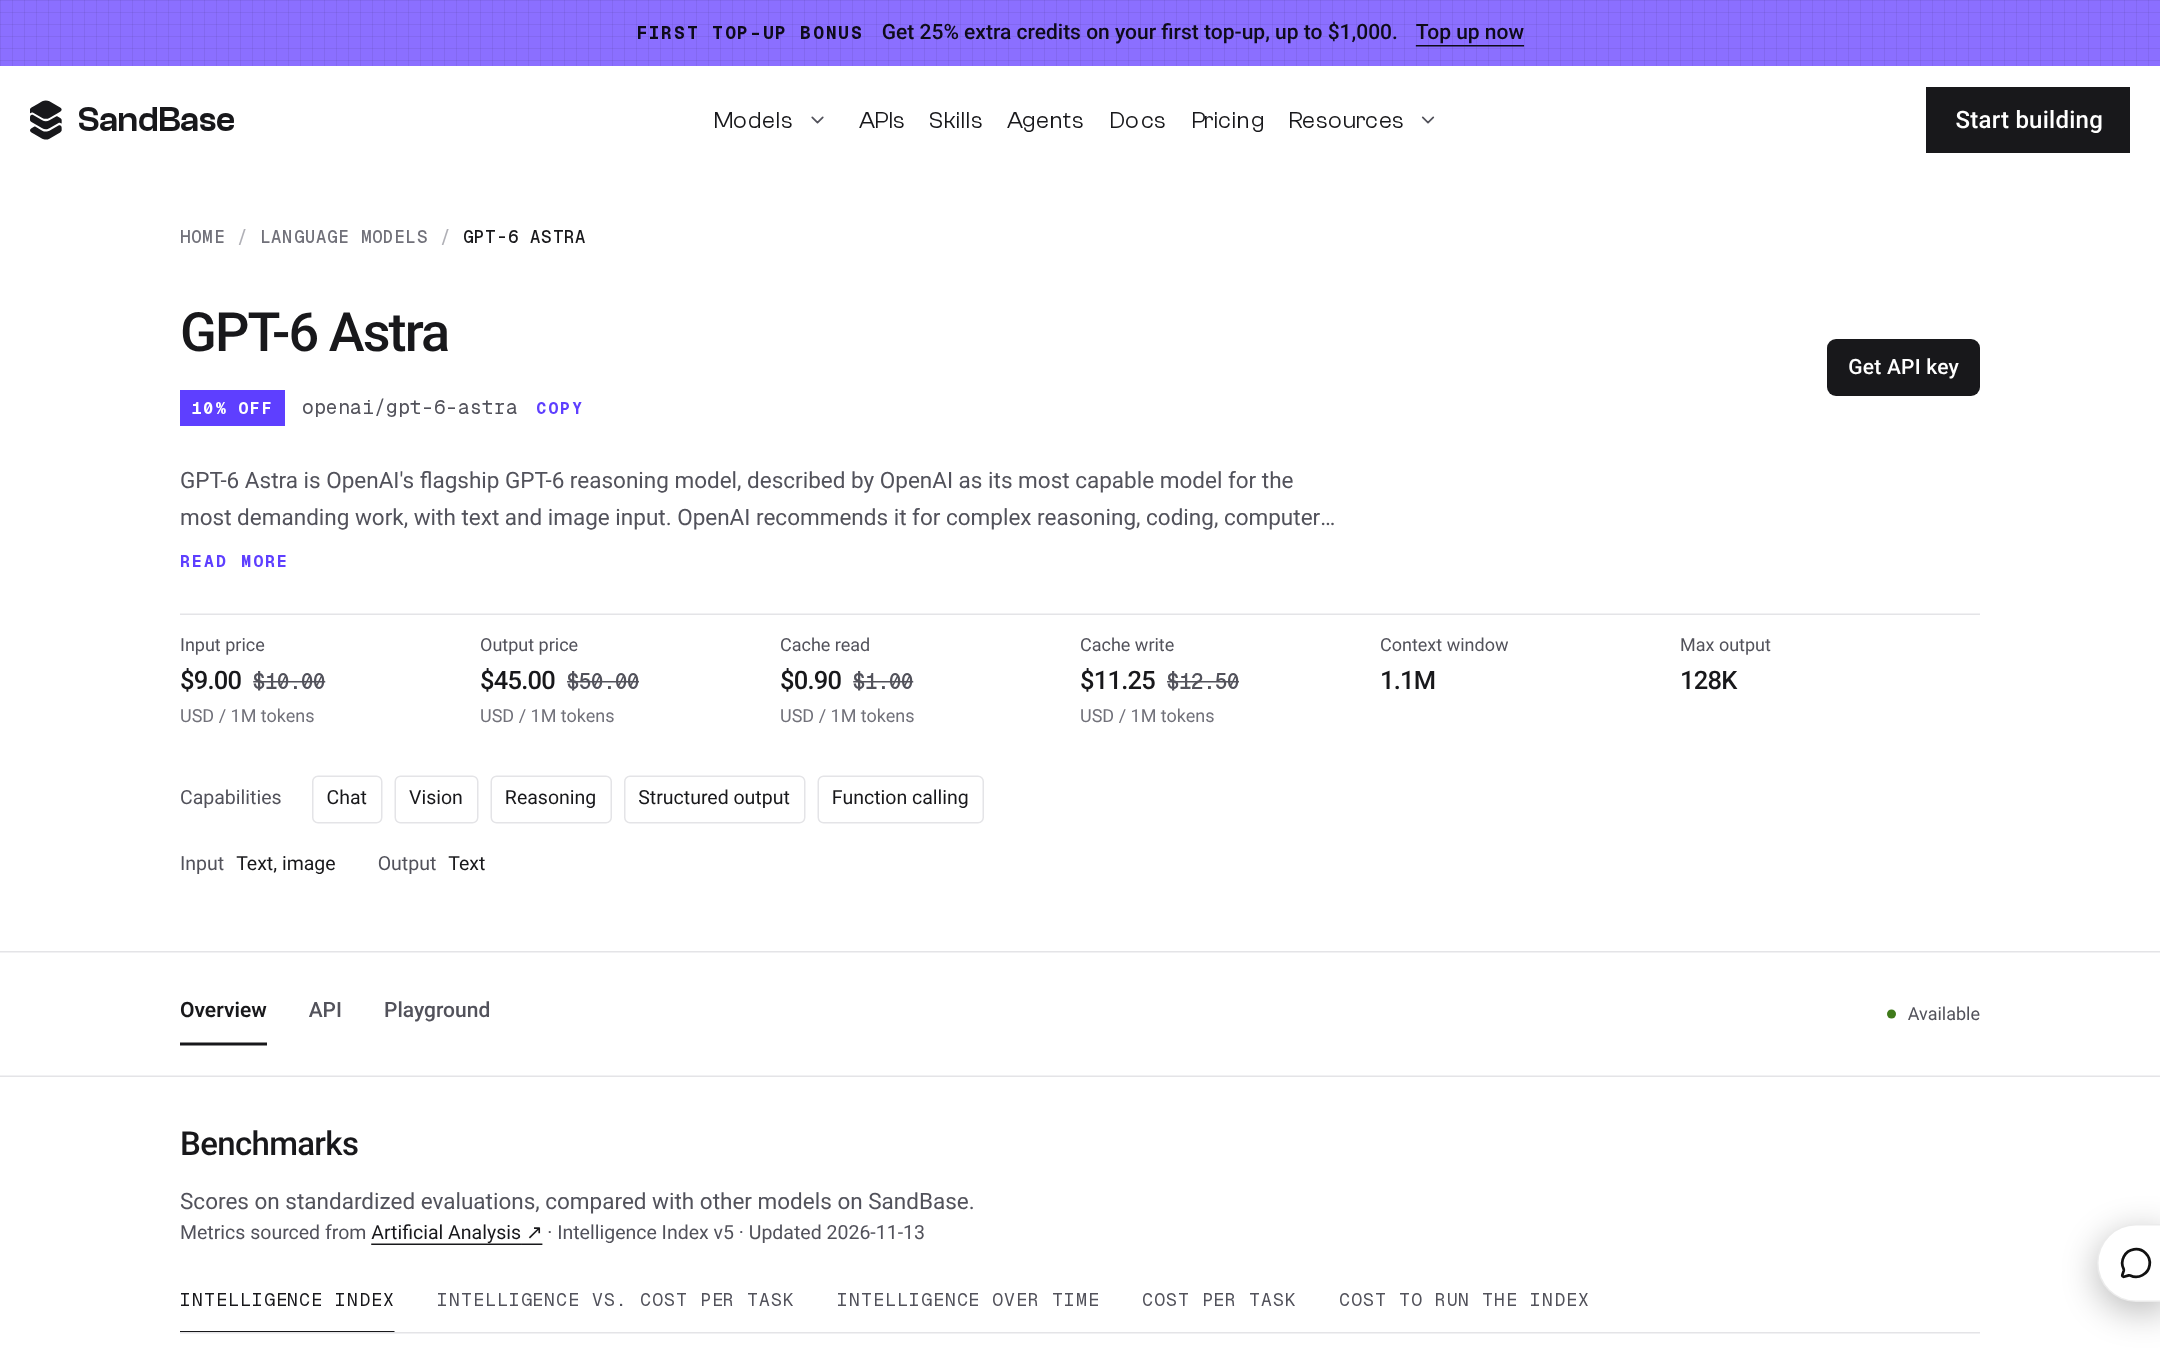
Live SandBase GPT-6 Astra card at /models/openai/gpt-6-astra, captured 15 Nov 2026, Asia/Shanghai. Hero is $9 / $45 (10% off the official $10 / $50 list), with cache read $0.90 and cache write $11.25 per 1M tokens. The card prints a 1.1M context window; official OpenAI docs list 1.05M context and 128K max output.
Astra’s 10% is on this card, the same way Qwen3.8 Max’s 10% is on that card. The long-context multiplier is official and separate: above 272K input tokens, OpenAI prices the full request at 2x input and cache and 1.5x output. The SandBase hero does not replace that vendor rule. Confirm it on the host you call before you budget a long prompt.
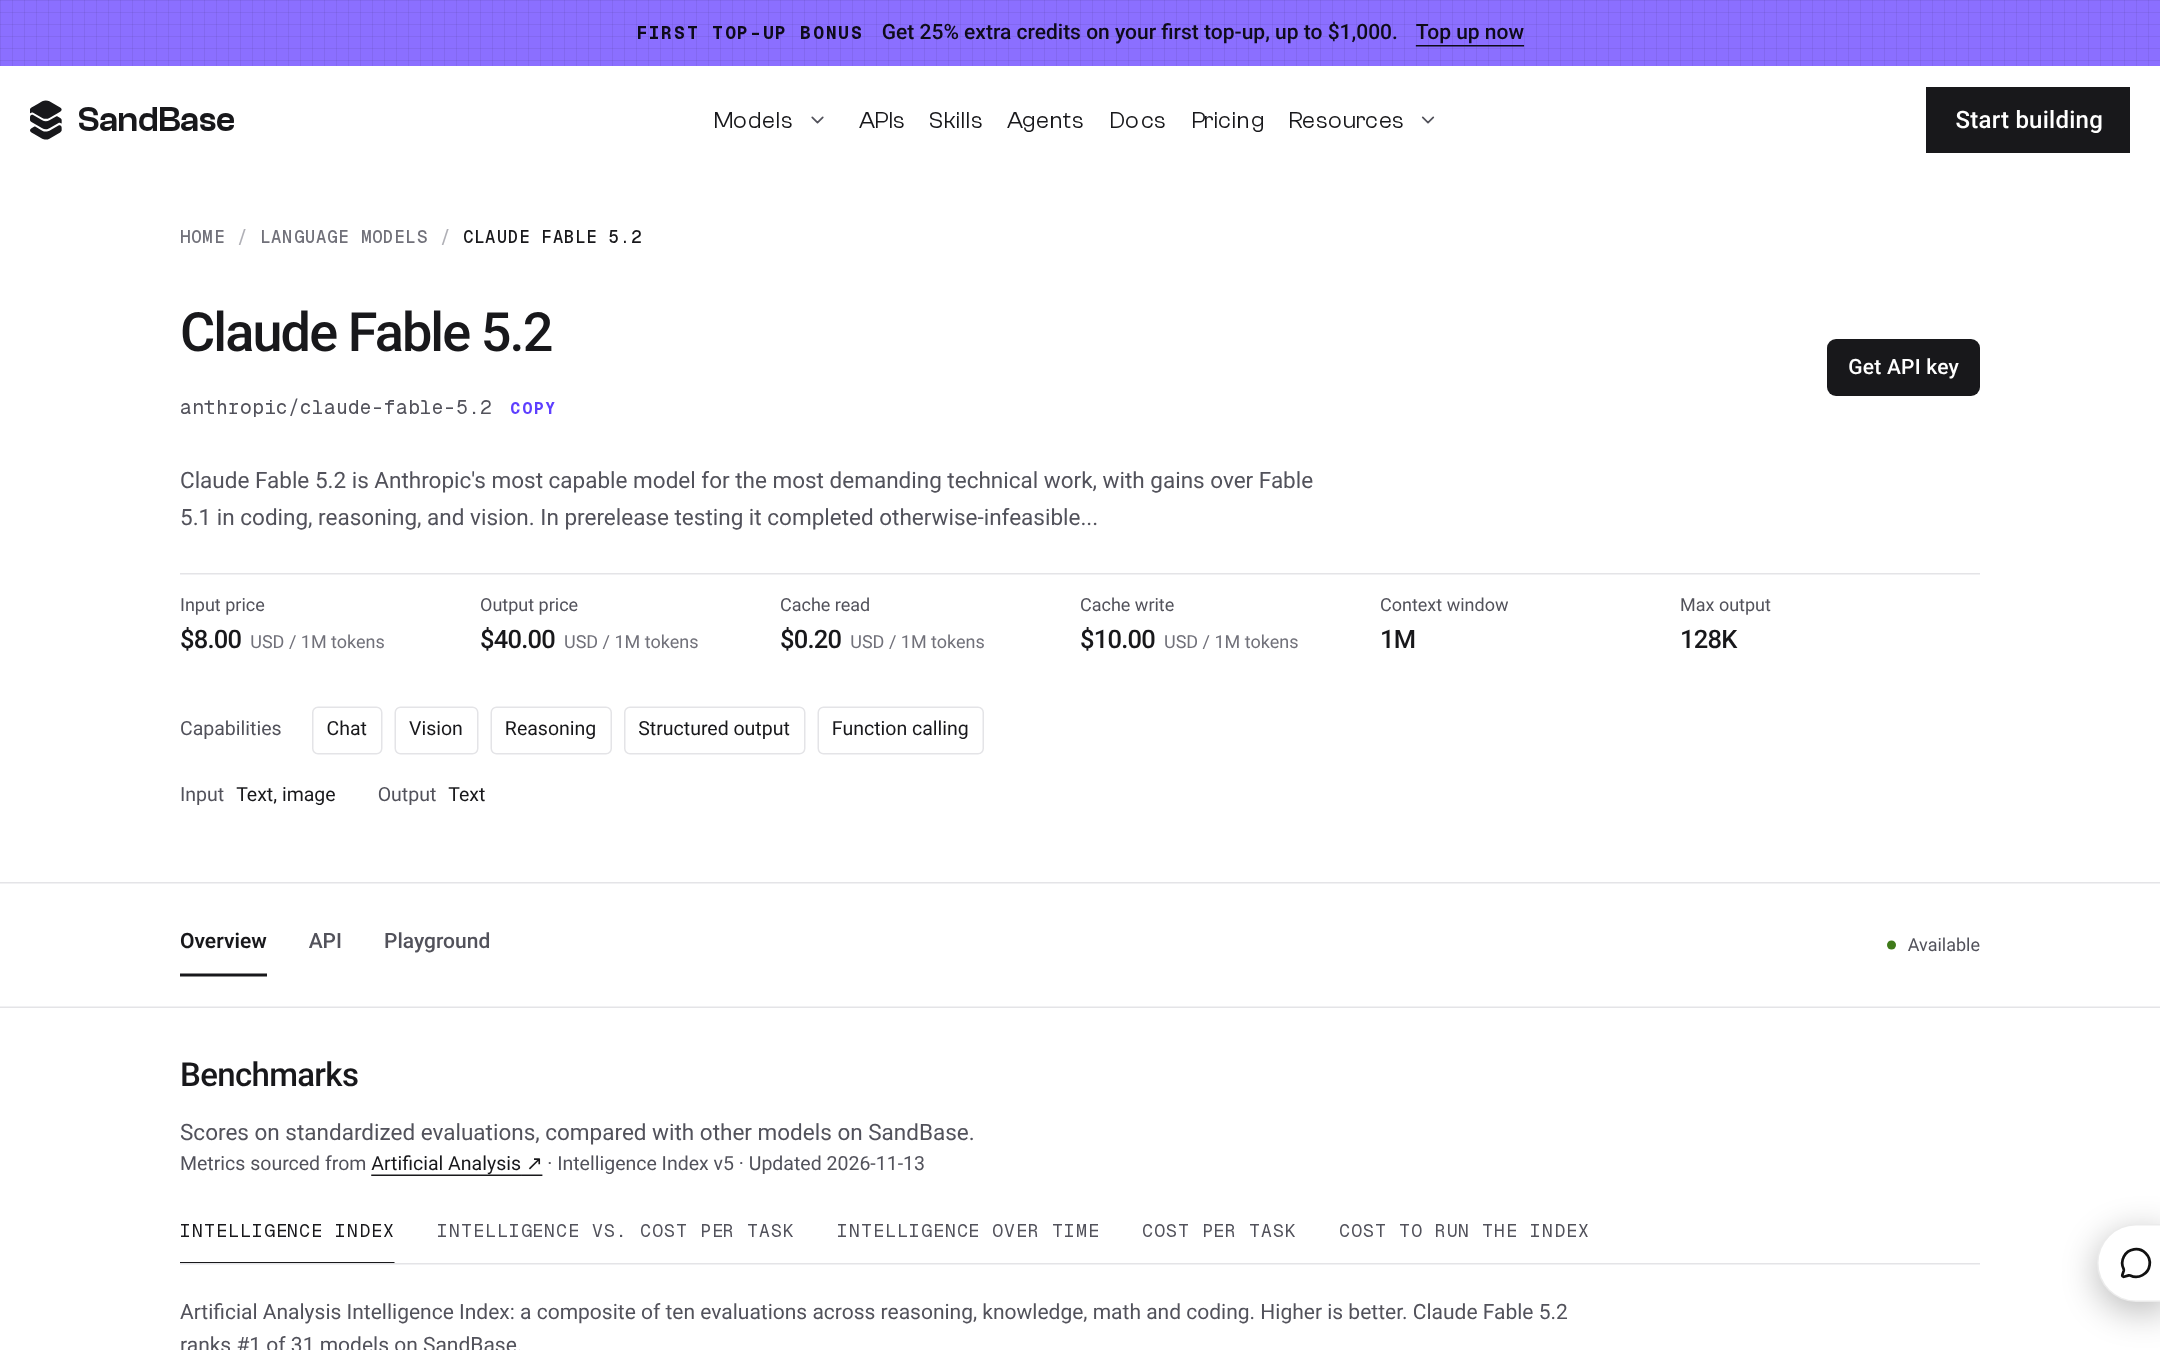
Live SandBase Claude Fable 5.2 card at /models/anthropic/claude-fable-5.2, captured 15 Nov 2026, Asia/Shanghai. Hero is $8 / $40, with cache read $0.20 and cache write $10.00 per 1M tokens, 1M context, and 128K max output. The cache-write figure matches the official 5-minute cache-write rate; official Anthropic docs also list a 1-hour cache write at $16, which is not printed on this card.
Fable 5.2 is the row where list price and the SandBase hero match at $8 / $40, and where the cache-write line is easy to over-read. $10 on the card is the official 5-minute write. $16 is the official 1-hour write, and it is not a SandBase hero number. Fast mode at $16 / $80 is official, not a figure on this hero.
Modalities, only where a page actually says so
Official Qwen4-Max-Preview docs describe text generation plus image and video understanding. They do not claim audio input. Official Gemini 4 Carbon docs include text, image, audio, and video input. The SandBase Carbon card lists audio input among its capabilities. Official GPT-6 Astra input is text and image. Official Claude Fable 5.2 input is text and images, with text output, and the overview lists a knowledge cutoff of June 2026. That cutoff is an Anthropic docs field, not a number read off the SandBase hero.
Do not add audio to Qwen4 or to Astra to make the grid look even. A job that needs audio input on a Qwen you can call today is Qwen3.8 Omni Flash, covered in which Qwen to call today.
What you still cannot compare
Official Qwen4 benchmark scores. A public Qwen4 unit price. A parameter count. Open weights. Whether a later GA model keeps the preview ID. Qwen4-Plus, Qwen4-Flash, and Qwen4-27B, which are reported names and not rows in the 11 November changelog.
Third-party leaderboards are not a stand-in. This verdict does not paste them. Score tables that already exist for models you can call are in other notes: Gemini 4 Carbon vs Argon, Astra, and Opus and Fable 5.2 vs Opus 5.5 and GPT-6 Astra. The Fable release writeup is Claude Fable 5.2 Is Out. A call-shaped Carbon note is Gemini 4 Carbon on SandBase.
What to call today
Open Qwen4 Max when you wanted a Qwen flagship after 16 November 2026. ID alibaba/qwen4-max. The 15 November Qwen in this comparison was Qwen3.8 Max: hero $1.80 / $5.40 per 1M, 10% off $2 / $6, cache read $0.23, cache write $2.25, 1M context, 131.1K max output on the card, 128k in official Alibaba docs. ID alibaba/qwen3.8-max. Endpoint POST https://api.sandbase.ai/v1/chat/completions.
Open Gemini 4 Carbon when you want the long-horizon card that is actually listed. Budget the SandBase hero at $4 / $20 and cache read $0.20, and keep Google’s $2 / $10 intro (cache read $0.10 through 30 November 2026, then $4 / $20) as the vendor price, not as the SandBase sticker. ID google/gemini-4-carbon.
Open Claude Fable 5.2 when you want the $8 / $40 flagship whose hero matches the official list price. Cache read on the card is $0.20. Cache write on the card is $10, the official 5-minute rate. Remember the official 1-hour write is $16 and is not on the card. SandBase ID anthropic/claude-fable-5.2. Official ID claude-fable-5-2.
Open GPT-6 Astra when the job is the OpenAI flagship. Hero $9 / $45, 10% off $10 / $50, cache read $0.90, cache write $11.25. The card prints 1.1M context; official docs say 1.05M and 128K max output. SandBase lists both POST https://api.sandbase.ai/v1/responses and POST https://api.sandbase.ai/v1/chat/completions.
Sign up, then use the first API call doc. Vendor hubs for the three live flagships: Google, OpenAI, and Anthropic. The Qwen hub still describes Qwen3.8 and earlier.
FAQ
Can I rank Qwen 4 against Carbon, Astra, and Fable 5.2 today?
You can rank access, context, output rules, and price, with the source on each number. You cannot rank official benchmark scores. The Qwen4-Max-Preview pages checked on 15 November 2026 do not include a benchmark table, and this note does not borrow a third-party one.
Why does SandBase show $4 / $20 for Gemini 4 Carbon during Google’s intro?
The 15 November 2026 SandBase hero shows the post-intro list: $4 / $20 and cache read $0.20. Google’s Agent Platform pricing still lists $2 / $10 and cache read $0.10 through 30 November 2026, then $4 / $20 from 1 December 2026. The intro footnote describes promotional pricing via 50% credits back on net spend. Use the price of the surface you will call.
Is Astra’s context 1.05M or 1.1M?
Official OpenAI docs say 1,050,000 tokens (1.05M), with max output 128,000. The SandBase card prints 1.1M context and 128K max output. Quote the label from the host you call.
Which Fable 5.2 ID do I send?
On Anthropic’s API, claude-fable-5-2. On SandBase, anthropic/claude-fable-5.2. The punctuation is part of the ID.
What Qwen can I call on SandBase while the preview is up?
As of 16 November 2026, Qwen4 Max at alibaba/qwen4-max. Qwen3.8 Max remains the 10% off baseline from the table above. Routing among Max, 27B, and Omni Flash, with the 16 November update on top, is which Qwen to call today.
Sources
Checked 15 November 2026, Asia/Shanghai. Qwen preview: QwenCloud latest-model, text generation table, Token Plan updates. Carbon: Agent Platform pricing and Gemini 4 Carbon docs (docs updated 2026-11-13 UTC). Astra: OpenAI pricing and the GPT-6 Astra model page. Fable 5.2: overview and Anthropic pricing. SandBase heroes linked above are from the same evening’s card check.
The status post is the preview record. The access guide is the Token Plan how-to. Sibling score notes stay linked above and are not copied here.
Prices and windows checked 15 November 2026, Asia/Shanghai. Vendor pages for official list prices and output rules. SandBase heroes for the sticker a call on SandBase uses.
Found this useful? Share it