Qwen4-Max vs Qwen3.8 Max: Should You Switch Production Traffic?
Start new production on Qwen4-Max (SandBase $1.67 / $5.00). Keep Qwen3.8 Max ($1.80 / $5.40, 10% off) when you need that baseline.
Start new production on Qwen4-Max. Keep Qwen3.8 Max when the account is already standardized on it, or when you want that card’s 10% off and you have not re-validated agents against a new default effort. Both models are generally available. Qwen4-Max became generally available on 16 November 2026, with a public pay-as-you-go price and a live SandBase card. Official docs now recommend qwen4-max when you are prioritizing quality, and they list qwen3.8-max under older models.
How to call the new ID, including the output caps and the price gap versus Alibaba’s own list, is Qwen4-Max Is Generally Available. The 15 November note, Qwen4-Max-Preview vs Qwen3.8 Max, is the preview-era switch decision and stays that way. The long page for the incumbent is Qwen 3.8 Max: Alibaba’s 2.4T Multimodal Flagship.
Key takeaway
- New production: Qwen4 Max, ID
alibaba/qwen4-max. SandBase hero $1.67 / $5.00, cache read $0.08, cache write $2.08, no 10% off. Official Singapore list is $1.50 / $4.50. Official Beijing and Global list is $1.413 / $4.24.- Keep Qwen3.8 Max as the proven baseline. SandBase hero $1.80 / $5.40, 10% off list $2 / $6, cache read $0.23, cache write $2.25. Official Alibaba max output for
qwen3.8-maxremains 128k. The SandBase hero prints 131.1K.- Official context is 1,000,000 on both. Official Qwen4-Max output is 131,072 non-thinking and 262,144 thinking plus the answer. The preview’s 393,216 cap is not the GA limit.
- A 9-task SandBase probe on 16 November 2026 scored both models 8 pass, 1 partial, 0 fail. Qwen4-Max was faster on every task in that set. It is a small practical probe, not a public leaderboard.
- Do not start new production on
qwen4-max-preview. That preview still retires after 24:00 on 25 November 2026 (UTC+8).
Update (16 Nov 2026): In a same-day SandBase streaming probe (concurrency 1, default thinking, fixed-length decode), Qwen3.8 Max often emitted the first reasoning token earlier, but it thought longer, so the first answer token arrived about 2.2 seconds later than on Qwen4-Max. Qwen4-Max also decoded faster in this sample (median 93.1 vs 54.1 tokens/s). This is a single-box gateway probe, not a capacity test and not an official benchmark; it is separate from the 9-task practical probe below. Full tables and method: Qwen4-Max vs Qwen3.8 Max: Measured TTFT, TPOT, Throughput, and Cache Hit Rate on SandBase.
The side-by-side you can defend
Sources for the official column are the QwenCloud latest-model page, the QwenCloud pricing page, and Alibaba’s text generation and visual understanding table, all checked 16 November 2026. SandBase figures are the live heroes the same afternoon.
| Item | Qwen4-Max | Qwen3.8 Max |
|---|---|---|
| Status | GA as of 16 Nov 2026. First model in the Qwen4 family. | GA. Official text-generation page now lists it under older models. |
| SandBase ID | alibaba/qwen4-max | alibaba/qwen3.8-max |
| Official Singapore list / 1M | $1.50 / $4.50 | $2 / $6 |
| Official Beijing / Global | $1.413 / $4.24 | Not restated here. The Singapore list above is the one re-confirmed for this comparison. |
| SandBase hero / 1M | $1.67 / $5.00. No 10% off. | $1.80 / $5.40, 10% off list $2 / $6. |
| SandBase cache read / write | $0.08 / $2.08 | $0.23 / $2.25 (list $0.25 / $2.50) |
| Official context | 1,000,000 | 1,000,000 |
| Official max output | 131,072 non-thinking; 262,144 thinking + answer | 128k |
| SandBase context / max output | 1M / 131.1K | 1M / 131.1K |
| Thinking default | On. reasoning_effort default high. | Unchanged on this check. Do not copy the new Qwen4 default onto an old client without a re-test. |
| Modalities | Official: text, image, video in; text out. Card lists vision. | Official table: text, image, video. Card lists vision, plus chat, reasoning, structured output, and function calling. |
| Batch | Official model pages: not supported. | Not claimed as a reason to stay. |
Two output labels for Qwen3.8 Max stay in separate cells. Alibaba prints 128k. The SandBase hero prints 131.1K. A client should follow the limit of the surface it calls.
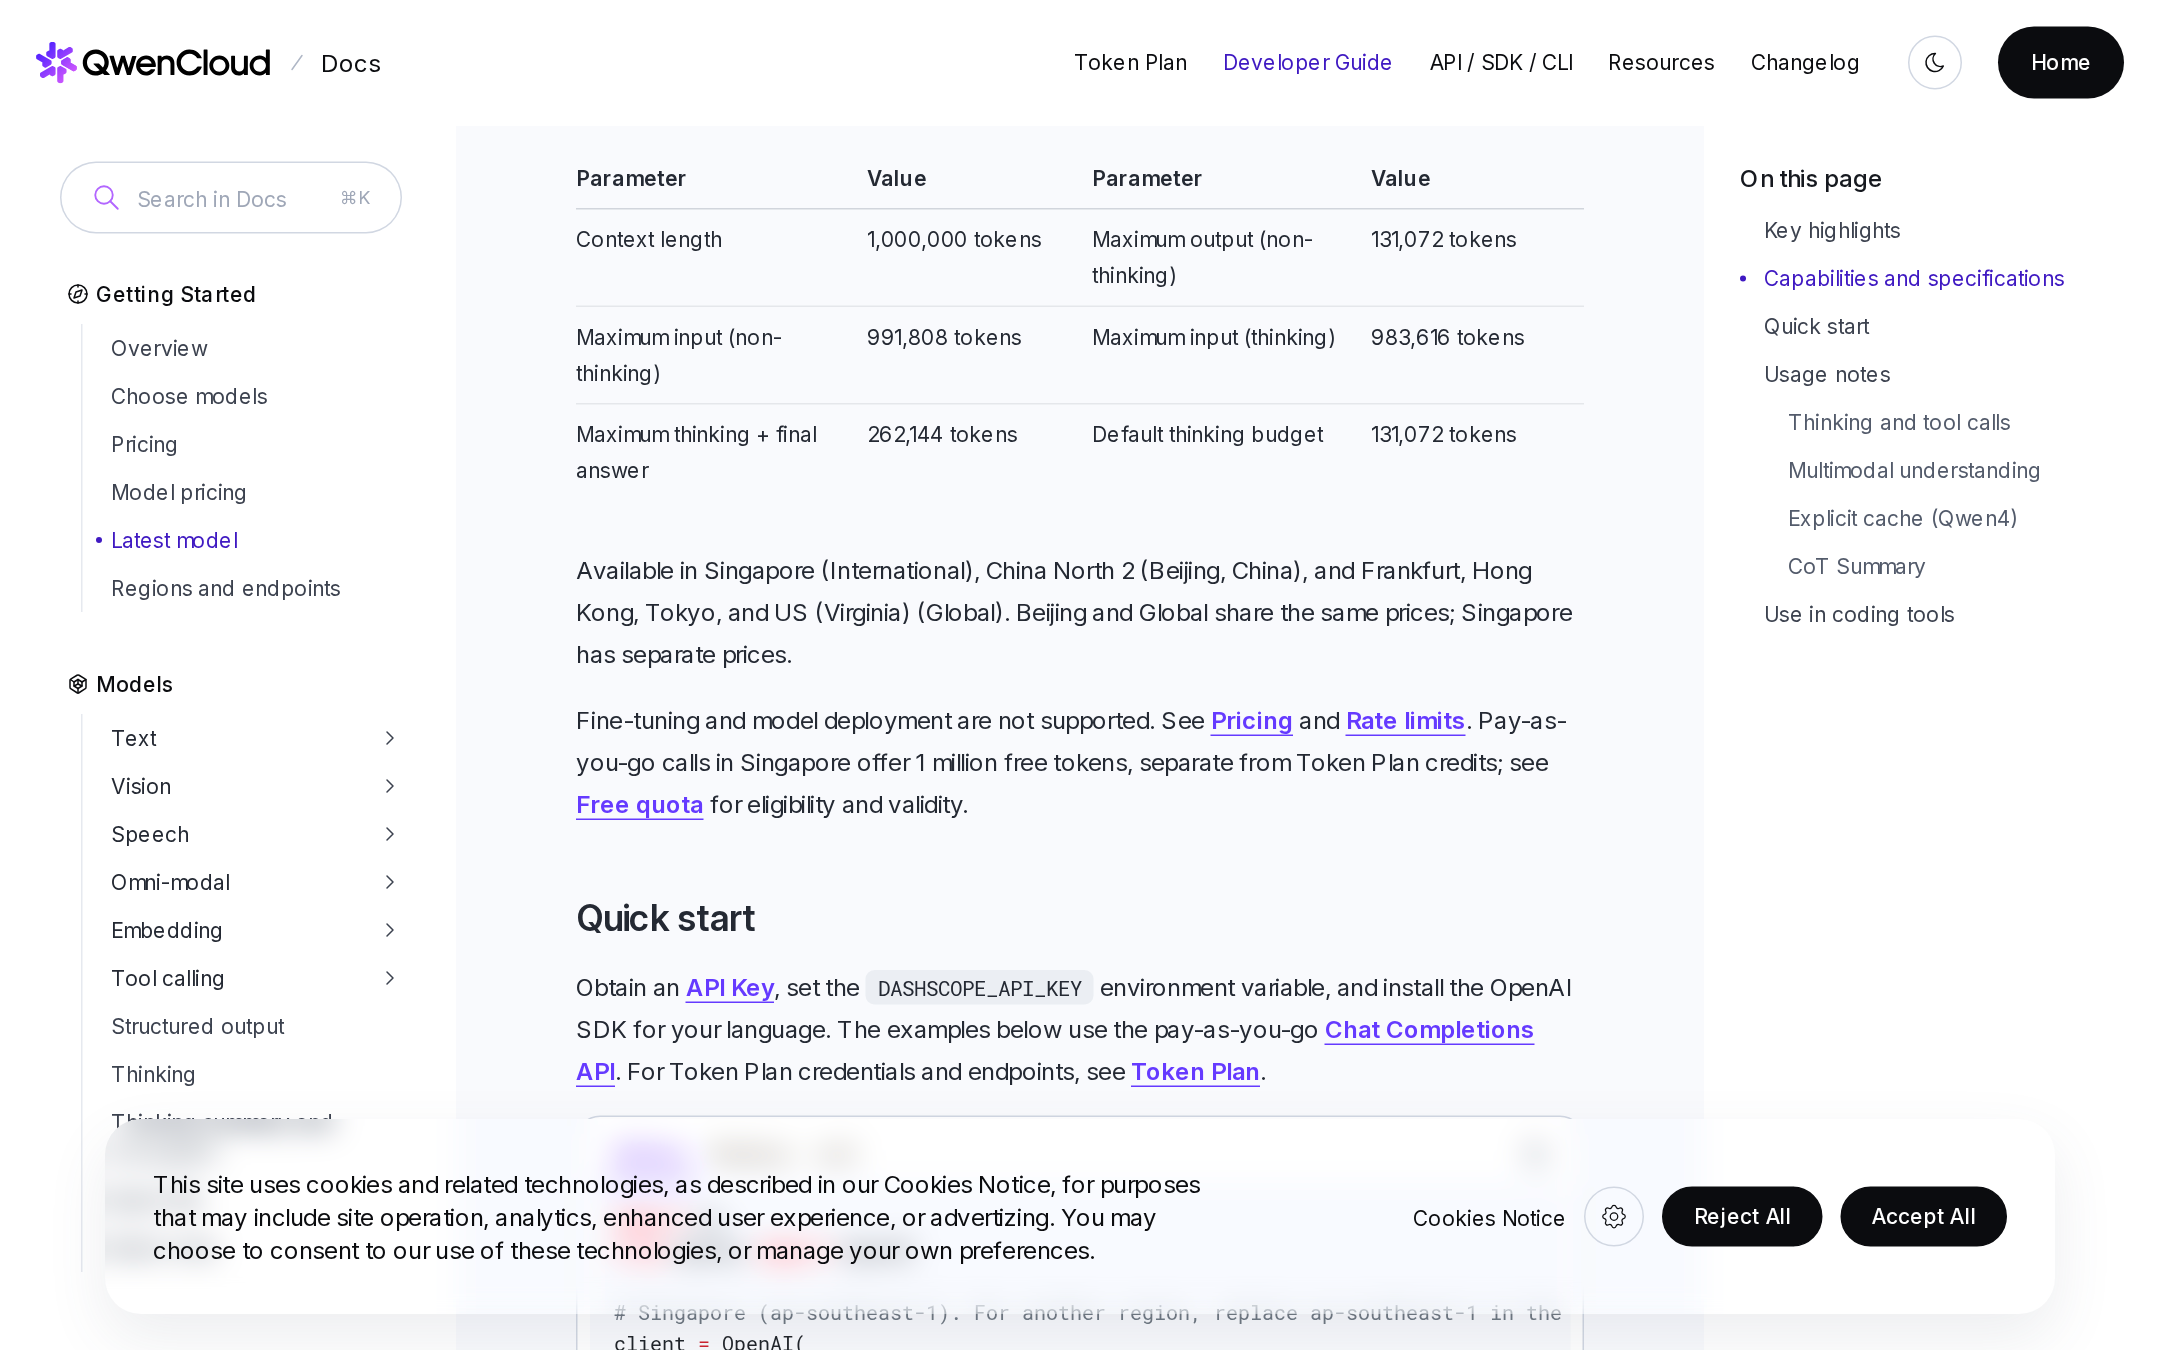
Official QwenCloud latest-model page as of 16 Nov 2026, Asia/Shanghai. Official GA limits are 1,000,000 context, 131,072 maximum output (non-thinking), and 262,144 maximum combined thinking plus final answer. The same page states that fine-tuning and model deployment are not supported, and that pay-as-you-go calls in Singapore offer 1 million free tokens. (A site cookie banner is visible at the bottom of this capture and does not cover the limits table.)
The same afternoon, Alibaba’s text-generation page recommends qwen4-max when you are prioritizing quality, with max output “131,072 (Non-thinking); 262,144 (thinking + output)”, 1M context, 16M max pixels per image, and a 2-hour max video duration. It recommends qwen3.8-flash when you are prioritizing cost, and it lists qwen3.7-plus as a balanced, start-here option. qwen3.8-max sits under “Older models,” still at 1M context and official 128k max output, with the note that these models are no longer the first recommendation. qwen4-max-preview and the 393,216 cap are gone from that table. That is an official recommendation. It is not a SandBase ranking, and it is not a reason to invent Qwen4-Plus, Qwen4-Flash, or Qwen4-27B cards. A screenshot of that table was not usable on 16 November; the figures above are from the page text.
What the cards charge
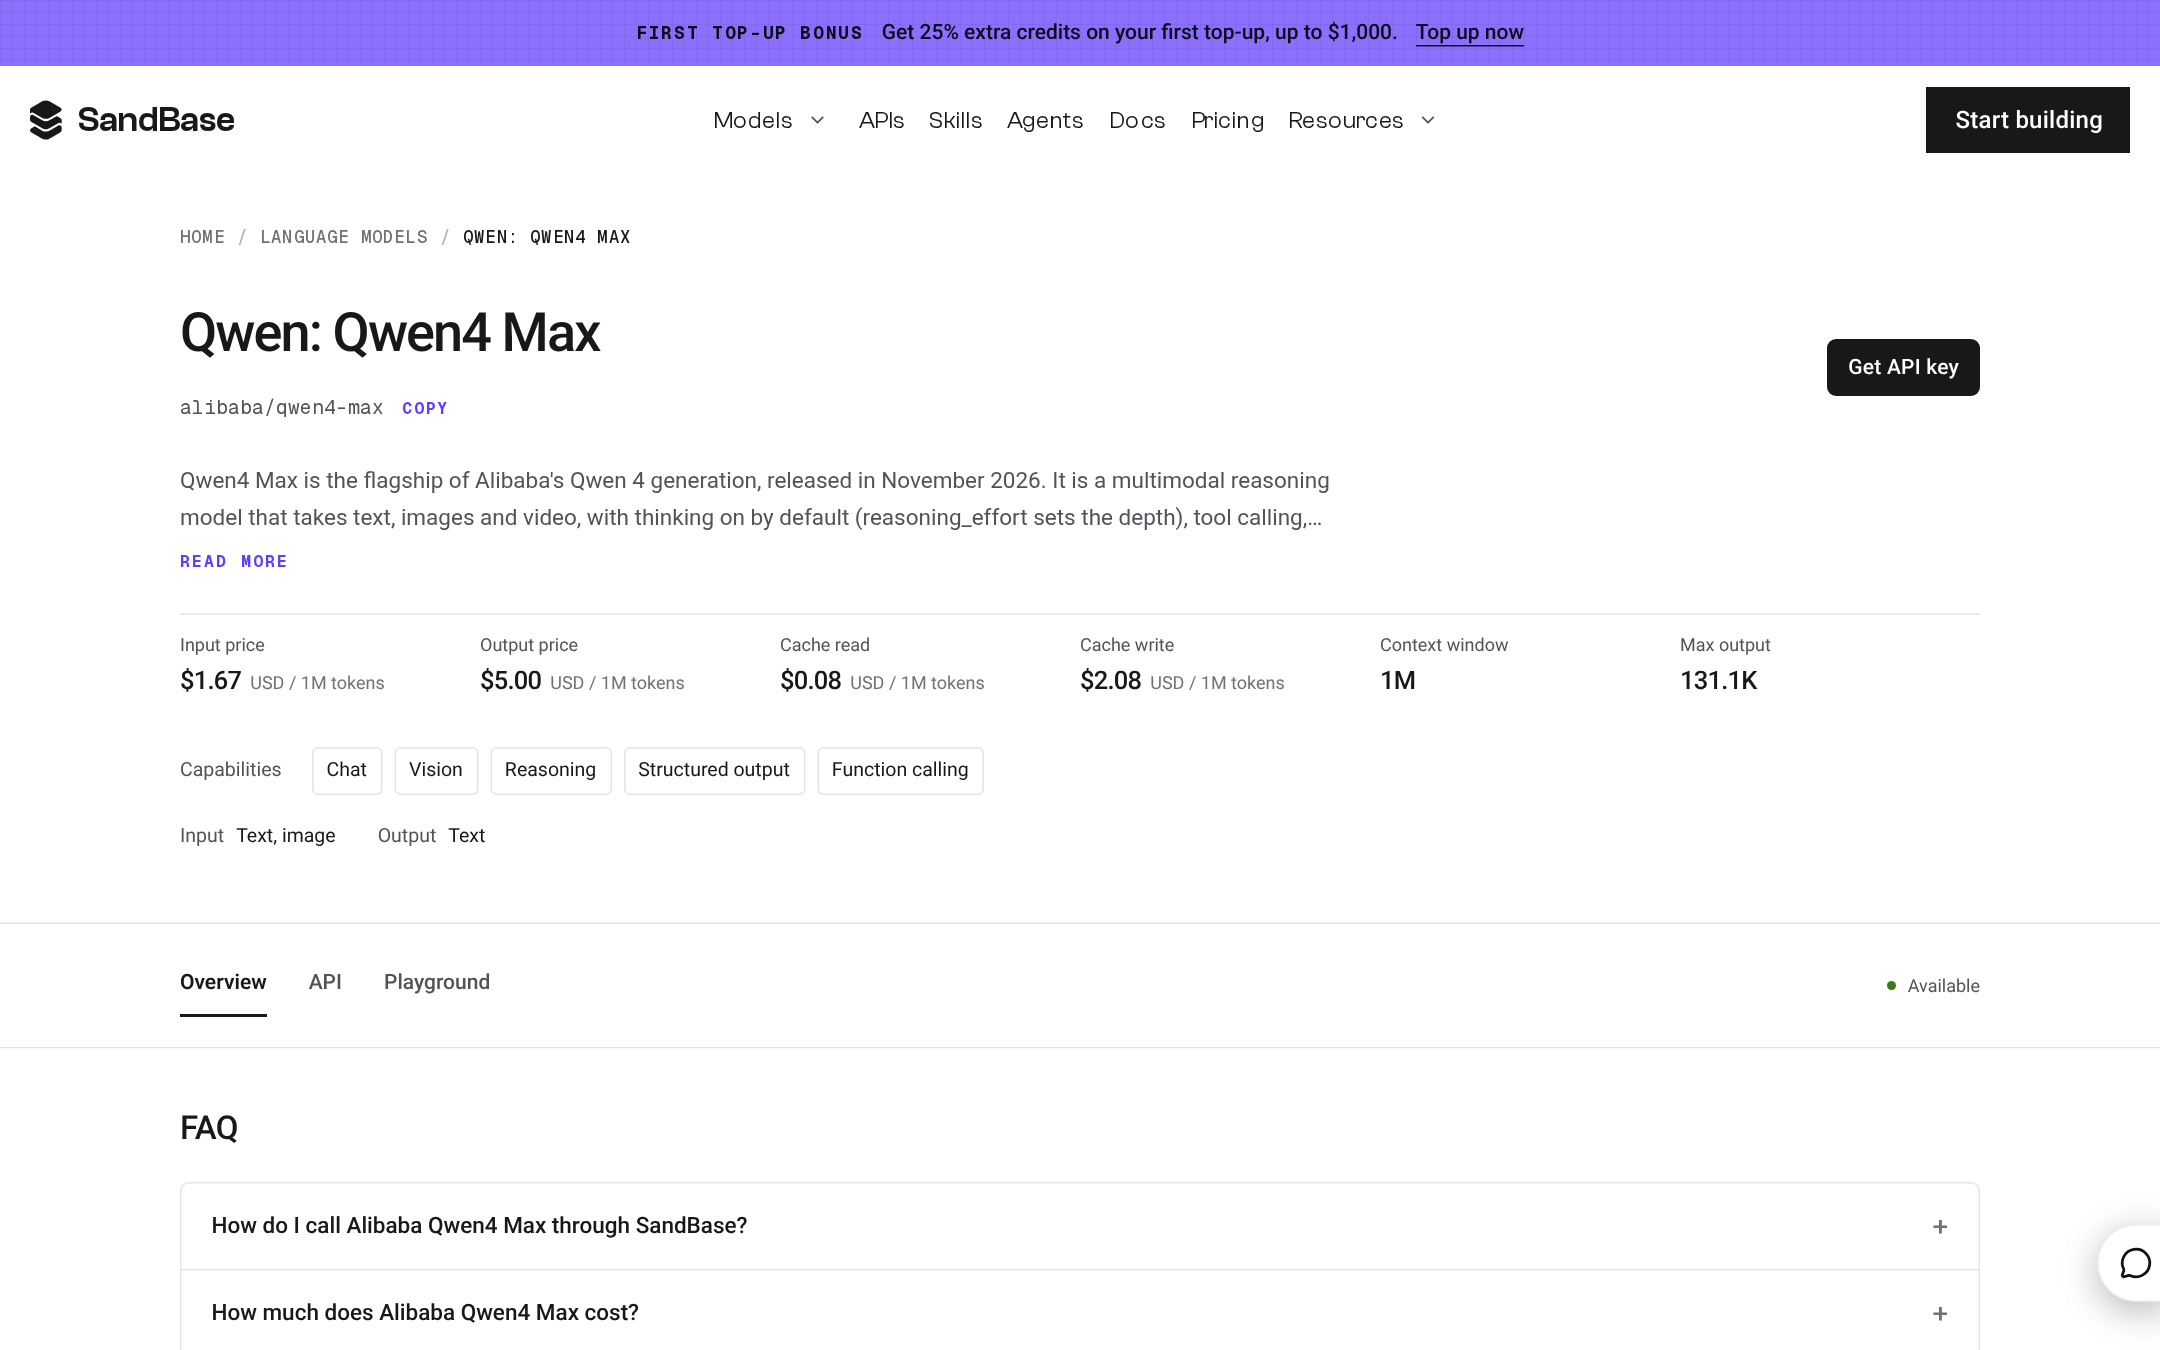
Live SandBase Qwen4 Max card at /models/alibaba/qwen4-max, captured 16 Nov 2026, Asia/Shanghai (HTML and .md both HTTP 200). Hero is $1.67 / $5.00, with cache read $0.08 and cache write $2.08 per 1M tokens, 1M context, and 131.1K max output. There is no 10% off badge. These SandBase prices are above the official Singapore list of $1.50 / $4.50, and above official Beijing / Global $1.413 / $4.24, but still below SandBase Qwen3.8 Max at $1.80 / $5.40. The card hero max output of 131.1K matches the official non-thinking cap; the card description still incorrectly says “up to 393K output tokens shared by thinking and the answer,” which is a preview leftover, not the official GA limit.
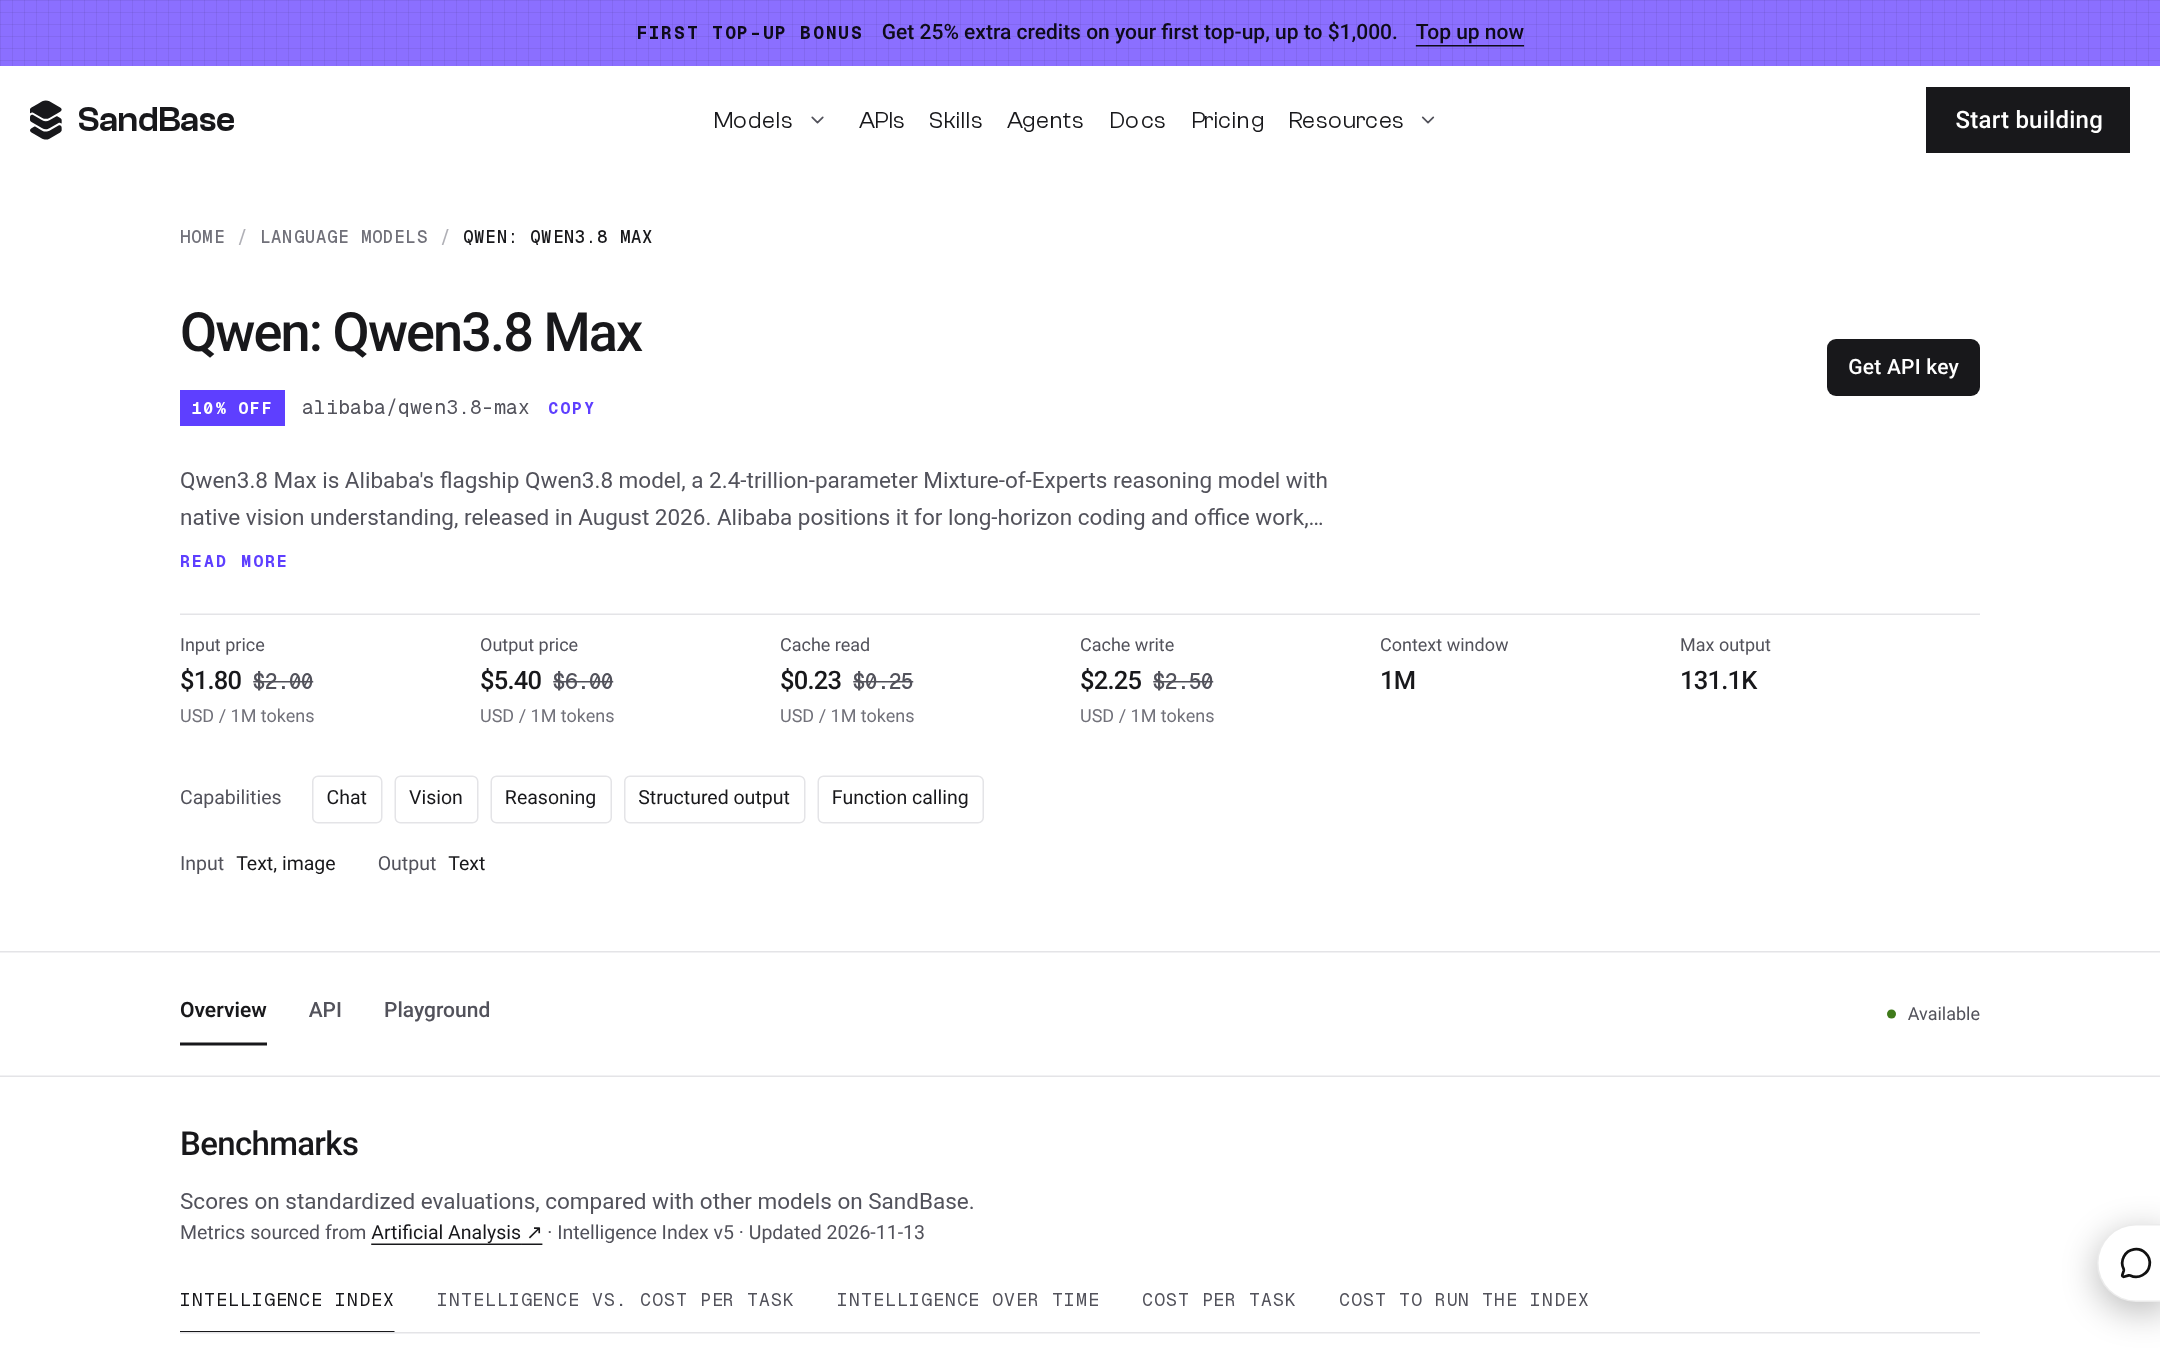
Live SandBase Qwen3.8 Max card at /models/alibaba/qwen3.8-max, captured 16 Nov 2026, Asia/Shanghai. Hero is $1.80 / $5.40 (10% off the $2 / $6 list), with cache read $0.23 and cache write $2.25 per 1M tokens, 1M context, and 131.1K max output. Official Alibaba max output for qwen3.8-max remains 128k; cite both figures and name the source.
On SandBase, Qwen4-Max is the cheaper of the two flagship heroes: $1.67 / $5.00 versus $1.80 / $5.40. The discount badge belongs only to Qwen3.8 Max. Official cache also differs from the Qwen4-Max card. Singapore cache read is $0.075 and cache write is $1.875 for five minutes or $3 for one hour. The card prints a single write of $2.08 and a read of $0.08. Thinking tokens are billed as output on the official price page, and Qwen4-Max has no input-length tiers. The generic Batch API 50% bullet on that pricing page does not apply: official Qwen4-Max model pages say batch inference is not supported.
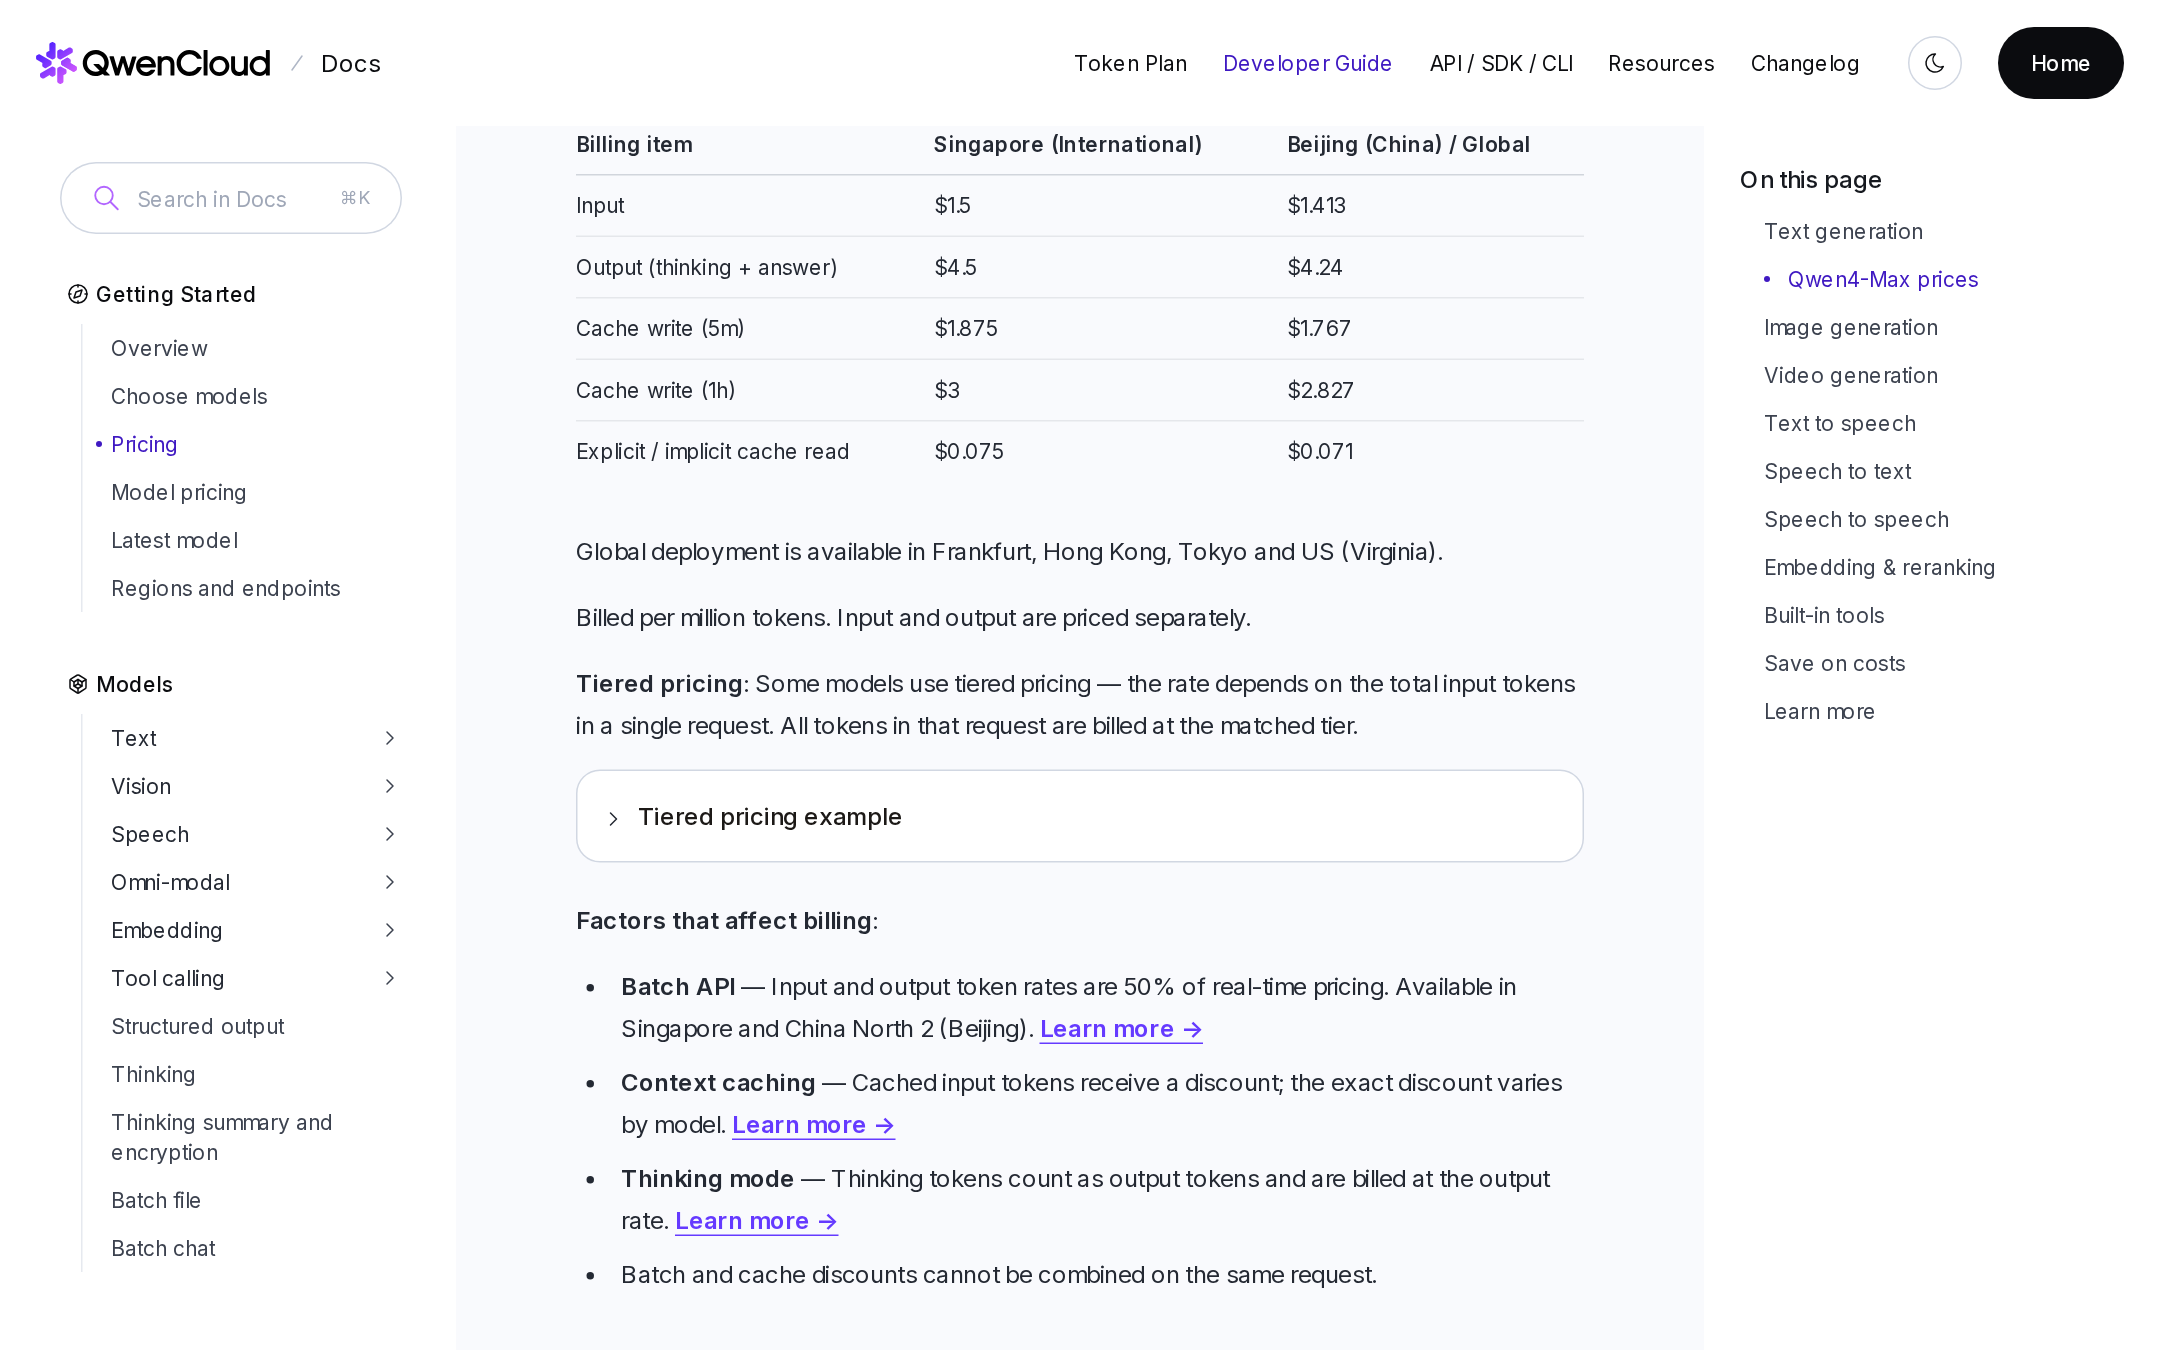
Official QwenCloud pricing page, captured 16 Nov 2026, Asia/Shanghai. Singapore (International) list is $1.5 / $4.5 per 1M tokens (the page prints $1.5 / $4.5, equivalent to $1.50 / $4.50), with cache write $1.875 (5m) / $3 (1h) and cache read $0.075. Beijing / Global is $1.413 / $4.24, with cache write $1.767 / $2.827 and cache read $0.071. The page states that thinking tokens are billed at the output rate, and that Qwen4-Max has no input-length tiers. The “Batch API 50%” bullet on this page is a general billing factor — official Qwen4-Max model pages list batch inference as not supported for this model.
Singapore pay-as-you-go on official QwenCloud offers 1 million free tokens, separate from Token Plan credits. Other regions do not. The SandBase card does not state that grant.
A 9-task probe, with the limits stated first
On 16 November 2026, Asia/Shanghai, the same Chat Completions route ran nine tasks against alibaba/qwen4-max and alibaba/qwen3.8-max. The window was 12:17:28 to 12:19:08 (UTC+8). Thinking was left at the API default, which is on. max_tokens was 4096. Scoring was automatic, against hidden expected answers. This is a small practical probe. It is not a published benchmark, not a vendor score, and not a ranking against Gemini 4 Carbon, GPT-6 Astra, or Claude Fable 5.2. Those models were not in the set.
| Qwen4-Max | Qwen3.8 Max | |
|---|---|---|
| Score | 8 pass, 1 partial, 0 fail | 8 pass, 1 partial, 0 fail |
| Wall time | 33.566s | 66.332s |
| Estimated cost at SandBase card rates | $0.006376 | $0.012456 |
| Prompt / completion tokens | 971 / 951 | 1394 / 1842 |
Qwen4-Max was faster on every task in this set. Completion tokens were 951 versus 1842. Costs use the card rates ($1.67 / $5.00 versus $1.80 / $5.40), not official list prices.
| Task | Result | Qwen4-Max | Qwen3.8 Max |
|---|---|---|---|
| smoke | Both exact OK | 2.959s, 32/17 | 7.96s, 71/29 |
| math_mod (3^100 mod 7 = 4) | Both pass | 5.748s, 61/220 | 8.099s, 100/229 |
| lockers (100 lockers = 10) | Both pass | 5.688s, 84/177 | 6.228s, 123/220 |
| pack_discount ($2.40 vs 5 for $10, 17%) | Both pass | 4.52s, 86/126 | 5.665s, 125/186 |
| coding_lis | Both O(n log n) bisect_left patience-sorting; 7 hidden tests passed | 2.379s, 91/89, 9 reasoning tokens | 4.943s, 130/175, 83 reasoning tokens |
| json_extract | Both Maya Chen / 34 / Singapore | 1.868s, 62/26, one-line object | 4.439s, 101/79, pretty-printed, scored match in body |
| zh_formula | Both H₂O only | 2.678s, 44/31 | 4.508s, 83/88 |
| vision_probe | Both partial, 4/5 | 6.013s, 314/223 | 20.867s, 315/779 |
| tool_weather | Both called get_weather with city=Tokyo | 1.713s, 197/42, empty content plus the tool call | 3.623s, 346/57, also said it would check Tokyo weather |
The shared partial is a probe-quality issue. Both models misread “SB-Q4-42” as “SB-04-42” because the generated bitmap Q looked like a 0. Both got the red circle and the green shape. Qwen4-Max called the 160 by 140 block a square. Qwen3.8 Max called it a rectangle. That is not a model ranking, and the probe image is not reproduced here.
What this set supports: on these nine tasks, accuracy matched, and Qwen4-Max used less time, fewer completion tokens, and less card-rate spend. What it does not support: a general claim that Qwen4-Max is “smarter,” or any claim about Carbon, Astra, or Fable.
What the official blog says about the same pair
The launch blog says Qwen4-Max is “a significant step up from Qwen3.8-Max, delivering stronger performance across nearly every capability we evaluated.” On Work360 it reports 52.69 versus 47.74 for Qwen3.8-Max. On token usage versus Qwen3.8-Max it says Work360 usage is “approximately 24% and 35% at Xhigh and High effort, respectively,” and Terminal-Bench 4.0 is “approximately 48% and 49%, respectively.” It also says API prices were lowered compared with Qwen3.8-Max, “with particularly large reductions in cached-input pricing,” and that Work360 average cost per task went “from $4.43 to $1.67 — a 62% reduction.”
Those sentences are vendor claims about named evaluations. They are not the 9-task probe, and they are not a blanket “half the tokens” line you can paste onto an arbitrary agent. The blog’s $1.67 is an average cost per Work360 task. The SandBase $1.67 is the input price per million tokens on the Qwen4-Max card. Same digits, different units. Footnotes for the vendor scores live on the blog, not in this probe.
When Qwen3.8 Max is still the call
Stay on Qwen3.8 Max when three things are true at once: the prompts, tools, and graders are already pinned to it; you want the 10% off hero and its cache rates; and you are not ready to re-validate against reasoning_effort=high and the new output caps. A new default effort changes how many tokens a “same” prompt spends before the answer. That is a migration, not a string swap.
Other live Qwen3.8 cards, if the flagship is the wrong size:
- Qwen3.8 27B at $0.50 / $3, cache $0.10 / $0.63, 1M / 131.1K. Dense open-weight vision-language model. The card lists vision.
- Qwen3.8 Omni Flash at $0.15 / $0.47, cache $0.02 / $0.15, 1M / 131.1K. Text, image, audio, and video in, text out. Official Qwen4-Max docs do not claim audio input.
- Qwen3.8 Flash at $0.15 / $0.47, cache $0.02 / $0.20. The SandBase hero prints context window N/A and max output 131.1K. Do not invent a SandBase context. Official docs, separately, list
qwen3.8-flashat 1M / 128k. - Qwen3.8 Max Prime at $4 / $12, cache $0.50 / $5.00, 1M / 131.1K. Faster serving of the same Max model.
- Qwen3.8 2.4T A95B at $2 / $6, cache $0.25 / $2.50, 1M / 52.4K. The card lists chat, reasoning, structured output, and function calling. Vision is not on that list.
Routing among Max, 27B, and Omni Flash, written while the preview was the only Qwen4 story, is Which Qwen Should You Call Today?. Read the 16 November update at the top of that page before you treat it as current.
Do not start on the preview
alibaba/qwen4-max-preview is still listed, at $2.00 / $6.00, cache $0.25 / $2.50. The hero context window is N/A. Official Token Plan copy still retires the preview model after 24:00 on 25 November 2026 (UTC+8). The GA ID for production is alibaba/qwen4-max. Endpoint for both language-model cards: POST https://api.sandbase.ai/v1/chat/completions.
Confirmed versus unknown
| Confirmed | Unknown, or out of scope |
|---|---|
| Both models are GA and live on SandBase, with the prices and caps in the table | Whether Qwen4-Max is “smarter” in general |
Official quality recommendation now points at qwen4-max; qwen3.8-max is under older models | Official blog scores beyond the sentences quoted above |
| The 9-task probe: same 8 / 1 / 0, Qwen4-Max faster and cheaper on this set, at card rates | Any claim that the probe ranks Qwen4-Max against Carbon, Astra, or Fable |
Batch inference is not supported for qwen4-max on official model pages | A SandBase 10% off for Qwen4-Max |
FAQ
Should existing Qwen3.8 Max traffic move this week?
New traffic, yes, unless you still need the incumbent’s prompt stack untouched. Existing traffic moves after you re-run the graders with thinking left at the new default and with a completion cap that can hold thinking plus the answer. The probe above is a reason to run that check. It is not a substitute for your own tasks.
Which output cap do I copy?
For Qwen4-Max, copy 131,072 when thinking is off and 262,144 when thinking and the answer share the budget. For Qwen3.8 Max, copy 128k from official Alibaba docs, or 131.1K from the SandBase hero, and name which host you mean. The SandBase Qwen4-Max blurb that still says 393K is a leftover.
Is the SandBase Qwen4-Max price the official price?
No. Official Singapore is $1.50 / $4.50. Official Beijing and Global is $1.413 / $4.24. SandBase is $1.67 / $5.00 with no discount. It is still below the SandBase Qwen3.8 Max hero.
What to open
Qwen4 Max for new production, with the official list and the card hero both in view. Qwen3.8 Max when the 10% off baseline is the point. Sign up and send the first request through the first API call doc, model alibaba/qwen4-max, before you cut a queue over.
Card heroes, official limits, and the 9-task probe are from 16 November 2026, Asia/Shanghai. Vendor Work360 and Terminal-Bench sentences are quoted from the official launch blog only. The probe did not include Gemini 4 Carbon, GPT-6 Astra, or Claude Fable 5.2.
Related reading
Found this useful? Share it