Is Qwen 4 Out? What's Confirmed in the Qwen4-Max-Preview, and What You Can Call Today
15 Nov record of Qwen4-Max-Preview. Update 16 Nov 2026: Qwen4-Max is GA with PAYG and live on SandBase as alibaba/qwen4-max.
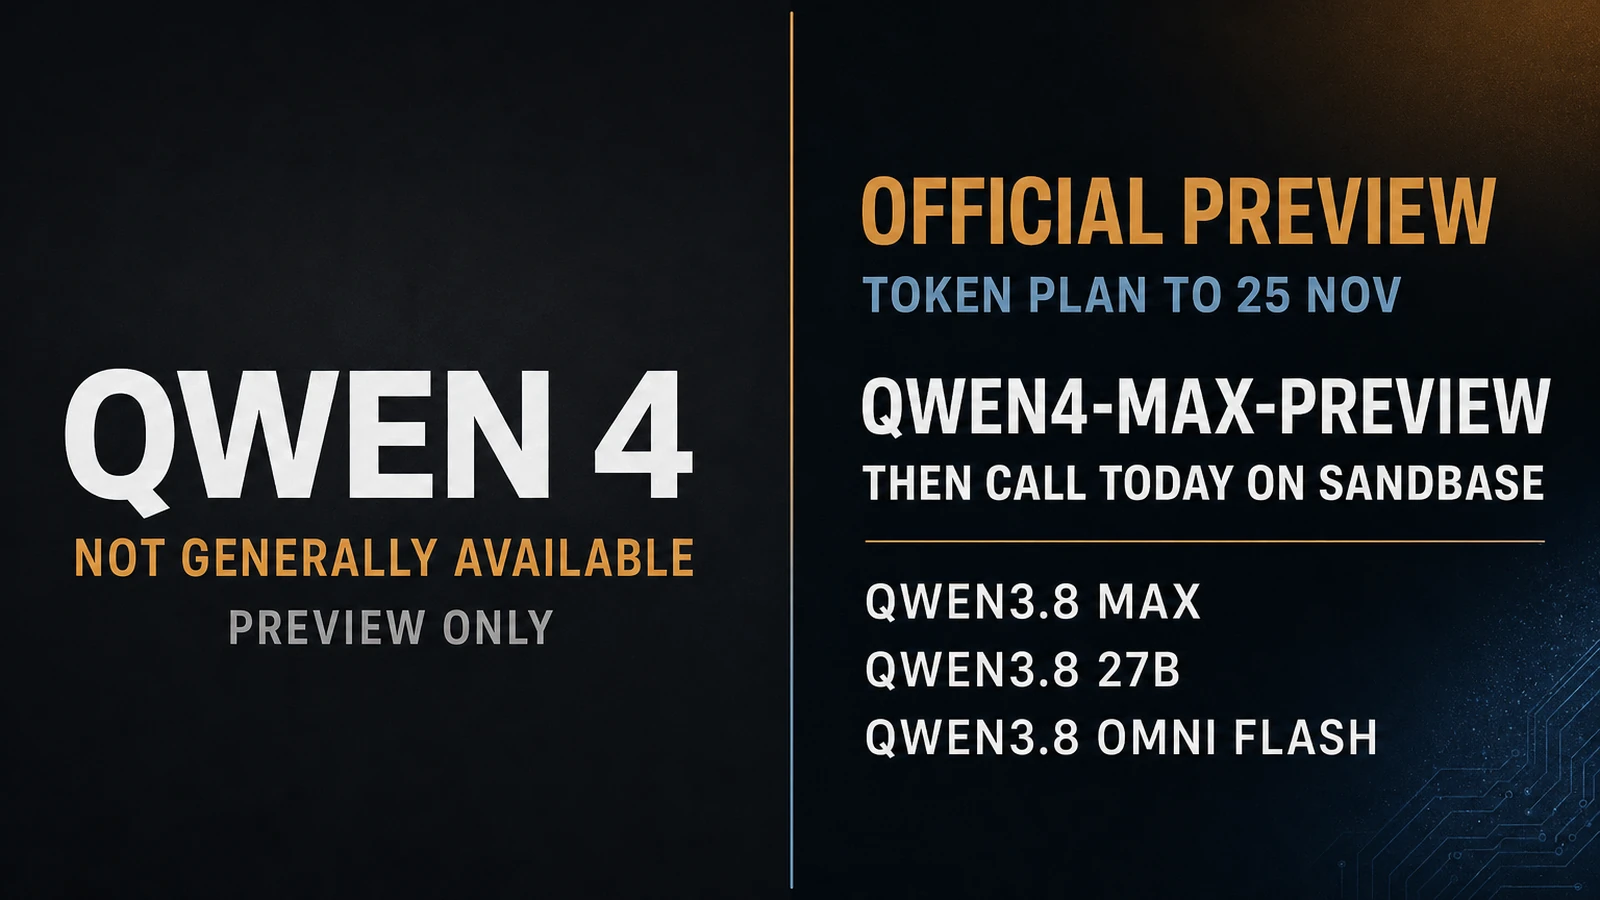
Update (16 Nov 2026): Qwen4-Max is officially generally available, pay-as-you-go is on, and it is live on SandBase as
alibaba/qwen4-max. The sections below are the 15 November preview record and stay as history. Official limits, the public price, and the call shape are in Qwen4-Max Is Generally Available. Whether to switch production off Qwen3.8 Max is Qwen4-Max vs Qwen3.8 Max. The public-price comparison with Gemini 4 Carbon, GPT-6 Astra, and Claude Fable 5.2 is the 16 November comparison.
On the evening of 15 November 2026, Asia/Shanghai, Alibaba’s official preview was out. The product name is Qwen4-Max-Preview. The model ID is qwen4-max-preview. Token Plan access runs from 10:00 on 11 November 2026 to 24:00 on 25 November 2026 (UTC+8). Official copy says the preview model will be retired after that window. On that evening it was not general availability, and SandBase had no Qwen4 card. A request on SandBase that evening still used the live Qwen3.8 cards, starting with Qwen3.8 Max. The update above is the 16 November status.
The check that evening covered the QwenCloud latest-model page, the Model Studio releases page (last updated 11 November 2026), the Token Plan product updates (last updated 13 November 2026), and the Token Plan team overview. At 20:35 Asia/Shanghai, candidate SandBase paths returned HTTP 404 on both the HTML card and the markdown file. Live Qwen3.8 cards in the same window returned 200 on both.
Readers who already have a Token Plan key, and who need the request-shape changes, should use the 13 November guide: Qwen4-Max-Preview: Access, Token Plan, and the November 25 Deadline. That page owns max_tokens (thinking plus the answer), reasoning_effort, and preserve_thinking. This page answers a different question: what the 15 November check confirmed, what was still unknown that evening, and which IDs SandBase accepted then. The 16 November IDs are in the update above.
Key takeaway
- Update, 16 Nov 2026: Qwen4-Max (
qwen4-max) is generally available with pay-as-you-go, and live on SandBase asalibaba/qwen4-max. Read the launch post linked above for the price and the 131,072 / 262,144 caps.- The bullets below are the 15 Nov 2026 preview record. Official preview: Qwen4-Max-Preview (
qwen4-max-preview), Token Plan only, from 10:00 on 11 Nov 2026 to 24:00 on 25 Nov 2026 (UTC+8). Official copy says that preview model will be retired after the window.- On the pages fetched 15 Nov, the preview had no public pay-as-you-go API and no dollar price per million tokens. Credits promotions are not a tariff. That absence described the preview check, not the 16 Nov GA model.
- The official Qwen Hugging Face org search for Qwen4 returned zero models on the 15 November 2026 check. Qwen4-Plus, Qwen4-Flash, and Qwen4-27B are not in the 11 Nov release entry.
- At 20:35 Asia/Shanghai on 15 Nov, SandBase paths for a Qwen4 ID returned HTTP 404 on both HTML and
.md. Callable that evening: Qwen3.8 Max at $1.80 / $5.40 per 1M (10% off list $2 / $6), Qwen3.8 27B at $0.50 / $3, and Qwen3.8 Omni Flash at $0.15 / $0.47. Route:POST https://api.sandbase.ai/v1/chat/completions.
Short answer from the 15 Nov 2026 check: official preview, not yet general availability, and not yet on SandBase
The search phrase is “Qwen 4”. The official product name in the docs is Qwen4-Max-Preview, with no space in “Qwen4”. “Qwen 4 Max Preview” and “Qwen-4-Max” are not the official product spelling.
| Claim | Grade | What the 15 Nov check found |
|---|---|---|
Official preview named Qwen4-Max-Preview, ID qwen4-max-preview | Confirmed | Latest-model page and the 11 Nov Model Studio entry. |
| Token Plan only, 11 Nov 10:00 through 25 Nov 24:00 (UTC+8), then retired | Confirmed | Latest-model page. “No changes will be made during this period, and the model will be retired after the preview ends.” |
| Public pay-as-you-go API or a $/1M price | Confirmed absent | Credits promotion only: as low as 20% of the standard rate, and 8% of the standard rate in the overnight window. |
| Official open weights on the Qwen Hugging Face org | Confirmed absent | author=Qwen search for Qwen4 returned 0 models. Newest official uploads visible were still Qwen3.8. |
| Qwen4-Plus, Qwen4-Flash, or Qwen4-27B as a shipping SKU | Not in the official 11 Nov docs | Some reports use those names. They are not rows on the pages from the 15 November 2026 check. |
| Listed on SandBase | Confirmed absent | HTML and .md both 404 (“Model Not Found” / Not found) at 20:35 Asia/Shanghai. |
| A generally available Qwen 4 family, or a promised GA date of 25 Nov 2026 | Unknown, and not what the docs say | 25 Nov 2026, 24:00 UTC+8 is the scheduled retirement of this preview model. |
The official one-sentence description, from the latest-model page:
Qwen4-Max-Preview is the next-generation flagship multimodal model in the Qwen family, combining text generation, image and video understanding, and deep reasoning.
That sentence describes the preview. Parameter count, benchmark scores, a later GA date, whether a later model keeps this ID, and any open-weight license are absent here. Those blanks are listed again below, and they stay blank.
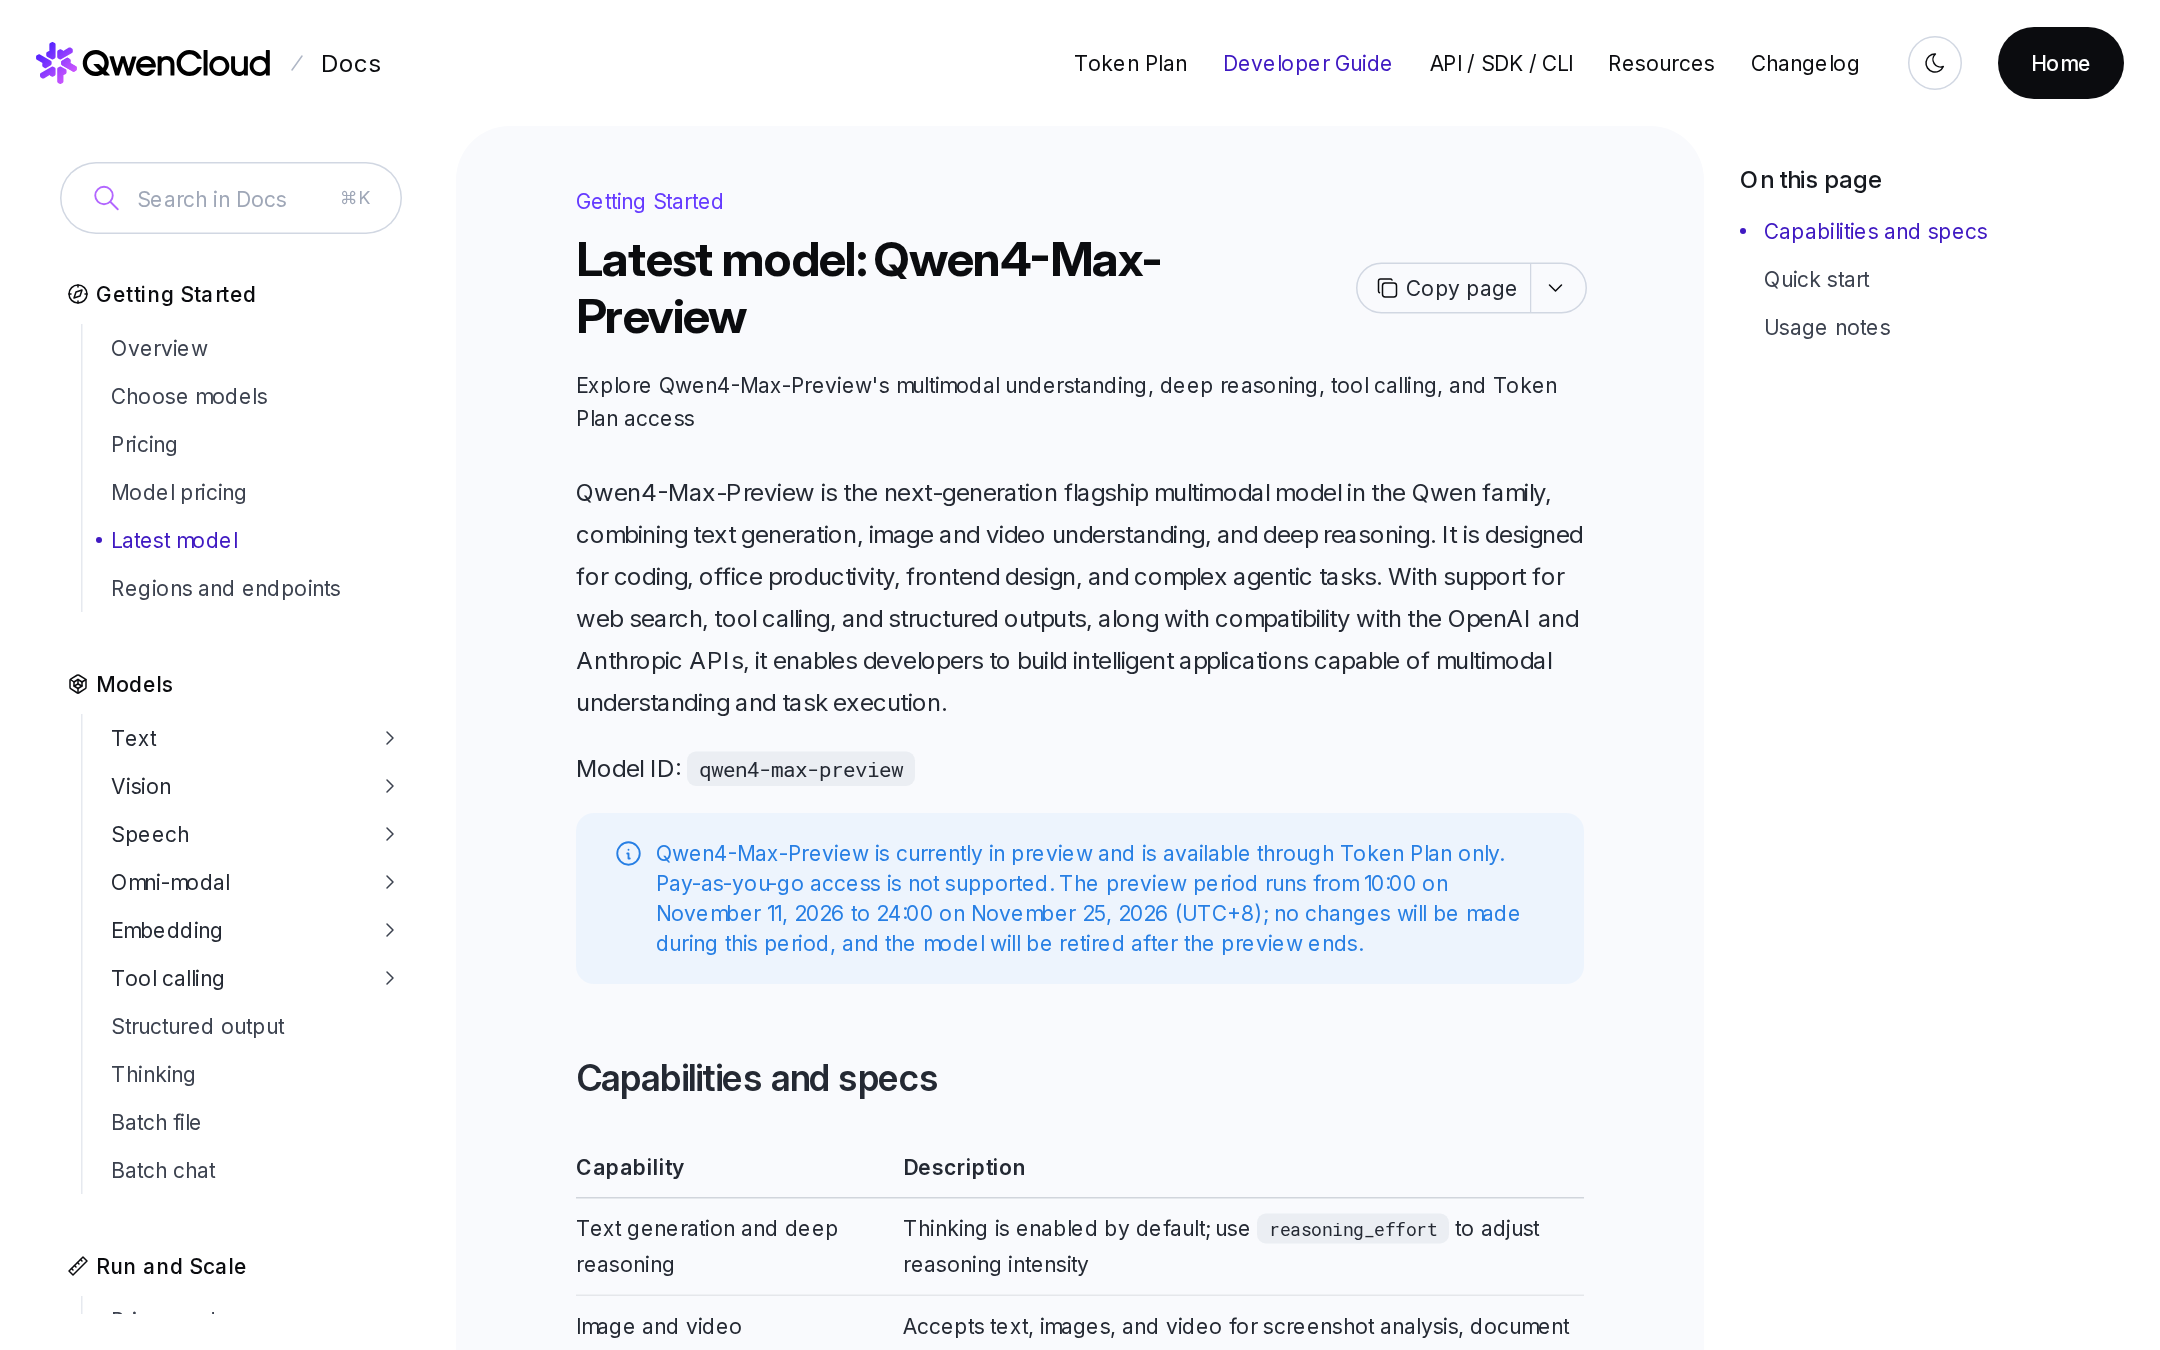
Official QwenCloud latest-model page as of 15 Nov 2026, Asia/Shanghai. It names Qwen4-Max-Preview (qwen4-max-preview), restricts access to Token Plan, and states the preview ends at 24:00 on 25 Nov 2026 (UTC+8), after which the model will be retired.
The crop is the official preview page. It is the right picture for “is the preview real?” It is the wrong picture for “can I send this ID on SandBase?” Those are separate checks, and the second one failed.
What Alibaba has officially confirmed
Official name, ID, and window
Product spelling on the vendor pages is Qwen4-Max-Preview. The family name on those pages is Qwen4. The ID to prefer in prose is qwen4-max-preview.
The Token Plan team overview says the alias of qwen4-max-preview is qwen4.0-max-preview. Both IDs can be used, and bills uniformly show qwen4.0-max-preview.
| Item | Official value, fetched 15 Nov 2026 |
|---|---|
| Product name | Qwen4-Max-Preview |
| Model ID | qwen4-max-preview |
| Preview window | 10:00 on 11 Nov 2026 to 24:00 on 25 Nov 2026 (UTC+8) |
| After the window | The preview model will be retired. The pages do not schedule a GA replacement on that clock time. |
| Where it was announced in docs | Model Studio releases, last updated 11 Nov 2026, with a 2026-11-11 entry. Token Plan product updates, last updated 13 Nov 2026, with an 11 Nov “Qwen4-Max-Preview available” note. |
| Editions | Personal Edition and Team Edition both support the model, per the Token Plan updates page. |
The supported-models table on the team page lists qwen4-max-preview for reasoning, vision understanding, and text generation, next to qwen3.8-max and qwen3.8-flash. That table has no qwen4-plus, qwen4-flash, or qwen4-27b row.
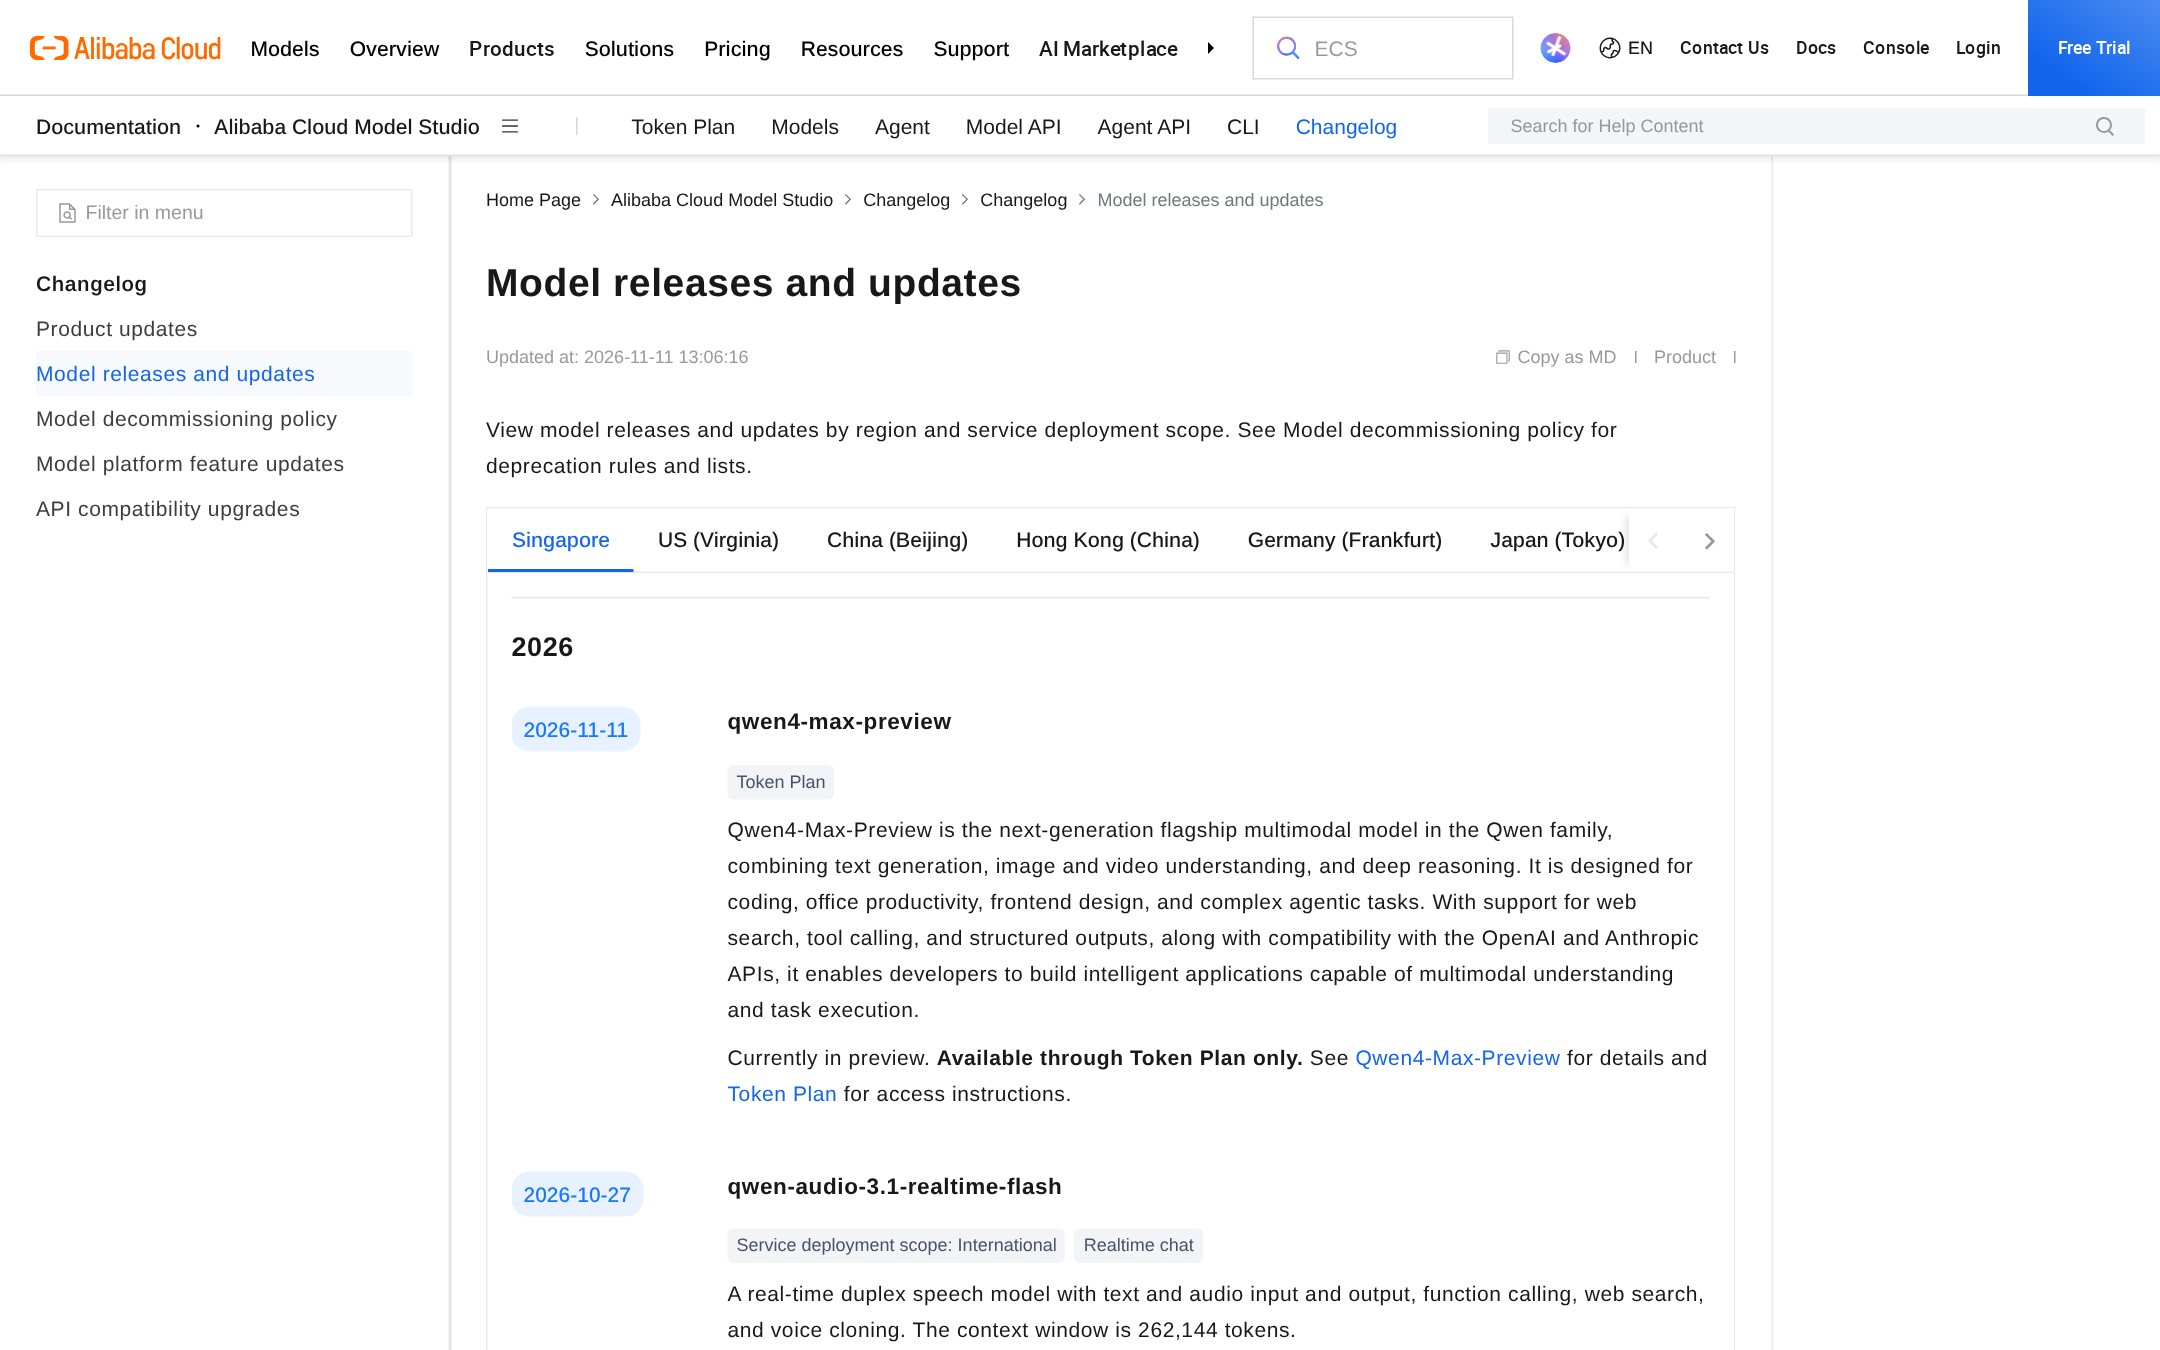
Official Model Studio “Model releases and updates” page (updated 2026-11-11 13:06:16 on the page), captured 15 Nov 2026, Asia/Shanghai. The 11 Nov entry is qwen4-max-preview, labeled Token Plan only — not a general-availability listing.
The page stamp in the caption is the releases page’s own update time, visible on the capture. The entry itself is the 11 November preview row. A Token Plan badge on that row is the access label. It is not a general-availability chip for the rest of Qwen 4. The screenshot shows a Singapore-region row. This note does not turn that label into a claim that every other region is closed, and it does not turn it into a public pay-as-you-go listing.
Secondary writeups of the official 11 November announcement describe a teaser along the lines of Qwen4 coming, with Qwen4-Max in preview on Token Plan, and early access also named on QwenWork, Qoder, Qwen APP, and QwenStudio. The original social post was not re-fetched on the 15 November 2026 check, so this note does not invent a tweet. Treat that teaser as a pointer to the docs above. It is not a how-to for those apps, and it is not a GA announcement. The docs put the time at 10:00 on 11 November 2026 (UTC+8). Secondary citations of the teaser put it at 11 November 2026, 10:01 Asia/Shanghai.
Official specs
Figures below are from the latest-model page on the 15 November 2026 check. Nothing in this table is a SandBase limit. SandBase does not list this ID.
| Parameter | Official value |
|---|---|
| Context length | 1M tokens |
| Maximum output | 393,216 tokens, shared by thinking and the final answer |
| Input | Text, images, and video |
| Thinking | Enabled by default. reasoning_effort: low, medium, or xhigh (default). Do not set reasoning_effort and thinking_budget together. |
| Tools | Function calling, web search, built-in tools |
| Structured outputs | JSON Object and JSON Schema |
| API compatibility | OpenAI Chat Completions, Responses, and Anthropic Messages |
| Access | Token Plan only |
| Pay-as-you-go | Not supported |
| Stability | No changes during the preview. Retired after 25 Nov 2026, 24:00 UTC+8. |
The page also says that, starting with qwen4-max-preview, max_tokens is equivalent to max_completion_tokens, and both limit thinking plus the final answer. A cap sized only for the visible answer can truncate the run. Chat Completions enables preserve_thinking by default: return historical thinking in reasoning_content, and do not concatenate it into content. Those three behaviors are why the 13 November guide exists. Use that guide for the migration. This status note stops at the official values.
Designed-for lines on the same page: coding, office productivity, frontend design, and complex agentic tasks. The page does not publish a parameter count or a benchmark table. A missing number stays missing.
How you can access the preview
Access is Token Plan only. Pay-as-you-go is not supported. During the preview, the updates page says Credits consumption is as low as 20% of the standard rate, with an additional 60% off between 22:00 and 08:00. The team-edition page states that overnight rate as 8% of the standard rate, and it describes the 20% rate as 5× usage. Those are Credits promotions. They are not a public dollar price per million tokens, and this note does not convert them into one.
The latest-model page lists a dedicated base URL, https://token-plan.maas.qwencloudapi.com, and tells readers to use the Token Plan guide for the complete endpoint for each protocol. The 13 November SandBase access note also cites https://token-plan.ap-southeast-1.maas.aliyuncs.com as an international base. This page does not collapse those two hostnames into one invented canonical URL. Pick the endpoint from the official Token Plan docs for the protocol you are calling, and use the 13 November access guide for the migration details already written up there.
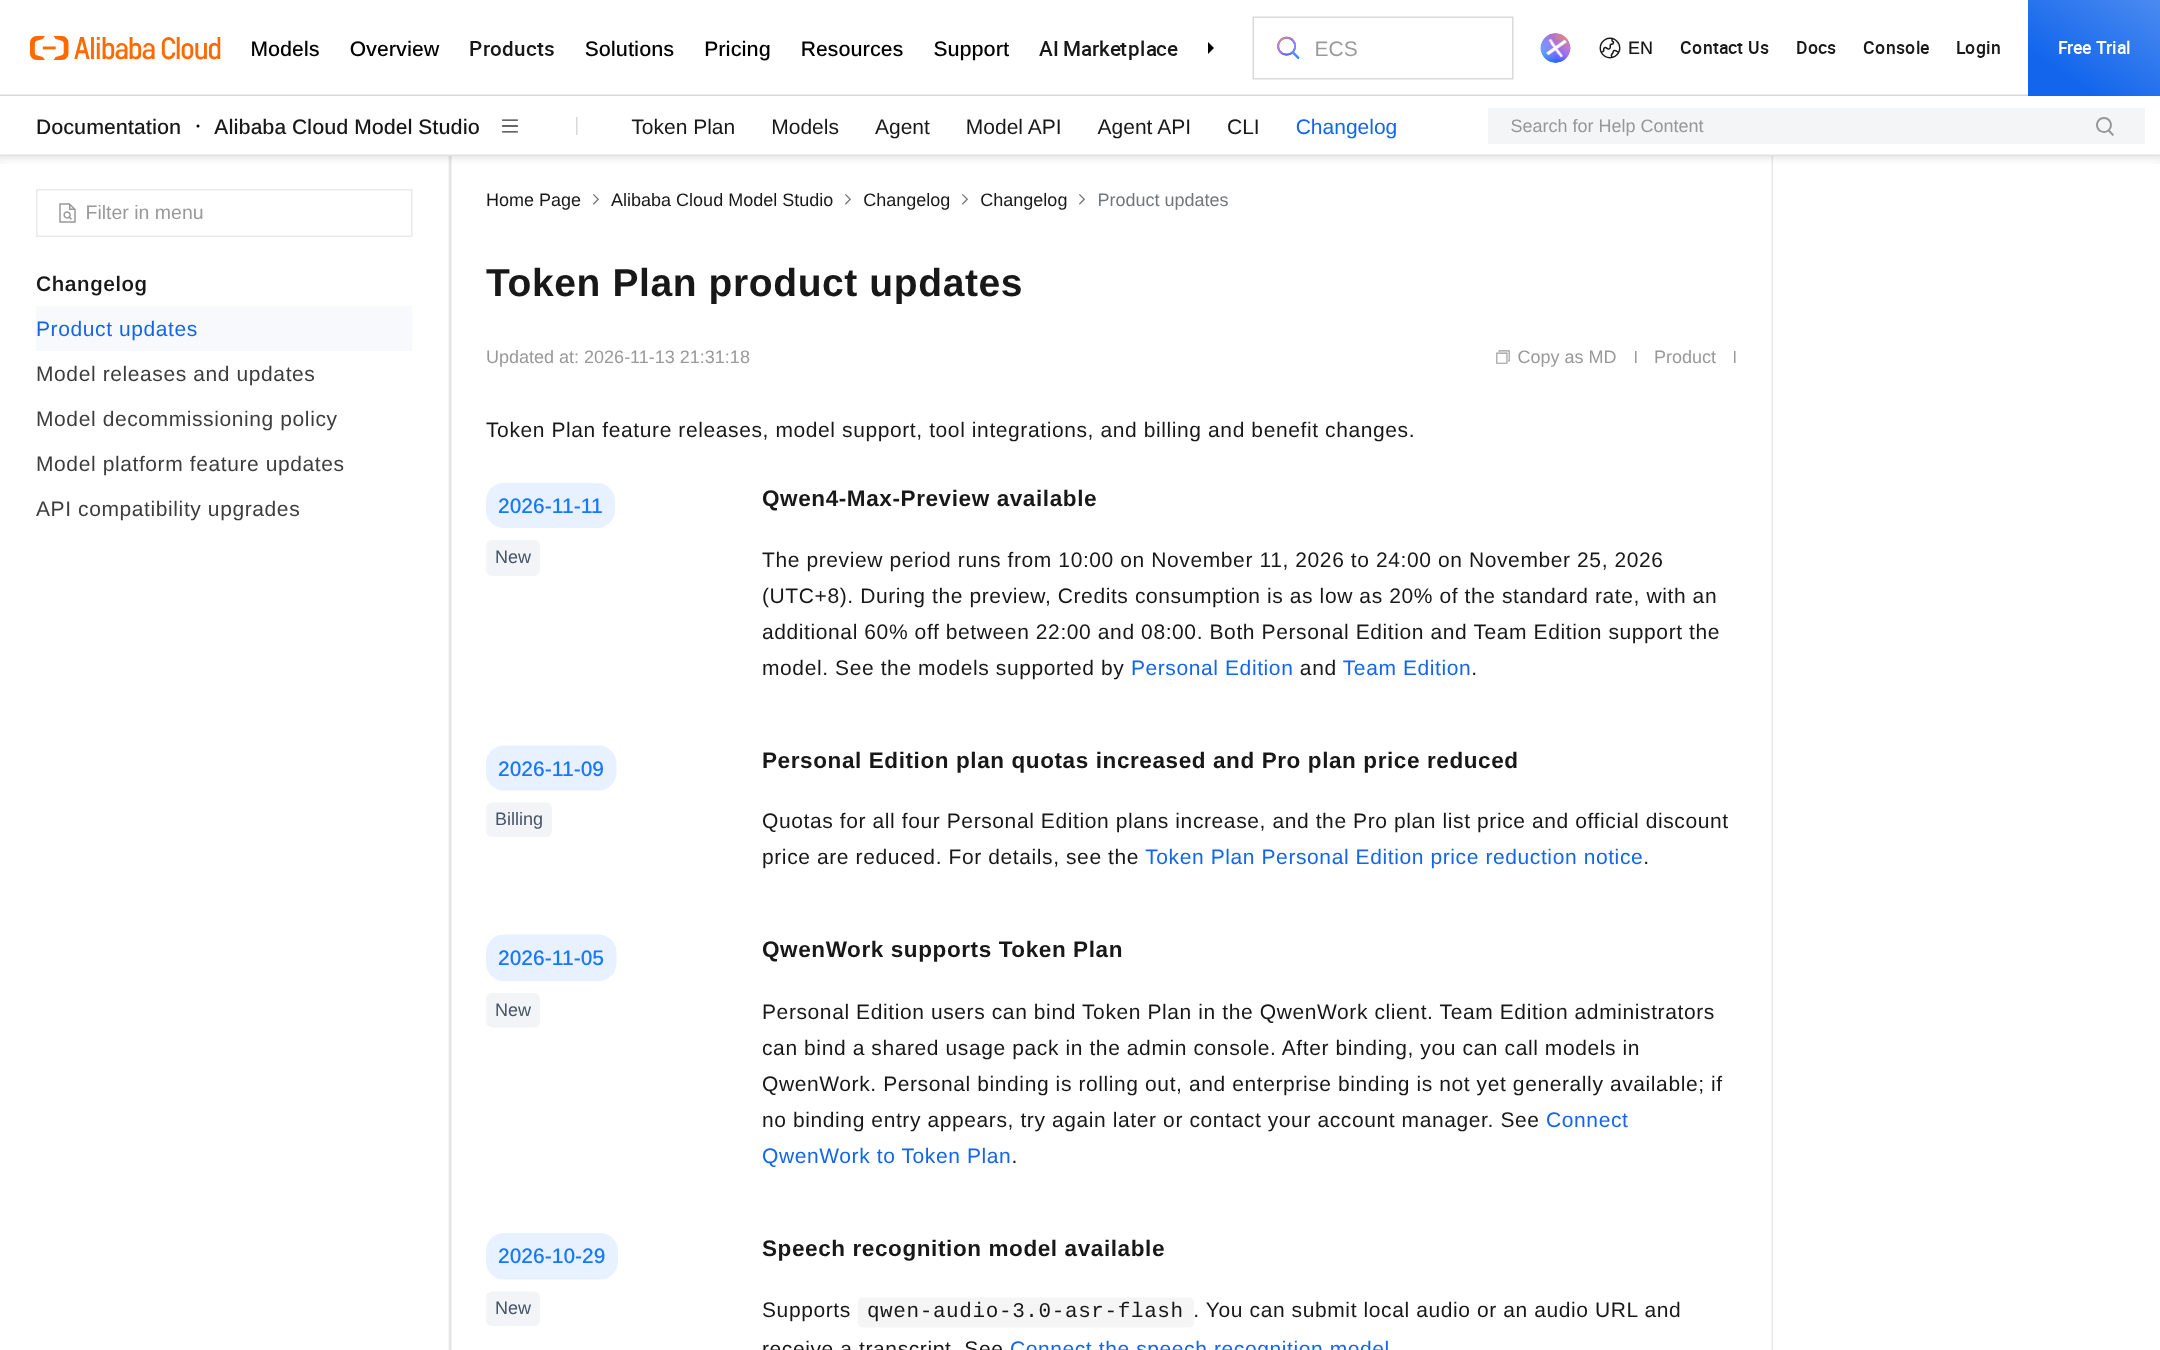
Official Token Plan product updates (page updated 2026-11-13 21:31:18), captured 15 Nov 2026, Asia/Shanghai. The 11 Nov note confirms the preview window and the Credits promotion. It is not a public pay-as-you-go price list.
No paid Alibaba or SandBase call was made for this 15 November note. The curl below uses a Qwen3.8 ID from that evening. A SandBase key does not belong on the Token Plan host.
What is still not released
This section is shorter on purpose. Confirmed facts are above. The items here are either absent from the official pages or only reported elsewhere.
The full set of names that showed up in October conference writeups is not a lineup you can order. Qwen4-Plus, Qwen4-Flash, and Qwen4-27B do not appear in the official 11 November Model Studio entry, the latest-model page, or the team-edition supported-models table from the 15 November 2026 check. Some reports attributed those names to Apsara / conference materials and to a “next week” remark. That grade is Reported. They are not released SKUs, not official IDs, and not SandBase cards.
Official open weights are absent. GET https://huggingface.co/api/models?author=Qwen&search=Qwen4 returned 0 results. The newest official Qwen/ uploads visible on the 15 November 2026 check, sorted by lastModified, were still the Qwen3.8 series, including Qwen/Qwen3.8-2.4T-A95B dated 7 November 2026. Unofficial repositories that put “Qwen4-27B” in the name are not official weights. This note does not link them.
On the 15 November 2026 check there was no public pay-as-you-go price, and there was no SandBase card. At 20:35 Asia/Shanghai the HTML card and the .md file were both 404 for the preview ID, the alias, and a set of hyphenations under /models/alibaba/ and /models/qwen/. The 16 November card is alibaba/qwen4-max. Control cards for Qwen3.8 returned 200 on both in the same window, so the 404s are not a site outage. Paths are omitted here so a 404 string is not copied as a destination.
One older false start is worth a single sentence. Third-party model databases have carried a June 2026 “Qwen 4” row. No such shipping model is in the official 11 November docs. The first official Qwen4 model with a published ID is this 11 November preview.
Still unknown, and left unknown: parameter count, official benchmark scores, any GA date after 25 November, whether a later non-preview model will keep qwen4-max-preview, and an open-weight license for any Qwen4 tier.
What you could call on SandBase on 15 November 2026
The generally available Qwen generation you could name and call that evening was still Qwen3.8. As of 16 November 2026 the flagship call is alibaba/qwen4-max; this section keeps the 15 November card table. Official Model Studio listings fetched with the changelog on the 15 November 2026 check still include qwen3.8-max, snapshots such as qwen3.8-max-0902, qwen3.8-27b, qwen3.8-2.4t-a95b, qwen3.8-flash, and qwen3.8-omni-flash. The long flagship writeup is Qwen 3.8 Max: Alibaba’s 2.4T Multimodal Flagship. Earlier notes in the same line are Qwen 3.7 Max: Alibaba’s Agent-First Flagship (2026) and Qwen 3.6 for Agents: Alibaba’s Efficient Open Model. The Qwen models hub was HTTP 200 this evening, and its live intro still describes Qwen3.8 Max and earlier models.
Live cards and honest prices
Rechecked the evening of 15 November 2026, Asia/Shanghai. HTML and markdown both 200. Prices are the card Facts line. The Qwen3.8 Max cache figures are the live hero, which also shows the 10% off badge. SandBase does not bill the $2 / $6 list on that card.
| Card | SandBase ID | Input / output per 1M | Context / max output | What the card supports |
|---|---|---|---|---|
| Qwen3.8 Max | alibaba/qwen3.8-max | $1.80 / $5.40 | 1M / 131.1K | Chat, vision, reasoning, structured output, function calling. Card: 2.4-trillion-parameter MoE with native vision, the Aug 2026 flagship. Hero cache read $0.23 (list $0.25), cache write $2.25 (list $2.50). |
| Qwen3.8 27B | alibaba/qwen3.8-27b | $0.50 / $3 | 1M / 131.1K | Compact dense open-weight VLM. Vision and reasoning. No discount shown. |
| Qwen3.8 Omni Flash | alibaba/qwen3.8-omni-flash | $0.15 / $0.47 | 1M / 131.1K | Text, image, audio, and video input. Text output. No discount shown. |
| Qwen3.8 Max Prime | alibaba/qwen3.8-max-prime | $4 / $12 | 1M / 131.1K | Faster serving of the same Max model, about 1.5–2× tokens per second per the card. No discount shown. Higher price, so not a primary route. |
| Qwen3.8 2.4T A95B | alibaba/qwen3.8-2.4t-a95b | $2 / $6 | 1M / 52.4K | Open-weight Max-class sparse MoE. Chat, reasoning, structured output, function calling. Vision is not on the Facts list. |
| Qwen3.8 Flash | alibaba/qwen3.8-flash | $0.15 / $0.47 | Context not printed in the .md Facts block | Chat, vision, reasoning, structured output, function calling. No context window is invented here. |
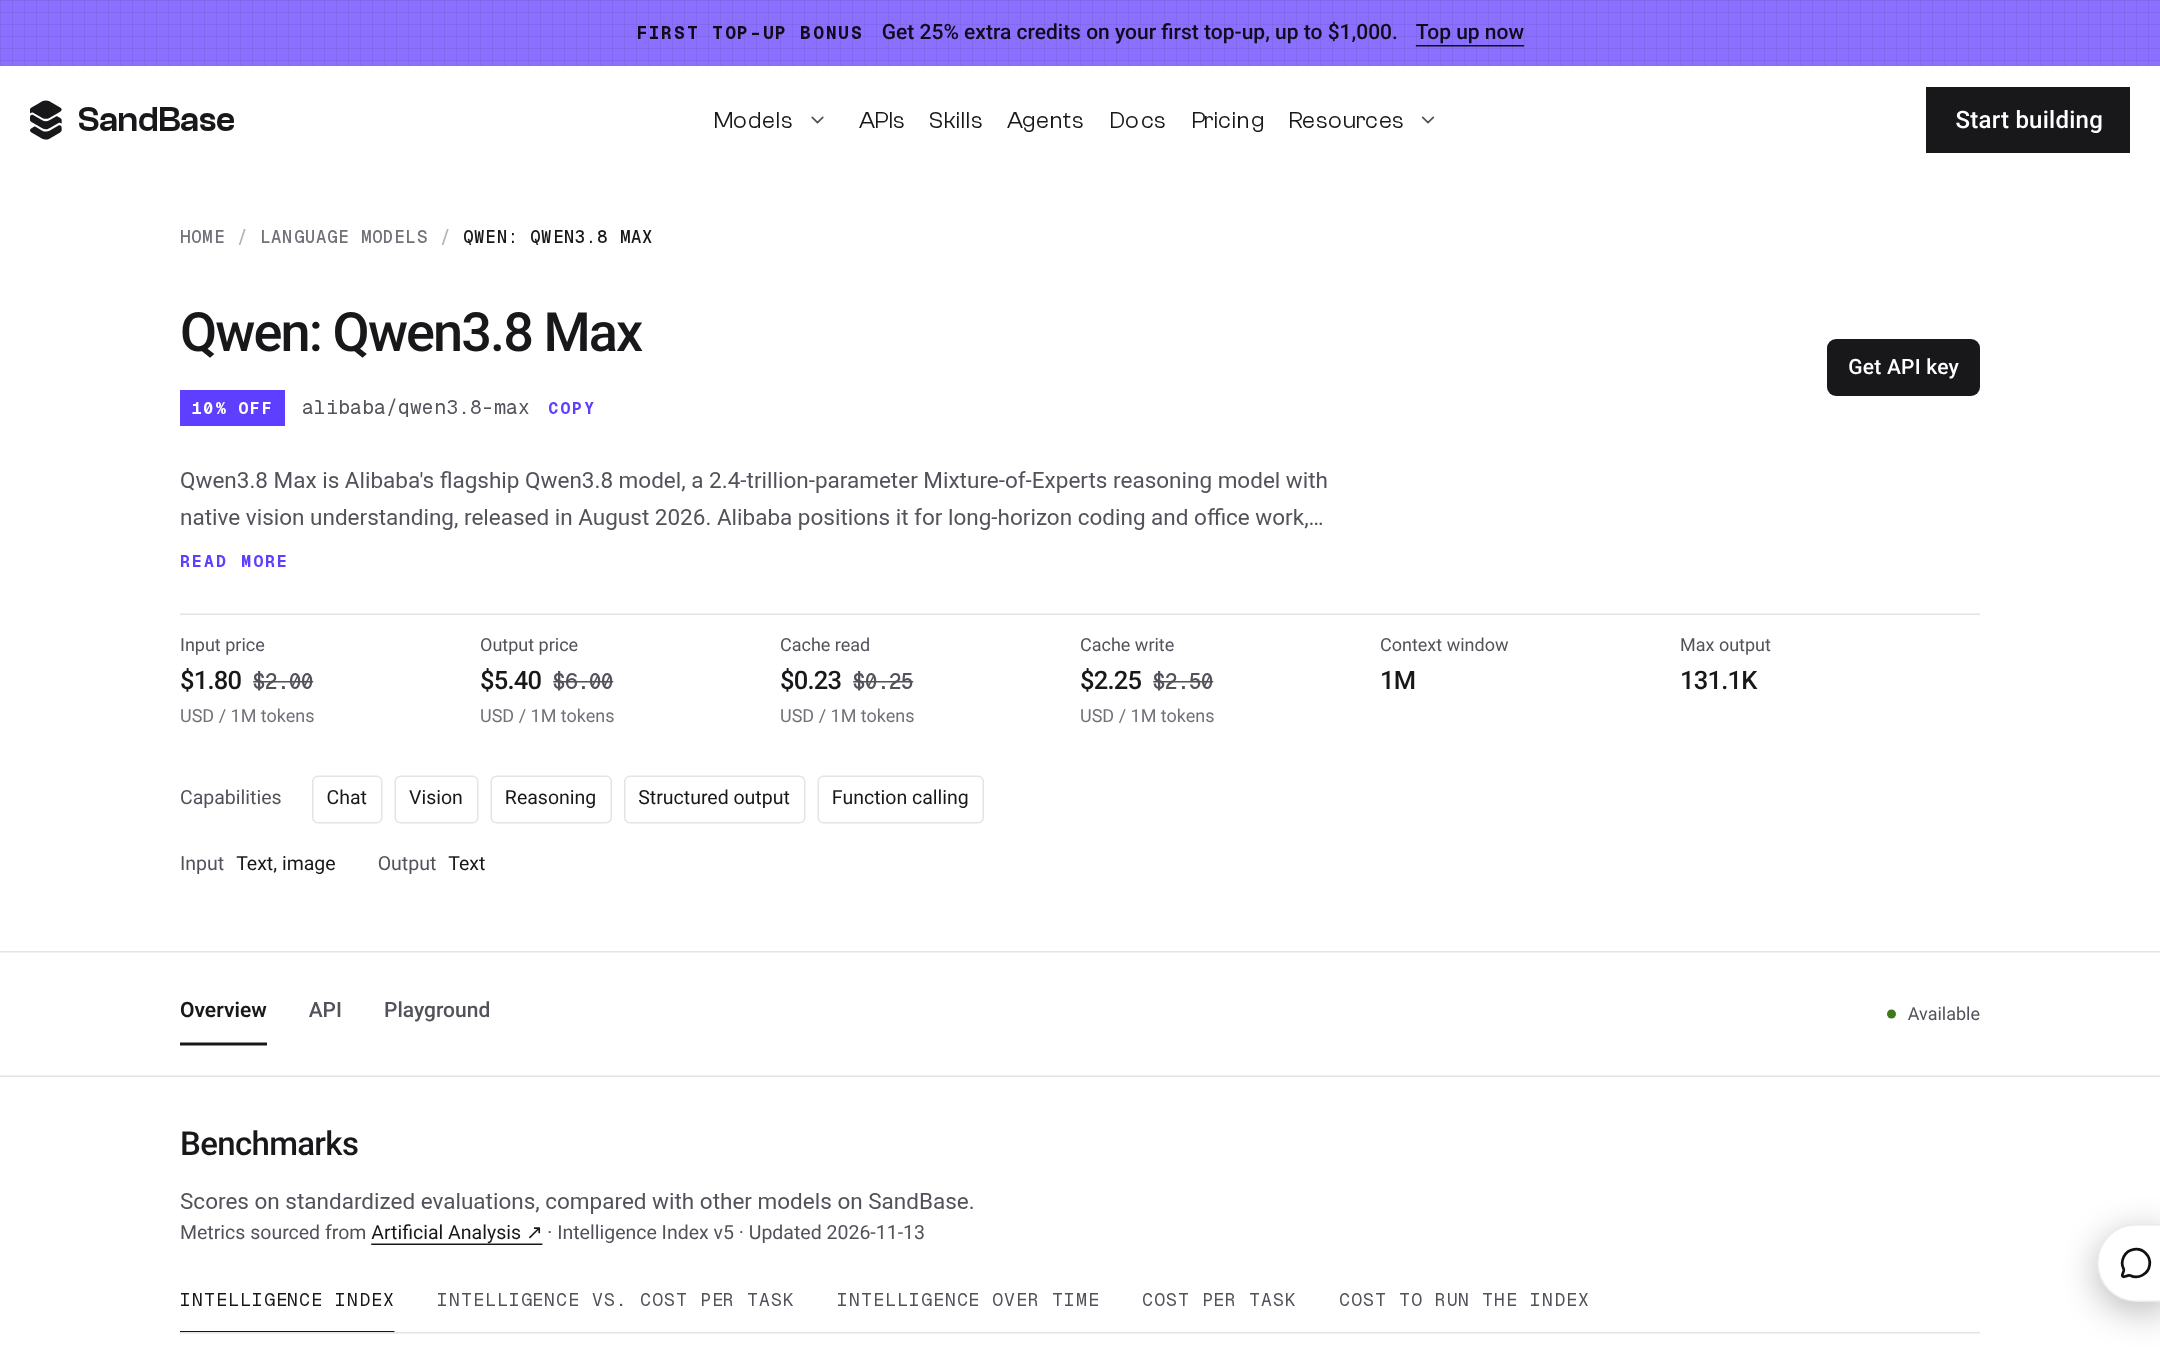
Live SandBase Qwen3.8 Max card at /models/alibaba/qwen3.8-max, captured 15 Nov 2026, Asia/Shanghai (HTML and .md both HTTP 200). Hero is $1.80 / $5.40 (10% off the $2 / $6 list), with cache read $0.23 and cache write $2.25 per 1M tokens. On this 15 Nov capture there was no Qwen4 card on SandBase. As of 16 Nov 2026, alibaba/qwen4-max is live; see the update at the top.
The struck list prices on that hero are $2.00 and $6.00. The current prices are $1.80 and $5.40, with cache read $0.23 and cache write $2.25 per 1M tokens. That 10% belongs to this card. Qwen3.8 27B, Qwen3.8 Omni Flash, and Qwen3.8 Max Prime showed no discount badge this evening.
Qwen3.8 27B is the compact dense VLM at $0.50 / $3. Qwen3.8 Omni Flash at $0.15 / $0.47 takes text, image, audio, and video in, and returns text. The preview’s official input list is text, images, and video, with no audio-input claim. Qwen3.8 Max Prime is faster serving of the same Max model at $4 / $12, so it is not the default. Qwen3.8 2.4T A95B is $2 / $6 with a 52.4K output cap, and its Facts list does not include vision. Qwen3.8 Flash uses the same $0.15 / $0.47 sticker. Its Facts block did not print a context window, so none is stated.
How to call them
Live language-model cards in this table use POST https://api.sandbase.ai/v1/chat/completions. /v1/run is the media route. These IDs do not go there.
No paid run was required. The example targets a live ID, alibaba/qwen3.8-max, because that is the flagship card, and because the price has to be quoted with the 10% off still attached. Swap in alibaba/qwen3.8-27b or alibaba/qwen3.8-omni-flash when that is the card you mean. The example below keeps the 15 November ID. The 16 November production string is alibaba/qwen4-max.
curl -X POST https://api.sandbase.ai/v1/chat/completions \
  -H "Authorization: Bearer $SANDBASE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "alibaba/qwen3.8-max",
  "messages": [
    {"role": "user", "content": "Hello"}
  ],
  "max_tokens": 2048
}'
Sign in is where /signup redirects. Create a key, then follow the first API call doc, which uses chat completions. The three cards to open first are Qwen3.8 Max, Qwen3.8 27B, and Qwen3.8 Omni Flash.
What we checked before calling it generally available
As of 16 November 2026 those checks have a result: Qwen4-Max is a generally available model with pay-as-you-go, a public per-token price, and a SandBase card that returns HTTP 200 for alibaba/qwen4-max. The list below is the method this page used on 15 November. The preview model’s retirement clock is unchanged.
- An official changelog entry or a model page that presents a Qwen4 model outside this preview: a pay-as-you-go API, or a non-preview GA entry.
- A public per-token price row for that ID. A Credits percentage is not that row.
- After those exist, a fresh GET of the SandBase HTML card and the matching
.md. Both have to return HTTP 200 before any catalog URL is added here. A 404 is not a link to publish. - The clock time 25 November 2026, 24:00 UTC+8 stays the scheduled retirement of this preview model unless a later official page says otherwise. It is not a promised GA day.
The 15 November SandBase IDs in the table above remain callable. New production uses alibaba/qwen4-max. The preview, if you still evaluate it, stays on Alibaba’s Token Plan, with an exit planned before the retirement. The 13 November guide is the place for that exit plan.
FAQ
Is Qwen 4 out?
As of 16 November 2026, Qwen4-Max (qwen4-max) is generally available with pay-as-you-go and live on SandBase as alibaba/qwen4-max. The preview ID qwen4-max-preview is still on Token Plan until 24:00 on 25 November 2026 (UTC+8), then scheduled to be retired. The evening of 15 November 2026 is when this page recorded the preview as not yet generally available and not yet on SandBase.
What is the API model ID?
On Alibaba’s GA API the ID is qwen4-max. On SandBase, as of 16 November 2026, send alibaba/qwen4-max. The preview ID on Token Plan remains qwen4-max-preview. The 15 November live IDs alibaba/qwen3.8-max, alibaba/qwen3.8-27b, and alibaba/qwen3.8-omni-flash are still on the account.
What can I call on SandBase today?
As of 16 November 2026, Qwen4 Max at alibaba/qwen4-max. The 15 November cards remain live: Qwen3.8 Max at $1.80 / $5.40 per 1M, which is 10% off the $2 / $6 list, with cache read $0.23 and cache write $2.25; Qwen3.8 27B at $0.50 / $3; Qwen3.8 Omni Flash at $0.15 / $0.47. Endpoint: POST https://api.sandbase.ai/v1/chat/completions.
Is 25 November 2026 the GA date?
No. Official copy says this preview model will be retired after 24:00 on 25 November 2026 (UTC+8). Qwen4-Max general availability is a separate event, dated 16 November 2026, with its own changelog entry, its own price row, and the SandBase ID alibaba/qwen4-max. This page does not treat 25 November as that day.
Is there a public price for the preview?
No dollar-per-million pay-as-you-go price was on the official pages from the 15 November 2026 check. The published figures are Credits promotions: as low as 20% of the standard rate, and 8% of the standard rate between 22:00 and 08:00. Do not quote those percentages as a $/1M tariff.
Sources
Confirmed on 15 November 2026, Asia/Shanghai: the QwenCloud latest-model page, Model Studio releases (last updated 11 Nov 2026), Token Plan product updates (last updated 13 Nov 2026), and the Token Plan team overview. The official Qwen Hugging Face org search for Qwen4 returned 0 models; the newest official uploads visible were still Qwen3.8, including Qwen/Qwen3.8-2.4T-A95B dated 7 Nov 2026. Live SandBase cards linked above returned HTTP 200 on HTML and markdown the same evening. Candidate Qwen4 paths returned 404 on both at 20:35. The 13 November access guide is the migration writeup this note points to and does not replace. The Qwen 3.8 Max flagship post is the long page for the 15 November incumbent. The 16 November call is in the update at the top.
Reported only, and not used for official names, IDs, or prices: October conference writeups that mention Qwen4-Plus, Qwen4-Flash, or Qwen4-27B; unofficial “Qwen4-27B” repositories outside the Qwen org; syndication of an 11 November teaser that also names QwenWork, Qoder, Qwen APP, and QwenStudio; older database rows that listed a June 2026 Qwen 4. The original social post was not re-fetched.
For a live card, open Qwen4 Max. The 15 November alternatives remain Qwen3.8 Max at the hero’s 10% off, Qwen3.8 27B, and Qwen3.8 Omni Flash.
Sources checked 15 November 2026, Asia/Shanghai. Official pages for the preview name, ID, window, specs, and Credits promotion. SandBase cards for prices you can actually call. Third-party names only inside the “not released” section.
Found this useful? Share it