Qwen4-Max Is Generally Available: Official PAYG Pricing, Limits, and How to Call It on SandBase
Qwen4-Max is generally available as of 16 Nov 2026. Official Singapore PAYG is $1.50 / $4.50. Call alibaba/qwen4-max on SandBase at $1.67 / $5.00.
On 16 November 2026, Qwen4-Max stopped being a preview question. Alibaba published it as the first model in the Qwen4 family, turned on pay-as-you-go, and the SandBase card for alibaba/qwen4-max is live. If you are wiring a new production call today, that ID is the one to send. The preview ID is still on a clock, and it is the wrong default.
The official launch post is Qwen4-Max: Your New Teammate Has Arrived, dated 2026/11/16, QwenTeam. The spec page that owns context, output caps, and the Singapore free-token note is the QwenCloud latest-model page. The 15 November status note, Is Qwen 4 Out?, and the 13 November access guide stay as the preview record. Whether to move traffic off Qwen3.8 Max is Qwen4-Max vs Qwen3.8 Max. What you can put next to Gemini 4 Carbon, GPT-6 Astra, and Claude Fable 5.2, now that a public price exists, is the 16 November flagship comparison.
Key takeaway
- Qwen4-Max (
qwen4-max) is generally available as of 16 November 2026. Pay-as-you-go is supported. On SandBase the ID isalibaba/qwen4-max, viaPOST https://api.sandbase.ai/v1/chat/completions.- Official context is 1,000,000 tokens. Official max output is 131,072 in non-thinking mode and 262,144 for thinking plus the final answer. The preview’s 393,216 cap is not the GA limit.
- Official Singapore (International) PAYG is $1.50 input and $4.50 output per 1M tokens. Beijing and Global are $1.413 / $4.24. The SandBase hero is $1.67 / $5.00, cache read $0.08, cache write $2.08, with no 10% off.
- Thinking is on by default.
reasoning_effortdefault is nowhigh. The separate preview modelqwen4-max-previewstill retires after 24:00 on 25 November 2026 (UTC+8).- Official API docs still do not print a parameter count. Fine-tuning, model deployment, and batch inference are not supported for this model.
Update (16 Nov 2026): A same-day SandBase streaming probe measured time to first token, time per output token, decode throughput, and prompt-cache hit rate for
alibaba/qwen4-maxagainstalibaba/qwen3.8-max. It is a single-box, single-day gateway measurement, not official vendor latency. The numbers and the method are in Qwen4-Max vs Qwen3.8 Max: Measured TTFT, TPOT, Throughput, and Cache Hit Rate on SandBase.
What shipped on 16 November
Qwen4-Max is the first model in the Qwen4 family. Official model pages list input as text, image, and video, and output as text. Thinking is on by default. Pay-as-you-go is now a supported access path. Token Plan Personal and Team also list the GA model, per the Token Plan product updates page, last updated 16 November 2026. The Model Studio newly released models page carries an International entry for 2026-11-16, and the QwenCloud model changelog records qwen4-max on the same date.
Official Qwen launch blog at qwen.ai/blog?id=qwen4-max, captured 16 Nov 2026, Asia/Shanghai. The post is titled “Qwen4-Max: Your New Teammate Has Arrived,” dated 2026/11/16, and the hero states that Qwen 4 is now available.
The launch blog is a vendor essay, not the API reference. It says Qwen4-Max is built on the new Qwen4 architecture, “with a 2.4-trillion-parameter backbone, native vision capabilities, and a one-million-token context window.” In the pre-training section it adds “2.4T backbone parameters, 71B activated per token, and an additional 328B N-gram Embedding parameters,” plus GDN + Qwen Sparse Attention (QSA), Gated Residual, and N-gram Embedding. Those counts belong to the blog. The Alibaba Qwen4-Max docs and the QwenCloud latest-model page, both last updated 16 November 2026, still do not state a parameter count. Quote the blog as the blog.
The same post says the model is available on QwenCloud, and that you can start with either the Token Plan or the API. It also names QwenWork, Qoder, and QwenStudio. The closing line is future tense: smaller models in the family are “coming to open source.” That sentence is not a shipping list.
Regions named on the latest-model page: Singapore (International), China North 2 (Beijing), Frankfurt, Hong Kong, Tokyo, and US Virginia (Global). Beijing and Global share one price row. Singapore has its own. Built-in tools listed there include function calling, structured output, web search, PDF understanding, code interpreter (thinking required), web scraping, text-to-image and image-to-image search, MCP, explicit cache, and CoT Summary. Streaming, parallel tool calls, prefix completion, and implicit caching are also listed as supported. Fine-tuning and model deployment are not supported, in every region the page lists.
How to call it on SandBase
Open Qwen4 Max. The SandBase ID is alibaba/qwen4-max. The endpoint on that card is Chat Completions:
curl -X POST https://api.sandbase.ai/v1/chat/completions \
  -H "Authorization: Bearer $SANDBASE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "alibaba/qwen4-max",
  "messages": [
    {"role": "user", "content": "List the official Qwen4-Max output caps, and name which one the SandBase hero matches."}
  ]
}'
Sign up redirects to the login page. Create a key, then follow the first API call doc. The model string in the body is alibaba/qwen4-max, not the bare official ID and not the preview ID.
Thinking stays on unless you turn it off. Official reasoning_effort values are low, high, and xhigh. The default is now high. medium maps to high, minimal maps to low, and max maps to xhigh. That default moved: the preview’s default was xhigh. thinking_budget defaults to 131,072. preserve_thinking defaults on. In Chat Completions, enable_thinking=false turns thinking off. max_completion_tokens limits thinking and the final answer together. The documented defaults are 262,144 when thinking is on and 131,072 when it is off. A cap copied from a short-answer habit will cut the trace before the answer exists. Re-check any agent that still sends the preview’s xhigh default, or that sizes max_tokens as if it covered only the visible reply.
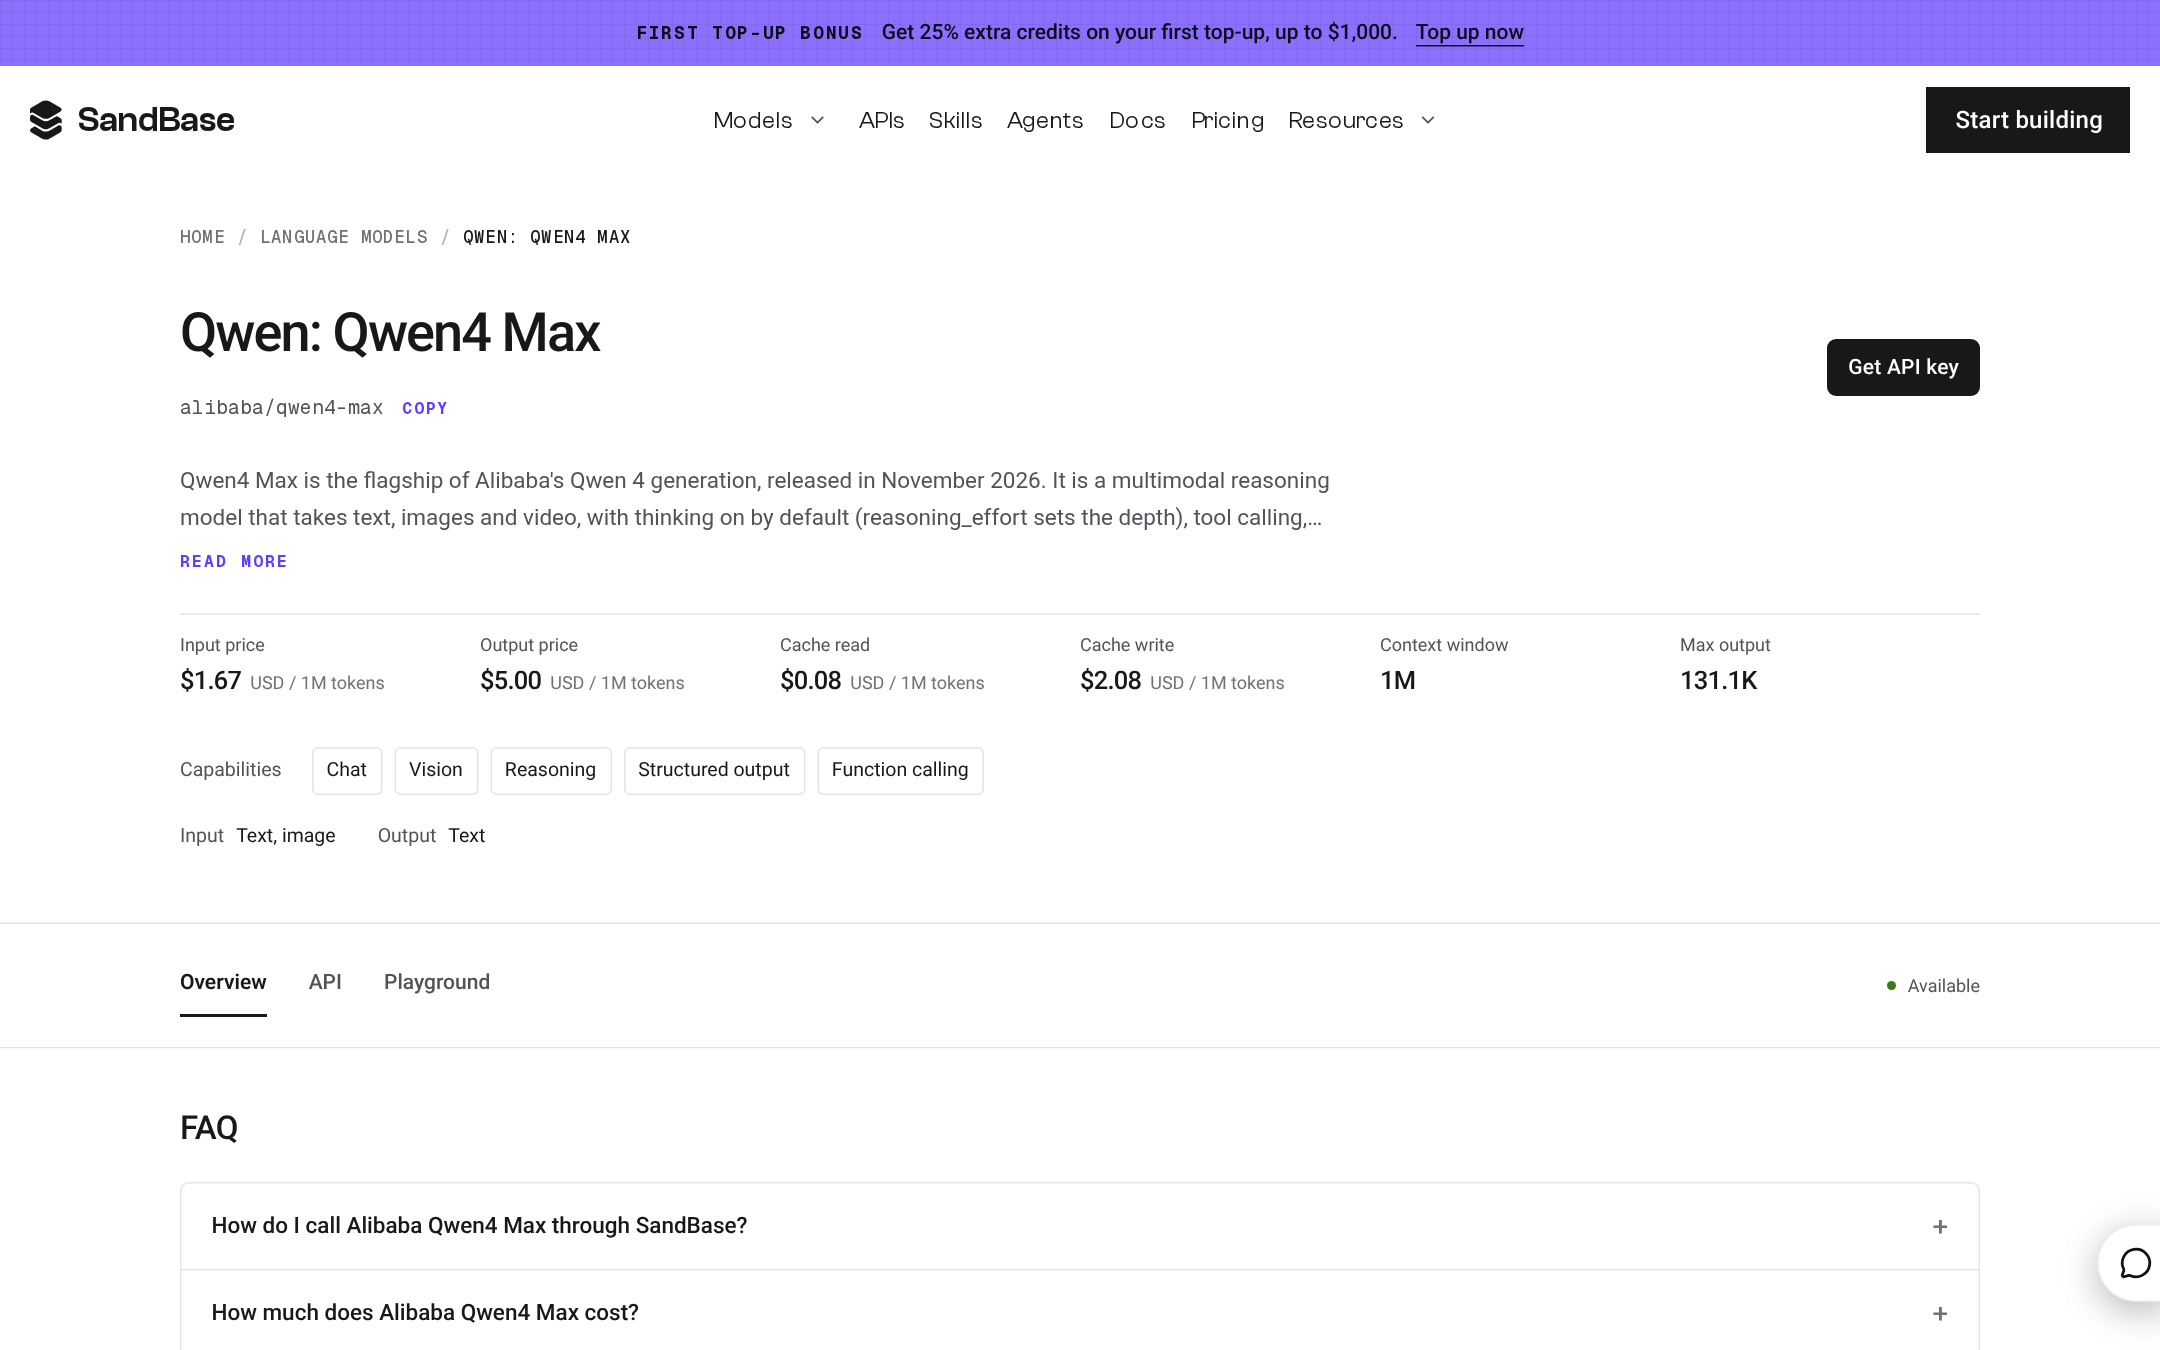
Live SandBase Qwen4 Max card at /models/alibaba/qwen4-max, captured 16 Nov 2026, Asia/Shanghai (HTML and .md both HTTP 200). Hero is $1.67 / $5.00, with cache read $0.08 and cache write $2.08 per 1M tokens, 1M context, and 131.1K max output. There is no 10% off badge. These SandBase prices are above the official Singapore list of $1.50 / $4.50, and above official Beijing / Global $1.413 / $4.24, but still below SandBase Qwen3.8 Max at $1.80 / $5.40. The card hero max output of 131.1K matches the official non-thinking cap; the card description still incorrectly says “up to 393K output tokens shared by thinking and the answer,” which is a preview leftover, not the official GA limit.
The card title is “Alibaba Qwen4 Max API: Pricing & Specs | SandBase”. Capabilities listed: chat, vision, reasoning, structured output, function calling. The hero context is 1M. The hero max output is 131.1K. The schema input price is 1.666667, which is the $1.67 the hero prints. There is no strikethrough list price and no 10% off badge. The card is also in the sitemap and in llms-full.txt.
If you are not ready to retune agents onto a new default effort, keep the call on Qwen3.8 Max. That hero is still $1.80 / $5.40, 10% off the $2 / $6 list, with cache read $0.23 and cache write $2.25. It is a higher SandBase sticker than Qwen4-Max, and it is the proven baseline. The switch criteria are in the comparison post linked above.
Official limits, and the 393K leftover
Read the latest-model page for the caps. Then read the card hero. Then ignore any leftover sentence that still says 393K.
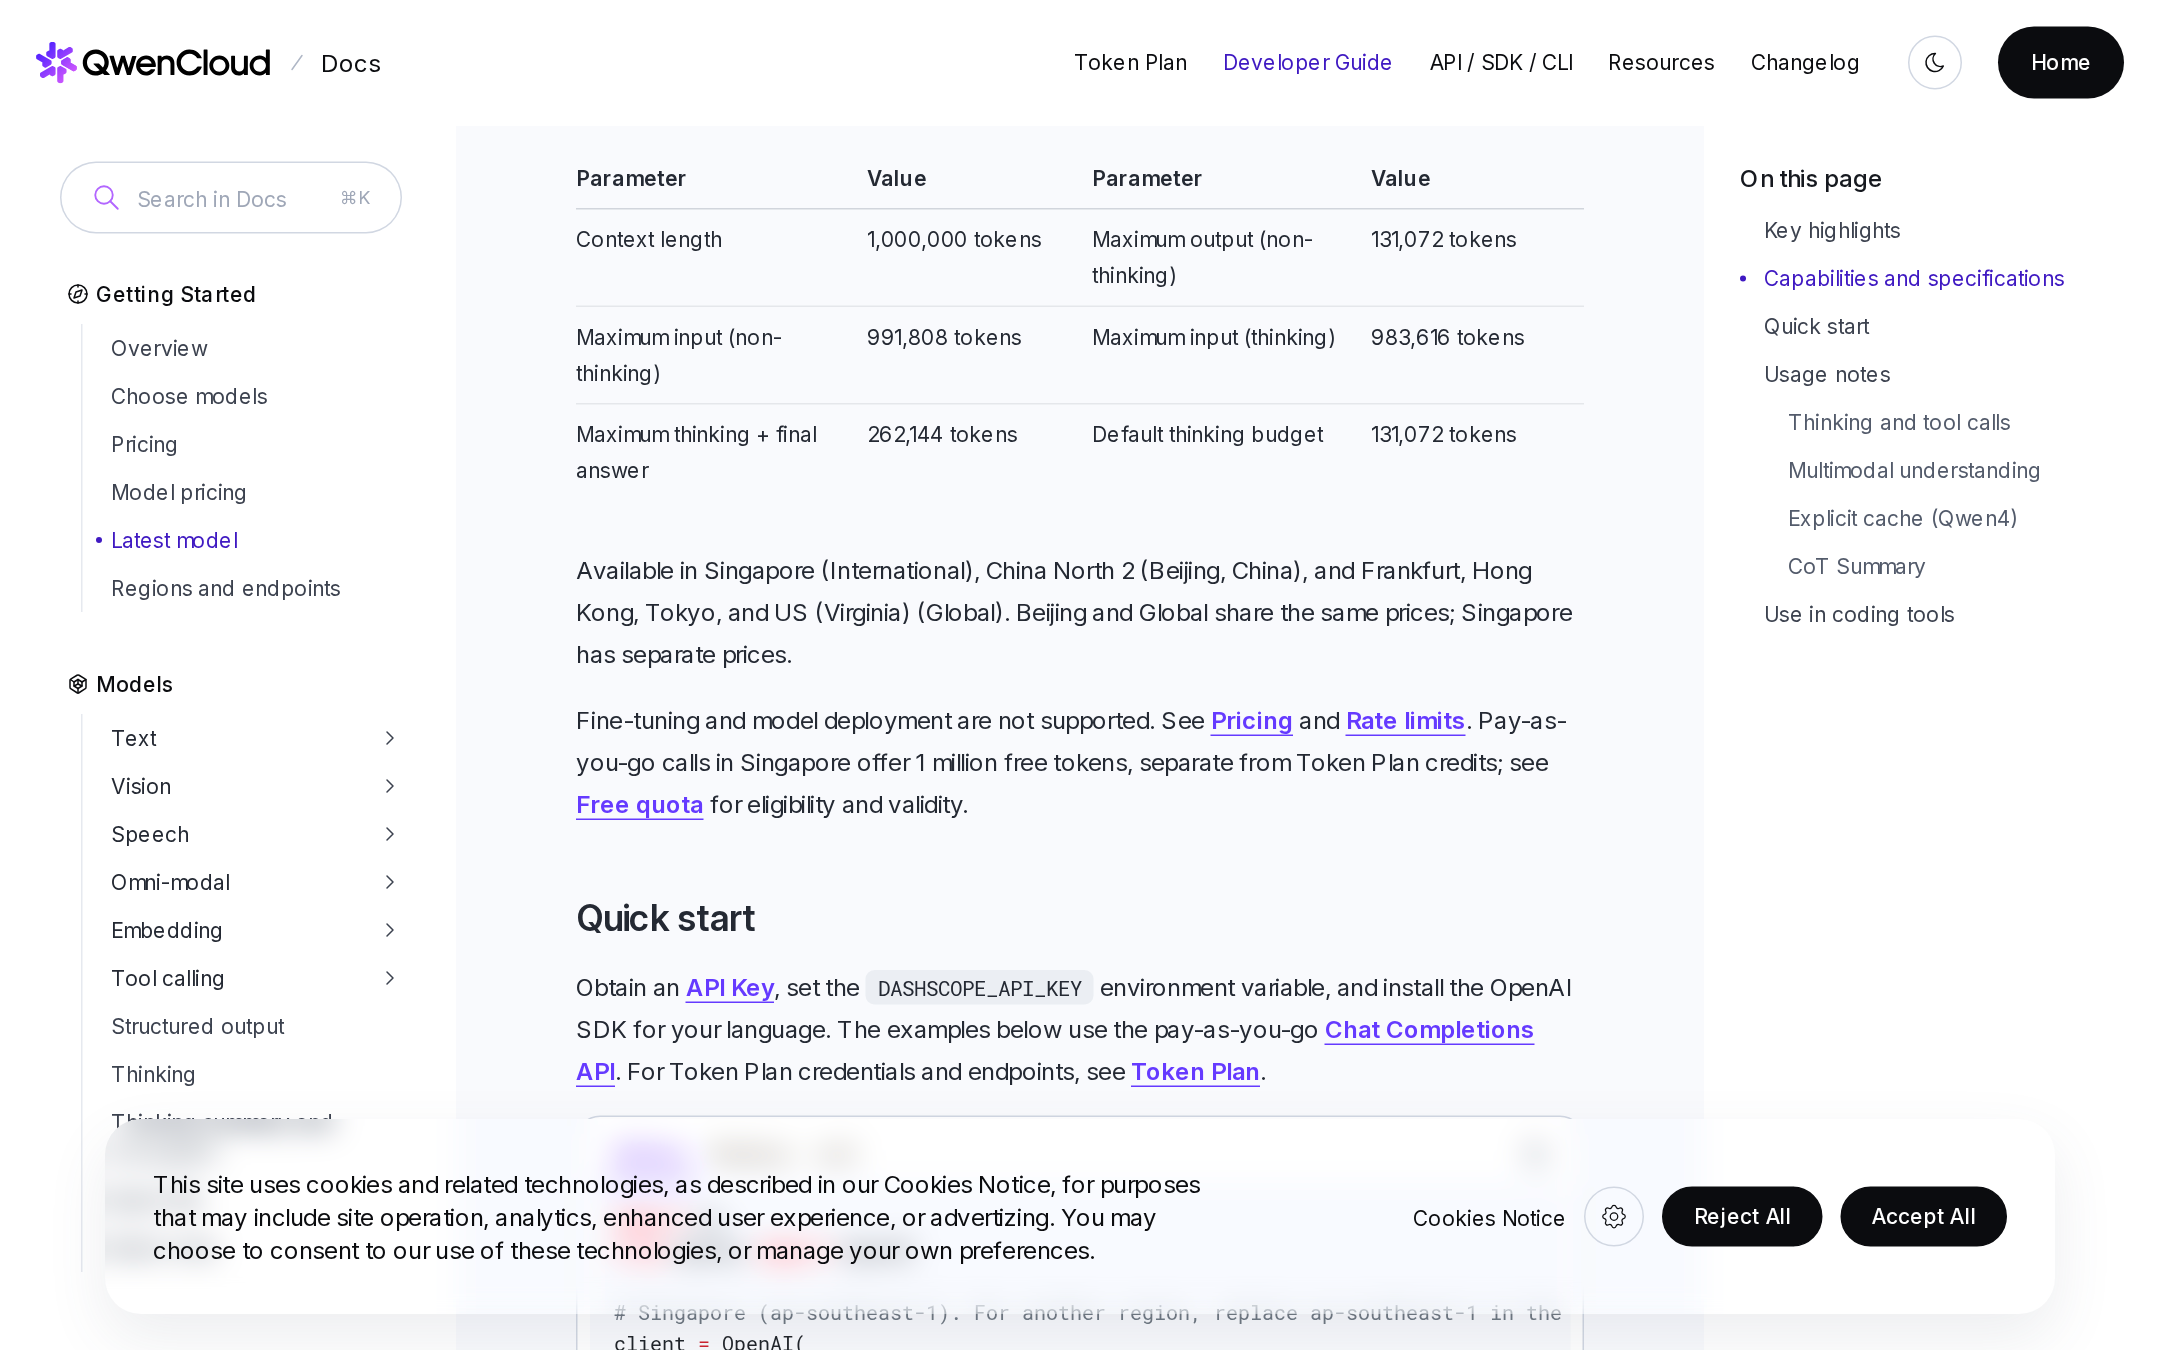
Official QwenCloud latest-model page as of 16 Nov 2026, Asia/Shanghai. Official GA limits are 1,000,000 context, 131,072 maximum output (non-thinking), and 262,144 maximum combined thinking plus final answer. The same page states that fine-tuning and model deployment are not supported, and that pay-as-you-go calls in Singapore offer 1 million free tokens. (A site cookie banner is visible at the bottom of this capture and does not cover the limits table.)
| Limit | Official GA value |
|---|---|
| Context | 1,000,000 tokens |
| Max output, non-thinking | 131,072 |
| Max combined thinking + final answer | 262,144 |
| Max input, non-thinking | 991,808 |
| Max input, thinking | 983,616 |
| Default thinking budget | 131,072 |
Default reasoning_effort | high |
The SandBase hero’s 131.1K matches the official non-thinking cap. It does not print the 262,144 combined ceiling. If your client thinks, budget against 262,144, and confirm the host you call will accept a completion cap that high. The card description still says “up to 393K output tokens shared by thinking and the answer.” That sentence is a preview leftover. It is not the official GA limit, and it disagrees with the hero on the same card.
The QwenCloud marketplace page still shows Max Output 393K, Max Output (Thinking) 393K, and Max Reasoning 262K, plus a Batches tile. Treat that page as a conflict. The authoritative limits are the latest-model page, the Alibaba Qwen4-Max page, and the text generation and visual understanding table, all updated 16 November 2026. That table lists qwen4-max as a recommended model when you are prioritizing quality, with max output “131,072 (Non-thinking); 262,144 (thinking + output)”, 1M context, 16M max pixels per image, and a 2-hour max video duration. qwen4-max-preview and the 393,216 cap are gone from the table.
Batch inference is not supported for qwen4-max. The Alibaba model page says so for China (Beijing), Singapore (International), and every listed Global region (Frankfurt, Virginia, Tokyo, Hong Kong). The QwenCloud latest-model page says “Batch inference: Not supported,” with no regional exception. A generic “Batch API — 50% of real-time pricing” bullet on the pricing page is a general billing factor. It is not a statement that this model accepts batch jobs.
Official price versus the SandBase card
Thinking and non-thinking use the same unit price. There are no input-length tiers. Thinking tokens are billed as output: the official label is “Output (thinking + answer).” Official pages often print $1.5 and $4.5. Those are the same figures as $1.50 and $4.50.
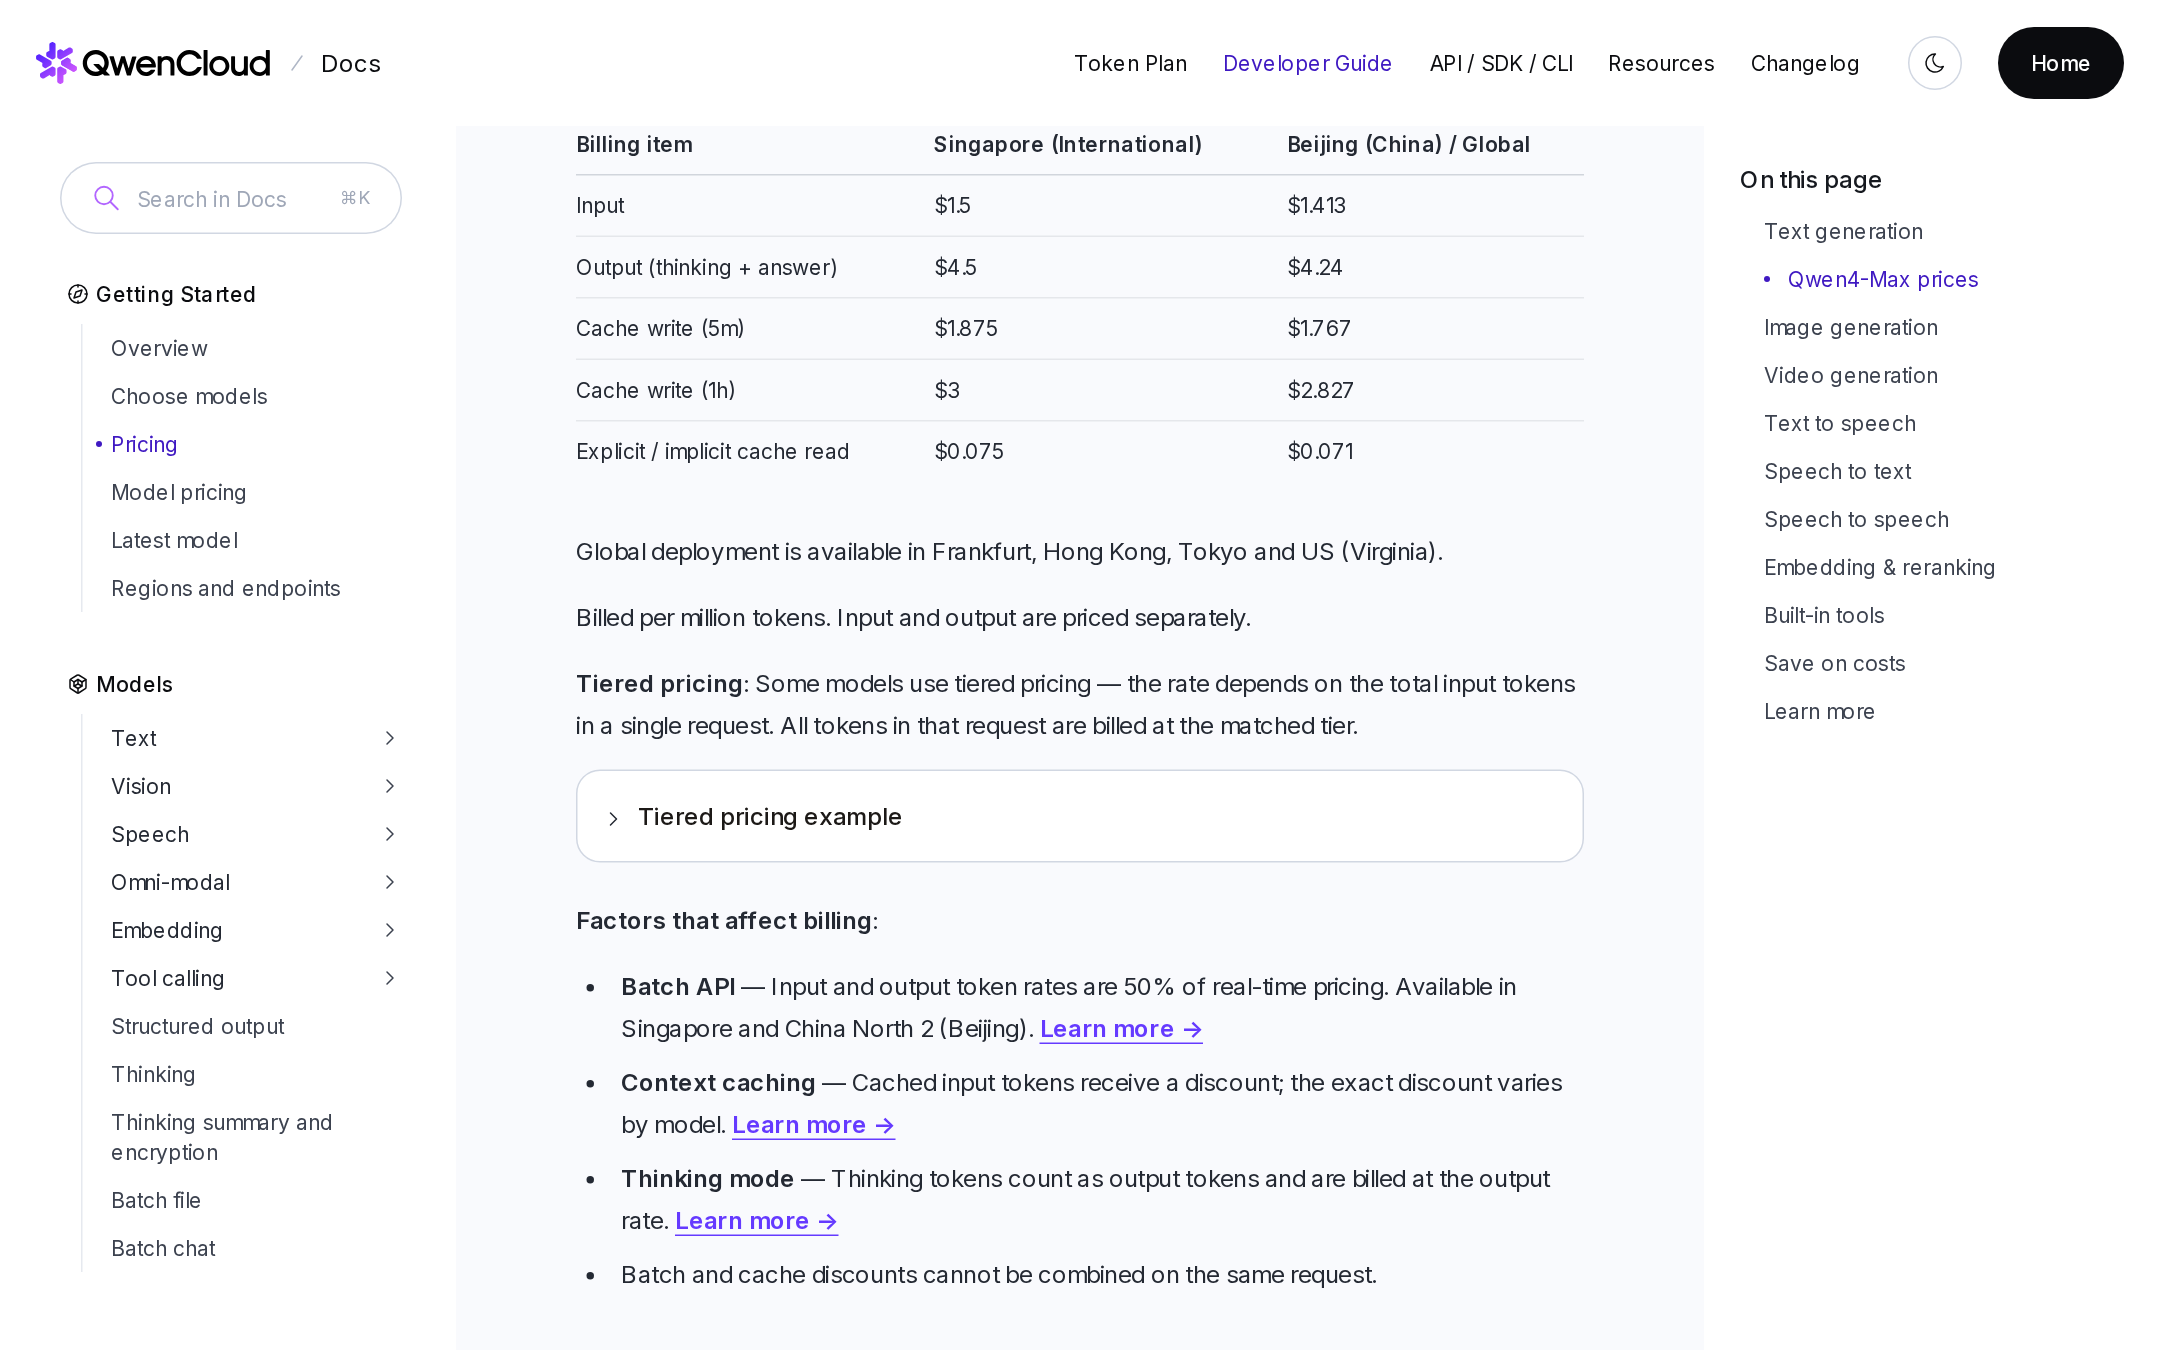
Official QwenCloud pricing page, captured 16 Nov 2026, Asia/Shanghai. Singapore (International) list is $1.5 / $4.5 per 1M tokens (the page prints $1.5 / $4.5, equivalent to $1.50 / $4.50), with cache write $1.875 (5m) / $3 (1h) and cache read $0.075. Beijing / Global is $1.413 / $4.24, with cache write $1.767 / $2.827 and cache read $0.071. The page states that thinking tokens are billed at the output rate, and that Qwen4-Max has no input-length tiers. The “Batch API 50%” bullet on this page is a general billing factor — official Qwen4-Max model pages list batch inference as not supported for this model.
| Singapore (International) | Beijing / Global | SandBase card | |
|---|---|---|---|
| Input / 1M | $1.50 | $1.413 | $1.67 |
| Output / 1M | $4.50 | $4.24 | $5.00 |
| Cache read / 1M | $0.075 | $0.071 | $0.08 |
| Cache write / 1M | $1.875 (5m), $3 (1h) | $1.767 (5m), $2.827 (1h) | $2.08 (one write figure) |
| Discount | — | — | None. No 10% off badge. |
The SandBase hero sits above both official lists. It still sits below SandBase Qwen3.8 Max at $1.80 / $5.40. Official Singapore list for qwen3.8-max remains $2 / $6 on the model-prices page. Do not invent a SandBase 10% off for Qwen4-Max. The card does not show one.
Singapore pay-as-you-go calls on official QwenCloud offer 1 million free tokens, separate from Token Plan credits. Other regions do not, per the latest-model page and the pricing callout. That free-token offer is an official QwenCloud Singapore term. The SandBase card does not state a free-token grant, so this note does not invent one.
One number that looks identical and is not: the launch blog’s Work360 average cost per task falls from $4.43 to $1.67. That $1.67 is a vendor cost-per-task on one named evaluation. The SandBase $1.67 is the card’s input price per million tokens. They share digits. They are not the same measurement. The blog’s token and cost claims are quoted, with their benchmark names attached, in the switch post.
The preview is still a deadline
qwen4-max-preview still exists. Official Token Plan updates still describe the preview window from 10:00 on 11 November 2026 to 24:00 on 25 November 2026 (UTC+8), after which the preview model will be retired. The SandBase preview card, Qwen4 Max Preview, was still up on 16 November at $2.00 / $6.00, cache read $0.25 and cache write $2.50. The hero prints context window N/A and max output 131.1K. A playground widget on that page also prints “1M context.” Cite the hero: context is N/A. Do not fill in a SandBase context window the hero does not print. The description still mentions 393K output. The preview card is not in the sitemap or llms-full.txt.
Production traffic goes to alibaba/qwen4-max. The preview card is a warning, not a place to start a new client. Historical Token Plan setup stays in the 13 November access guide.
What is still unknown
Official docs do not list Qwen4-Plus, Qwen4-Flash, or Qwen4-27B as available APIs. The launch blog’s “coming to open source” line is a future statement. There are no live SandBase cards for those names, and this page does not invent URLs for them. Qwen4-Max-Prime is in the same bucket.
The Qwen hub is HTTP 200, and its title is still “Qwen API: Alibaba Qwen3.8, 3.7 and Open-Weight Models | SandBase”. The hero lineup still names Qwen3.8 Max, 27B, Omni Flash, and Qwen3.7 tiers. The page does not mention Qwen4. That is a stale hub. It is not evidence that the model is missing: the individual card is live, and the sitemap and llms-full.txt include it.
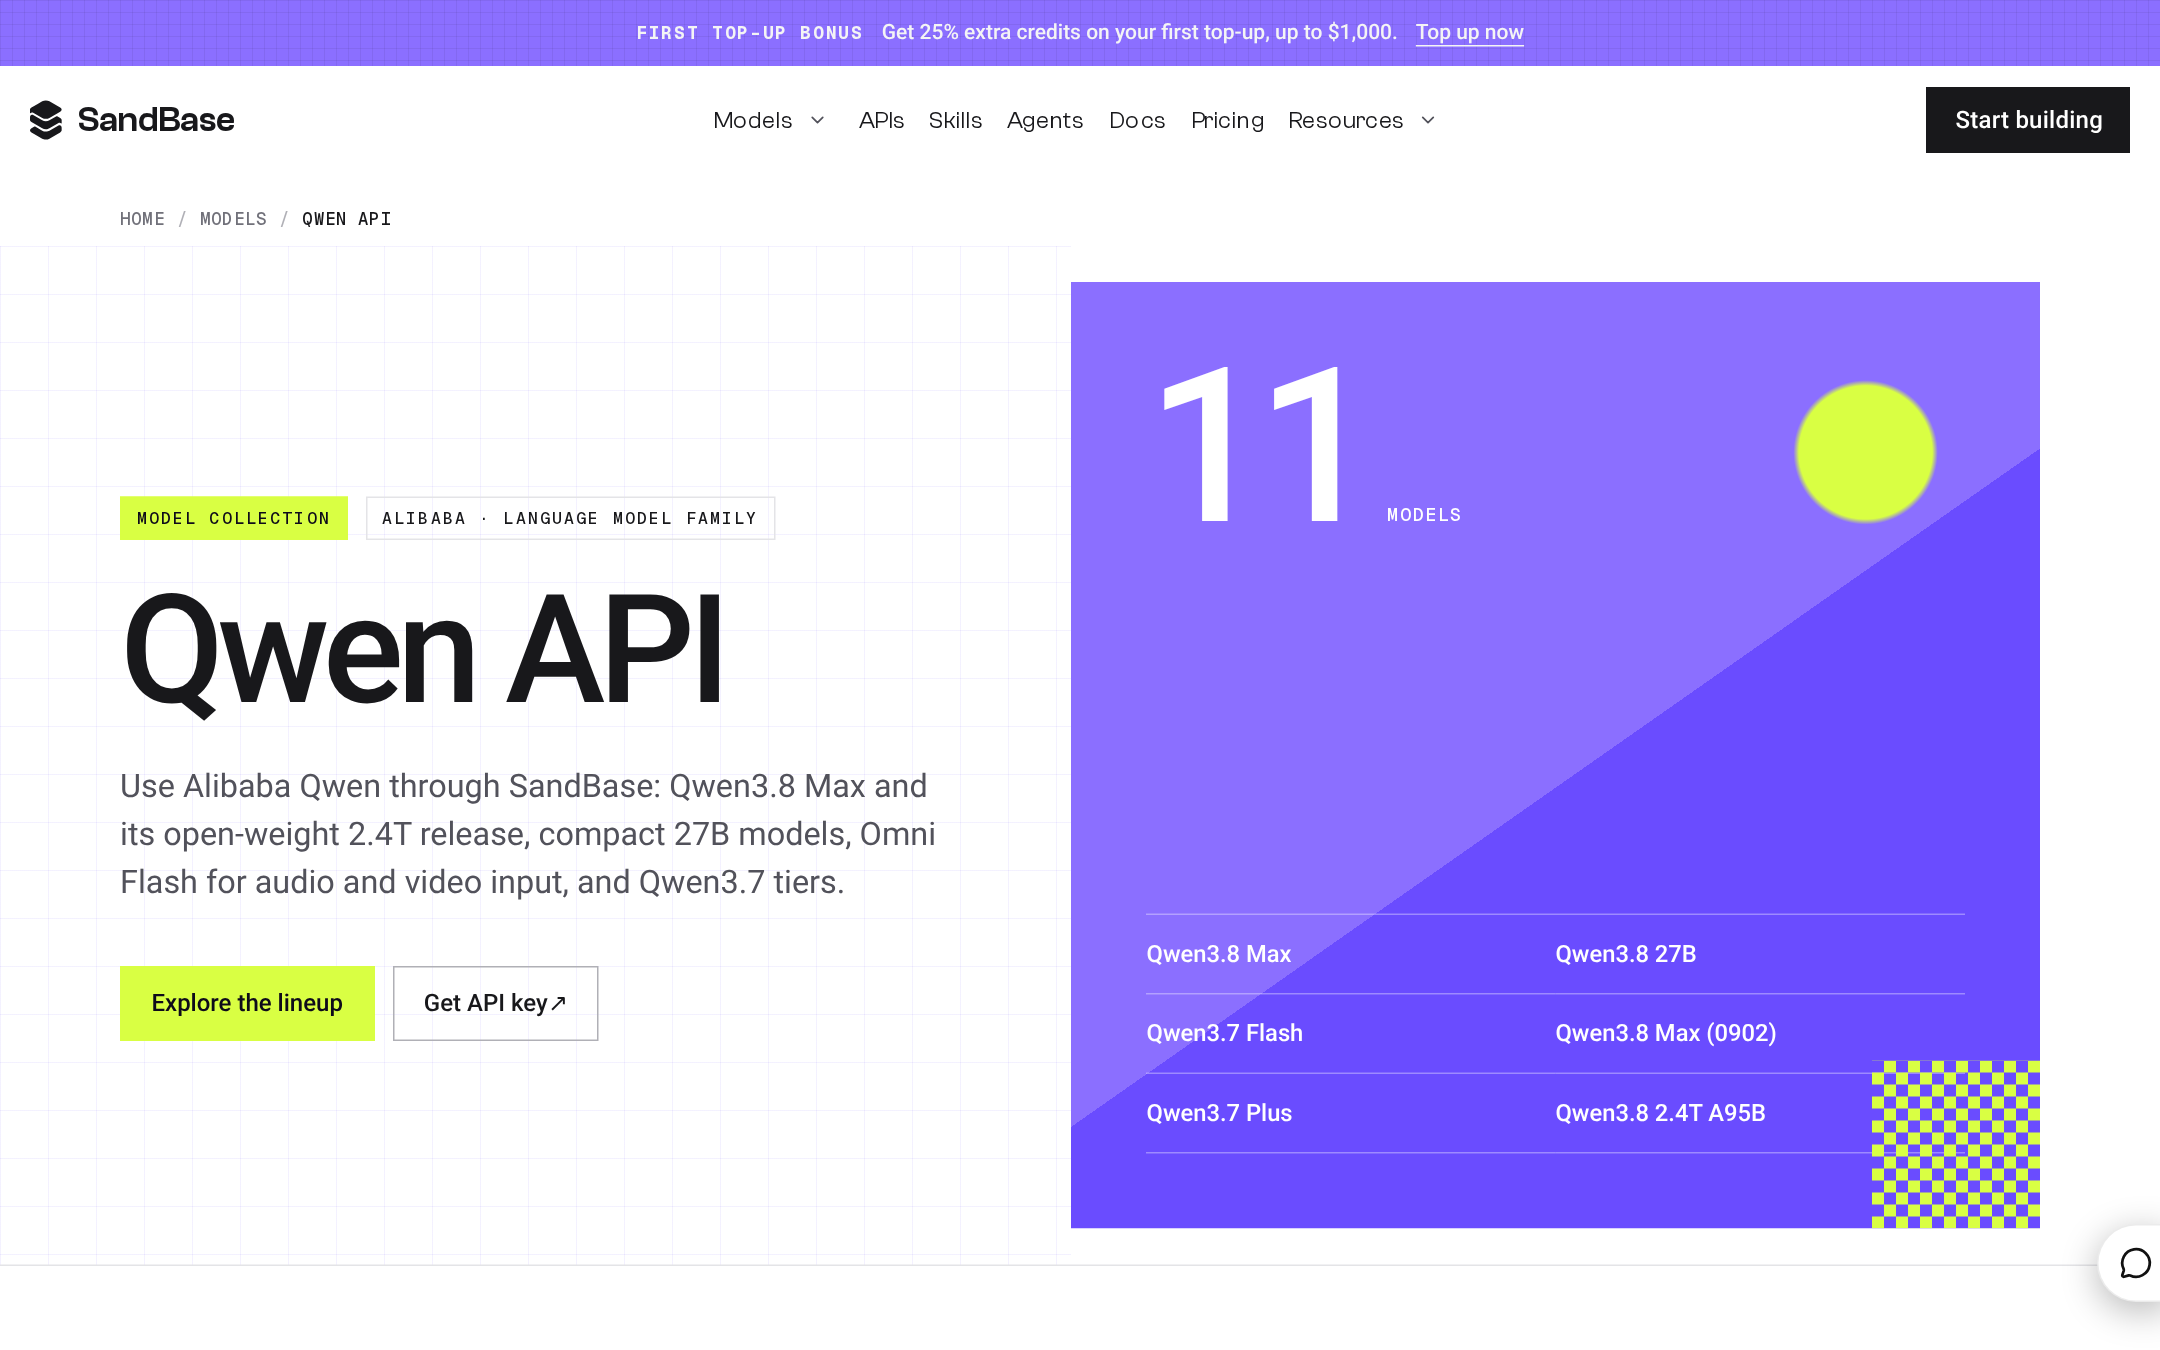
Live SandBase Qwen hub at /models/qwen, captured 16 Nov 2026, Asia/Shanghai. The page title and hero lineup are still Qwen3.8 / Qwen3.7 — they do not yet mention Qwen4-Max, even though the individual Qwen4-Max card is live and listed in the sitemap and llms-full.txt. Use this only to disclose the stale hub, not as a reason to say the model is missing from SandBase.
Also still unsupported, on the official model pages: fine-tuning, model deployment, and batch inference. Audio input is not an official Qwen4-Max claim. If the job needs audio in, the live SandBase path remains Qwen3.8 Omni Flash.
Confirmed versus unknown
| Confirmed on 16 Nov 2026 | Do not invent |
|---|---|
GA date, official ID qwen4-max, PAYG on | A SandBase 10% off for Qwen4-Max |
| Official limits 1,000,000 / 131,072 / 262,144 | Treating 393,216 as the official GA cap |
| Singapore $1.50 / $4.50; Beijing and Global $1.413 / $4.24 | Applying the generic Batch API 50% bullet to this model |
Thinking on; reasoning_effort default high | Shipped Qwen4-Plus, Qwen4-Flash, Qwen4-27B, or Qwen4-Max-Prime cards |
SandBase alibaba/qwen4-max at $1.67 / $5.00, cache $0.08 / $2.08 | A SandBase free-token offer, or a SandBase context for the preview hero that says N/A |
| Preview remains until 25 Nov 2026, 24:00 UTC+8 | Parameter counts as if they appeared in the API docs |
Vendor Work360 and Terminal-Bench figures may be cited only as claims on the official launch blog, with the benchmark name attached. They are not SandBase measurements.
FAQ
What ID do I send on SandBase?
alibaba/qwen4-max, to POST https://api.sandbase.ai/v1/chat/completions. The official API ID is qwen4-max. The preview ID is qwen4-max-preview, and new production should not start there.
Is the max output 131K or 262K?
Both, for different modes. Official non-thinking max output is 131,072. Official combined thinking plus final answer is 262,144. The SandBase hero prints 131.1K, which matches the non-thinking cap. The 393K figure on the card blurb and on the QwenCloud marketplace is a leftover conflict, not the official GA limit.
Why is the SandBase price above the official list?
The live hero on 16 November 2026 is $1.67 / $5.00, with no discount badge. Official Singapore list is $1.50 / $4.50. Official Beijing and Global list is $1.413 / $4.24. Cache figures differ too: the card prints a single write of $2.08 and a read of $0.08. Quote the host you will actually call.
Does Singapore’s 1 million free tokens apply on SandBase?
The official latest-model page and the pricing callout attach that grant to pay-as-you-go calls in Singapore on QwenCloud, separate from Token Plan credits. The SandBase card does not state it. Do not assume the grant transfers.
Can I batch qwen4-max at 50% off?
Official model pages say batch inference is not supported for this model, including in Beijing. The 50% batch bullet on the general pricing page is not a qwen4-max feature.
What to open
Call Qwen4 Max when the new flagship is the point of the change, and keep the official-versus-card price in the same sentence as the link. Stay on Qwen3.8 Max when you want the 10% off baseline and you have not re-validated agents against reasoning_effort=high and the new output caps. Create a key and run the first call against alibaba/qwen4-max before you move a queue.
Prices, limits, and card heroes checked 16 November 2026, Asia/Shanghai. Official QwenCloud and Alibaba Model Studio pages for GA specs and list prices. The SandBase hero for the sticker a call on SandBase uses. The launch blog only where a sentence is attributed to it.
Related reading
Found this useful? Share it