Qwen4-Max vs Gemini 4 Carbon, GPT-6 Astra, and Claude Fable 5.2: What You Can Compare Now That Pricing Is Public
Qwen4-Max now has public PAYG pricing and a SandBase card. Compare access, context, output, and official vs card prices with Carbon, Astra, and Fable 5.2.
Qwen4-Max has a public pay-as-you-go price and a live SandBase card as of 16 November 2026. That is what changed. It does not make this a “who is smarter” ranking. The comparison you can finish today is access, context, output limits, official versus SandBase price, and modalities, each labeled with its source.
Call Qwen4 Max when you want the new Alibaba flagship on SandBase. Call Gemini 4 Carbon, GPT-6 Astra, or Claude Fable 5.2 when the account is already standardized there, or when you need a modality or limit those vendors document and Qwen4-Max does not. How the Qwen4-Max call is shaped, including the 131,072 / 262,144 caps, is Qwen4-Max Is Generally Available. The 15 November preview comparison, at a different slug, is what you could compare while Qwen 4 was still preview-only. Sibling notes that already own the other three models: Gemini 4 Carbon on SandBase, what’s confirmed for Carbon, Carbon vs Argon vs Astra vs Opus, and Fable 5.2 vs Opus 5.5 vs Astra. This page does not paste those score tables again.
Key takeaway
- All four are generally available APIs with live SandBase cards. Qwen4-Max’s SandBase ID is
alibaba/qwen4-max. This is not a quality ranking.- Official Qwen4-Max context is 1,000,000. Official output is 131,072 non-thinking and 262,144 thinking plus the answer. The SandBase hero prints 1M / 131.1K.
- Official Carbon is a unified 1,048,576-token window, with a 65,536 single-segment streaming cap and a long-decode path. The SandBase hero prints 1M / 65.5K. Official intro price is $2 / $10 through 30 November 2026, then $4 / $20. The card already shows $4 / $20.
- Official Astra is $10 / $50, context 1,050,000, max output 128,000. The SandBase hero is $9 / $45 (10% off), cache read $0.90, cache write $11.25, and it prints 1.1M / 128K.
- Official and SandBase Fable 5.2 agree on $8 / $40 and on 1M / 128K. The card’s cache write of $10 matches the official 5-minute rate. Official 1-hour cache write is $16, and it is not on the card.
Update (16 Nov 2026): A same-day SandBase streaming probe measured TTFT, TPOT, throughput, and cache hit rate for Qwen4-Max versus Qwen3.8 Max only. It did not include Gemini 4 Carbon, GPT-6 Astra, or Claude Fable 5.2, and it is not a latency ranking of those models. The Qwen-only results are in Qwen4-Max vs Qwen3.8 Max: Measured TTFT, TPOT, Throughput, and Cache Hit Rate on SandBase.
Access, now that Qwen4-Max is a card
| Model | Official API ID | SandBase ID | SandBase route |
|---|---|---|---|
| Qwen4-Max | qwen4-max | alibaba/qwen4-max | POST https://api.sandbase.ai/v1/chat/completions |
| Gemini 4 Carbon | gemini-4-carbon | google/gemini-4-carbon | POST https://api.sandbase.ai/v1/chat/completions |
| GPT-6 Astra | gpt-6-astra | openai/gpt-6-astra | POST https://api.sandbase.ai/v1/responses and POST https://api.sandbase.ai/v1/chat/completions |
| Claude Fable 5.2 | claude-fable-5-2 | anthropic/claude-fable-5.2 | POST https://api.sandbase.ai/v1/chat/completions and /v1/messages |
Carbon’s own docs, last updated 2026-11-13 UTC, are where enterprise-region availability is spelled out. That vendor note does not take the SandBase card offline. google/gemini-4-carbon was HTTP 200 on 16 November 2026, HTML and the card itself. Qwen4-Max-Preview (alibaba/qwen4-max-preview) is a side warning only: it still retires after 24:00 on 25 November 2026 (UTC+8). New Qwen production uses alibaba/qwen4-max.
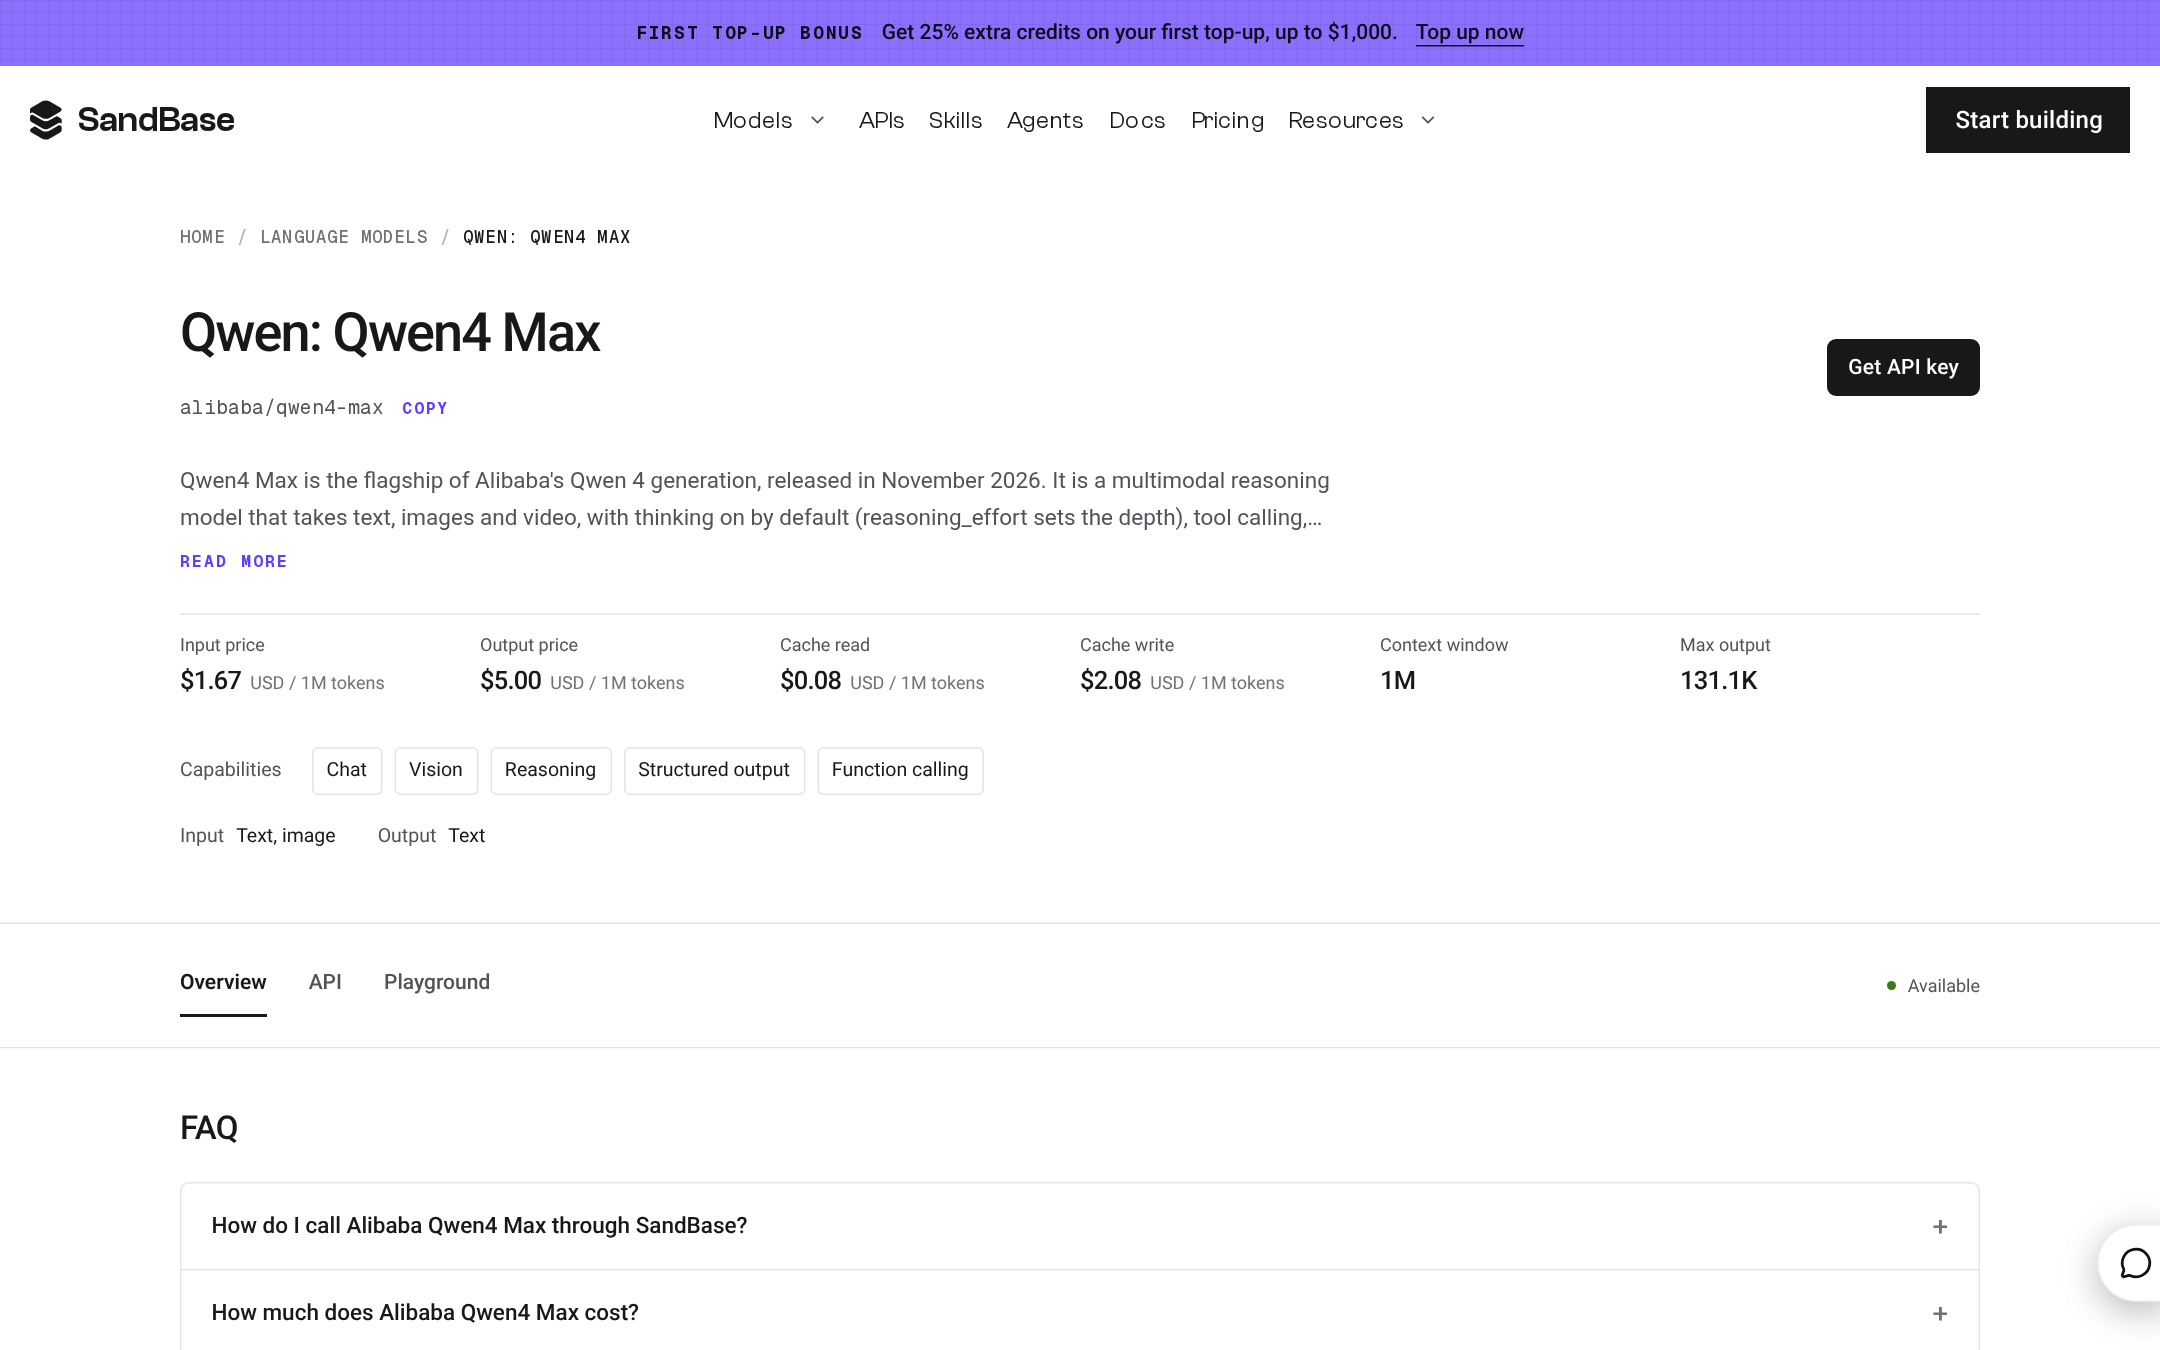
Live SandBase Qwen4 Max card at /models/alibaba/qwen4-max, captured 16 Nov 2026, Asia/Shanghai (HTML and .md both HTTP 200). Hero is $1.67 / $5.00, with cache read $0.08 and cache write $2.08 per 1M tokens, 1M context, and 131.1K max output. There is no 10% off badge. These SandBase prices are above the official Singapore list of $1.50 / $4.50, and above official Beijing / Global $1.413 / $4.24, but still below SandBase Qwen3.8 Max at $1.80 / $5.40. The card hero max output of 131.1K matches the official non-thinking cap; the card description still incorrectly says “up to 393K output tokens shared by thinking and the answer,” which is a preview leftover, not the official GA limit.
Context and output, kept as four different rules
| Model | Official context and output | What the SandBase hero prints |
|---|---|---|
| Qwen4-Max | 1,000,000 context. 131,072 non-thinking. 262,144 thinking + answer. Max input 991,808 non-thinking / 983,616 thinking. | 1M / 131.1K. The 131.1K matches the non-thinking cap. The card blurb’s 393K is a leftover. |
| Gemini 4 Carbon | Unified 1,048,576 tokens, input and output together. A single foreground segment generates up to 65,536 output tokens when streaming, or 32,768 non-streaming. Long decodes can extend output up to 1,048,576 minus the input. | 1M / 65.5K. The 65.5K matches the single-segment streaming cap. It is not the official maximum output. |
| GPT-6 Astra | 1,050,000 context (1.05M). Max output 128,000. | 1.1M / 128K. |
| Claude Fable 5.2 | 1M context, 128K max output. | 1M / 128K. The two sources agree. |
Do not flatten these into “about 1M and about 128K.” A Qwen4-Max client that thinks needs the 262,144 combined ceiling in view, even though the SandBase hero prints 131.1K. A Carbon client that needs a long answer needs the long-decode path, even though the SandBase hero prints 65.5K. An Astra client should not treat the card’s 1.1M as the official 1,050,000.
Price, with the source in the cell
Official Qwen prices are from the QwenCloud pricing page, 16 November 2026. Official pages print $1.5 / $4.5, which are $1.50 / $4.50. Carbon’s official row is Google Agent Platform pricing. Astra’s official row is the OpenAI list cited on the card’s struck prices. Fable’s official row is Anthropic’s $8 / $40 list, including the two cache-write durations. SandBase figures are the 16 November heroes.
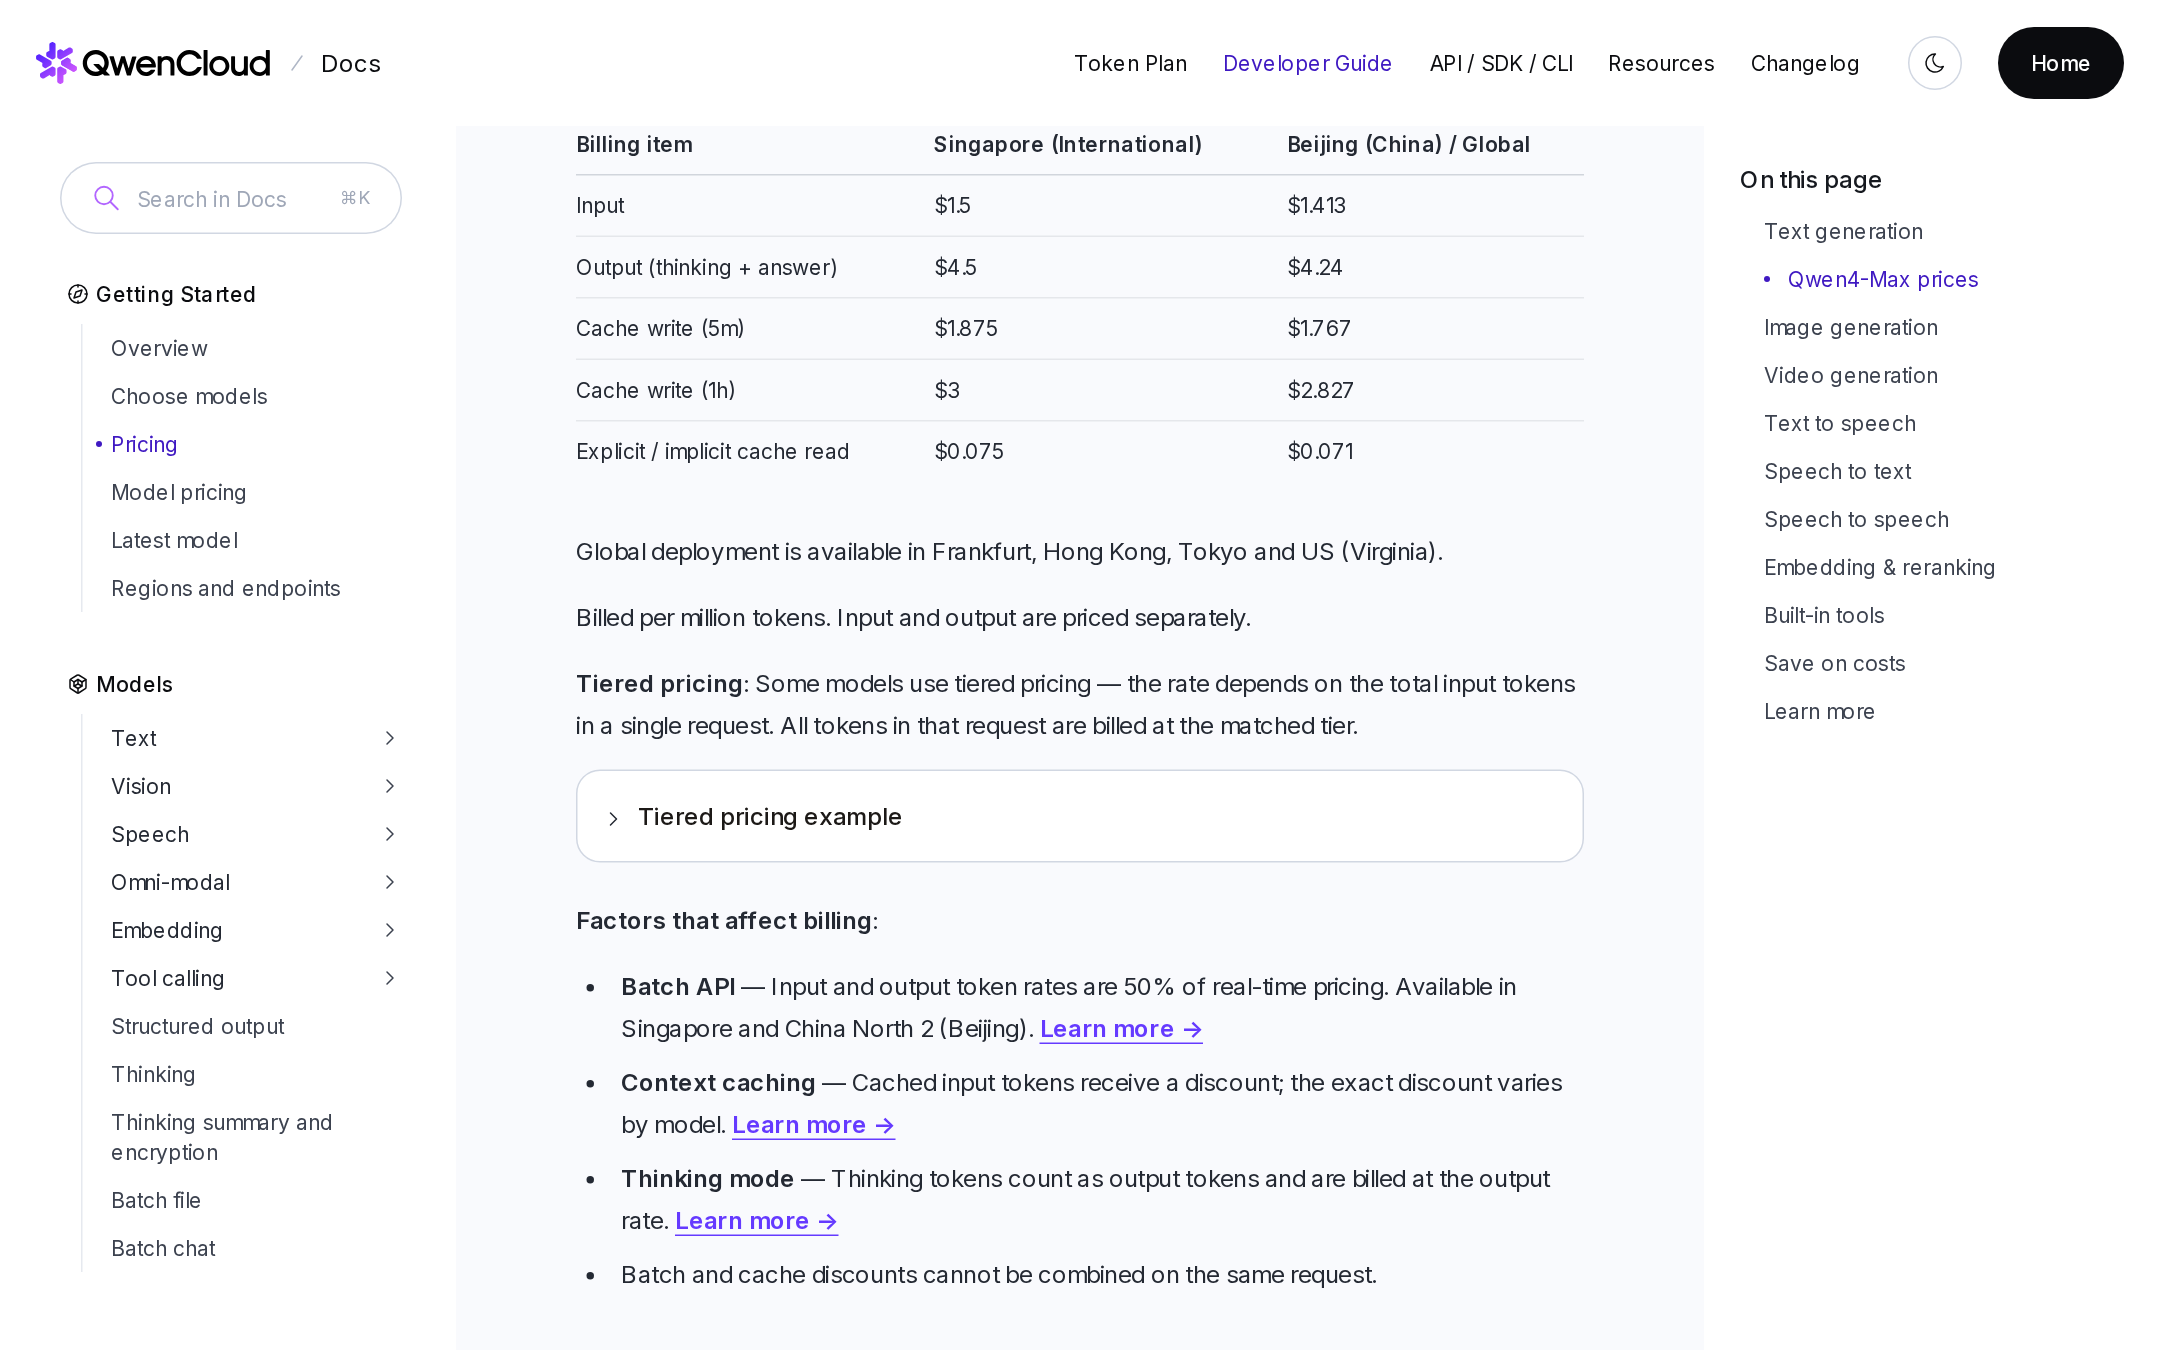
Official QwenCloud pricing page, captured 16 Nov 2026, Asia/Shanghai. Singapore (International) list is $1.5 / $4.5 per 1M tokens (the page prints $1.5 / $4.5, equivalent to $1.50 / $4.50), with cache write $1.875 (5m) / $3 (1h) and cache read $0.075. Beijing / Global is $1.413 / $4.24, with cache write $1.767 / $2.827 and cache read $0.071. The page states that thinking tokens are billed at the output rate, and that Qwen4-Max has no input-length tiers. The “Batch API 50%” bullet on this page is a general billing factor — official Qwen4-Max model pages list batch inference as not supported for this model.
| Official input / output per 1M | SandBase hero per 1M | Cache on the SandBase hero | |
|---|---|---|---|
| Qwen4-Max | Singapore $1.50 / $4.50. Beijing and Global $1.413 / $4.24. Thinking billed as output. No input-length tiers. | $1.67 / $5.00. No 10% off. Schema input price 1.666667. | Read $0.08, write $2.08. Official Singapore read is $0.075; write is $1.875 (5m) or $3 (1h). |
| Gemini 4 Carbon | $2 / $10, cache read $0.10, through 30 Nov 2026 (promotional 50% credits on net spend). $4 / $20, cache read $0.20, from 1 Dec 2026. | $4 / $20. The card shows the post-intro list while the intro window is still open. | Read $0.20. No cache-write figure on the hero. |
| GPT-6 Astra | $10 / $50. Cached input $1. Cache writes $12.50. | $9 / $45, 10% off the $10 / $50 list. | Read $0.90 (list $1.00). Write $11.25 (list $12.50). |
| Claude Fable 5.2 | $8 / $40. 5-minute cache write $10. 1-hour cache write $16. Cache read $0.20. | $8 / $40. No discount shown. | Read $0.20. Write $10, matching the official 5-minute rate. The $16 one-hour write is not on the card. |
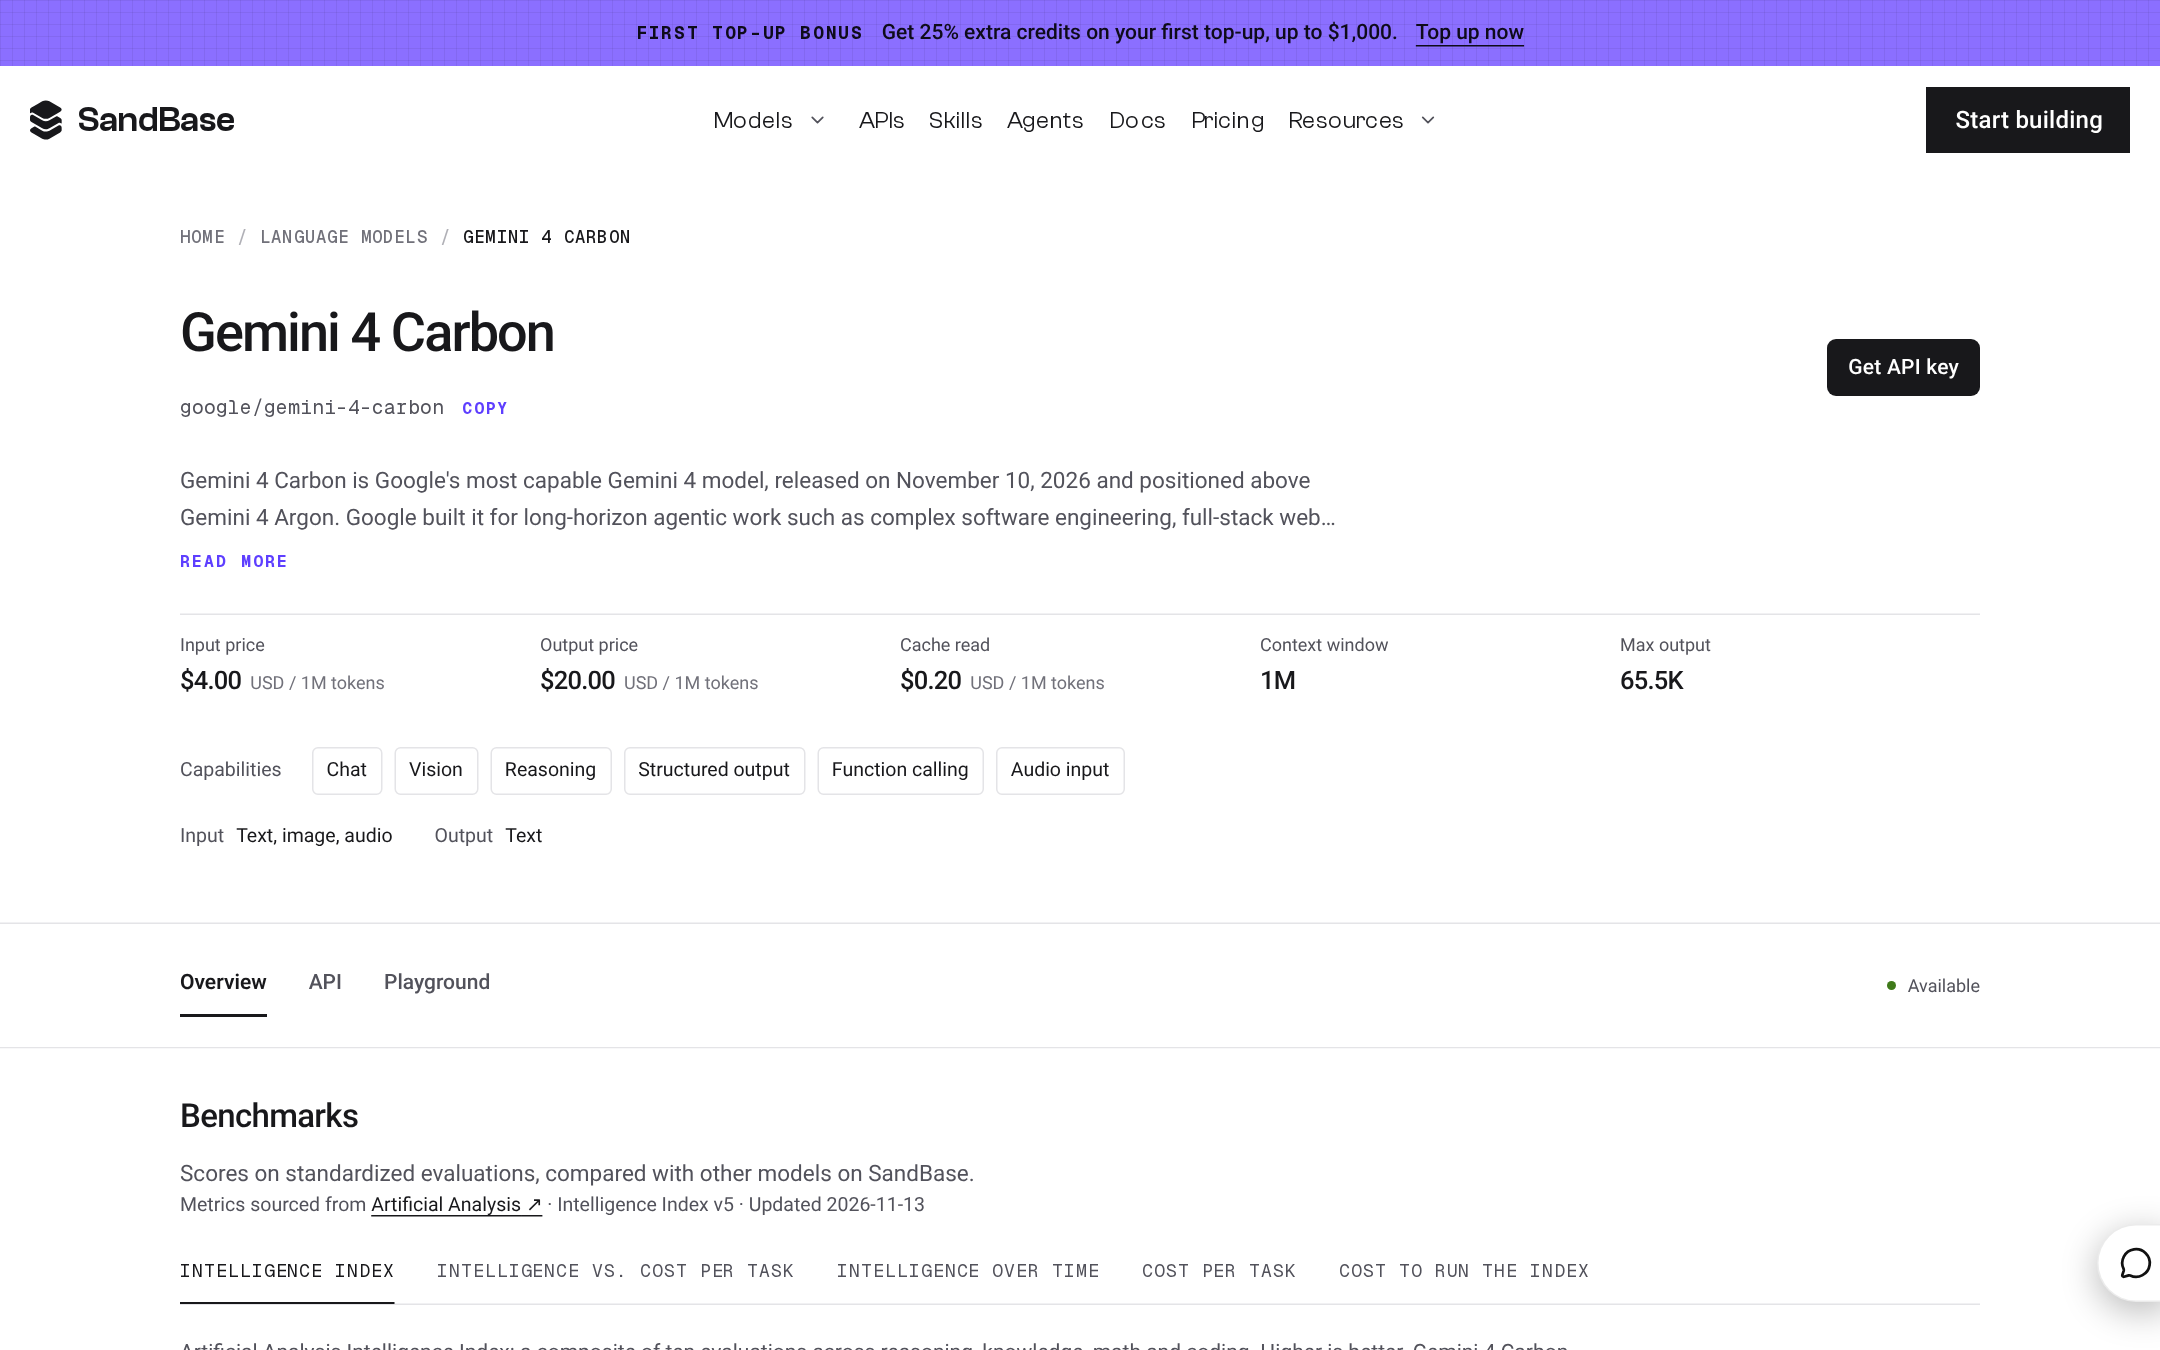
Live SandBase Gemini 4 Carbon card at /models/google/gemini-4-carbon, captured 16 Nov 2026, Asia/Shanghai. The hero is $4.00 / $20.00 with cache read $0.20, 1M context, and 65.5K max output. Official Google Global standard intro pricing is still $2 / $10 (cache read $0.10) through 30 Nov 2026 (promotional 50% credits), then $4 / $20 from 1 Dec 2026; the card currently shows the post-intro list. Official docs also allow long-decode output up to the unified 1,048,576-token window; the 65.5K figure matches the official single-segment streaming cap.
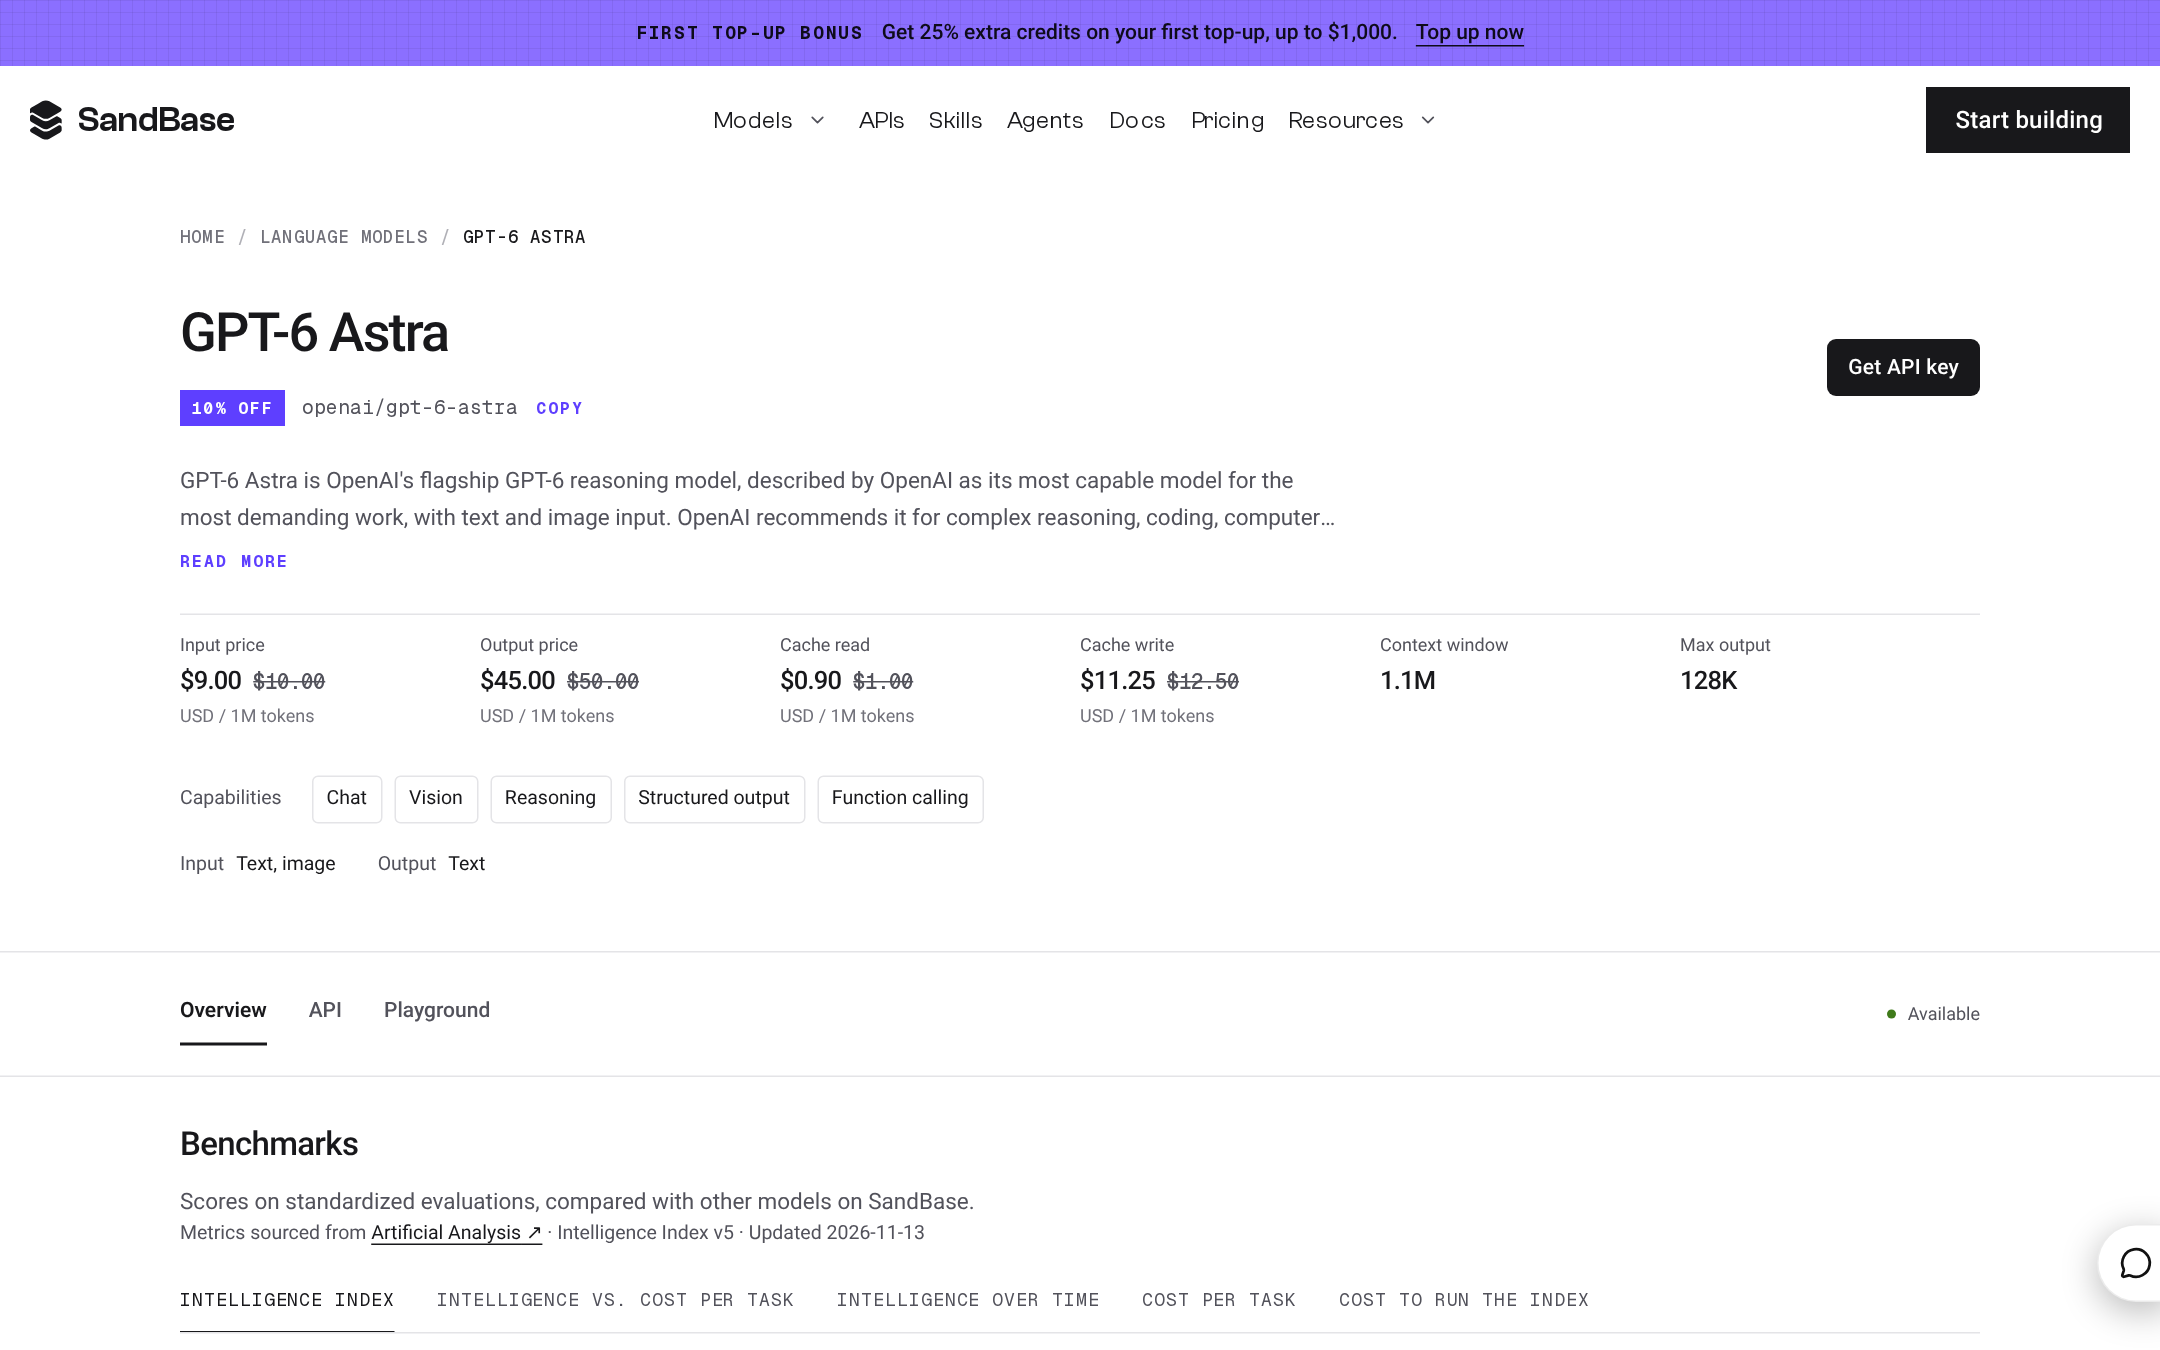
Live SandBase GPT-6 Astra card at /models/openai/gpt-6-astra, captured 16 Nov 2026, Asia/Shanghai. Hero is $9 / $45 (10% off the official $10 / $50 list), with cache read $0.90 and cache write $11.25 per 1M tokens. The card prints a 1.1M context window; official OpenAI docs list 1.05M context and 128K max output.
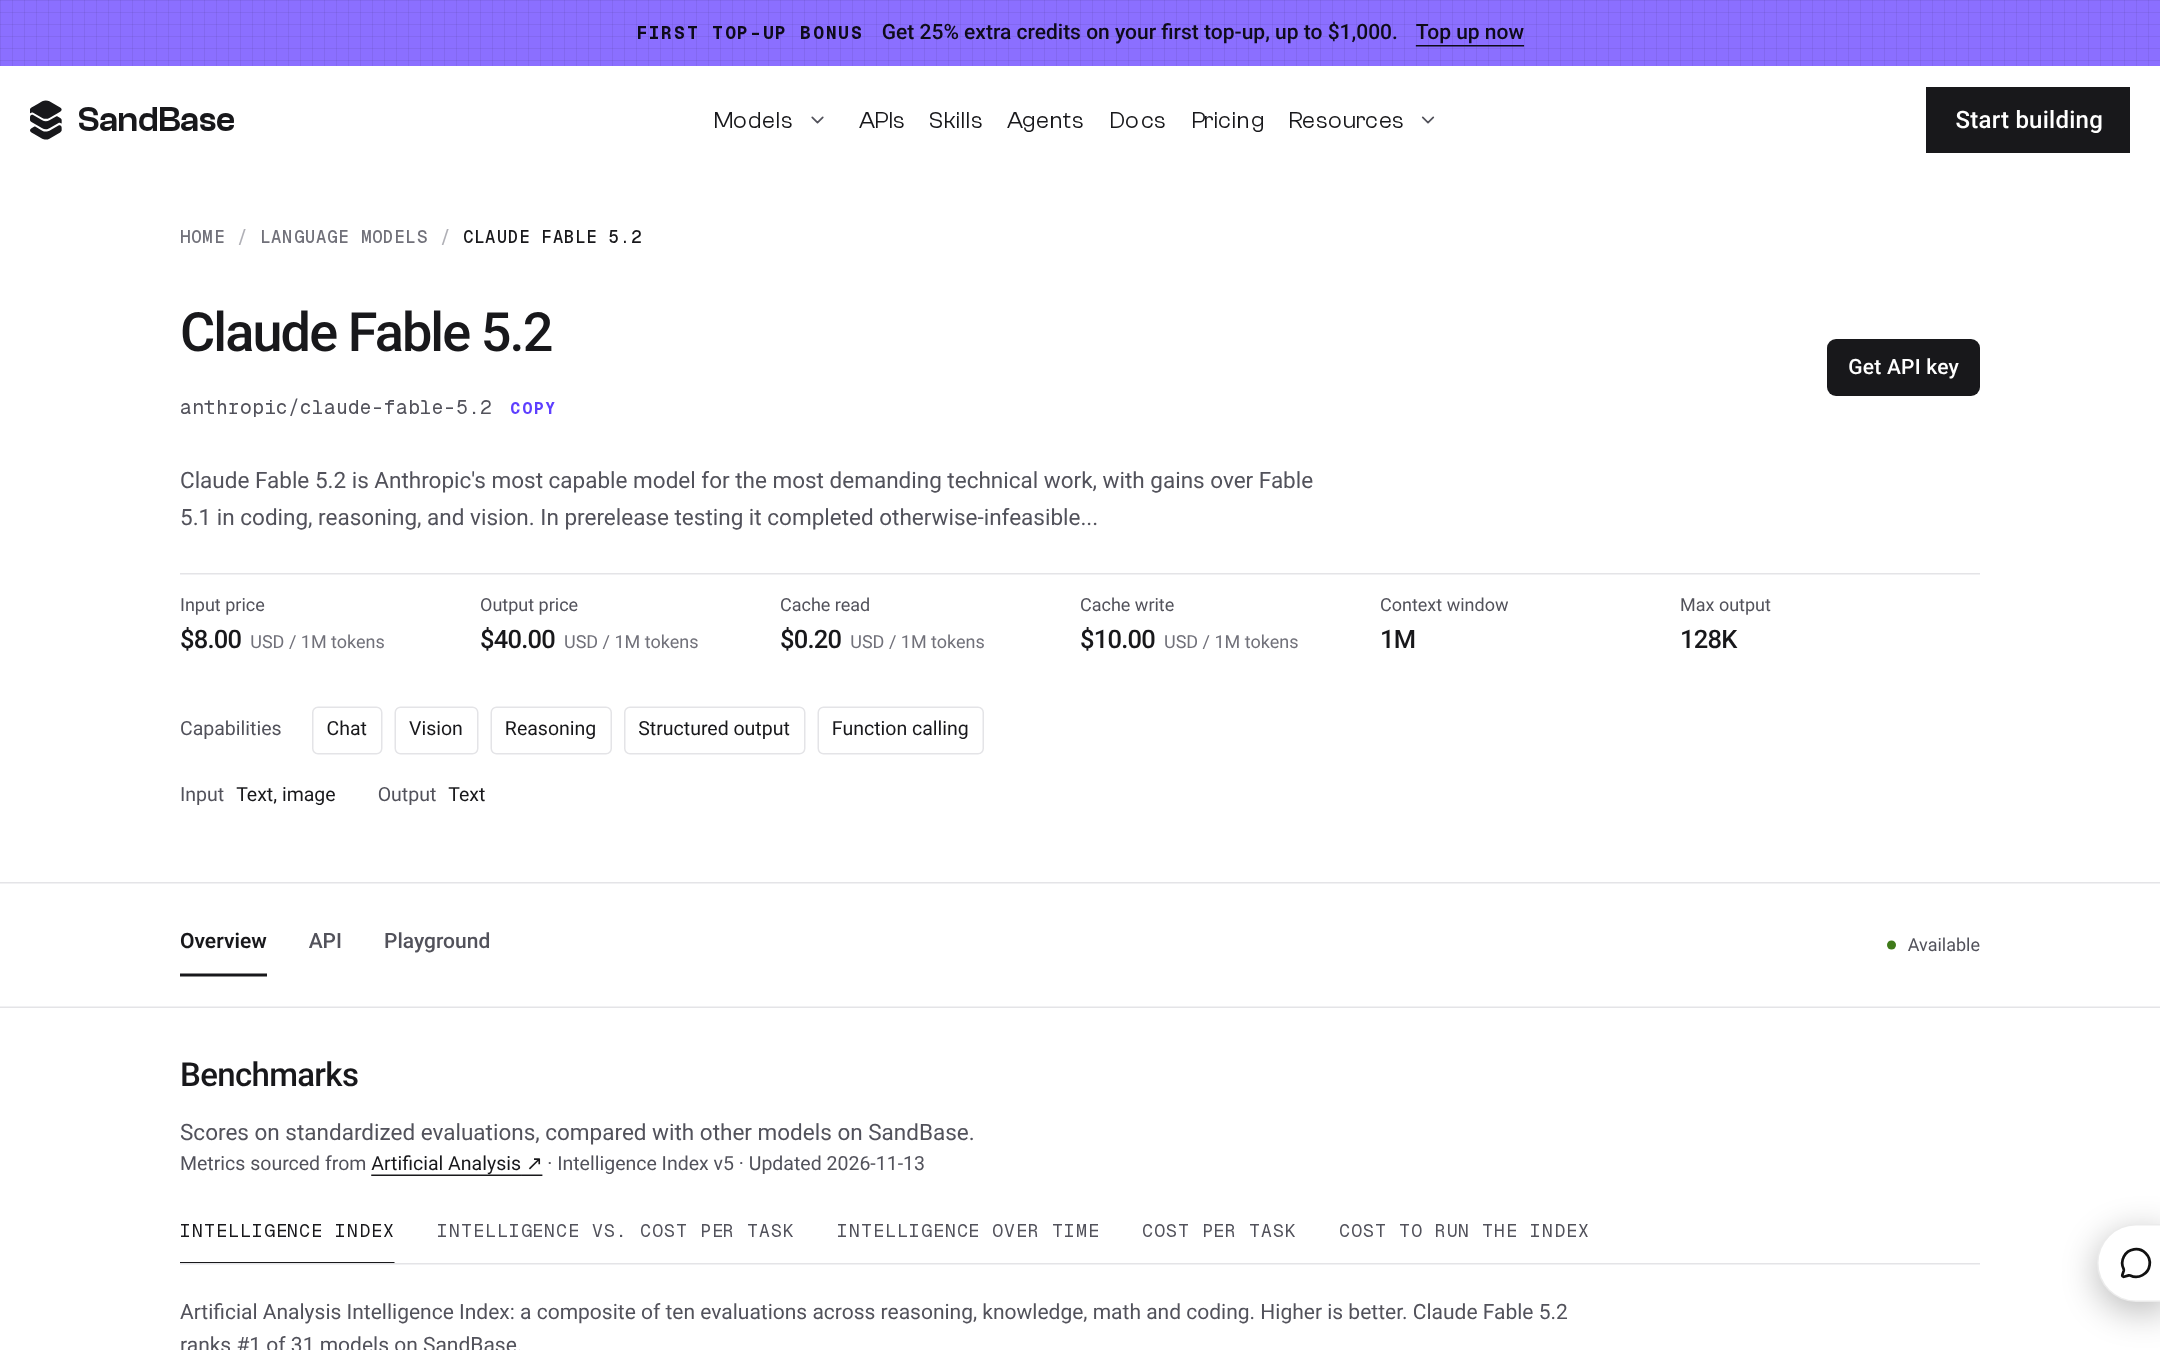
Live SandBase Claude Fable 5.2 card at /models/anthropic/claude-fable-5.2, captured 16 Nov 2026, Asia/Shanghai. Hero is $8 / $40, with cache read $0.20 and cache write $10.00 per 1M tokens, 1M context, and 128K max output. The cache-write figure matches the official 5-minute cache-write rate; official Anthropic docs also list a 1-hour cache write at $16, which is not printed on this card.
On a SandBase bill, the Qwen4-Max hero is the lowest input and output sticker of the four: $1.67 / $5.00, with no discount to “make it official.” Carbon’s card is $4 / $20 while Google’s own intro is still $2 / $10 through 30 November 2026. Astra’s 10% off is real on the card, and the cache read $0.90 / cache write $11.25 have to travel with the $9 / $45, because a cached agent run is where that discount and those cache rates show up. Fable 5.2 matches its official $8 / $40 on the hero. If you cache for an hour, the official $16 write is the number the card does not print.
Batch inference is not supported for qwen4-max on the official model pages, including Beijing. Do not apply a generic half-price batch bullet to that row. Singapore official QwenCloud pay-as-you-go also offers 1 million free tokens, and other Qwen regions do not. The SandBase card does not state that grant.
Modalities, only where a page says so
| Model | Input the official docs name | What the SandBase card adds in its capability list |
|---|---|---|
| Qwen4-Max | Text, image, video. Output is text. No official audio-input claim. | Chat, vision, reasoning, structured output, function calling. |
| Gemini 4 Carbon | Text, image, audio, and video, per the Carbon docs. | Chat, vision, audio input, reasoning, structured output, function calling. |
| GPT-6 Astra | Text and image. | The card is the place to read SandBase capabilities. Do not add audio. |
| Claude Fable 5.2 | Text and images, output text. | The hero does not add audio or video. |
Audio in, on a Qwen call, is still a Qwen3.8 Omni Flash question, not a Qwen4-Max one. The switch between those two Qwen IDs is Qwen4-Max vs Qwen3.8 Max.
What you still cannot rank
A 9-task SandBase probe on 16 November compared alibaba/qwen4-max with alibaba/qwen3.8-max only. Carbon, Astra, and Fable were not in it. The result does not say Qwen4-Max beats them, loses to them, or ties them. The official launch blog’s Work360 and Terminal-Bench sentences compare Qwen4-Max with Qwen3.8-Max. They are not a four-way leaderboard. Third-party scoreboards are not pasted here as fact.
Official Qwen4-Max docs also still do not print a parameter count. The launch blog does, and that attribution stays on the GA how-to. Smaller Qwen4 family names are not shipping APIs on the docs checked 16 November, and this page does not link cards that are not live.
Confirmed versus unknown
| Confirmed | Unknown |
|---|---|
| All four have public official prices and live SandBase cards | Which model is “smarter” |
| The official-versus-card figures in the tables above | Any use of the 9-task Qwen probe as a ranking against these three |
| Carbon’s intro window still runs through 30 November 2026, then $4 / $20 from 1 December | Official batch support for Qwen4-Max. Model pages say it is not supported. |
| Context and output caveats, including Carbon long-decode and Astra 1.05M versus the card’s 1.1M | A SandBase 10% off for Qwen4-Max |
What to call today
Route by the constraint you can name.
- New Alibaba flagship on SandBase, text / image / video in, text out, and you have read the $1.67 / $5.00 hero against the $1.50 / $4.50 Singapore list: Qwen4 Max.
- You already run on Carbon, or you need the official audio and video input plus the long-decode path, and you will quote Google’s $2 / $10 intro through 30 November separately from the card’s $4 / $20: Gemini 4 Carbon.
- You already run on Astra, or you need the official text-and-image model at the card’s 10% off ($9 / $45, cache read $0.90, cache write $11.25) and you will keep 1.05M and 1.1M as two labels: GPT-6 Astra.
- You already run on Fable 5.2, or you want the $8 / $40 list that the SandBase hero matches, with cache read $0.20 and cache write $10: Claude Fable 5.2.
Create a key, then send one bounded request through the first API call doc before you move a queue. The Qwen model string is alibaba/qwen4-max.
FAQ
Is this the same post as the 15 November comparison?
No. That slug is qwen-4-vs-gemini-4-carbon-gpt-6-astra-fable-5-2-2026. It records a world where Qwen4-Max-Preview had no public pay-as-you-go price and no SandBase card. This slug is the 16 November comparison, after both of those changed. The older page keeps its preview record, with a dated update on top.
Why does Carbon cost $4 / $20 on SandBase during a $2 / $10 intro?
Google’s Global standard intro is $2 / $10, cache read $0.10, through 30 November 2026, described as promotional pricing via 50% credits back on net spend. From 1 December 2026 the official list is $4 / $20, cache read $0.20. The SandBase hero on 16 November already shows $4 / $20 and cache read $0.20. Quote both if the bill might be either host.
Is Astra’s context 1.05M or 1.1M?
Official docs say 1,050,000 tokens and 128,000 max output. The SandBase card prints 1.1M and 128K. The 10% off ($9 / $45 versus $10 / $50) and the cache rates ($0.90 read, $11.25 write) are separate from that context label. Do not merge the pairs.
Can I batch Qwen4-Max because the other flagships have batch stories?
Official Qwen4-Max model pages say batch inference is not supported, including in Beijing. A half-price batch line on a general pricing page is not this model’s feature.
Heroes and official price pages checked 16 November 2026. Carbon docs dated 2026-11-13 UTC for the unified window and the long-decode rule. No quality ranking is implied by the price order.
Related reading
Found this useful? Share it