Which Qwen Should You Call Today? Qwen3.8 Max vs 27B vs Omni Flash While Qwen 4 Stays in Preview
15 Nov router for Qwen3.8 Max, 27B, and Omni Flash. Update 16 Nov 2026: Qwen4-Max is GA and live on SandBase as alibaba/qwen4-max.
Update (16 Nov 2026): Qwen4-Max is officially generally available with pay-as-you-go, and it is live on SandBase as
alibaba/qwen4-max. New flagship work starts there. This page keeps the 15 November router among Qwen3.8 Max, 27B, and Omni Flash. The GA call is Qwen4-Max Is Generally Available. The switch off Qwen3.8 Max is Qwen4-Max vs Qwen3.8 Max. The public-price comparison is Qwen4-Max vs Gemini 4 Carbon, GPT-6 Astra, and Claude Fable 5.2.
On the evening of 15 November 2026, Asia/Shanghai, Qwen 4 was still a Token Plan preview. The Qwen you could call on SandBase that evening was a Qwen3.8 ID. Route the job first, then read the preview sidebar. Long-horizon work on that evening, and the strongest Qwen then on the account, went to Qwen3.8 Max. A dense vision model that does not need the flagship bill goes to Qwen3.8 27B. Audio, or cheap image and video throughput that returns text, goes to Qwen3.8 Omni Flash. As of 16 November, the flagship call is alibaba/qwen4-max.
The Qwen hub the same evening still describes Qwen3.8 and Qwen3.7. That evening there was no Qwen4 card to send. The hub title was still stale on 16 November even after the individual card went live. What the preview is, and what it is not, is the 15 November status post Is Qwen 4 Out?. Whether to move production off Max before 25 November is Qwen4-Max-Preview vs Qwen3.8 Max.
Key takeaway
- Call Qwen3.8 Max for the flagship. Hero $1.80 / $5.40 per 1M (10% off $2 / $6), cache read $0.23, cache write $2.25, 1M context, 131.1K max output on the card. Official Alibaba docs list
qwen3.8-maxmax output as 128k.- Call Qwen3.8 27B when Max is more than the job. $0.50 / $3, cache read $0.10, cache write $0.63, 1M / 131.1K. The card describes a dense open-weight vision-language model that understands images and video.
- Call Qwen3.8 Omni Flash for text, image, audio, and video in, text out. $0.15 / $0.47, cache read $0.02, cache write $0.15, 1M / 131.1K. Official Qwen4-Max-Preview docs do not claim audio input.
- Qwen4-Max-Preview stays Token Plan only until 24:00 on 25 November 2026 (UTC+8), then official text says it will be retired. It is not the default in this routing table.
- All three SandBase IDs use
POST https://api.sandbase.ai/v1/chat/completions.
Three cards, three jobs
Prices below are the live heroes from the 15 November 2026 check, including cache. Context and max output are the card labels unless a cell says “official.”
| Call this | SandBase ID | Hero in / out per 1M | Cache read / write | Context / max output | When it is the one |
|---|---|---|---|---|---|
| Qwen3.8 Max | alibaba/qwen3.8-max | $1.80 / $5.40 (10% off list $2 / $6) | $0.23 / $2.25 (list $0.25 / $2.50) | Card: 1M / 131.1K. Official qwen3.8-max: 1M / 128k. | Long-horizon work, native vision, the strongest current Qwen on SandBase. |
| Qwen3.8 27B | alibaba/qwen3.8-27b | $0.50 / $3 | $0.10 / $0.63 | Card: 1M / 131.1K | Dense open-weight VLM. Images and video. Max is more model than the task needs. |
| Qwen3.8 Omni Flash | alibaba/qwen3.8-omni-flash | $0.15 / $0.47 | $0.02 / $0.15 | Card: 1M / 131.1K | Text, image, audio, and video in. Text out. Audio, or cheap multimodal throughput. |
The 10% off sits on Max only. 27B and Omni Flash showed no discount badge on this check. Do not spread the Max sticker across the row.
Qwen3.8 Max, when the job is the flagship
The card title on this check is “Qwen3.8 Max API: Plan Long-Horizon Work with Native Vision.” Capabilities listed: chat, vision, reasoning, structured output, function calling. The blurb calls it a 2.4-trillion-parameter mixture-of-experts model with native vision, the August 2026 flagship. That description is the card’s. The long explainer is Qwen 3.8 Max: Alibaba’s 2.4T Multimodal Flagship.
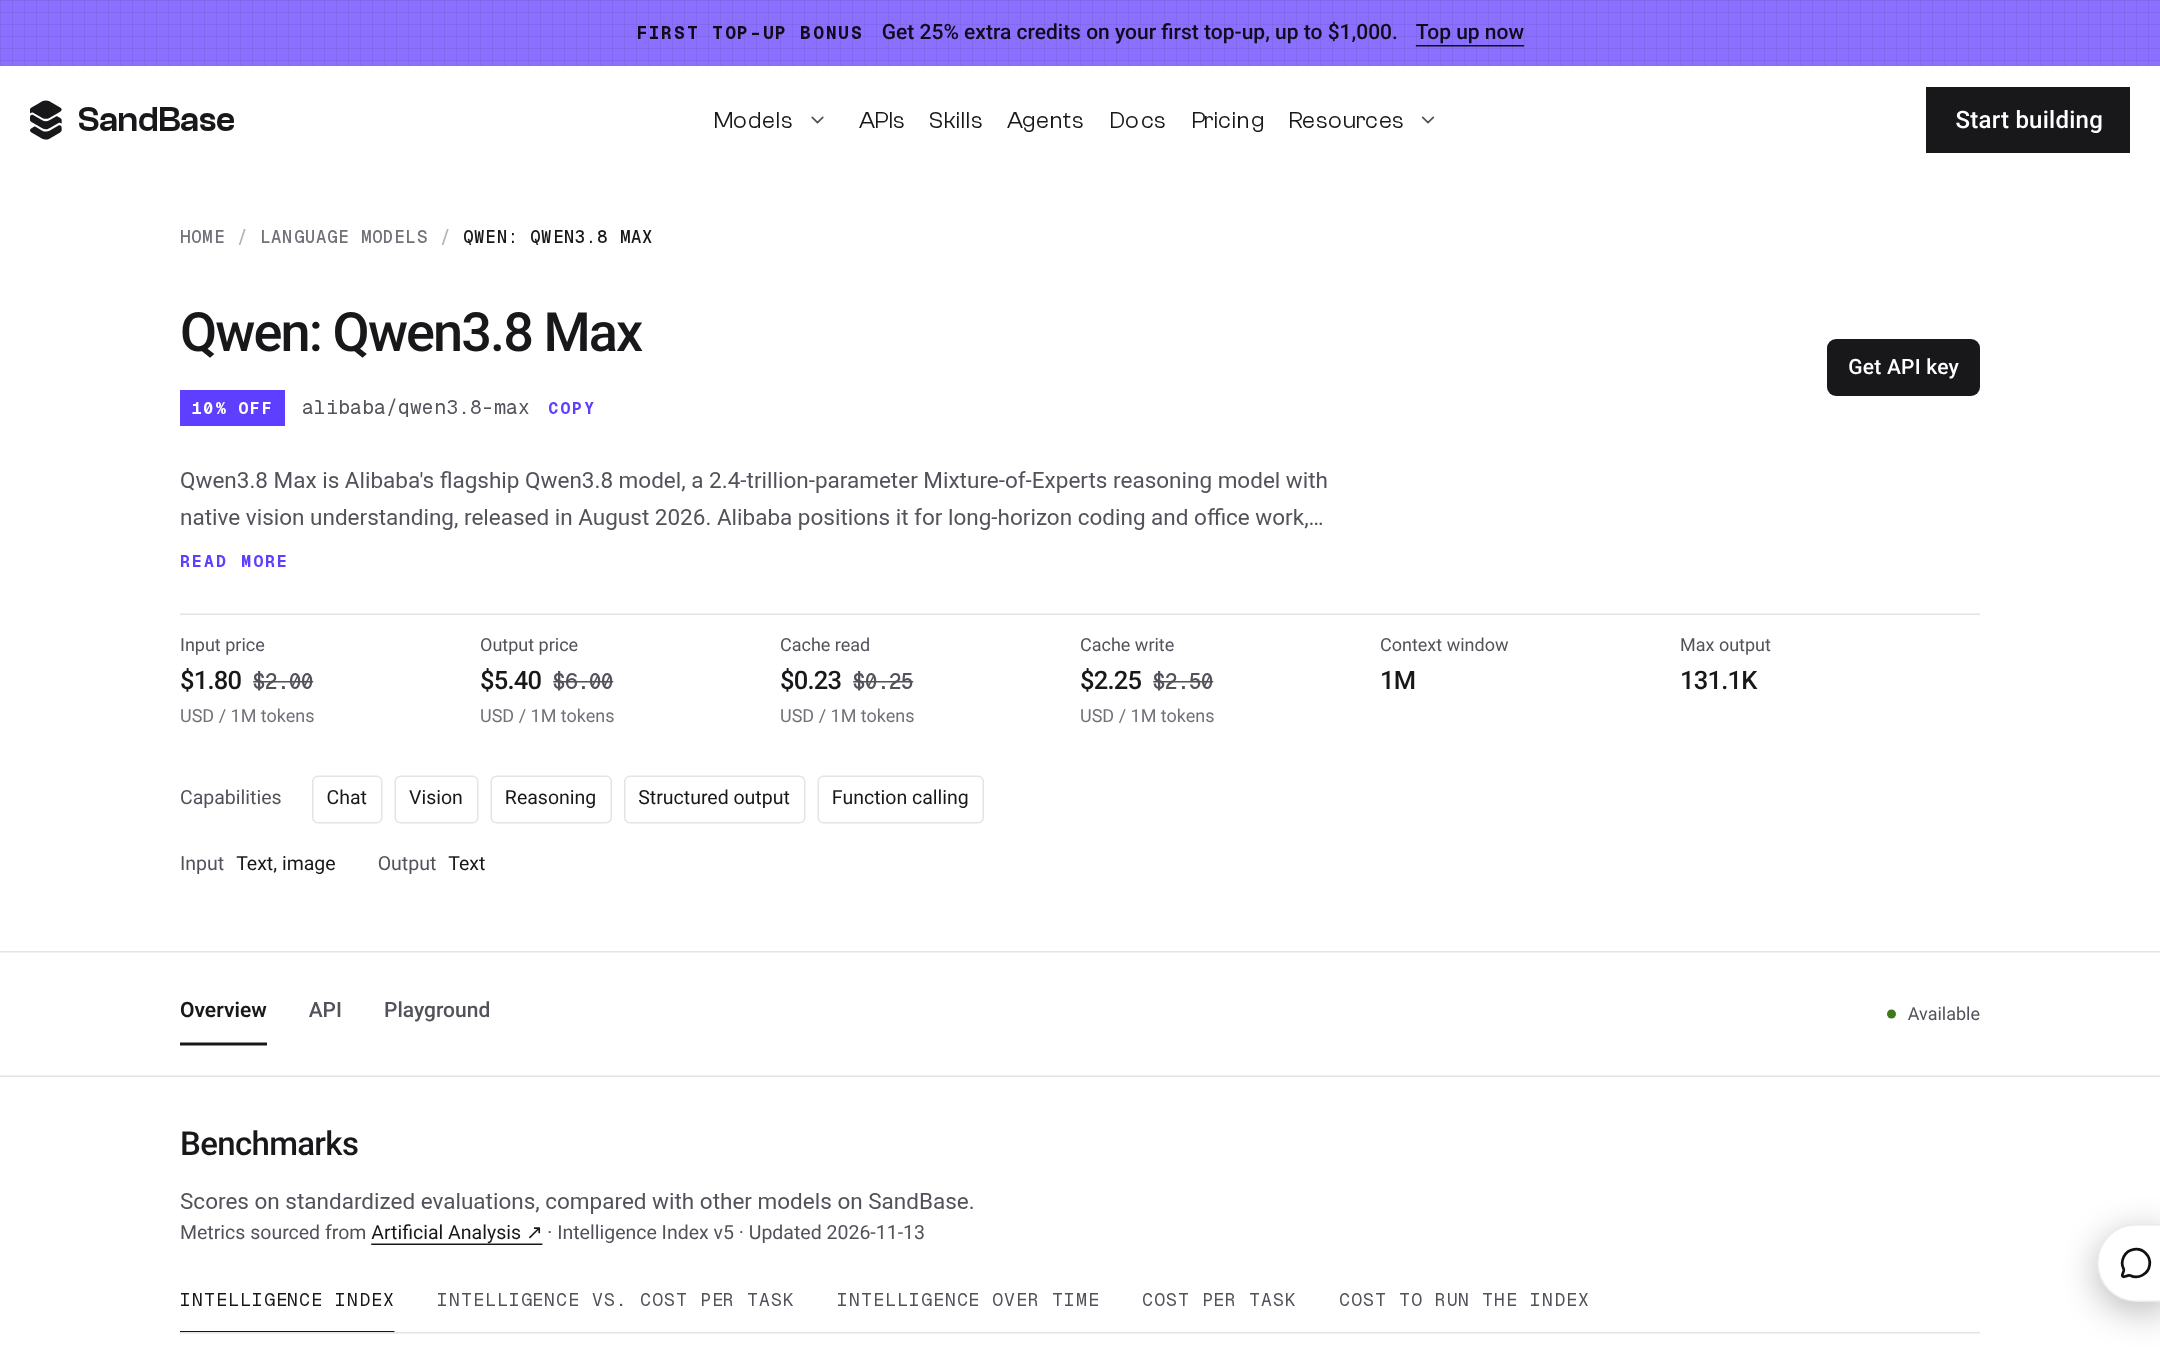
Live SandBase Qwen3.8 Max card at /models/alibaba/qwen3.8-max, captured 15 Nov 2026, Asia/Shanghai (HTML and .md both HTTP 200). Hero is $1.80 / $5.40 (10% off the $2 / $6 list), with cache read $0.23 and cache write $2.25 per 1M tokens. This is the generally available Qwen you can keep in production today.
Official Alibaba’s text-generation table still prints 128k max output for qwen3.8-max. The SandBase hero prints 131.1K. A call on SandBase follows the card. A call on Alibaba’s own API follows the official 128k label. Name the surface when you quote the cap. Cache on this hero is the part people drop: read $0.23 and write $2.25 per 1M, against list $0.25 / $2.50. A prompt that actually hits cache should be budgeted with those figures, not with the uncached $1.80 alone.
Qwen3.8 27B, when Max is too much model
The card title is “Qwen3.8 27B API: Code and Analyze Vision on a Dense 27B.” The blurb says it understands images and video, with thinking on by default. Capabilities include vision, plus chat, reasoning, structured output, and function calling. It is the compact dense open-weight vision-language model on this account, at $0.50 input and $3 output per 1M. Cache read $0.10 and cache write $0.63 are low enough that a vision loop which does not need the 2.4T flagship should start here.
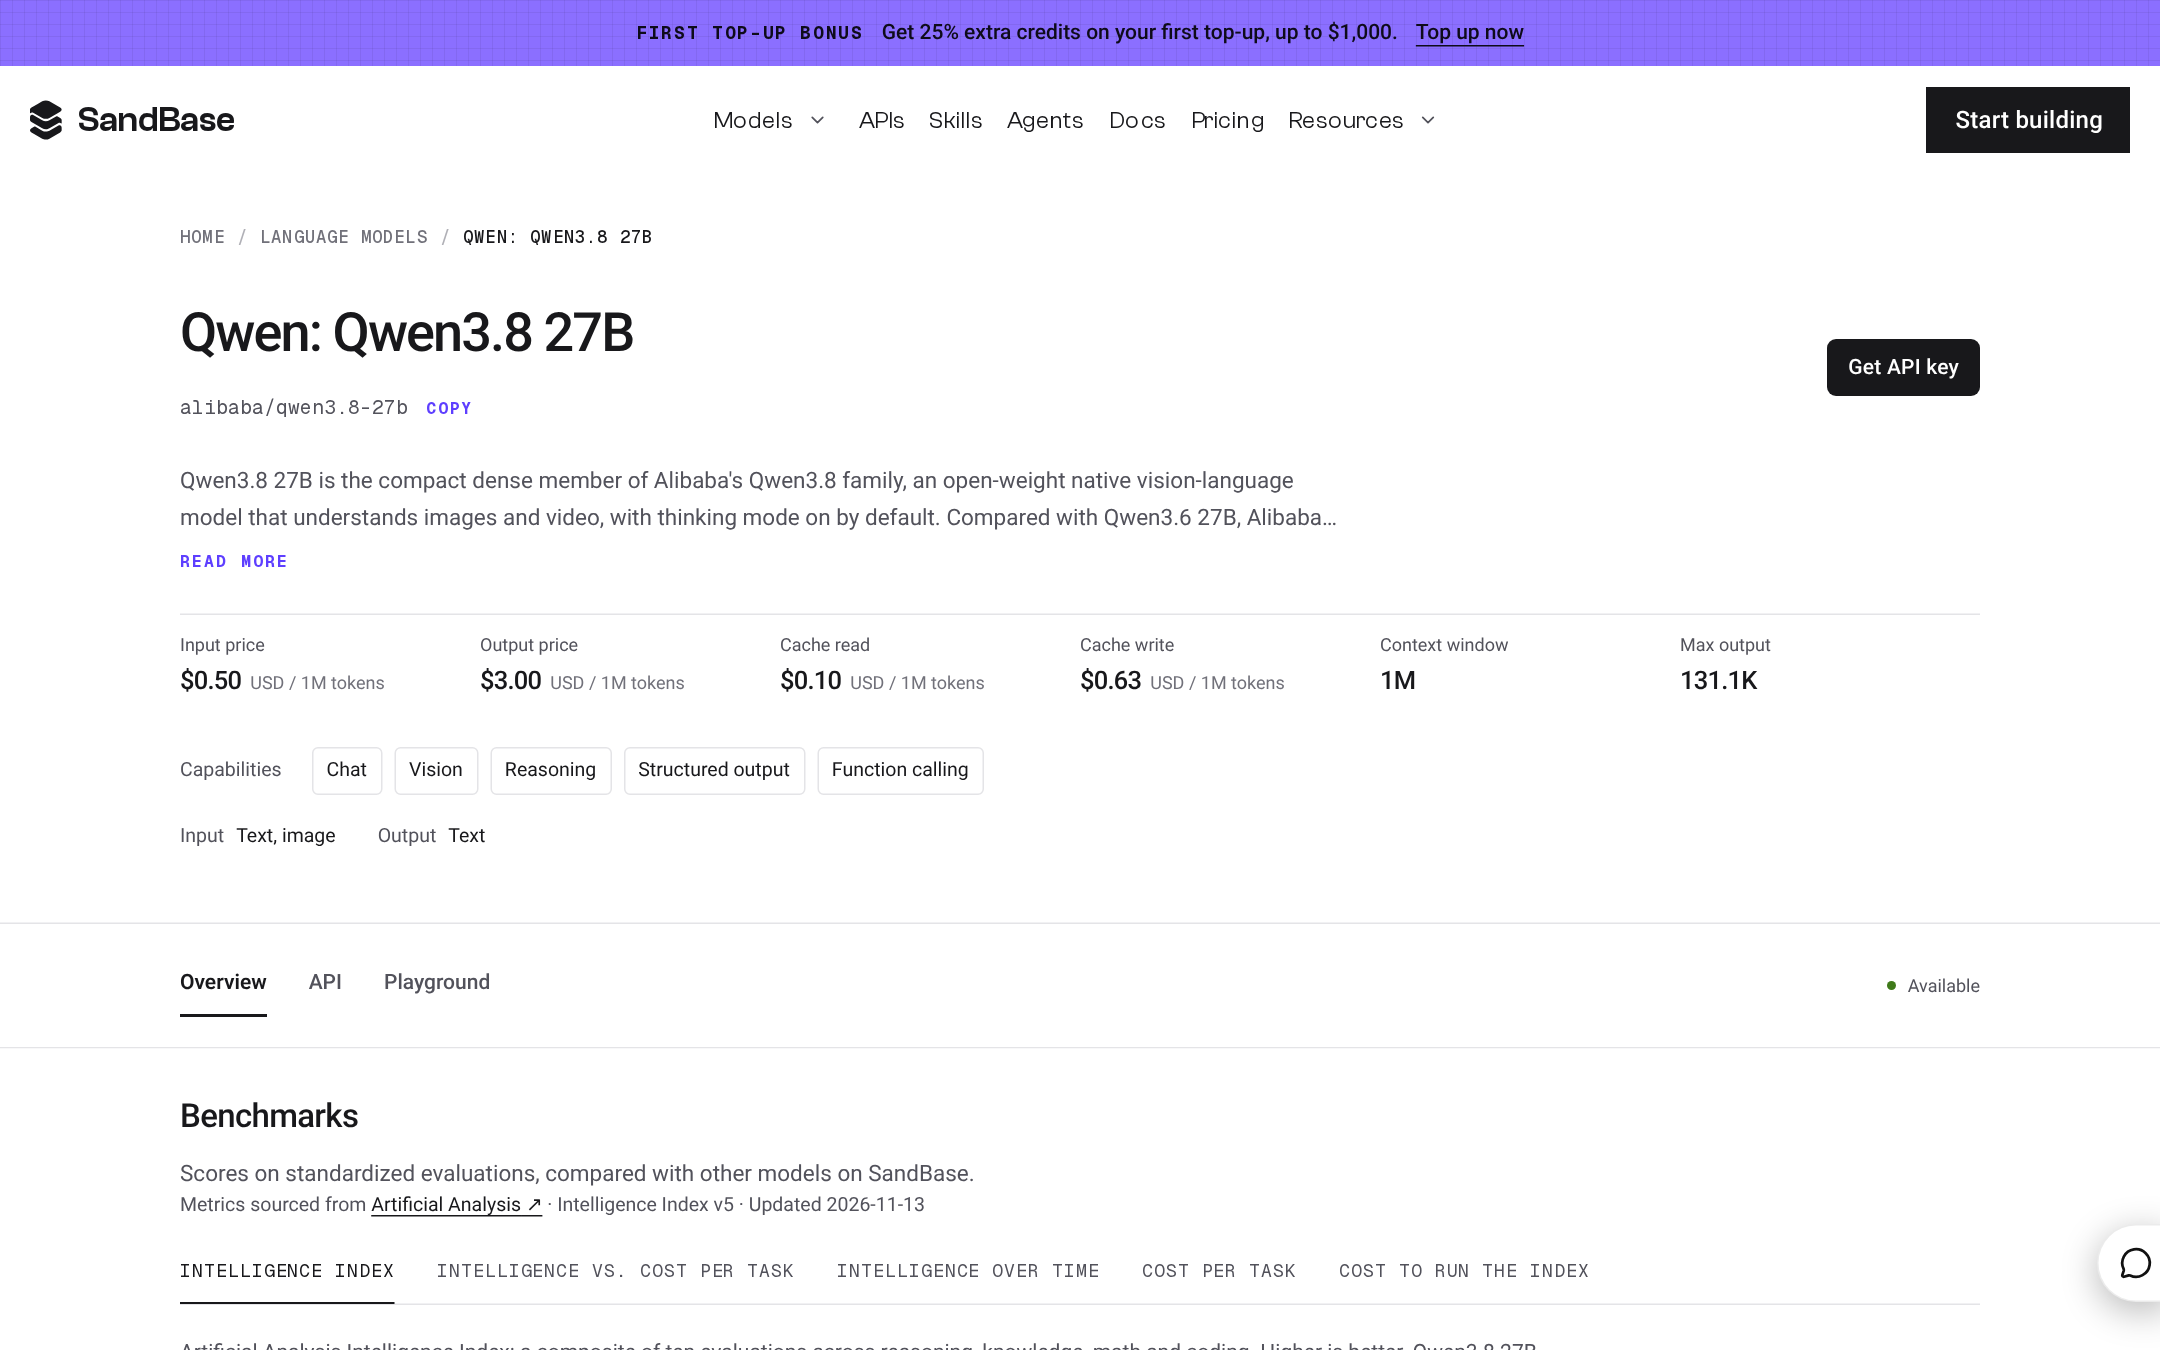
Live SandBase Qwen3.8 27B card at /models/alibaba/qwen3.8-27b, captured 15 Nov 2026, Asia/Shanghai. Hero is $0.50 / $3, with cache read $0.10 and cache write $0.63 per 1M tokens, 1M context, and 131.1K max output. The card describes a dense open-weight vision-language model that understands images and video.
Same card window as Max: 1M context and 131.1K max output. The split is price and shape, not a shorter context. Input is $0.50 against Max’s $1.80, and output is $3 against $5.40. Use 27B for code and image or video analysis that fits a dense 27B. Move back to Max when the task is the long-horizon one the Max card is named for. This note does not invent a benchmark gap between them. The official preview docs also do not supply that gap.
Qwen3.8 Omni Flash, when the input is audio or the volume is the point
The card title is “Qwen3.8 Omni Flash API: Summarize Audio and Video at 1M.” Hero $0.15 / $0.47 per 1M, cache read $0.02, cache write $0.15, 1M context, 131.1K max output. Input modalities on the card: text, image, audio, and video. Output is text.
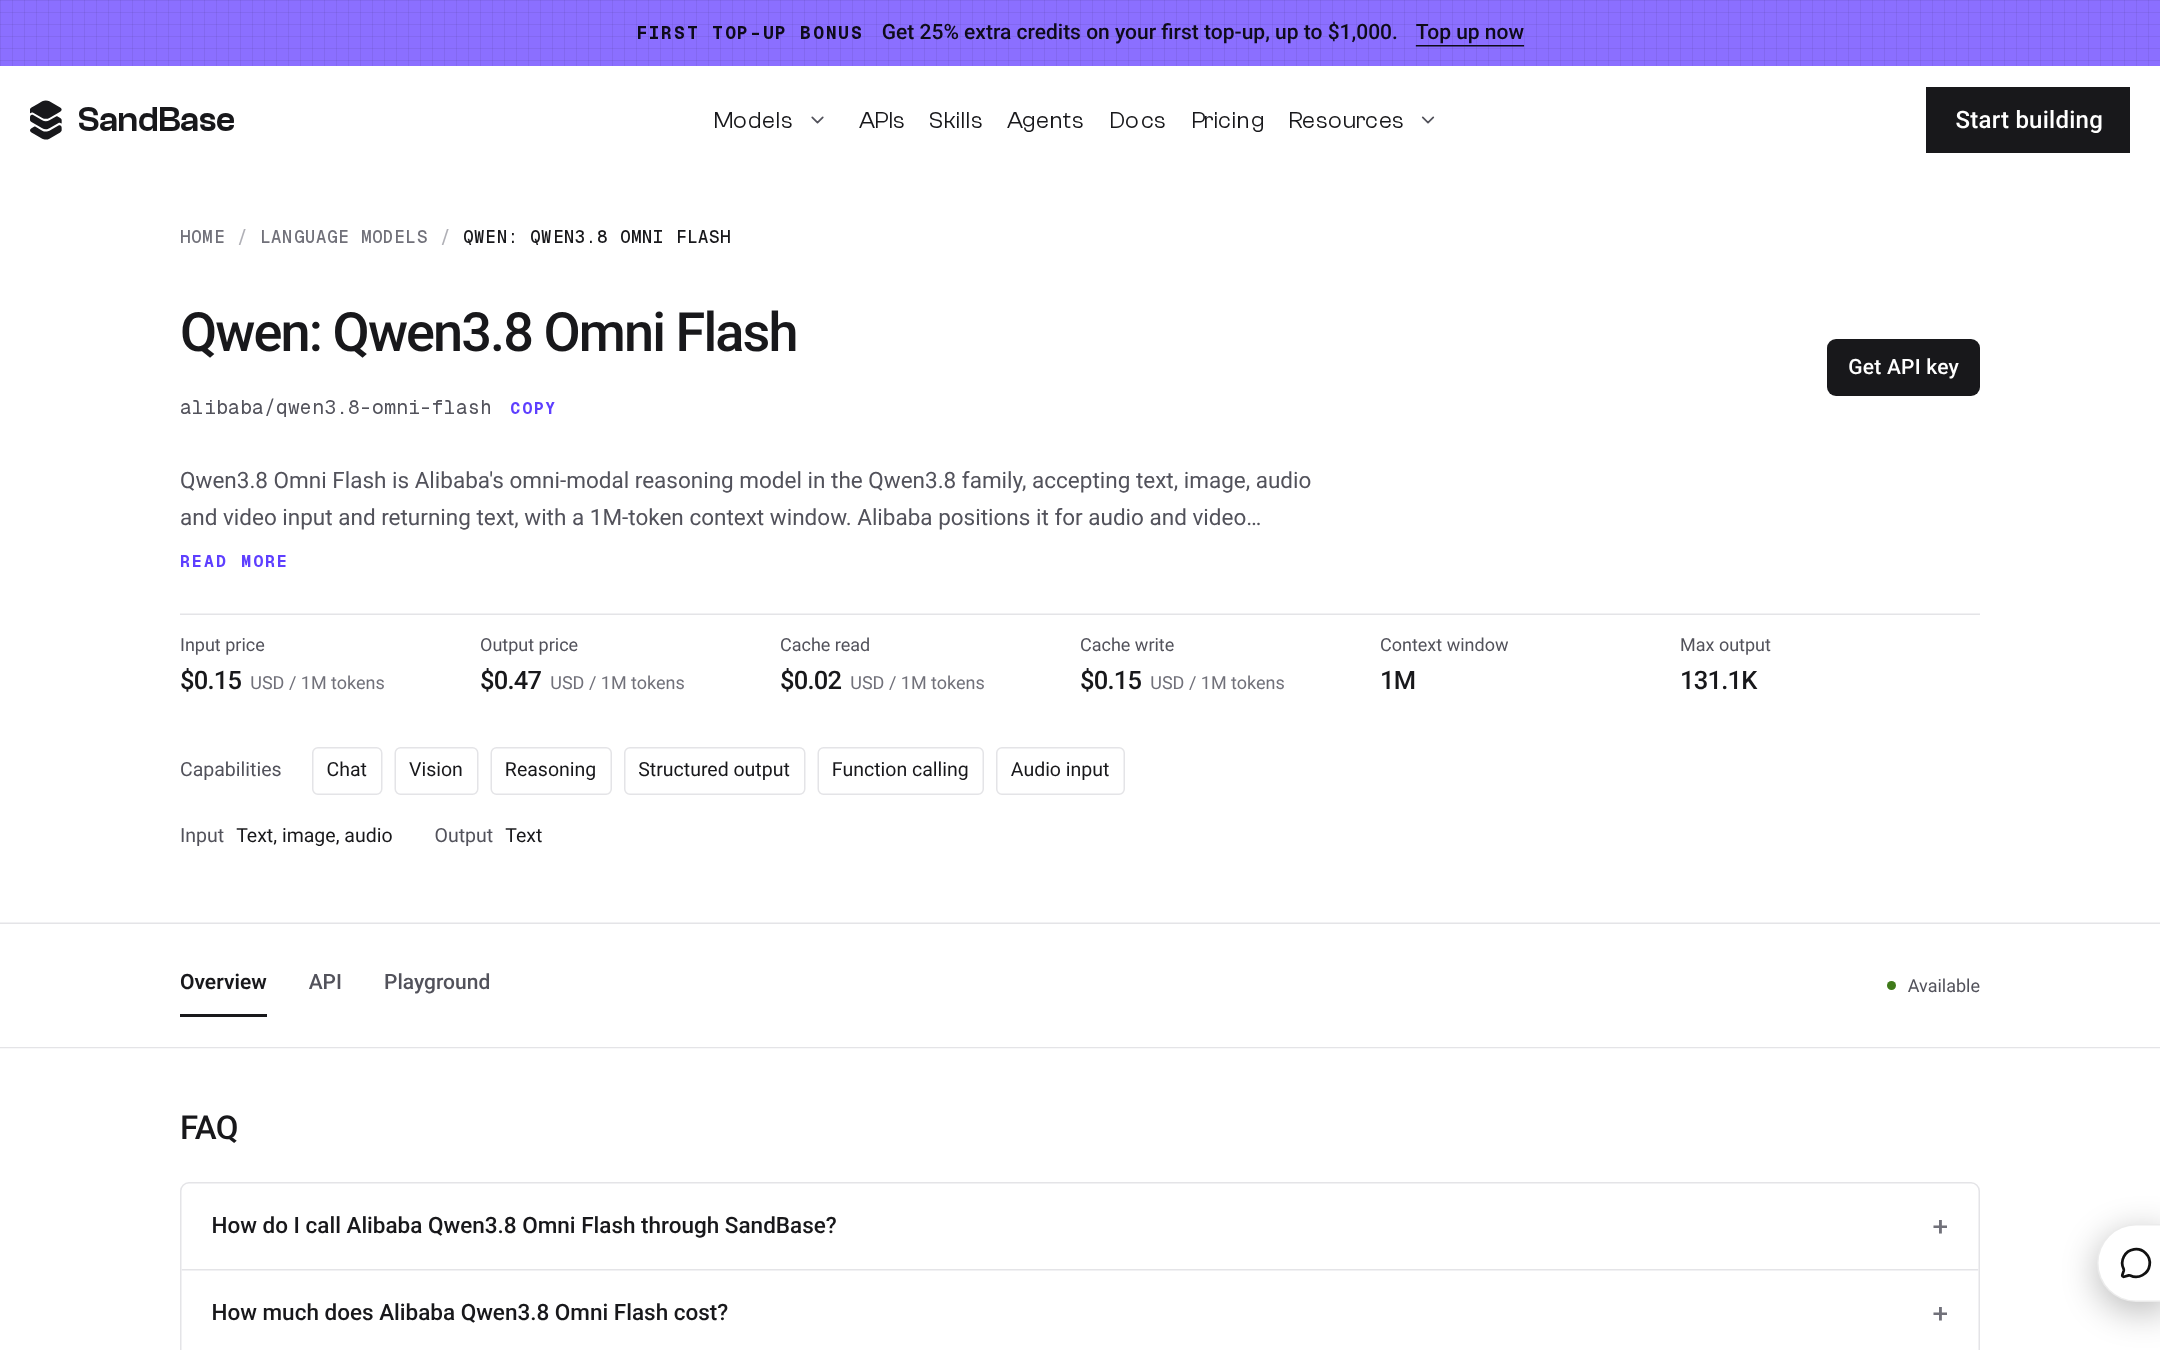
Live SandBase Qwen3.8 Omni Flash card at /models/alibaba/qwen3.8-omni-flash, captured 15 Nov 2026, Asia/Shanghai. Hero is $0.15 / $0.47, with cache read $0.02 and cache write $0.15 per 1M tokens, 1M context, and 131.1K max output. The card accepts text, image, audio, and video input and returns text — a modality the official Qwen4-Max-Preview docs do not claim for audio.
That audio line is the clean split with the preview. Official Qwen4-Max-Preview docs describe text, image, and video understanding. They do not claim audio input. If the file is a recording, Omni Flash is the Qwen on SandBase that lists audio. It is also the cheap path for image and video when you want text back and you do not need Max’s flagship bill. $0.15 / $0.47 is the same input/output sticker as Qwen3.8 Flash on this check. The cache-write figures are not the same, and Flash’s context label is a different problem, covered below.
The other Qwen3.8 cards, if the three above are the wrong shape
These are on the account. They are not the default route.
Qwen3.8 2.4T A95B is $2 / $6 per 1M, cache read $0.25 and cache write $2.50, 1M context, 52.4K max output. The card describes an open-weight Max-class sparse mixture-of-experts, about 95B active. Capabilities listed: chat, reasoning, structured output, function calling. Vision is not on that list. Do not send it an image job on the strength of the “Max-class” phrase.
Qwen3.8 Flash is $0.15 / $0.47, cache read $0.02 and cache write $0.20. The SandBase hero prints context window N/A and max output 131.1K. This note does not invent a SandBase context for it. Official Alibaba docs, separately, list qwen3.8-flash at 1M context and 128k max output. The official text-generation page also recommends qwen3.8-flash when you are prioritizing cost, and qwen4-max-preview when you are prioritizing quality, with that quality row marked Token Plan only. A cost-first call that has to stay on SandBase still needs a card whose context is printed. Max, 27B, and Omni Flash each print 1M. Flash, on the SandBase hero, does not.
Qwen3.8 Max Prime is $4 / $12, cache read $0.50 and cache write $5.00, 1M / 131.1K. The card describes faster serving of the same Max model. It is a speed tier, not a smarter model, and the hero is well above Max’s $1.80 / $5.40. It is not a primary route.
Where the preview fits, briefly
On 15 November, Qwen4-Max-Preview (qwen4-max-preview) was Token Plan only from 10:00 on 11 November 2026 to 24:00 on 25 November 2026 (UTC+8). Official text says that preview model will be retired after the window. Pay-as-you-go was not supported on the preview, and the preview had no public unit price. Official context is 1,000,000 tokens. The preview’s official max output that evening was 393,216, shared by thinking and the answer, which was higher than qwen3.8-max’s official 128k. That preview ceiling did not make the preview the production default, and it is not the 16 November GA cap. SandBase had no Qwen4 card on 15 November. As of 16 November the card is alibaba/qwen4-max. Endpoint setup for the preview stays in the 13 November access guide.
If the comparison you actually wanted was against Gemini 4 Carbon, GPT-6 Astra, and Claude Fable 5.2, that page is what you can compare today. It compares access and limits. It does not rank unofficial scores.
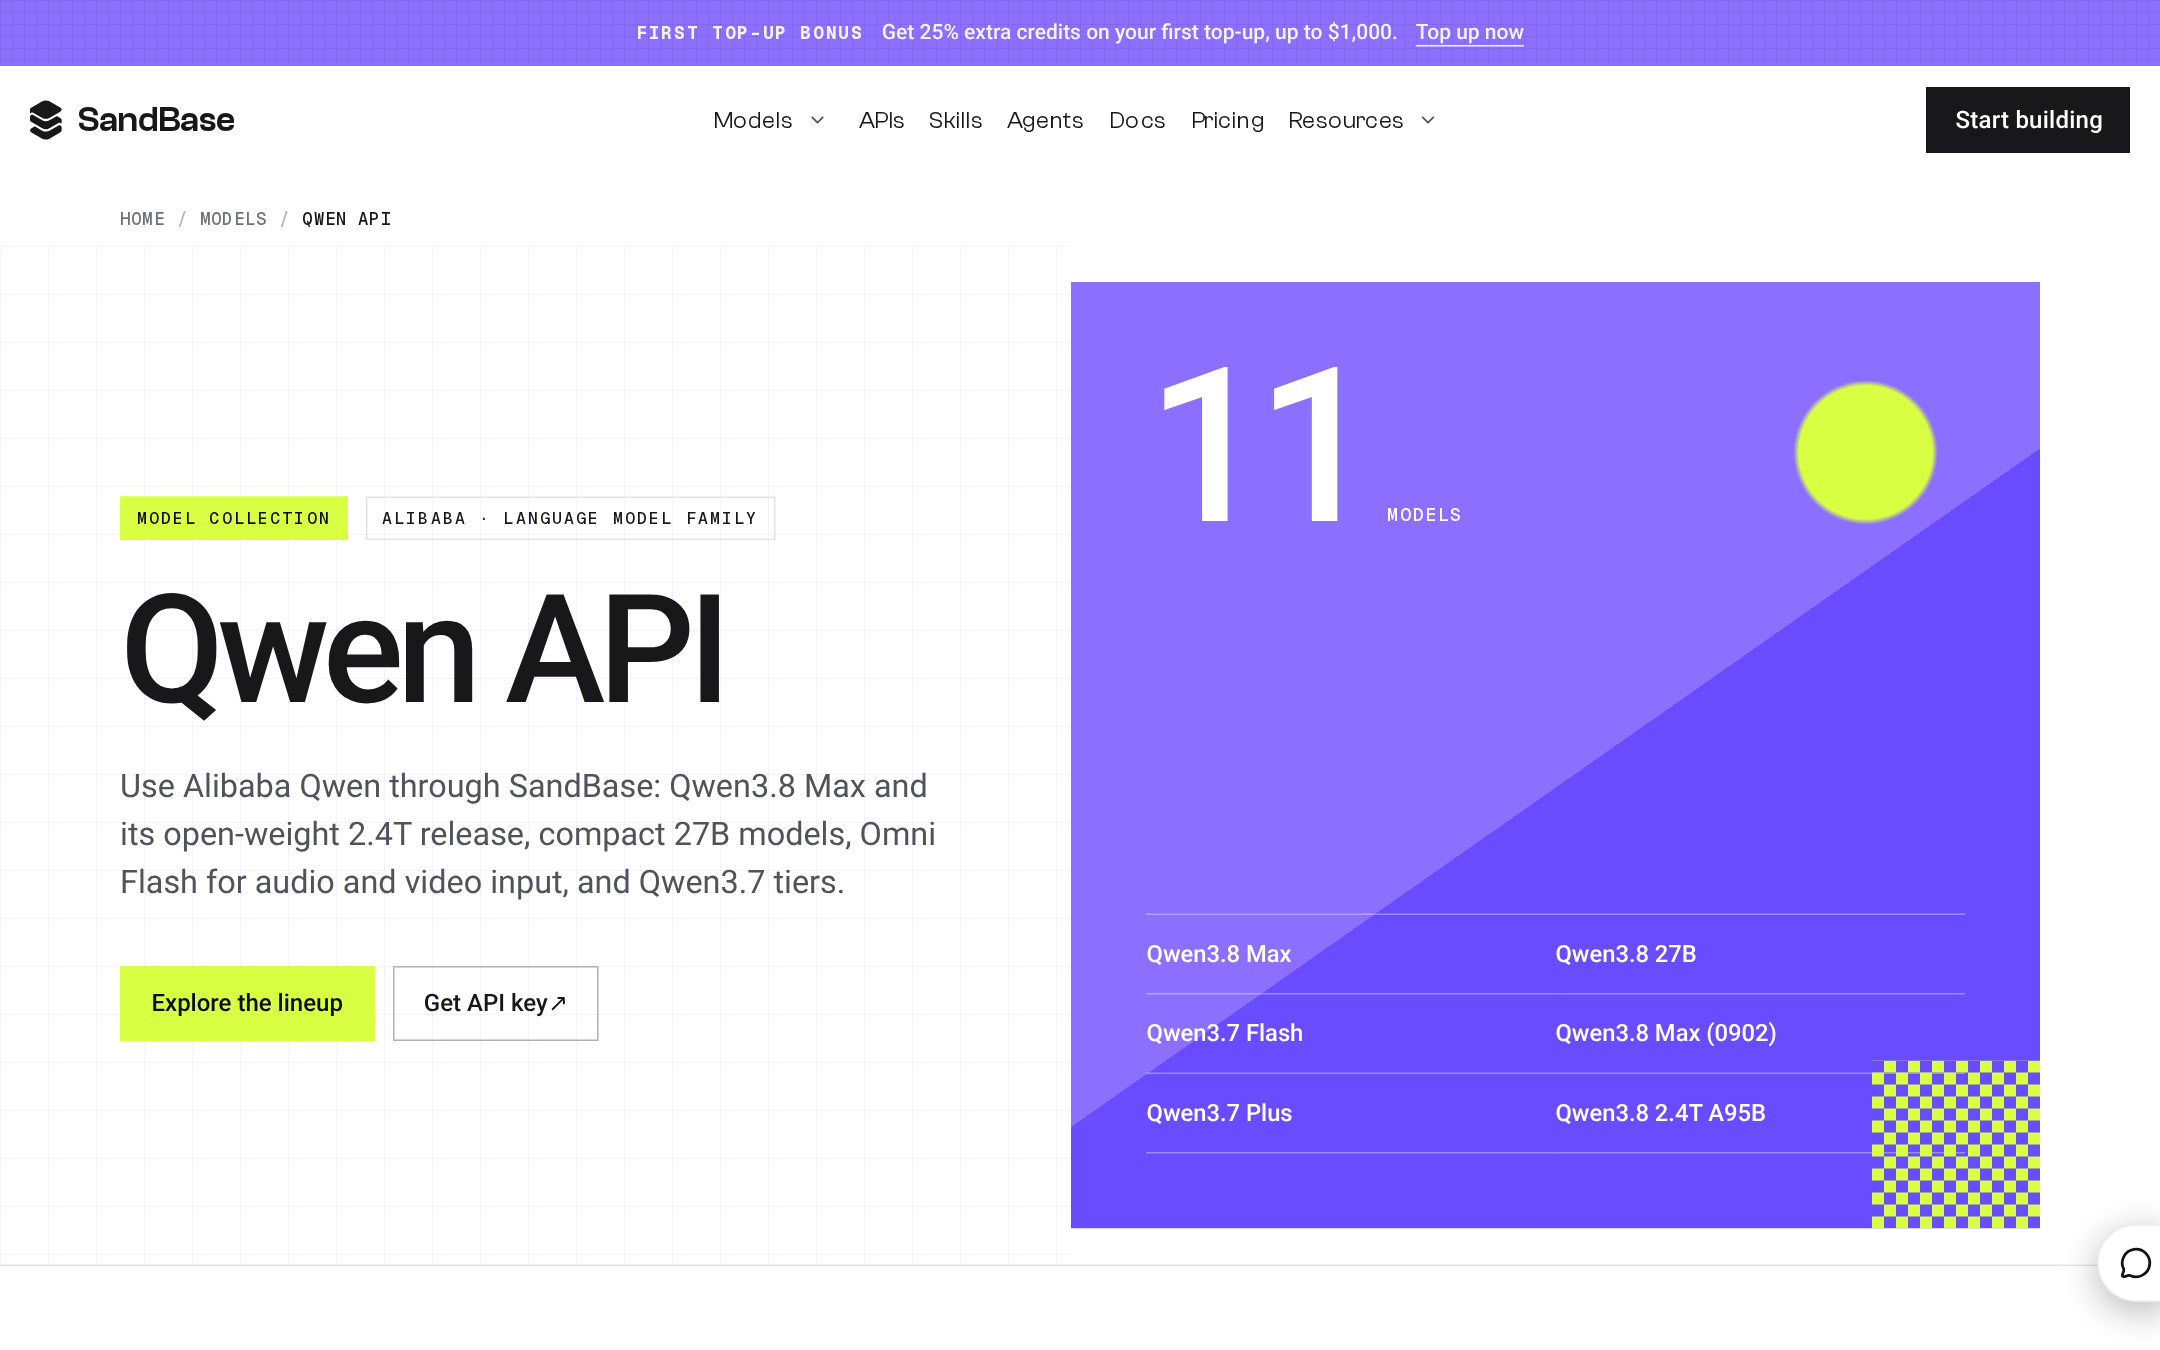
Live SandBase Qwen hub at /models/qwen, captured 15 Nov 2026, Asia/Shanghai. The page still describes the Qwen3.8 and Qwen3.7 lineup — not a Qwen 4 catalog.
The hub shot is the 15 November catalog check. The individual Qwen4-Max card existed by 16 November, so this routing note is stale for the flagship call. The hub title can still omit Qwen4. Read the hero of alibaba/qwen4-max before you treat the three IDs above as the only call.
What to open
Qwen3.8 Max at $1.80 / $5.40 (10% off $2 / $6), cache $0.23 / $2.25, when the work is long-horizon and you want vision on the flagship. Qwen3.8 27B at $0.50 / $3, cache $0.10 / $0.63, when a dense 27B with images and video is enough. Qwen3.8 Omni Flash at $0.15 / $0.47, cache $0.02 / $0.15, when the input includes audio or you want the cheap multimodal text-out path.
Create an account, then follow the first API call. The endpoint for these three is POST https://api.sandbase.ai/v1/chat/completions. The model string is alibaba/qwen3.8-max, alibaba/qwen3.8-27b, or alibaba/qwen3.8-omni-flash.
Generation history, if you want the line rather than today’s router: Qwen 3.7 Max and Qwen 3.6 for agents.
FAQ
Which Qwen ID should a new SandBase call use?
As of 16 November 2026, start flagship work at alibaba/qwen4-max. The 15 November router still holds: alibaba/qwen3.8-max for the previous flagship, alibaba/qwen3.8-27b for a cheaper dense vision model, alibaba/qwen3.8-omni-flash when the input includes audio or you are optimizing multimodal volume. The 15 November check itself found no Qwen4 ID.
When is 27B enough?
When the task fits a dense 27B that understands images and video, and you do not need the Max flagship bill. The card is $0.50 / $3, cache $0.10 / $0.63, with the same 1M / 131.1K labels as Max. This note does not claim a quality tie. It claims a price and a modality fit.
When does Omni Flash win?
When you need audio input, or when image and video can return text at $0.15 / $0.47 with cache read $0.02 and cache write $0.15. Official Qwen4-Max-Preview docs do not list audio input, so the preview is the wrong place to look for that modality.
Does the 2.4T A95B card include vision?
The 15 November 2026 capability list does not include vision. It lists chat, reasoning, structured output, and function calling, at $2 / $6, with max output 52.4K. Use Max, 27B, or Omni Flash for a vision job.
Where does Qwen4-Max-Preview fit?
As a Token Plan evaluation before 24:00 on 25 November 2026 (UTC+8), if you already have access. Official text says the preview model will be retired after that. It is not the ID this page tells you to put in production. The access guide covers the request shape.
Sources
SandBase heroes and the Qwen hub, checked 15 November 2026, Asia/Shanghai: Qwen3.8 Max, Qwen3.8 27B, Qwen3.8 Omni Flash, Qwen3.8 2.4T A95B, Qwen3.8 Flash, Qwen3.8 Max Prime, and the Qwen hub. Official qwen3.8-max and qwen3.8-flash context and output, and the quality-versus-cost recommendation, are from Alibaba’s text generation table. Preview window and the 393,216 output ceiling are from the QwenCloud latest-model page.
Card prices checked 15 November 2026, Asia/Shanghai. Official docs for the 128k labels and the preview window. The SandBase hero for every dollar figure in the routing table.
Found this useful? Share it