Qwen4-Max-Preview vs Qwen3.8 Max: What's Confirmed, and Should You Switch Before November 25?
15 Nov preview-vs-Qwen3.8 record. Update 16 Nov 2026: start new production on GA Qwen4-Max, live on SandBase as alibaba/qwen4-max.
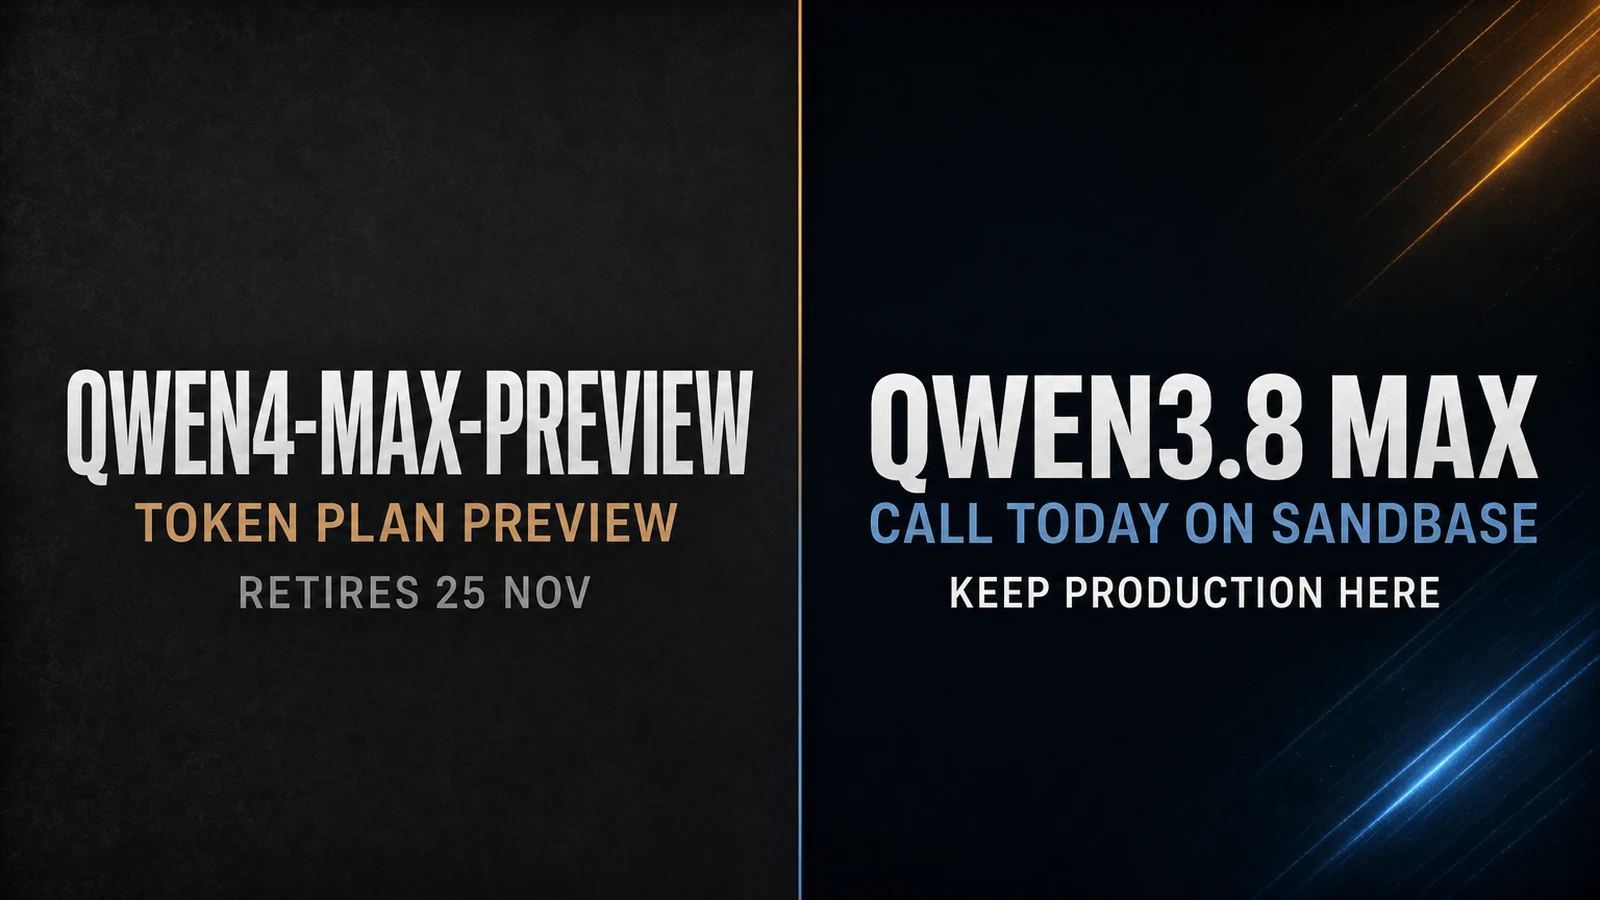
Update (16 Nov 2026): Qwen4-Max is officially generally available with pay-as-you-go, and it is live on SandBase as
alibaba/qwen4-max. New production starts there. This page keeps the 15 November preview-versus-Qwen3.8 record. How to call the GA model is Qwen4-Max Is Generally Available. The current switch decision is Qwen4-Max vs Qwen3.8 Max. The public-price comparison with Gemini 4 Carbon, GPT-6 Astra, and Claude Fable 5.2 is the 16 November comparison.
On 15 November 2026 the production call was to keep Qwen3.8 Max. That evening the SandBase card was live at $1.80 / $5.40 per million tokens, 10% off the $2 / $6 list, with cache read $0.23 and cache write $2.25. Qwen4-Max-Preview was a real official preview you could evaluate on Token Plan until 24:00 on 25 November 2026 (UTC+8). Official copy says the preview model will be retired after that window. That evening, the production ID to leave in place was alibaba/qwen3.8-max. After 16 November, new production belongs on alibaba/qwen4-max.
The search name is “Qwen 4”. The product spelling on the vendor pages is Qwen4-Max-Preview, with no space, and the ID to prefer is qwen4-max-preview. What is confirmed, what is still blank, and which SandBase IDs answer today are split across this note, the 15 November status post Is Qwen 4 Out?, and the 13 November access guide. This page is the switch decision. It does not restate the request-shape migration.
Key takeaway
- Update, 16 Nov 2026: new production starts on Qwen4-Max (
alibaba/qwen4-max). The 15 November verdict below was to stay on Qwen3.8 Max. That evening’s SandBase hero was $1.80 / $5.40 per 1M (10% off list $2 / $6), cache read $0.23, cache write $2.25, 1M context, 131.1K max output. Official Alibaba docs listqwen3.8-maxmax output as 128k. Cite both.- On 15 November, Qwen4-Max-Preview (
qwen4-max-preview) was Token Plan only, from 10:00 on 11 November 2026 to 24:00 on 25 November 2026 (UTC+8). Official text says that preview model will be retired after the window. Pay-as-you-go was not supported on the preview. The preview had no public dollar price per million tokens. The GA model priced on 16 November is a different ID.- Official context is 1,000,000 tokens on both rows. The confirmed output delta on Alibaba’s text-generation table is 393,216 tokens (thinking plus the answer) versus 128k.
- Official preview pages from the 15 November 2026 check have no benchmark table, no parameter count, and no open-weight license. Qwen4-Plus, Qwen4-Flash, and Qwen4-27B are not shipping rows in the 11 November changelog.
- A SandBase call on 15 November used
POST https://api.sandbase.ai/v1/chat/completionsand a Qwen3.8 ID. There was no Qwen4 card to link that evening. As of 16 November the card isalibaba/qwen4-max.
What the 15 November check can put in one table
The useful comparison is status, access, context, output, modalities, scores, and price. Anything else is a rumor column. Sources are the QwenCloud latest-model page, Alibaba’s text generation and visual understanding table, the Model Studio releases entry dated 11 November 2026, and the live Qwen3.8 Max card.
| Item | Qwen4-Max-Preview | Qwen3.8 Max |
|---|---|---|
| Status | Official preview. Scheduled to be retired after 24:00 on 25 Nov 2026 (UTC+8). | Generally available generation you can name today. Live SandBase card. |
| Access | Token Plan only. Pay-as-you-go is not supported. | Public card alibaba/qwen3.8-max on SandBase. |
| Context | Official 1,000,000 tokens. | Official 1M. SandBase card also prints 1M. |
| Max output | Official 393,216, shared by thinking and the final answer. | Official table: 128k. SandBase card: 131.1K. Two labels, two sources. |
| Image and video caps on the official table | 16M pixels per image, 2-hour video, 64 videos. | Same caps on the qwen3.8-max row. |
| Modalities | Official: text generation, image and video understanding. No audio-input claim. | SandBase card lists vision, plus chat, reasoning, structured output, and function calling. Card blurb: 2.4T MoE with native vision, Aug 2026. |
| Benchmarks | No official benchmark table on the pages checked 15 Nov 2026. | This note does not invent a Qwen3.8 score to fill the blank. |
| Price | No public pay-as-you-go unit price. Credits promotions are not a tariff. | SandBase hero $1.80 / $5.40 (10% off $2 / $6). Cache read $0.23 (list $0.25). Cache write $2.25 (list $2.50). |
The Token Plan team overview says the alias of qwen4-max-preview is qwen4.0-max-preview, and bills show the alias. This note uses qwen4-max-preview.
Two output numbers for Qwen3.8 Max have to stay in separate cells. Alibaba’s table prints 128k for qwen3.8-max. The SandBase hero prints 131.1K. A client should follow the limit of the surface it calls. Collapsing them into one “about 128k” cell is how a migration copies the wrong cap.
The generational delta you can defend
On the official text-generation table, context does not move. Both recommended-quality and current-flagship rows are 1M. Image pixels, video length, and video count do not move either: 16M, 2 hours, and 64 on both qwen4-max-preview and qwen3.8-max. The cell that changes is max output: 393,216 for the preview, counted as thinking plus the answer, against 128k for qwen3.8-max.
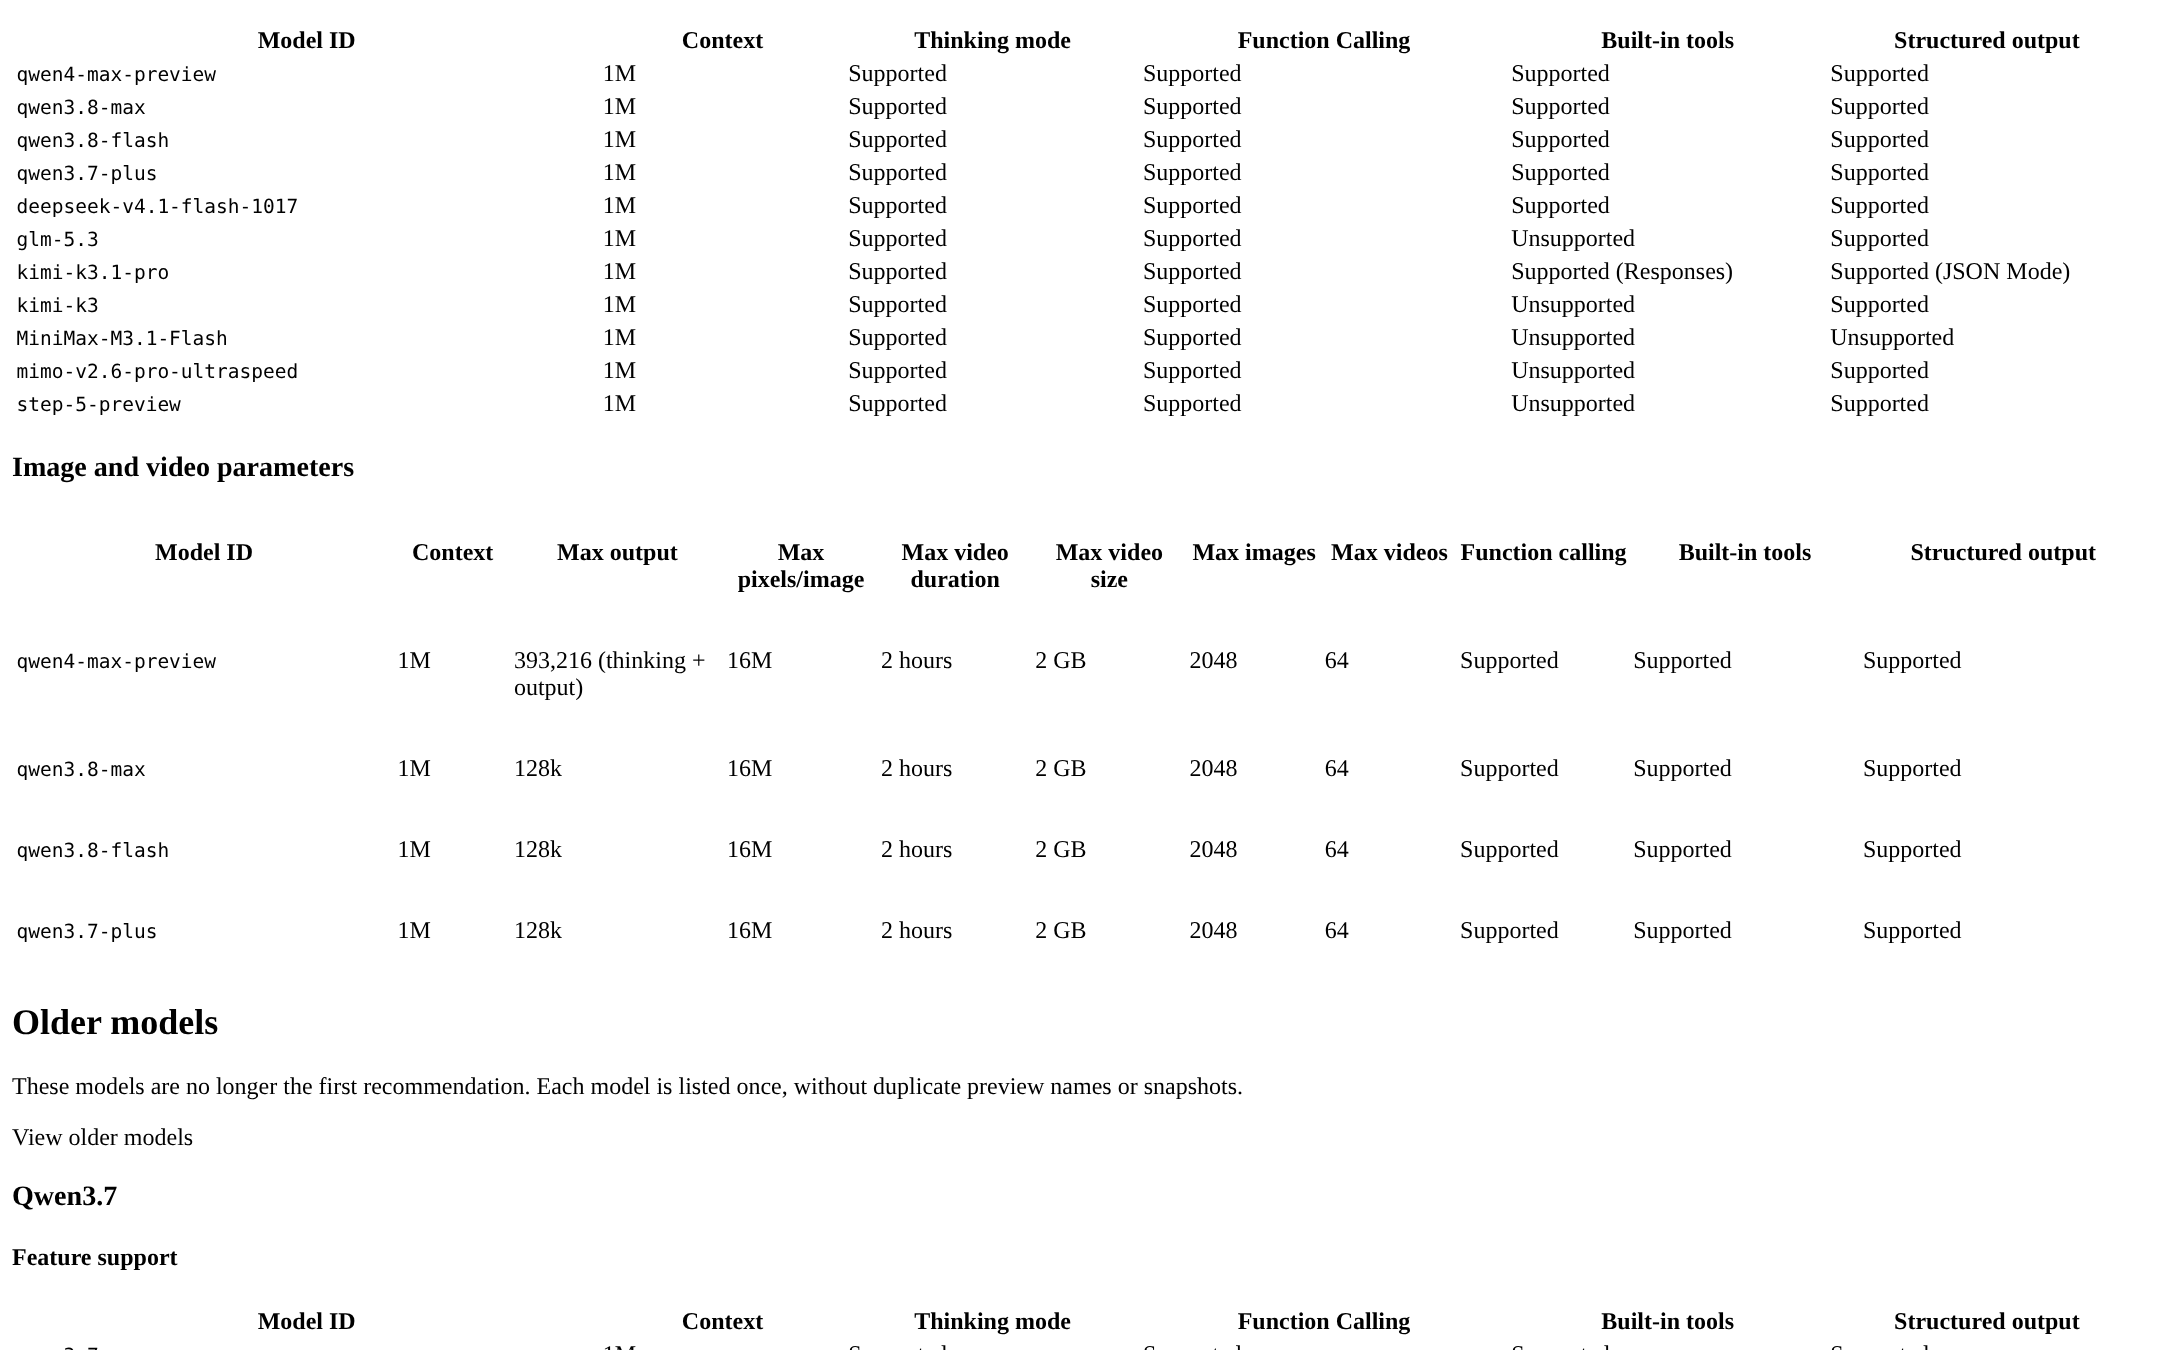
Official Alibaba Cloud “Text Generation and Visual Understanding” table, captured 15 Nov 2026, Asia/Shanghai. The confirmed generational delta on this page is max output: 393,216 (thinking + output) for qwen4-max-preview versus 128k for qwen3.8-max. Context is 1M on both rows.
That crop is an Alibaba docs page. It is evidence for the official caps. It is not a SandBase listing, and it is not a scoreboard.
The same official page currently recommends qwen4-max-preview when you are prioritizing quality, and it marks that row Token Plan only. It recommends qwen3.8-flash when you are prioritizing cost. The two rows it recommends also list thinking, function calling, built-in tools, and structured output as supported. The comparison table marks tools and structured output supported for qwen3.8-max as well. Read the quality line with the access line still attached. The vendor’s quality pick is a preview that the latest-model page says will be retired. A production client that needs a pay-as-you-go ID and a SandBase card still starts at Qwen3.8 Max. The long page for that model is Qwen 3.8 Max: Alibaba’s 2.4T Multimodal Flagship.
Official latest-model copy also positions Qwen4-Max-Preview as the next-generation flagship multimodal model: text generation, image and video understanding, and deep reasoning, aimed at coding, office productivity, frontend design, and complex agentic tasks. It documents web search, tool calling, and structured outputs (JSON Object and JSON Schema), and compatibility with OpenAI Chat Completions, Responses, and Anthropic Messages. Those are capability claims on the preview page. They are not a SandBase route, and they are not a benchmark.
What the request budget means if you do evaluate
Starting with this preview, official docs say max_tokens is equivalent to max_completion_tokens. Both count thinking and the final answer together. Thinking is on by default. reasoning_effort is low, medium, or xhigh, and xhigh is the default. Do not send reasoning_effort and thinking_budget together. Chat Completions enables preserve_thinking by default: return historical thinking in reasoning_content, and do not concatenate it into content.
A 128k max_tokens copied from a Qwen3.8 habit is under the new 393,216 ceiling, and it now has to pay for thinking as well as the answer. That is the migration bug worth a read before anyone points production at the preview. The parameter walkthrough, and the Token Plan base URLs, stay in the 13 November access guide. This note does not re-specify the endpoint.
The preview clock is an exit
The window on the latest-model page is 10:00 on 11 November 2026 through 24:00 on 25 November 2026 (UTC+8). The same page says pay-as-you-go is not supported, no changes are made during the preview, and the model will be retired after the preview ends. 25 November is the scheduled retirement of this preview model. It is not a date this note treats as general availability.
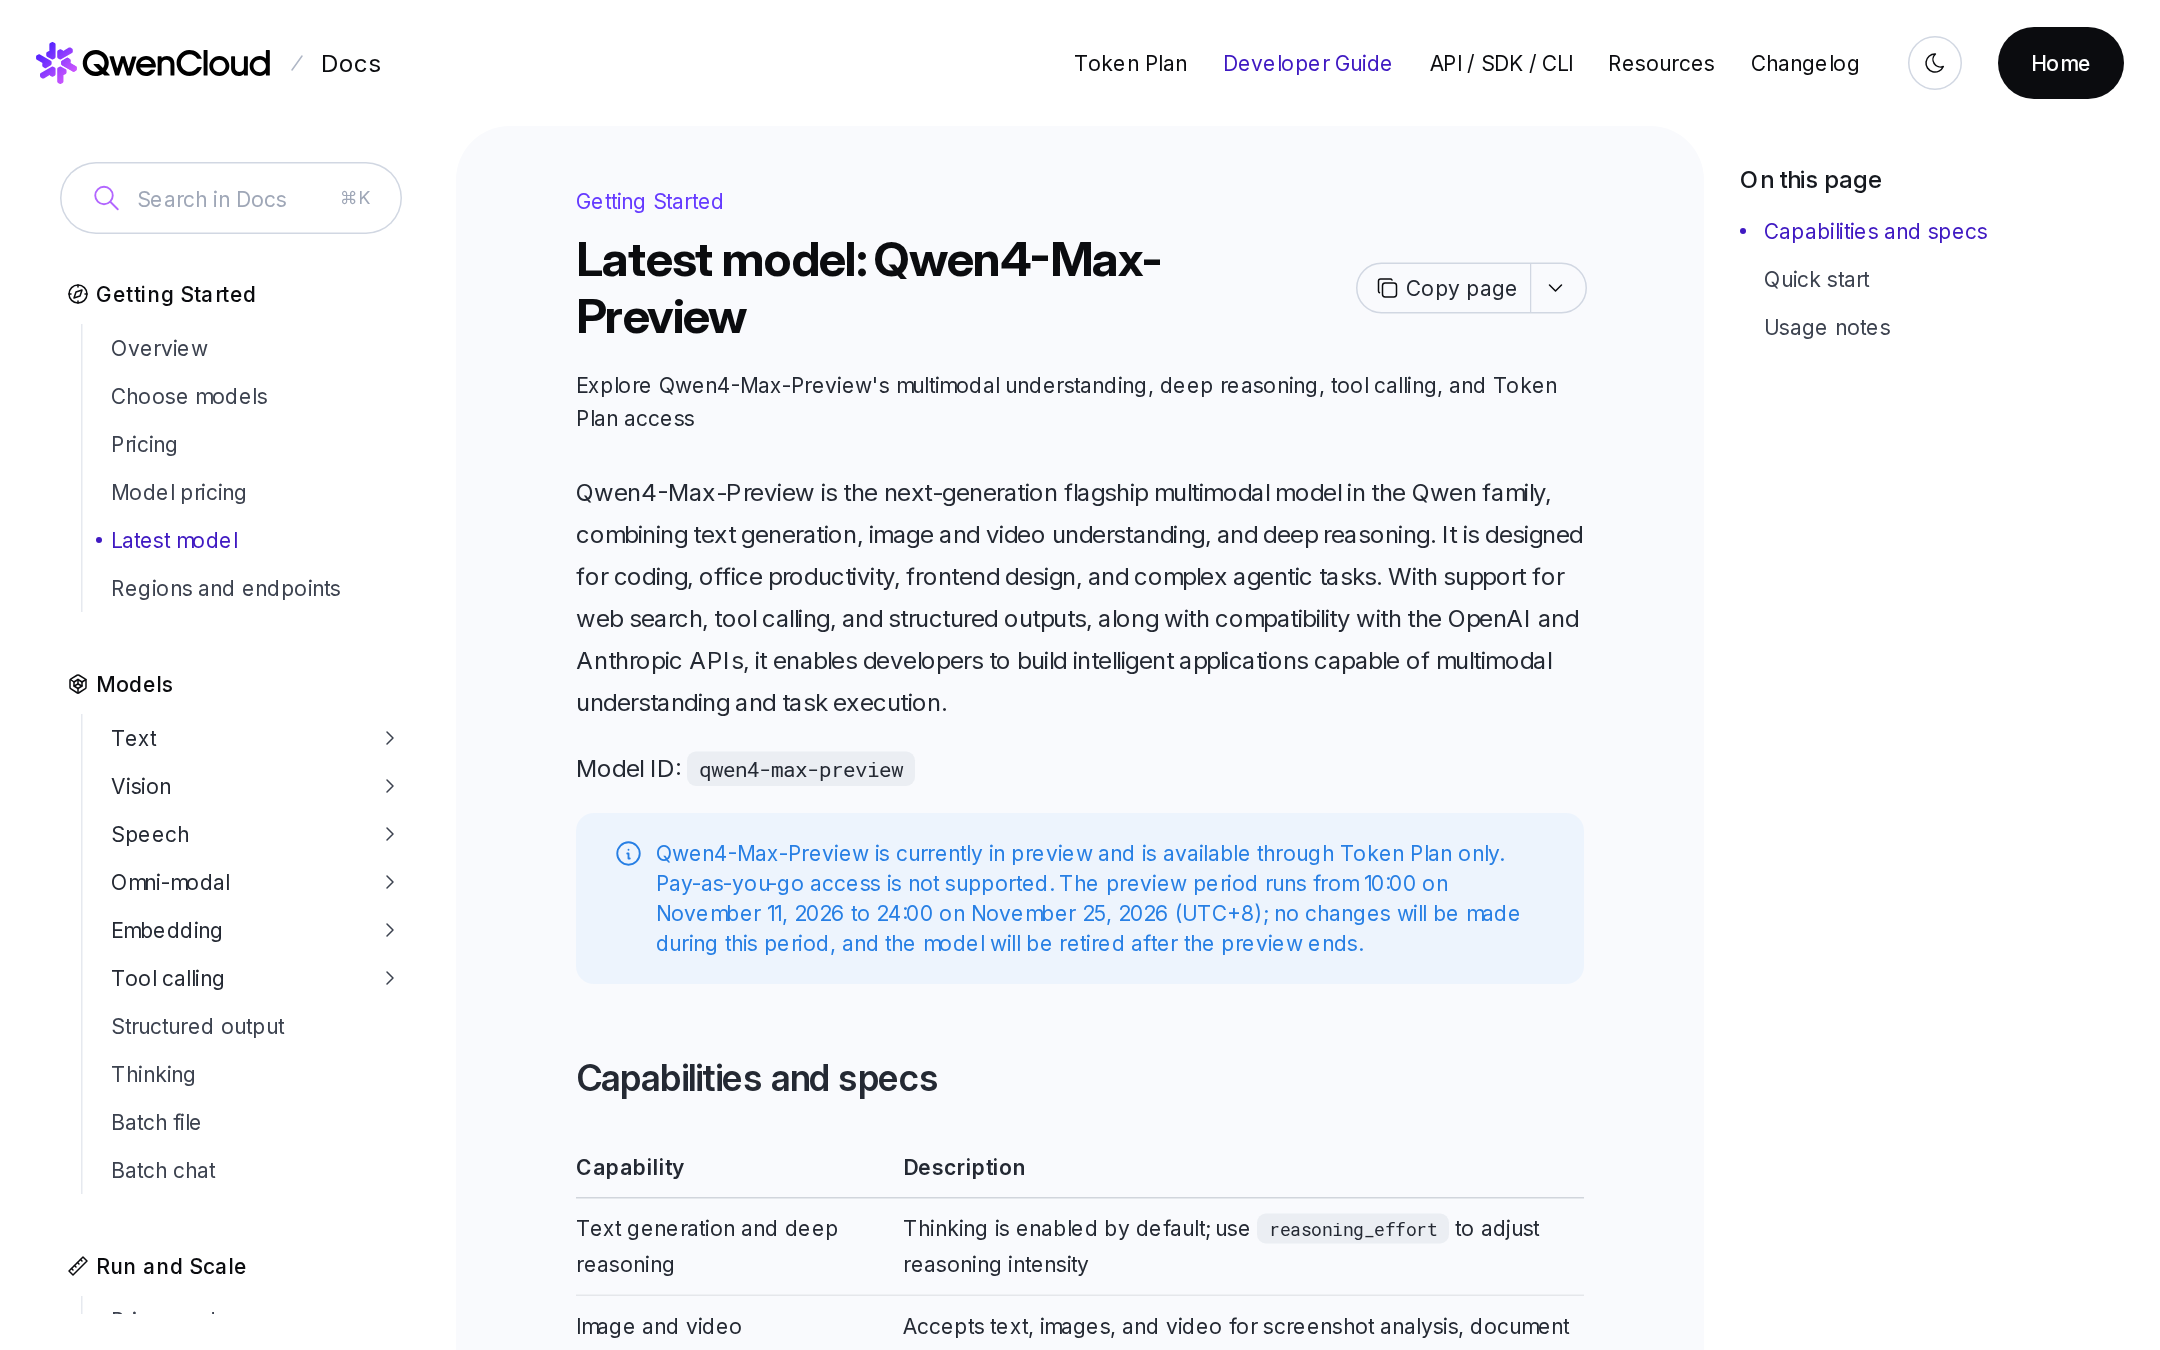
Official QwenCloud latest-model page as of 15 Nov 2026, Asia/Shanghai. It names Qwen4-Max-Preview (qwen4-max-preview), restricts access to Token Plan, and states the preview ends at 24:00 on 25 Nov 2026 (UTC+8), after which the model will be retired.
Token Plan credits, from the product updates page, can run as low as 20% of the standard rate during the preview, which the docs describe as 5x usage. Calls between 22:00 and 08:00 (UTC+8) get an additional 60% off, which is 8% of the standard rate. On the 15 November check the preview still had no public per-token pay-as-you-go price. A percentage of an unpublished standard rate is not a dollar tariff. The GA price published on 16 November belongs to qwen4-max, not to this preview row.
If you already hold a Token Plan key and you want to see whether the 393,216 output budget changes a real job, run that eval before the window closes, and keep a rollback ID. The rollback ID on SandBase is alibaba/qwen3.8-max.
What is still unknown
These cells stayed empty on the 15 November 2026 check. They stay empty here.
- Official benchmark table for Qwen4-Max-Preview. Anecdotal writeups are not a substitute, and this verdict does not use them.
- A public pay-as-you-go price per million tokens.
- Parameter count.
- An open-weight license, or official weights. Unofficial repository forks are not official weights.
- Whether any later Qwen4-Max ships after the preview retires, and whether it keeps this ID.
- Qwen4-Plus, Qwen4-Flash, and Qwen4-27B. Those names are not in the official 11 November changelog. Treat them as reported, not shipped.
The status post records the same blanks, including the official Qwen Hugging Face org search. This comparison does not reopen them as maybes.
What to call today
Call Qwen3.8 Max when the job is the long-horizon Qwen you can actually bill. The 15 November hero is $1.80 input and $5.40 output per 1M tokens, 10% off $2 / $6, with cache read $0.23 and cache write $2.25. The card prints 1M context and 131.1K max output. Official Alibaba docs still print 128k for qwen3.8-max. Route: POST https://api.sandbase.ai/v1/chat/completions.
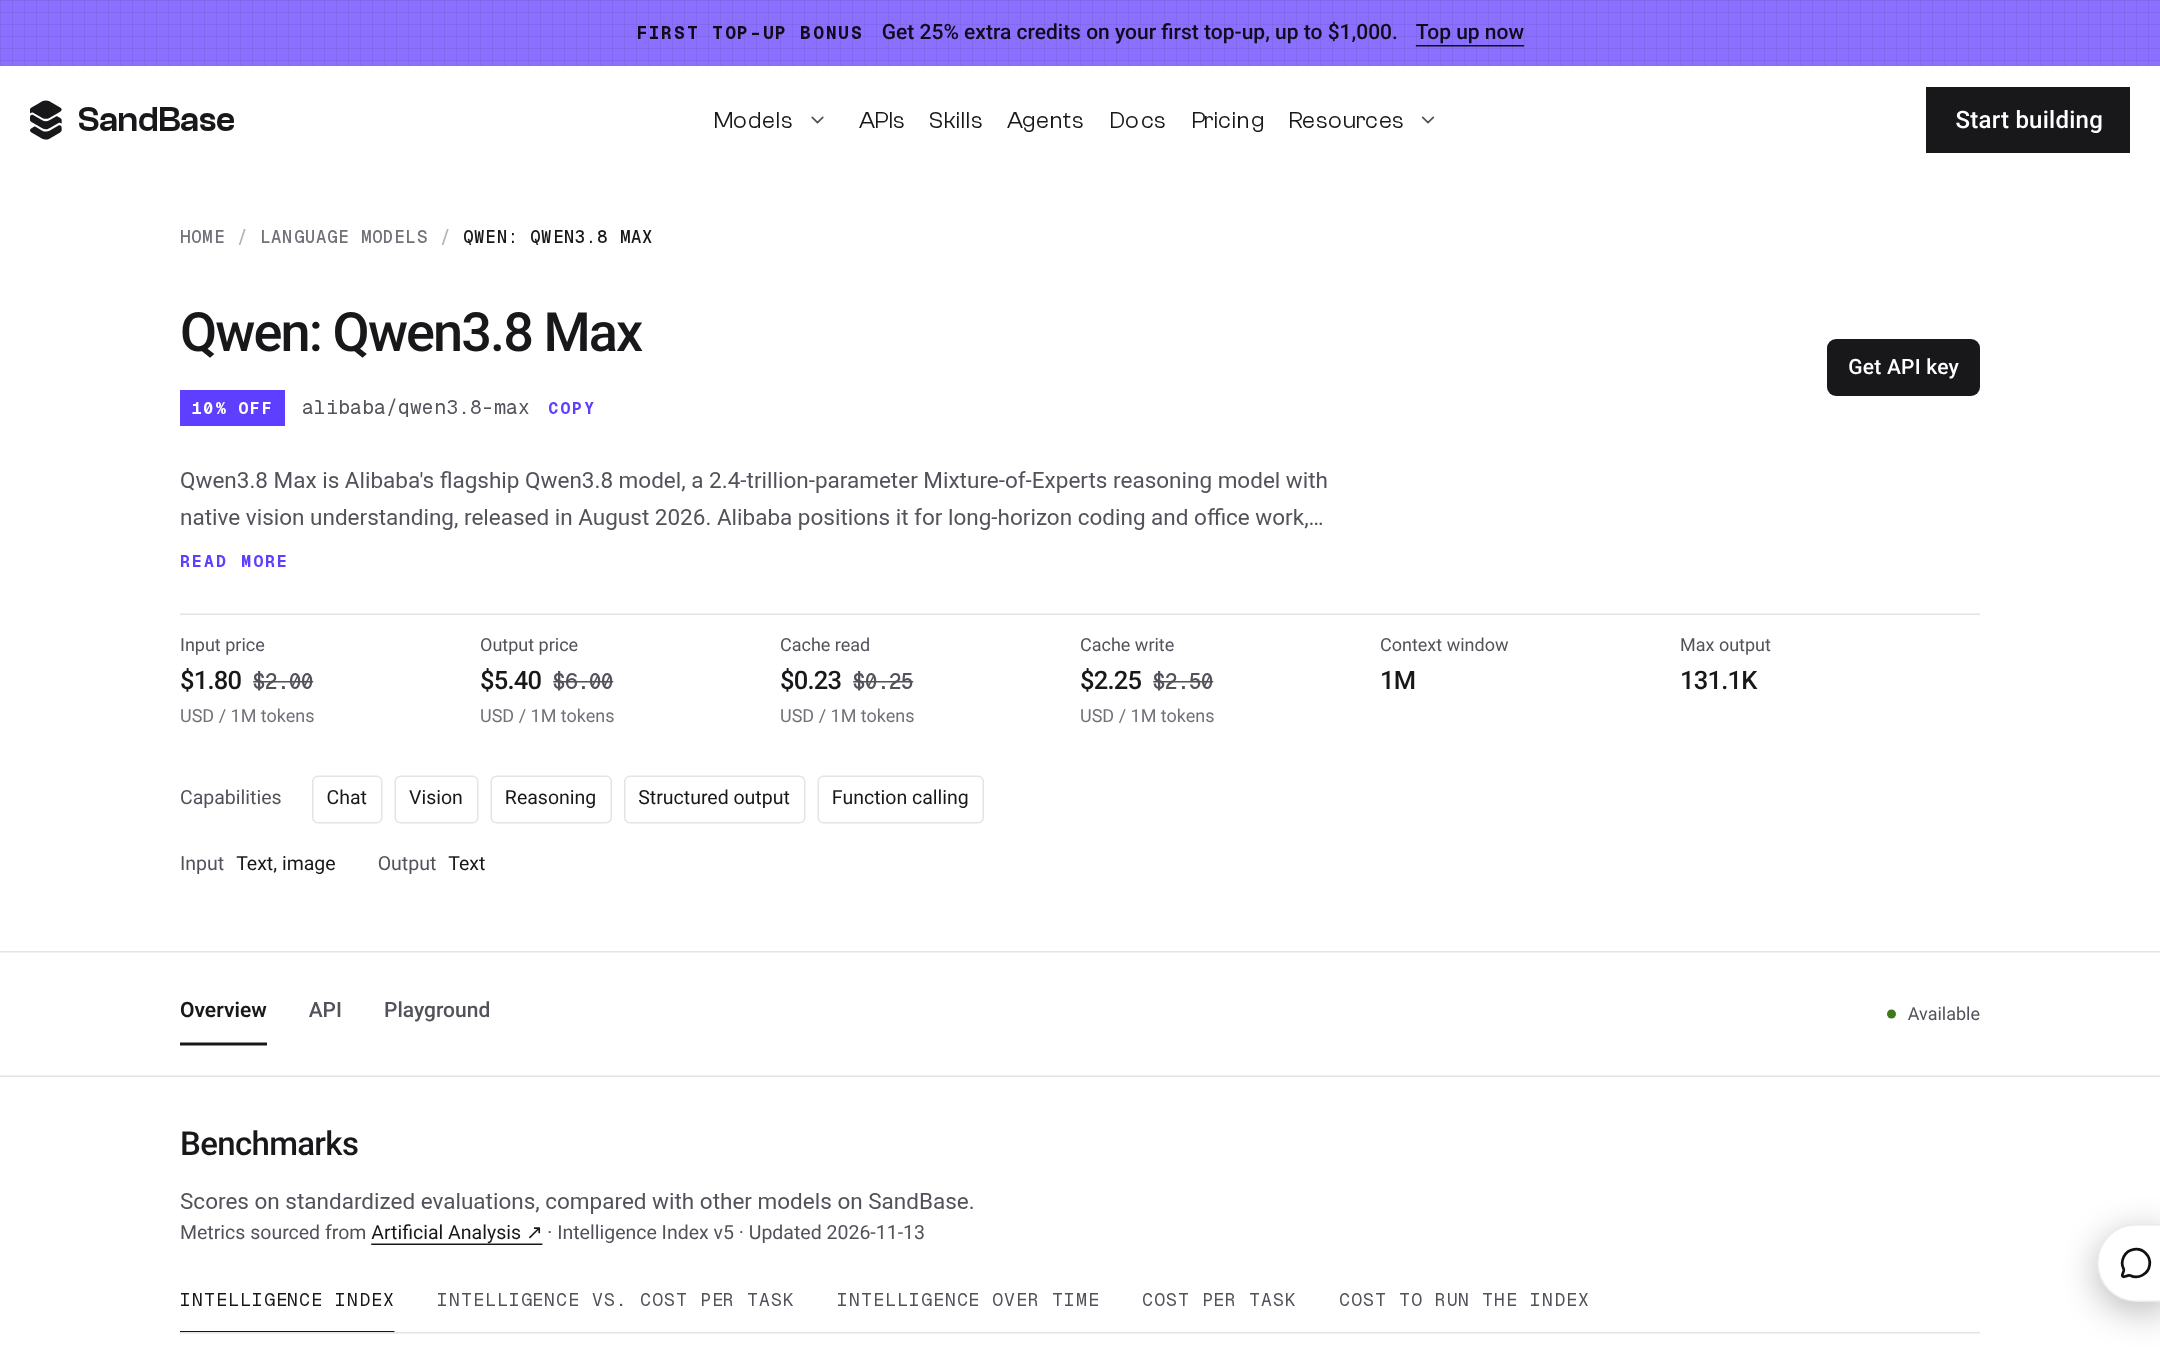
Live SandBase Qwen3.8 Max card at /models/alibaba/qwen3.8-max, captured 15 Nov 2026, Asia/Shanghai (HTML and .md both HTTP 200). Hero is $1.80 / $5.40 (10% off the $2 / $6 list), with cache read $0.23 and cache write $2.25 per 1M tokens. This is the generally available Qwen you can keep in production today.
The 10% badge is on this card. Do not copy it onto the preview, and do not copy it onto the cheaper Qwen3.8 cards, which showed no discount on the same check.
Qwen3.8 27B is the dense open-weight vision-language card at $0.50 / $3 per 1M, cache read $0.10 and cache write $0.63, with 1M context and 131.1K max output. Use it when Max is more model than the job needs and you still want images and video. Qwen3.8 Omni Flash is $0.15 / $0.47, cache read $0.02 and cache write $0.15, same 1M / 131.1K window, and it takes text, image, audio, and video in. The preview’s official input list does not include audio. How to choose among those three, while the preview stays a preview, is the routing note Which Qwen Should You Call Today?.
If the question is how the preview sits next to Gemini 4 Carbon, GPT-6 Astra, and Claude Fable 5.2, that comparison is what you can actually compare today. It is an access and limits comparison. It is not a leaderboard.
The Qwen hub on the same evening still describes the Qwen3.8 and earlier lineup. Create an account (the signup URL redirects to login), then follow the first API call doc. The model string in that call, for this decision, is alibaba/qwen3.8-max.
Earlier notes in the same line, if you want the generation history rather than the preview clock: Qwen 3.7 Max and Qwen 3.6 for agents.
FAQ
Should production switch to Qwen4-Max-Preview before 25 November?
No. Do not move production onto the preview. As of 16 November 2026, new production uses the GA ID alibaba/qwen4-max. On 15 November the production ID this page named was alibaba/qwen3.8-max. Use the preview only as a Token Plan evaluation if you already have access, and finish that evaluation before 24:00 on 25 November 2026 (UTC+8).
Is 25 November 2026 the general-availability date?
The latest-model page schedules retirement of this preview model at 24:00 on 25 November 2026 (UTC+8). A later general-availability model would need its own changelog entry, its own price, and a new SandBase check. This page does not schedule that day as a launch.
Why does one page say 128k and the SandBase card say 131.1K?
They are different surfaces. Official Alibaba docs list 128k max output for qwen3.8-max. The SandBase Qwen3.8 Max card prints 131.1K. Use the cap of the API you are calling, and name the source when you quote it.
Is there a public price for Qwen4-Max-Preview?
No dollar-per-million pay-as-you-go price was on the official pages in the 15 November 2026 check. The published figures are Credits promotions: as low as 20% of the standard rate, and 8% of the standard rate in the 22:00–08:00 (UTC+8) window. Do not quote those percentages as a unit price.
Which SandBase ID replaces the preview after the window?
This 15 November check had no Qwen4 SandBase ID. As of 16 November 2026 the production ID for new work is alibaba/qwen4-max. Qwen3.8 Max remains alibaba/qwen3.8-max. Cheaper multimodal options on the same account are alibaba/qwen3.8-27b and alibaba/qwen3.8-omni-flash.
Sources
Confirmed on 15 November 2026, Asia/Shanghai: the QwenCloud latest-model page, the text generation and visual understanding table, Model Studio releases (11 November 2026 entry), Token Plan product updates, and the Token Plan team overview for the alias. SandBase heroes linked above are from the same evening’s card check. The status post holds the wider “is it out” record. The access guide holds request-shape and base-URL detail.
Reported only, and not used for names, IDs, prices, or the verdict: conference mentions of Qwen4-Plus, Qwen4-Flash, or Qwen4-27B, and unofficial weight repositories.
For the card you can keep in production, open Qwen3.8 Max. For a smaller vision model, open Qwen3.8 27B. For audio input at the low sticker, open Qwen3.8 Omni Flash.
Sources checked 15 November 2026, Asia/Shanghai. Official pages for the preview name, window, output cap, and Credits promotion. The SandBase Qwen3.8 Max hero for the price and the 131.1K label.
Found this useful? Share it