GPT-6.2 Astra and Sol vs Gemini 4 Carbon and Claude Fable 5.2: Access, Context, and Price
Compare GPT-6.2 Astra and Sol with Gemini 4 Carbon and Claude Fable 5.2 on access, context, and price. No quality ranking. SandBase has no 6.2 card.
GPT-6.2 Astra and GPT-6.2 Sol have official API IDs and official prices as of 17 November 2026. That does not make this a ranking of which model is smarter. The comparison you can finish on 18 November is access, context, max output, modalities, and the gap between an official list price and a live SandBase card.
Two of the six rows below are official-only. SandBase returned HTTP 404 for GPT-6.2 Astra and GPT-6.2 Sol on the morning of 18 November 2026, Asia/Shanghai. The other four rows are cards you can open. What shipped, including the changelog rows and the “no bare gpt-6.2 SKU” limit, is GPT-6.2 Astra and Sol Are Officially Out. Whether to leave a live OpenAI tier is GPT-6.2 vs GPT-6 Astra and GPT-6.1 Sol. The 12 November record, from before the launch, is Is GPT-6.2 Out?.
Key takeaway
- GPT-6.2 Astra (
gpt-6.2-astra) and GPT-6.2 Sol (gpt-6.2-sol) are official API models. They are not on SandBase. Do not invent a/models/openai/gpt-6.2-astralink.- Official short-context Standard, per 1M tokens: Astra $8 / $0.40 cached / $40 output. Sol $2 / $0.10 cached / $10 output. Official context is 1,050,000, max output 128,000, text and image in, text out.
- GPT-6 Astra on SandBase is $9 / $45 (10% off $10 / $50), cache read $0.90, cache write $11.25, card 1.1M / 128K. GPT-6.1 Sol is $2 / $10, cache read $0.10, cache write $2.50, no discount badge.
- Gemini 4 Carbon hero is $4 / $20, cache read $0.20, 1M context, 65.5K max output, inputs text, image, audio. No cache-write figure on that hero.
- Claude Fable 5.2 hero is $8 / $40, cache read $0.20, cache write $10, 1M / 128K. SandBase ID uses a dot (
claude-fable-5.2). This page did not re-fetch an Anthropic price sheet on 18 Nov.
The table you can defend
Every figure is labeled with the page it came from on 18 November 2026. Official GPT-6.2 prices are the published model markdown. SandBase prices are the live heroes. “Not listed” means the HTML and the .md 404’d. It does not mean a price of zero.
| Model | Where a request goes today | Short input / output per 1M | Cache on the source cited | Context / max output |
|---|---|---|---|---|
| GPT-6.2 Astra | OpenAI API only | Official $8 / $40 | Official cached input $0.40; 30-minute write $10 | Official 1,050,000 / 128,000 |
| GPT-6.2 Sol | OpenAI API only | Official $2 / $10 | Official cached input $0.10; 30-minute write $2.50 | Official 1,050,000 / 128,000 |
| GPT-6 Astra | SandBase openai/gpt-6-astra | Card $9 / $45, list $10 / $50 | Card read $0.90, write $11.25 | Card prints 1.1M / 128K |
| GPT-6.1 Sol | SandBase openai/gpt-6.1-sol | Card $2 / $10 | Card read $0.10, write $2.50 | Card prints 1.1M / 128K |
| Gemini 4 Carbon | SandBase google/gemini-4-carbon | Card $4 / $20 | Card read $0.20; no write on the hero | Card prints 1M / 65.5K |
| Claude Fable 5.2 | SandBase anthropic/claude-fable-5.2 | Card $8 / $40 | Card read $0.20, write $10 | Card prints 1M / 128K |
Official long context for both 6.2 models, above 272K input tokens, doubles input and cache and multiplies output by 1.5 for the full request. Batch is half of Standard. Fast is 2×. Ultrafast is 3× through 28 February 2027 and 6× from 1 March 2027, Pacific time. Those multipliers are on the model pages. They are not SandBase tiers.
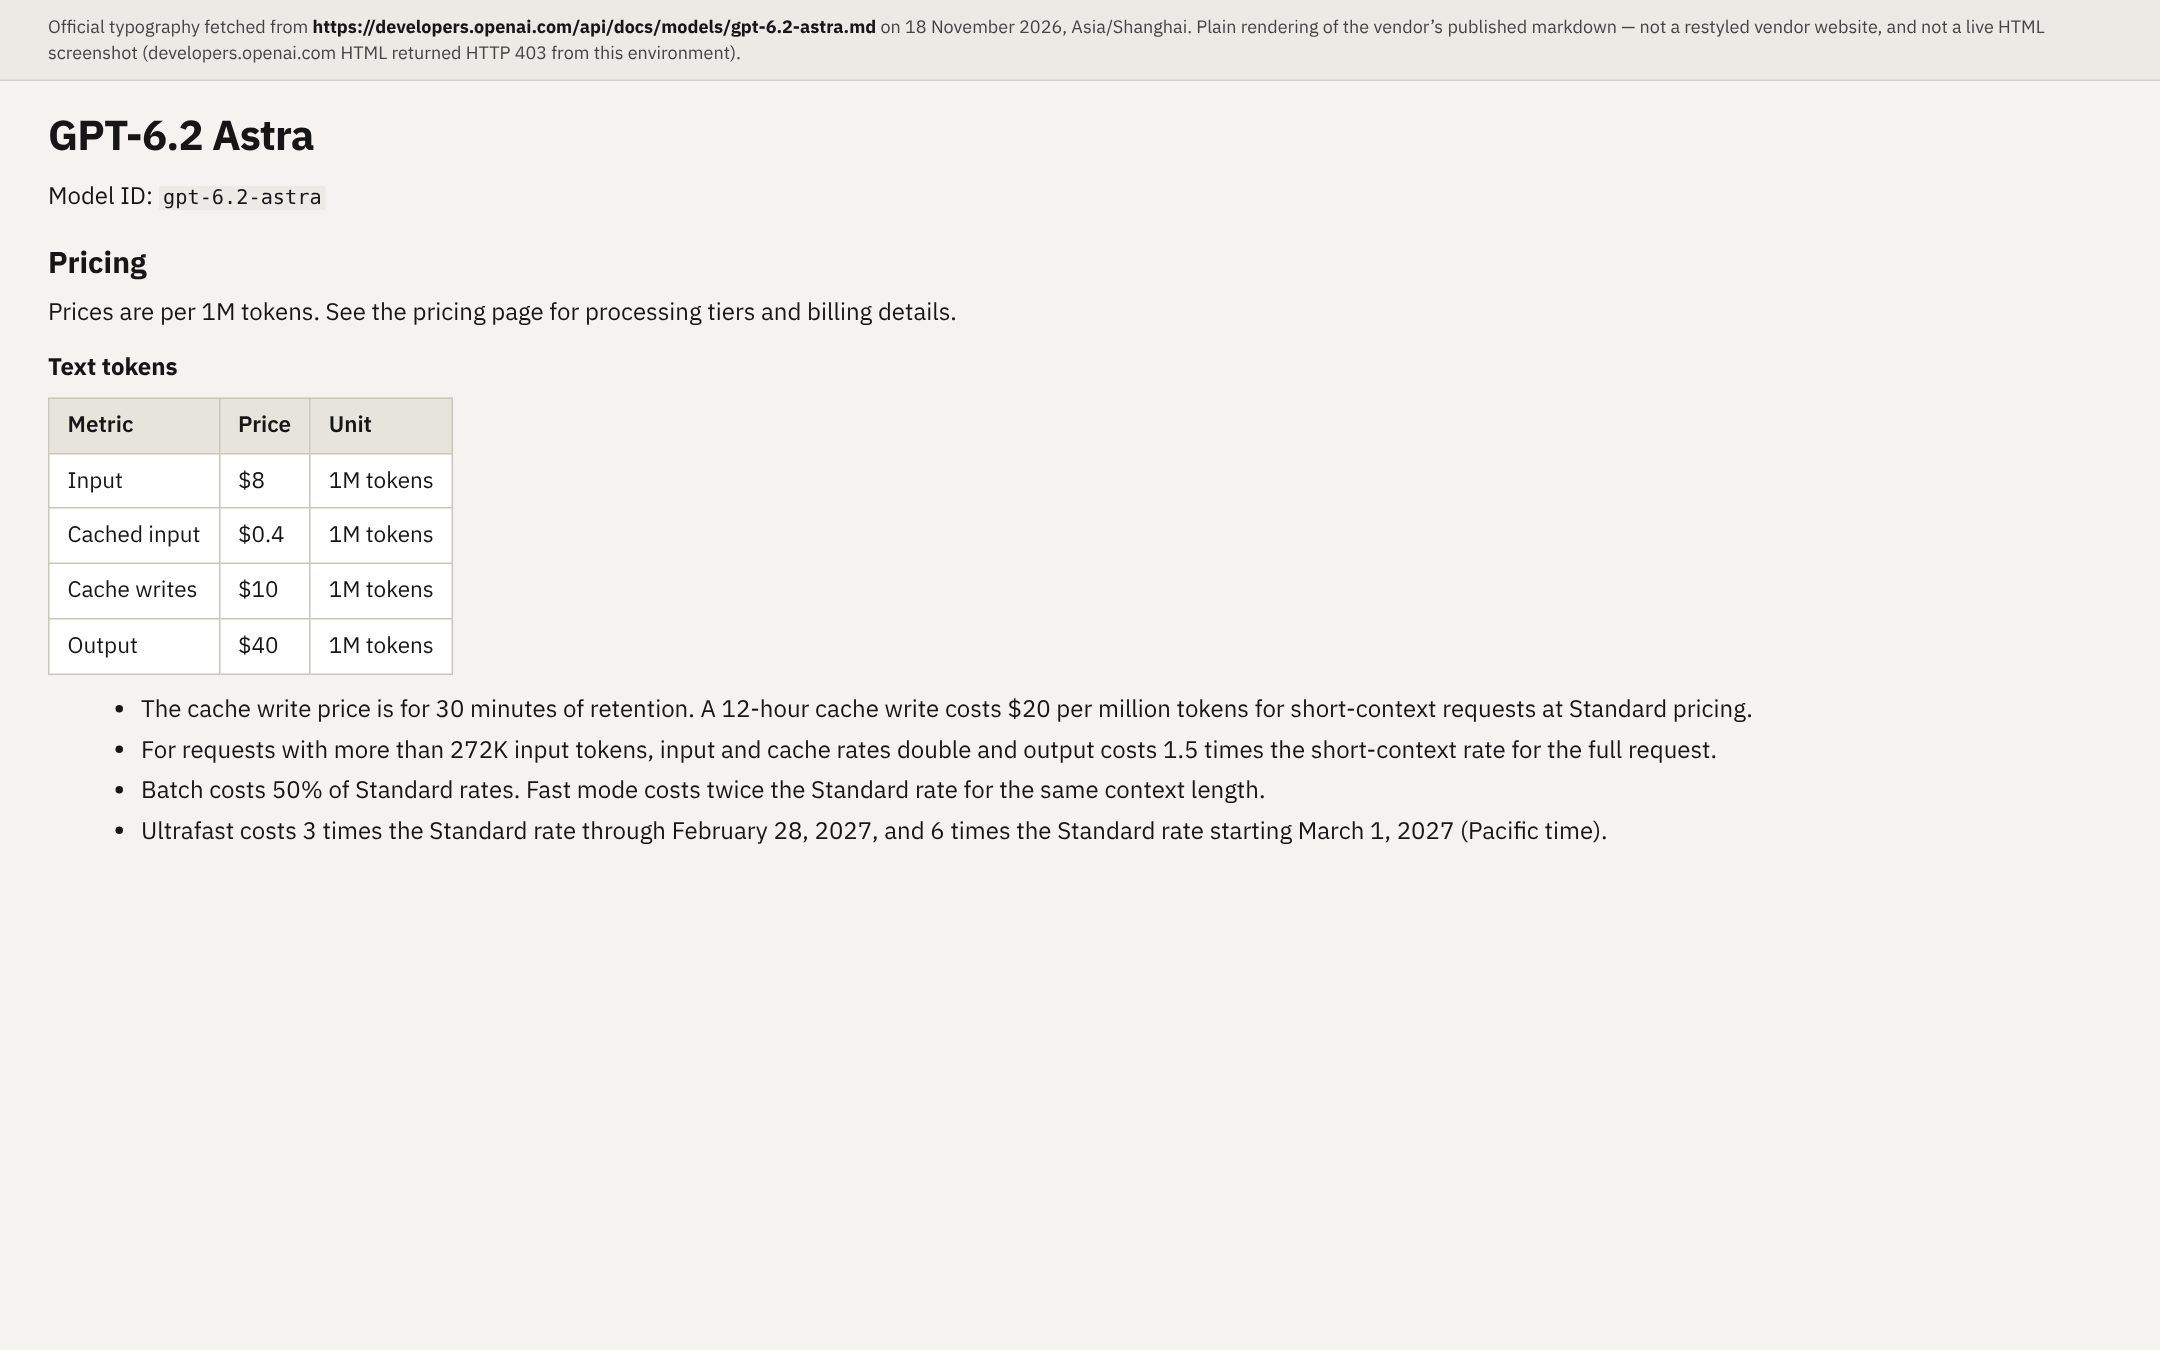
Official GPT-6.2 Astra pricing typography from https://developers.openai.com/api/docs/models/gpt-6.2-astra.md, fetched 18 November 2026, Asia/Shanghai. Plain rendering of published official markdown, not a live HTML screenshot (HTML 403 from this environment). The table prints $8 input, $0.4 cached input, $10 cache writes, $40 output per 1M tokens. The bullets print: 30-minute cache-write rate, 12-hour cache writes at $20 / 1M for short-context Standard, input and cache rates double and output 1.5× when input exceeds 272K tokens, Batch at 50% of Standard, Fast at 2× Standard, Ultrafast at 3× Standard through 28 February 2027 and 6× starting 1 March 2027 (Pacific time).
Cite 1,050,000 when you mean OpenAI’s GPT-6.2 or GPT-6 Astra window. Cite 1.1M only when you mean the number printed on a SandBase GPT-6 card. Carbon’s card prints 1M and 65.5K. Do not “correct” that hero to 1,048,576 in the same sentence, and do not assume the card exposes a 1M long-decode path. The 11 November note on Google’s own window is Gemini 4 Carbon is now available. This check did not re-fetch Google’s pricing page, so it does not restate the $2 / $10 intro clock. The number a SandBase request sees today is the $4 / $20 hero.
What each live card shows
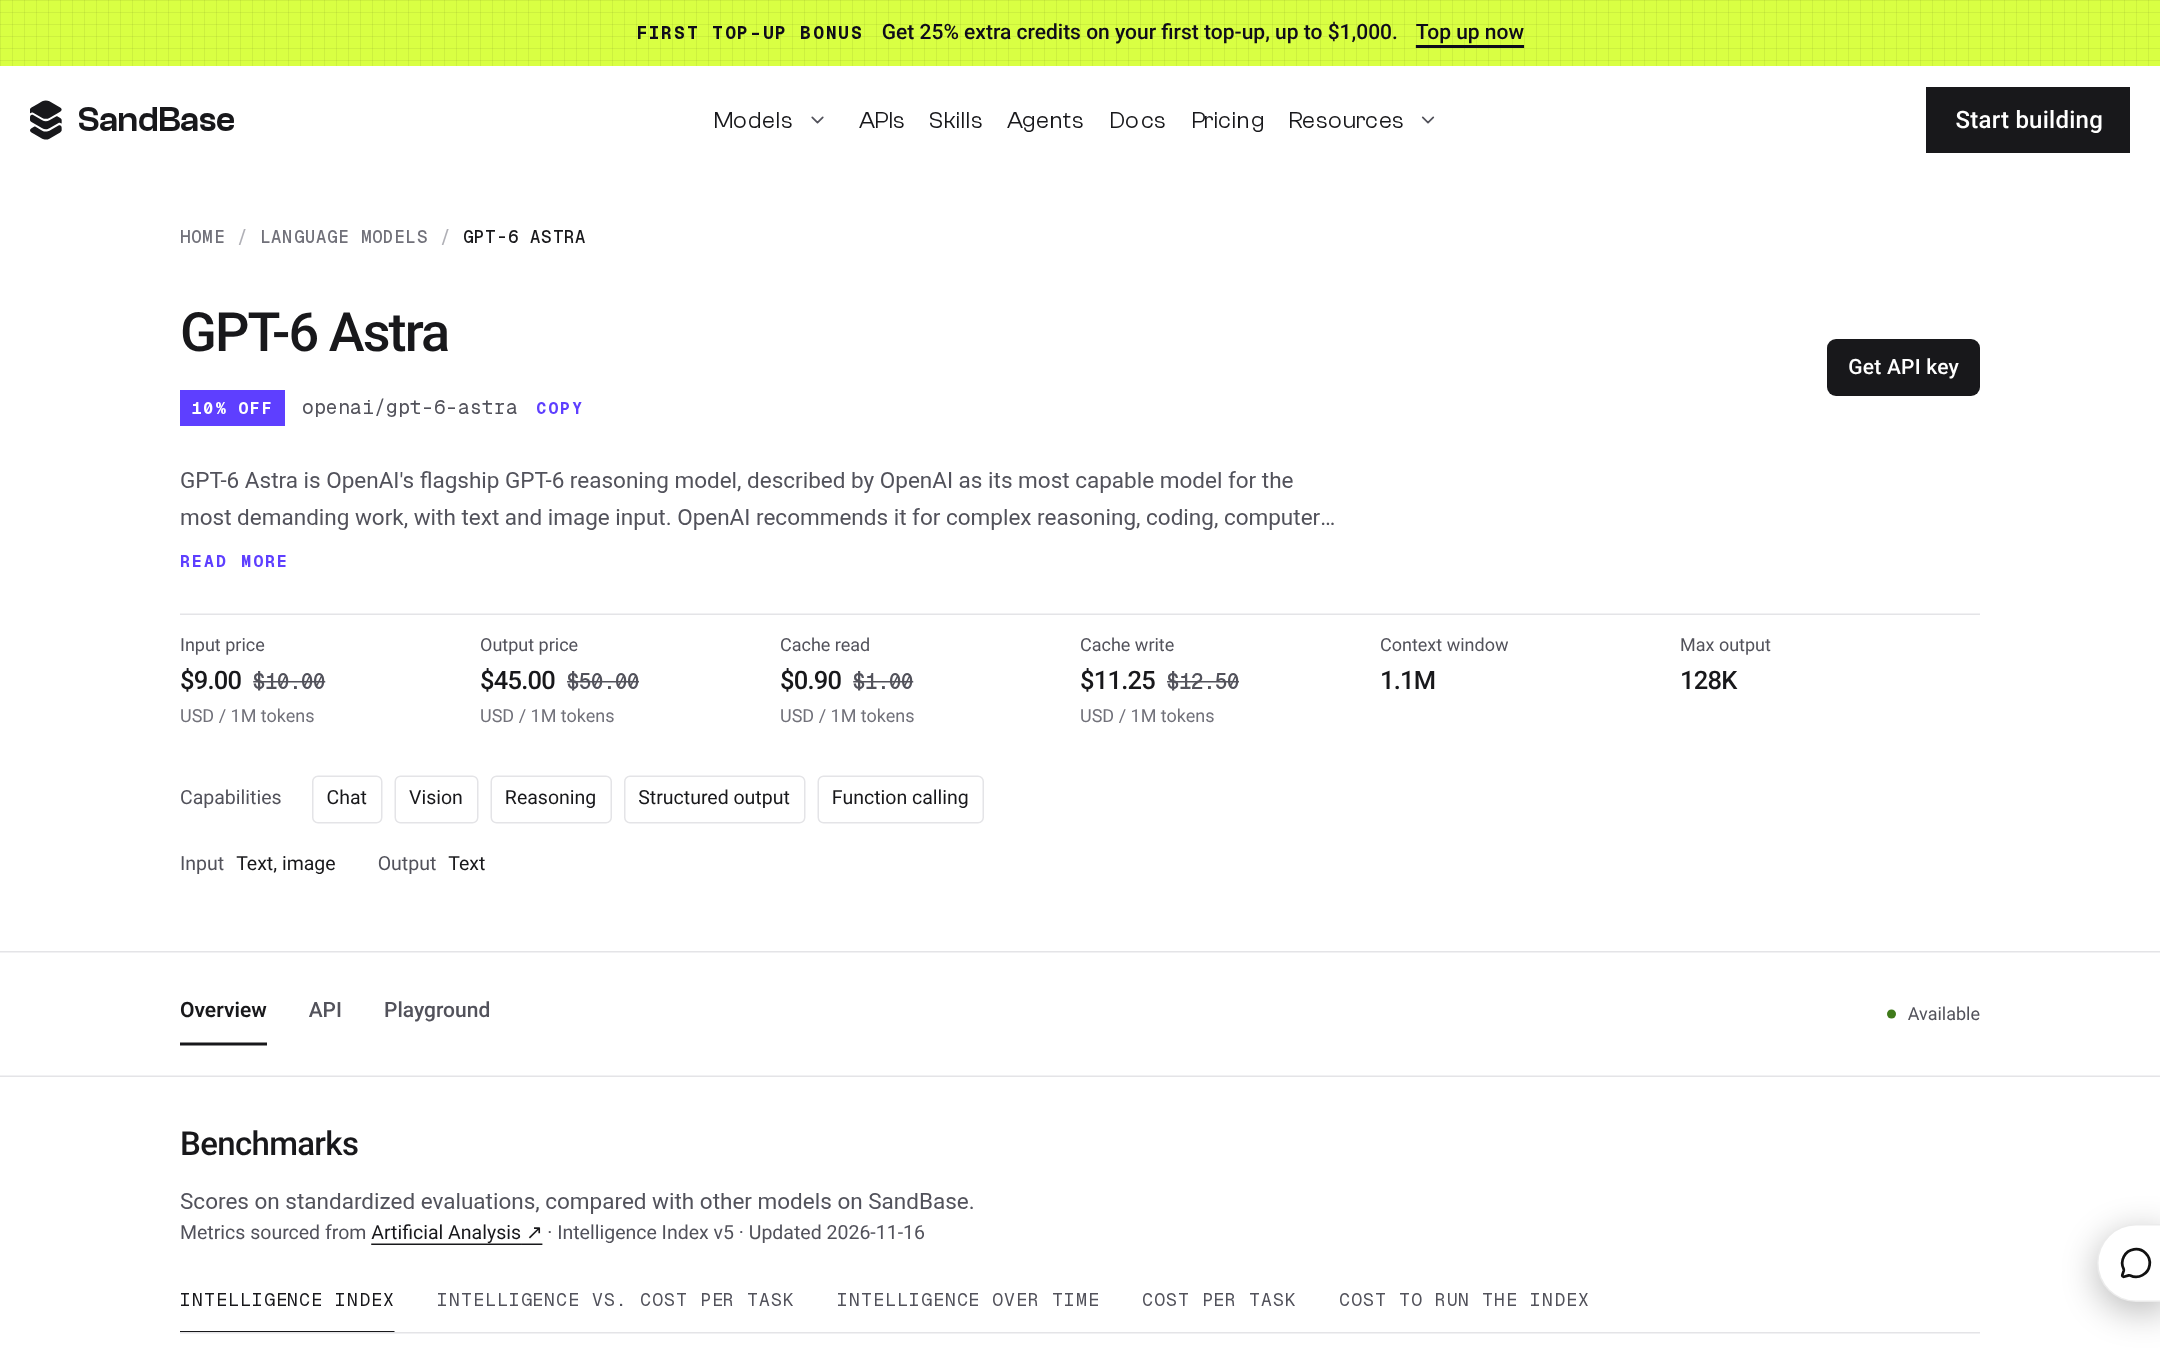
Live SandBase GPT-6 Astra card at /models/openai/gpt-6-astra, captured 18 November 2026, Asia/Shanghai (HTTP 200). Hero is $9.00 / $45.00 (10% off the $10.00 / $50.00 list), with cache read $0.90 and cache write $11.25 per 1M tokens, 1.1M context, 128K max output. This is a predecessor listing, not a GPT-6.2 card. A site-wide first-top-up bonus banner is visible at the top; it is not a model discount. Only the Astra card carries a 10% OFF badge.
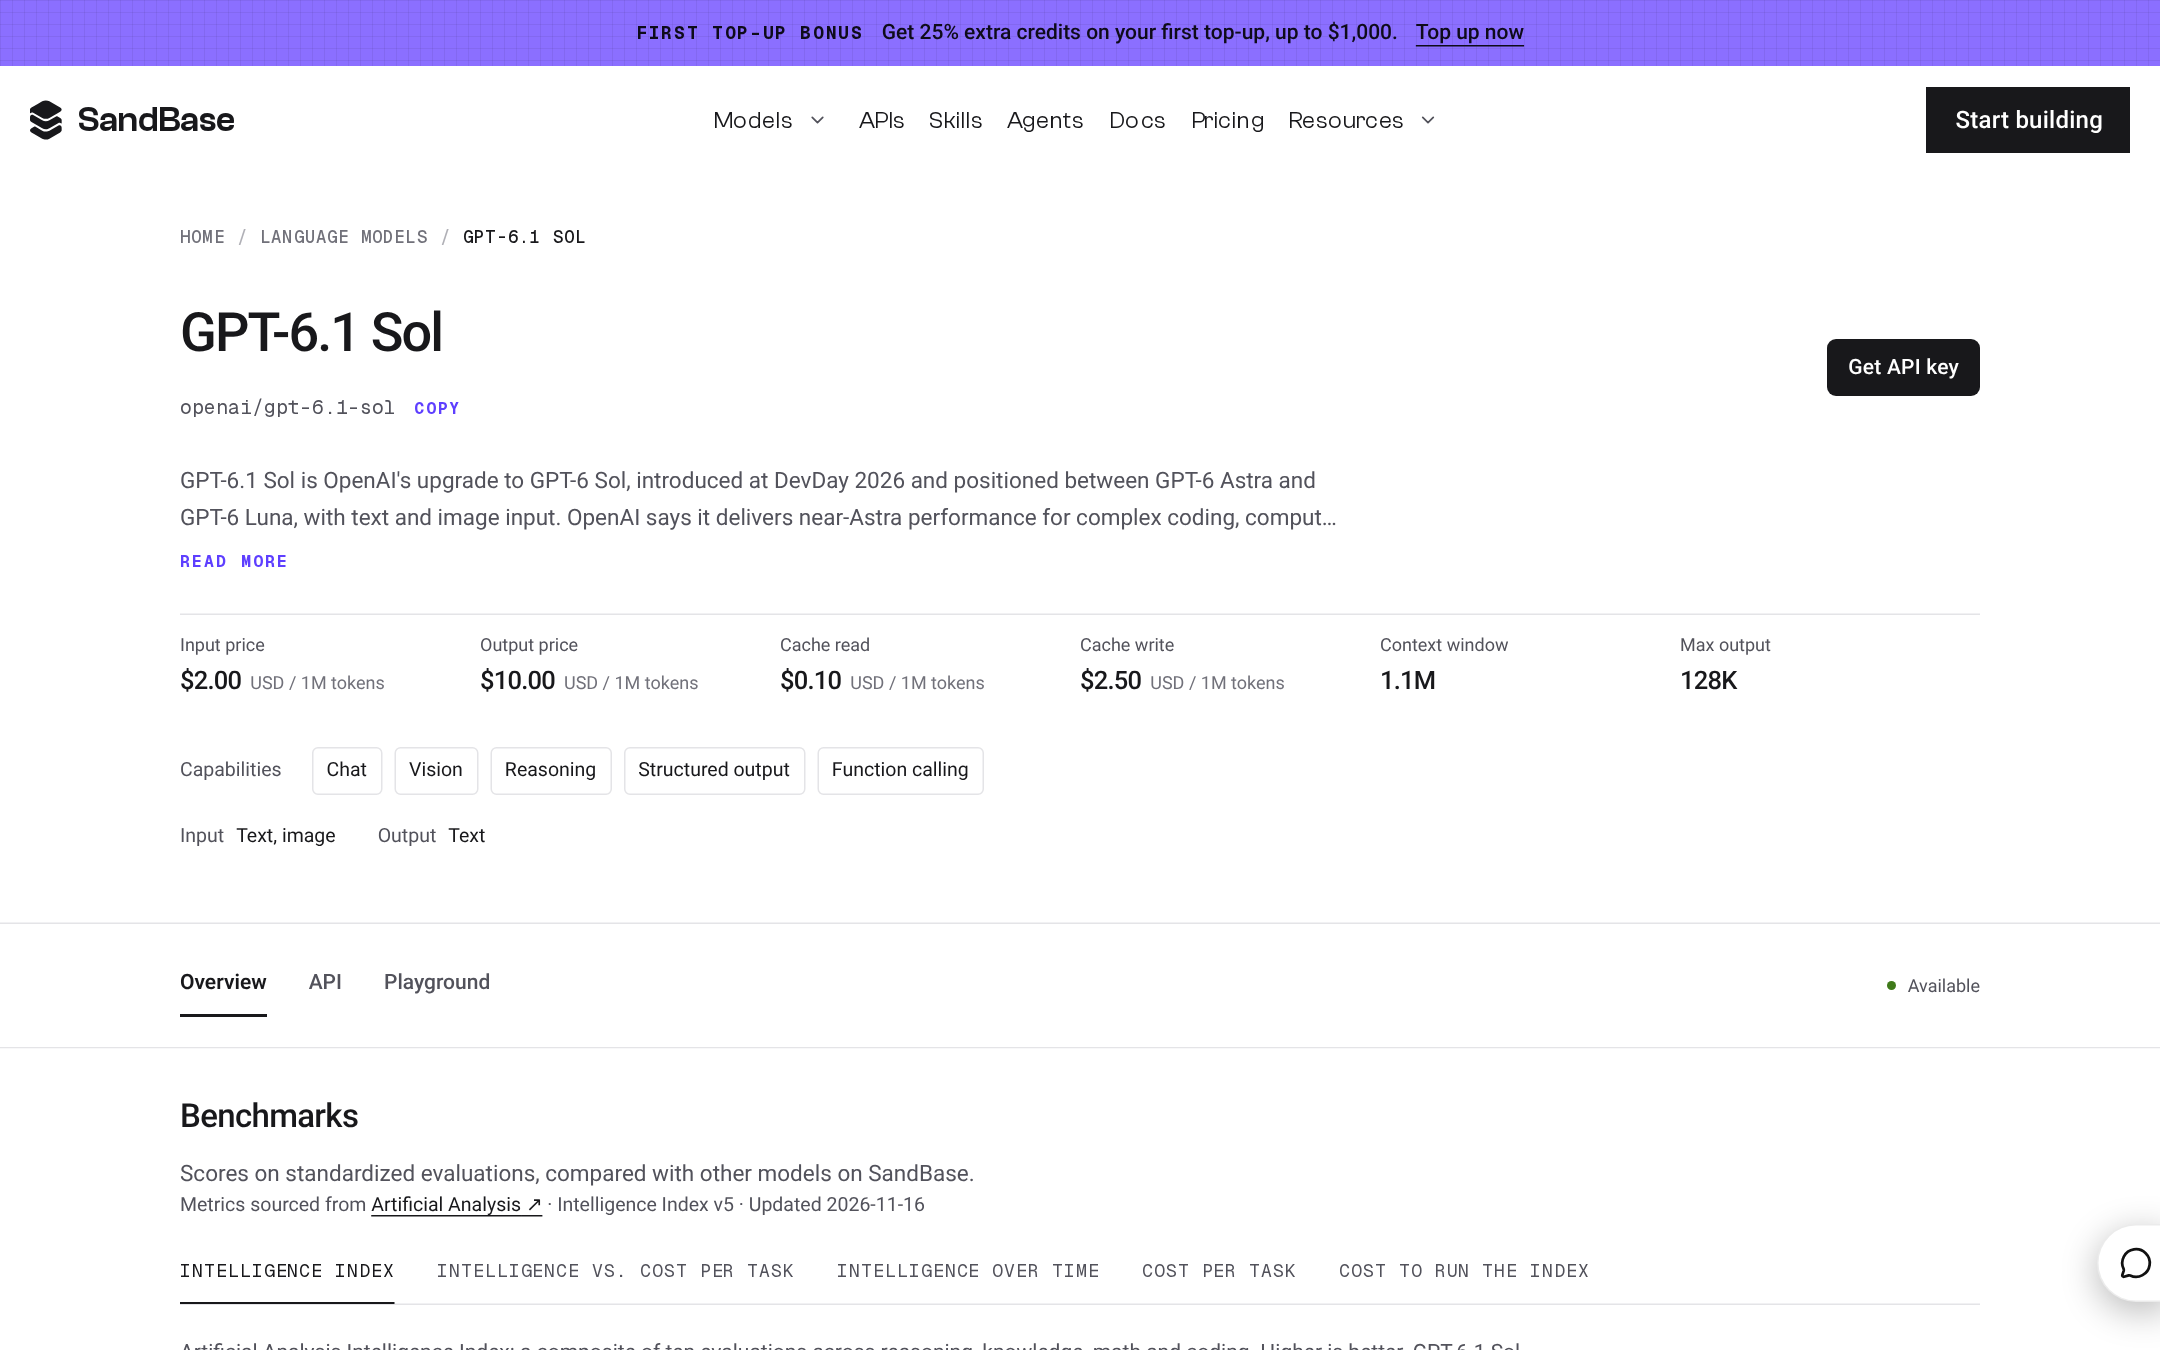
Live SandBase GPT-6.1 Sol card at /models/openai/gpt-6.1-sol, captured 18 November 2026, Asia/Shanghai (HTTP 200). Hero is $2.00 / $10.00, cache read $0.10, cache write $2.50 per 1M tokens, 1.1M context, 128K max output, no discount badge. This is a live predecessor listing, not a GPT-6.2 Sol card. A site-wide first-top-up bonus banner is visible at the top; it is not a model discount. Only the Astra card carries a 10% OFF badge.
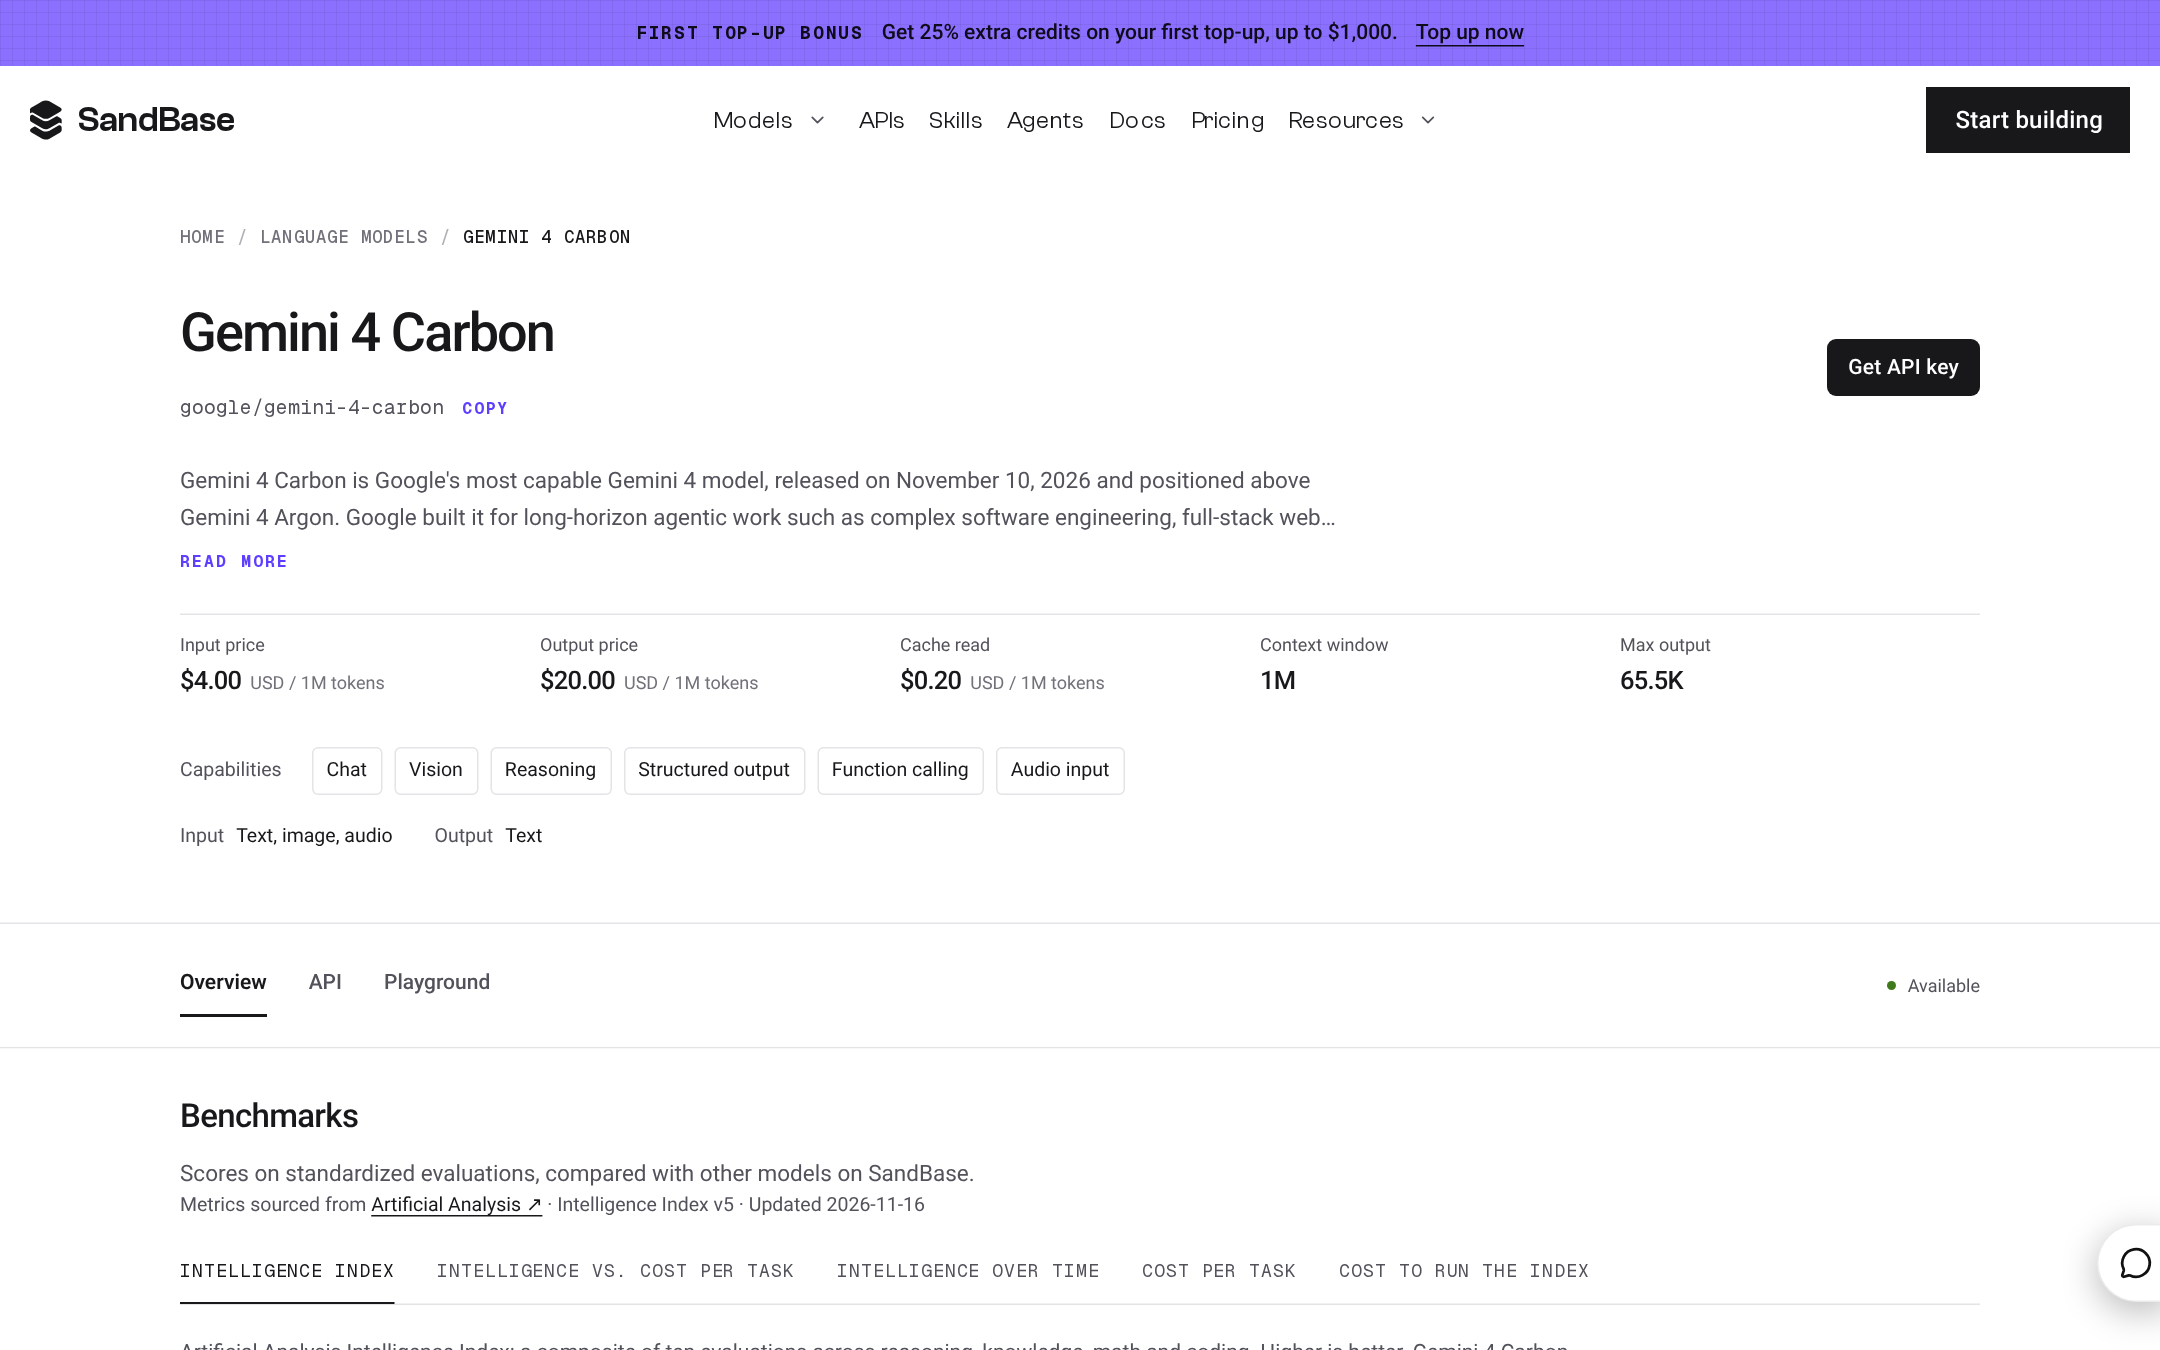
Live SandBase Gemini 4 Carbon card at /models/google/gemini-4-carbon, captured 18 November 2026, Asia/Shanghai (HTTP 200). Hero is $4.00 / $20.00, cache read $0.20, no cache-write cell, 1M context, 65.5K max output. Capabilities include Audio input. Hero inputs: text, image, audio. Official GPT-6.2 model pages list audio as unsupported — if the job is audio in, Carbon is the live card to point at, not a 6.2 listing. A site-wide first-top-up bonus banner is visible at the top; it is not a model discount. Only the Astra card carries a 10% OFF badge. How to call the card is Gemini 4 Carbon on SandBase.
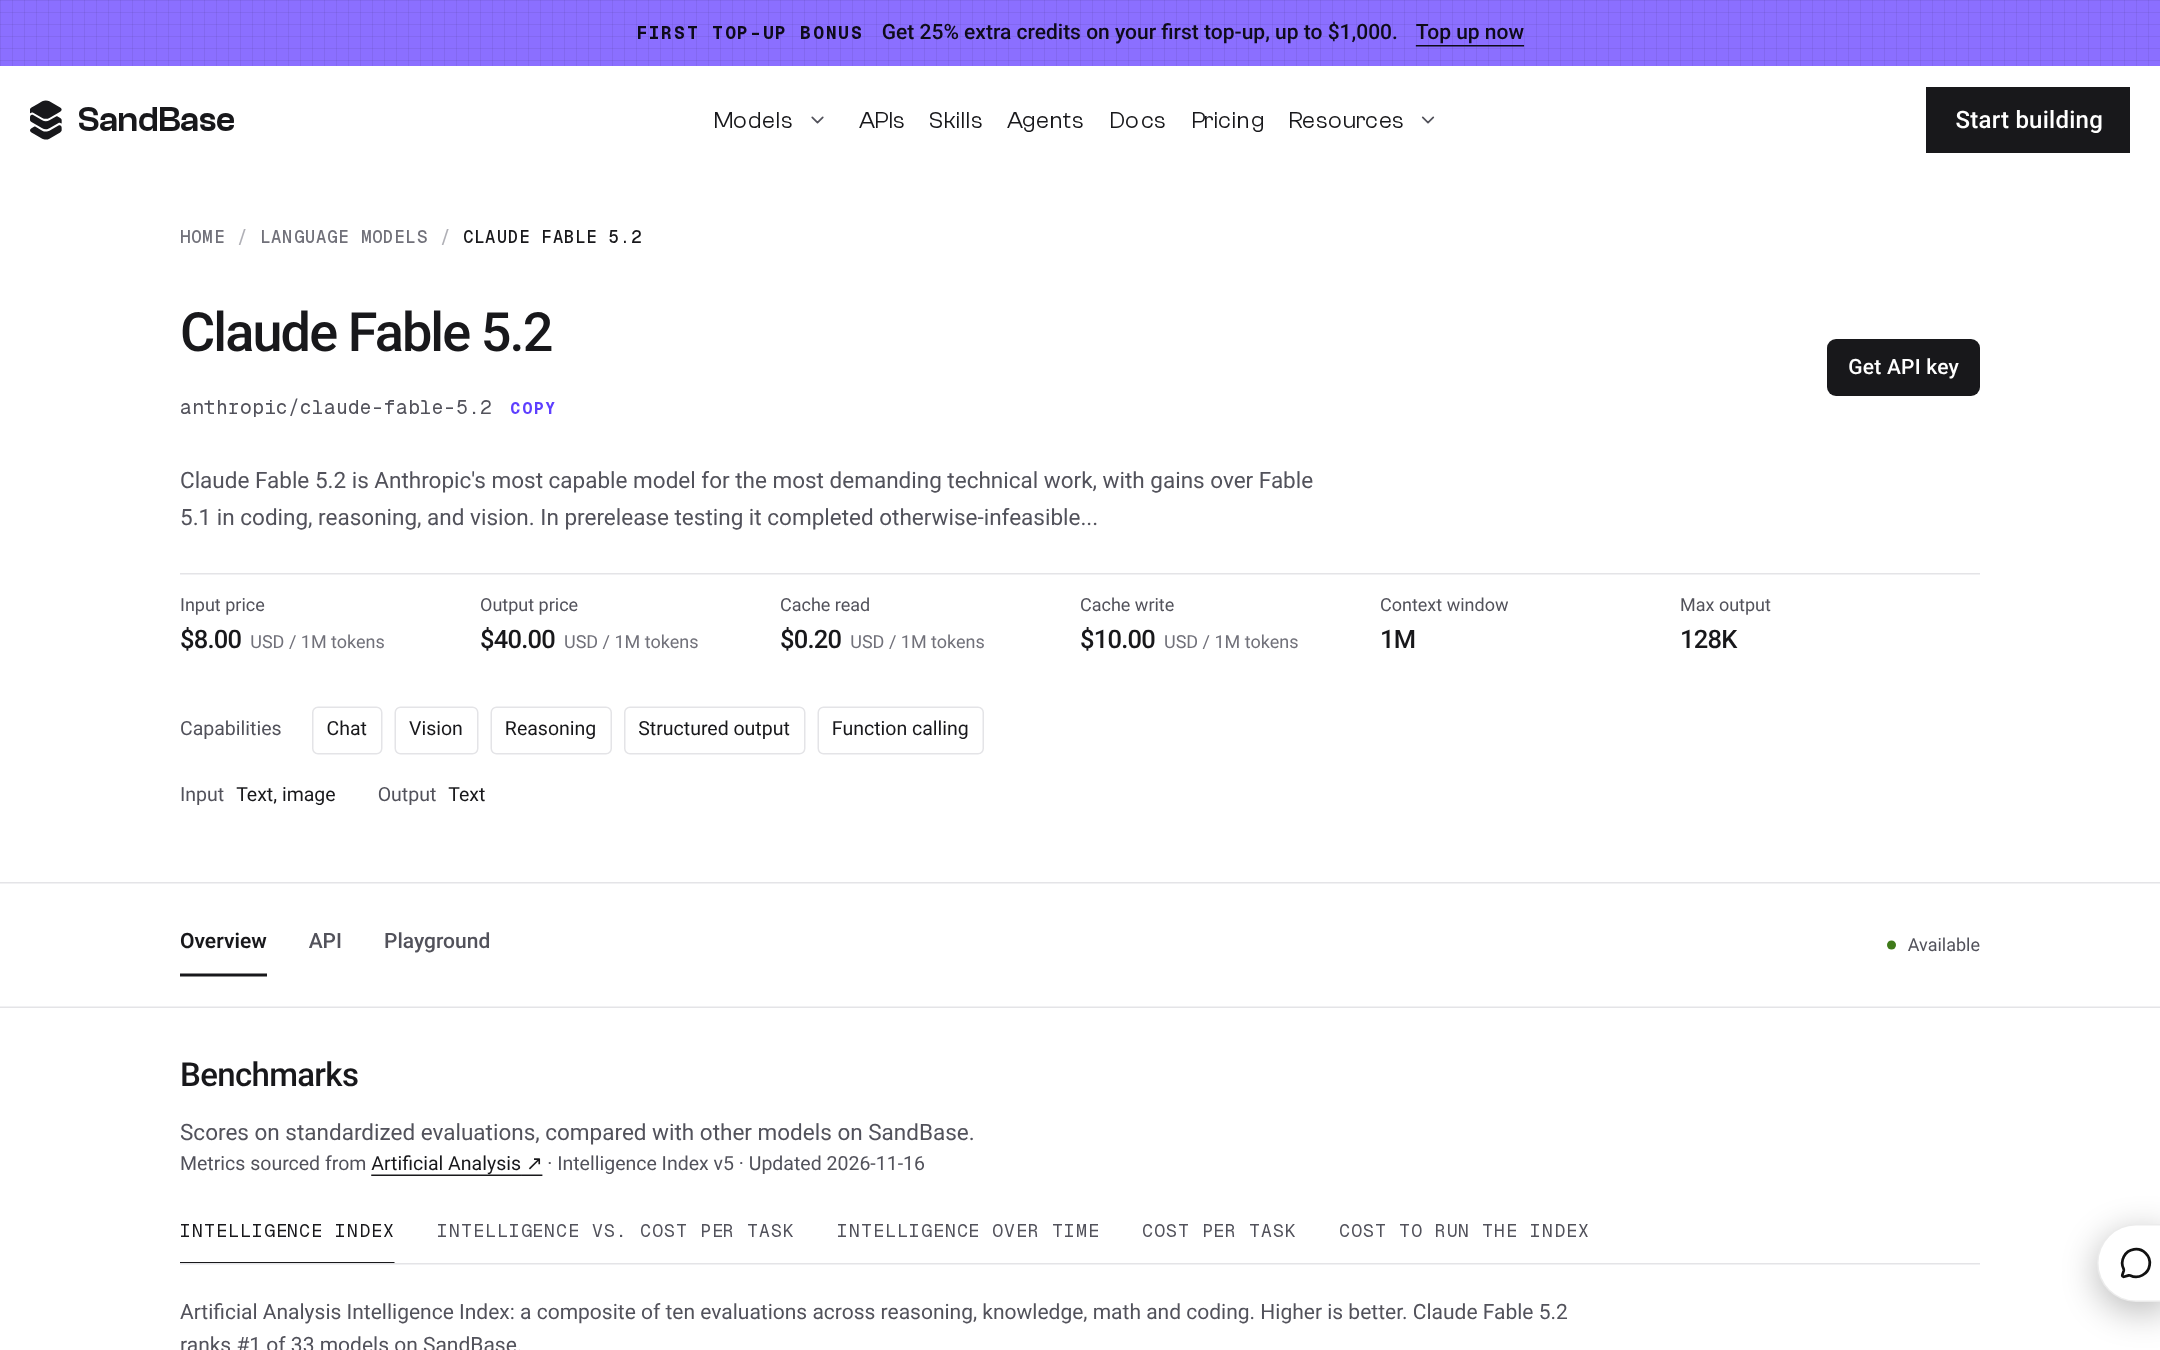
Live SandBase Claude Fable 5.2 card at /models/anthropic/claude-fable-5.2, captured 18 November 2026, Asia/Shanghai (HTTP 200). Hero is $8.00 / $40.00, cache read $0.20, cache write $10.00, 1M context, 128K max output. This is a live comparison card, not an official Anthropic screenshot and not a SandBase 6.2 listing. A site-wide first-top-up bonus banner is visible at the top; it is not a model discount. Only the Astra card carries a 10% OFF badge. Routing notes that already own Fable against older flagships: Fable 5.2 vs Opus 5.5 vs GPT-6 Astra and Carbon vs Argon vs Astra vs Opus.
A cheaper live flagship sits outside this table on purpose. Qwen4 Max is alibaba/qwen4-max at $1.67 / $5.00, card context 1M, hero max output 131.1K. The GA limits and the official Singapore list are in Qwen4-Max is generally available. It is a pointer, not a seventh scored row.
Modalities and the call shape
GPT-6.2 Astra and Sol, on the official pages: text and image in, text out. Audio and video are unsupported modalities. Fine-tuning and predicted outputs are unsupported. Tool calling requires the Responses API even though Chat Completions is a supported endpoint. The API rejects reasoning effort none.
SandBase GPT-6 Astra and GPT-6.1 Sol heroes: text and image in, text out, plus chat, vision, reasoning, structured output, and function calling. Carbon adds audio input on the hero. Fable’s hero matches the text-and-image pair. None of those chips is a promise that a SandBase payload accepts every tool named on OpenAI’s Responses list. Copy the tool list from the host you will actually call.
On SandBase, Astra and GPT-6.1 Sol document POST https://api.sandbase.ai/v1/chat/completions and POST https://api.sandbase.ai/v1/responses. Carbon and Fable document chat completions. Fable also documents POST https://api.sandbase.ai/v1/messages. Sign in to create the key. There is still no 6.2 string to put in model.
What OpenAI claims, which this page does not rerun
The 17 November launch post, read in the 18 November fact check, attributes the following to OpenAI. openai.com HTML did not render in this environment (Cloudflare interstitial), so there is no screenshot of the essay. Do not read the bullets as a SandBase leaderboard.
- Agents’ Last Exam: GPT-6.2 Astra scores 5.2 points higher than GPT-6 Astra at less than a third of the cost, and 5.5 points ahead of Claude Fable 5.2 at 5% of the cost. OpenAI notes the Fable 5.2 leaderboard results exclude nine tasks that used a fallback model.
- Terminal-Bench-Science 0.1: GPT-6.2 Astra is 9 percentage points higher than GPT-6 Astra at less than one-third the cost. OpenAI also claims a new high on the Vals Science Index. The footnote says Fable 5.2’s Terminal-Bench-Science 0.1 results are as reported by Artificial Analysis in the mini-swe-agent harness, while Anthropic reported 74.6% at max reasoning in Claude Code.
- FrontierCode 2.0 (Cognition): GPT-6.2 Sol comes within 0.5 points of GPT-6.2 Astra at about one-fifth the cost, both at max.
- LifeVal: GPT-6.2 Sol outscores GPT-6 Astra at about one-seventh the cost.
- Harvey LAB-AA v1.1: GPT-6.2 Astra sets a new state of the art, more than doubling Claude Fable 5.2’s pass rate at about one-sixth the cost. “Astra for Law” scores higher and is a configuration, not a public API ID in the catalog this check fetched.
- GDPval v2, OpenAI internal: GPT-6.2 Astra leads the models they tested, up 6.2 percentage points from GPT-6 Astra while using 22% fewer output tokens. GPT-6.2 Sol improves 5.3 points from GPT-6.1 Sol.
- AA-3D: GPT-6.2 Astra at 1,318 Elo, Claude Fable 5.2 at 1,271, GPT-6.2 Sol at 1,259.
Same post: both new models behaved like GPT-6 Astra on most alignment evals, and on two tests they were more likely to omit obstacles that blocked the work. Preparedness language stays in the launch note. It is not a reason to pick a row in this table, and it is not a procedure.
How to choose without a winner
Choose official GPT-6.2 Astra when the new ID is the point and you can call OpenAI directly. The SandBase path for “most capable OpenAI flagship today” is still GPT-6 Astra at $9 / $45, which is a higher unit price than official 6.2 Astra’s $8 / $40 and a lower unit price than official GPT-6 Astra’s $10 / $50.
Choose official GPT-6.2 Sol when you want the new Sol on OpenAI’s API at the $2 / $10 sticker. Choose SandBase GPT-6.1 Sol when the client already uses openai/gpt-6.1-sol and you are not moving that client off SandBase.
Choose Gemini 4 Carbon on SandBase when the hero you need is the one with audio input and a $4 / $20 card, and you can live with 65.5K max output on that hero. Choose Claude Fable 5.2 on SandBase when you want the $8 / $40 card that is actually listed, at 1M / 128K, under anthropic/claude-fable-5.2.
Do not choose a 6.2 SandBase URL. It 404s. Do not treat OpenAI’s eval deltas as a SandBase measurement. There is no TTFT, TPOT, throughput, or cache-hit figure for GPT-6.2 on SandBase, because there is no card to measure.
FAQ
Which is cheaper, GPT-6.2 Astra or Claude Fable 5.2?
On the unit prices in the table, official short-context Astra and the SandBase Fable hero both show $8 input and $40 output per 1M tokens. Cached input does not match: official Astra is $0.40, the Fable hero is $0.20 read and $10 write. Task cost still depends on how many tokens each model spends. This page did not measure that.
Is Gemini 4 Carbon’s SandBase price the Google intro price?
The hero captured 18 November 2026 is $4 / $20 / $0.20 cache read. This check did not re-fetch Google’s intro window. Use the card you will call.
Can I put gpt-6.2-astra in a SandBase request today?
No. The card is missing. The 404 is in the launch note. Use openai/gpt-6-astra or another live ID.
Does Sol replace GPT-6.1 Sol at the same price?
The stickers match on short-context input, output, and the 30-minute cache write. Sol is a new official ID. GPT-6.1 Sol is the ID SandBase lists. Same sticker, different host, until a 6.2 card exists.
What to open
Open Gemini 4 Carbon, GPT-6 Astra, GPT-6.1 Sol, or Claude Fable 5.2 for a card that returned HTTP 200 on 18 November. Open OpenAI’s own model pages for gpt-6.2-astra and gpt-6.2-sol.
SandBase cards captured 18 November 2026, Asia/Shanghai. The GPT-6.2 Astra price frame is a plain rendering of published markdown from https://developers.openai.com/api/docs/models/gpt-6.2-astra.md, fetched the same morning, not a live HTML screenshot (HTML returned HTTP 403 from this environment). OpenAI eval bullets are the launch post as checked that morning, not a SandBase rerun, and the openai.com essay was not screenshotted. No latency measurement.
Found this useful? Share it