GLM-5.3-Flash Multimodal and 1M Context
How GLM-5.3-Flash native multimodality and 1M-token context change browser, document, and visual agent workflows.
How GLM-5.3-Flash native multimodality and 1M-token context change browser, document, and visual agent workflows.
A careful reading of GLM-5.3-Flash coding and agent benchmarks, including vendor claims, token efficiency, and reproducible tests.
A hands-on guide to deploying GLM-5.3-Flash weights with Hugging Face, vLLM, SGLang, quantization, and production safeguards.
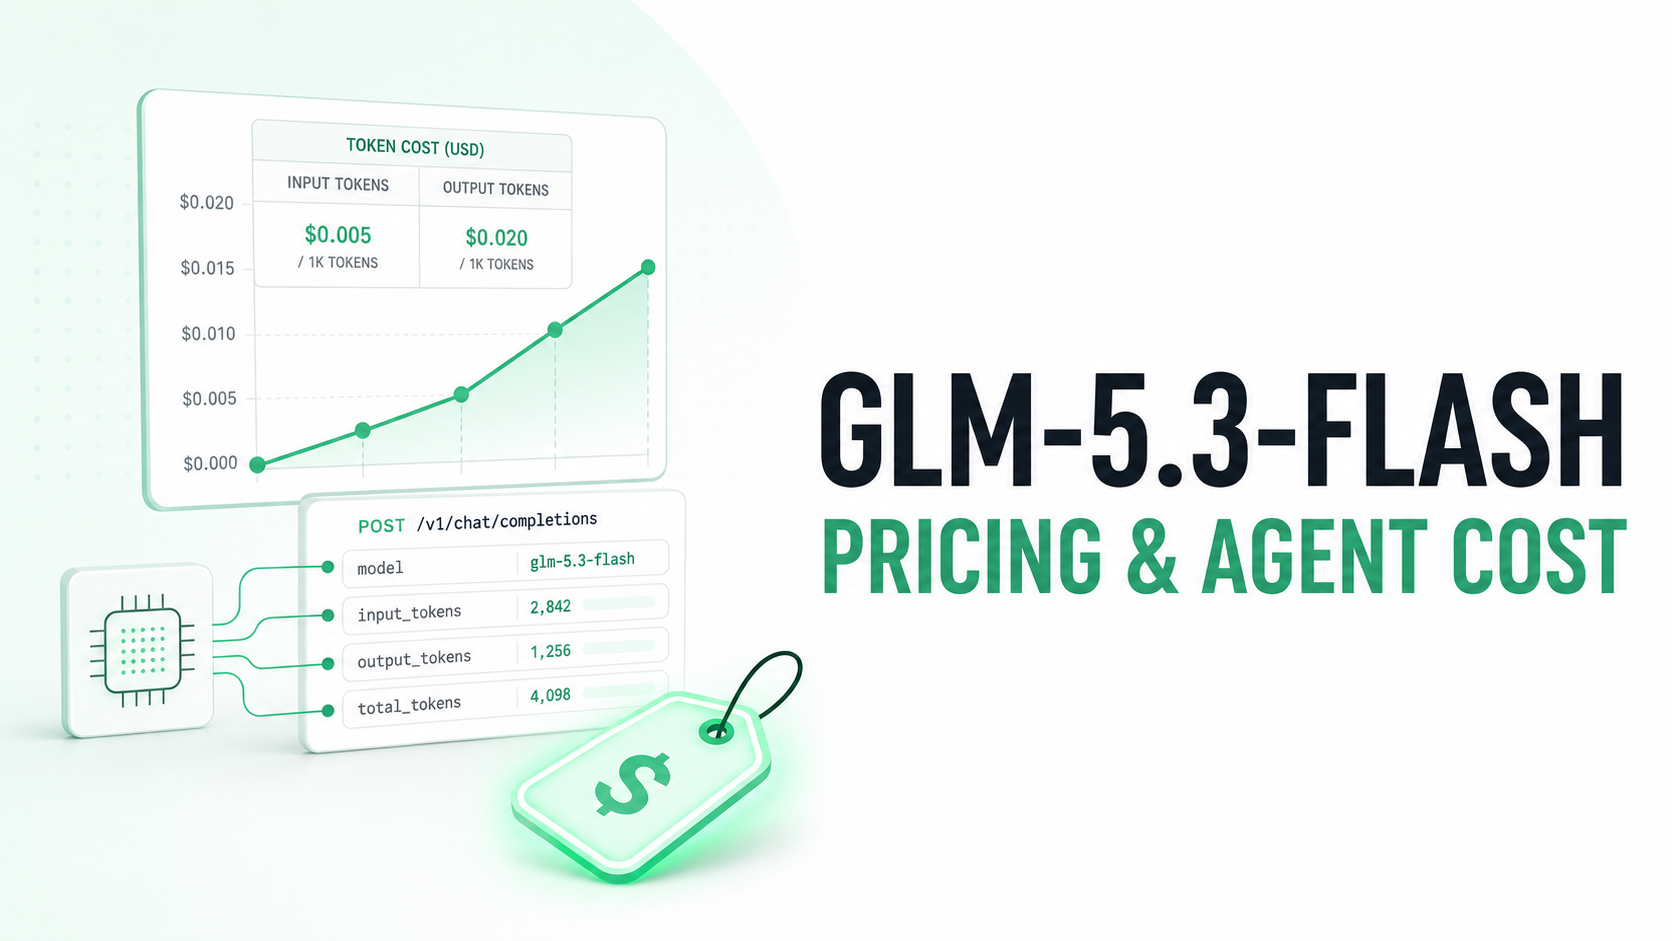
A cost guide to GLM-5.3-Flash token pricing, caching, routing, retries, and the real cost of successful agent workflows.
A practical GLM-5.3-Flash vs DeepSeek comparison covering agent quality, token pricing, latency, and successful-workflow cost.
Ouroboros can modify its own harness through reviewed Git commits. We examine its memory, evolution loop, benchmark claims, and safety boundaries.
Warp Agent CLI has become Oz CLI. Learn local and cloud runs, profiles, MCP, skills, orchestration, and how it compares with Claude Code and Codex.
Gemini 3.7 Flash launches at $0.75/$3.75 per million tokens, half the cost of 3.6 Flash. 1M context, multimodal, tunable thinking, strong tool use for agents.
GLM-5.3 release date and API pricing review: official coding and security benchmarks, API access, open-weight status, and changes from GLM-5.2.
Learn GitHub Copilot Agent Mode setup, MCP tools, permissions, pricing and runtime limits, with Microsoft Agent Framework examples for .NET and Python.
Muse Spark 1.2 vs Claude Sonnet 5: compare coding-agent benchmarks, API pricing, subagents, speed, reliability, and which model fits your workflow.
Meta launches Muse Code, a terminal-native coding agent powered by Muse Spark 1.2. Async background agents, event-log replay, and 24-hour GPU kernel optimization sessions.
DeepSeek V4 Flash 0731 exits preview with 82.7 Terminal-Bench and 54.4 DeepSWE. 284B/13B MoE, 1M context, MIT license, at $0.14/$0.28 per million tokens. Agent benchmarks beat V4-Pro-Preview.
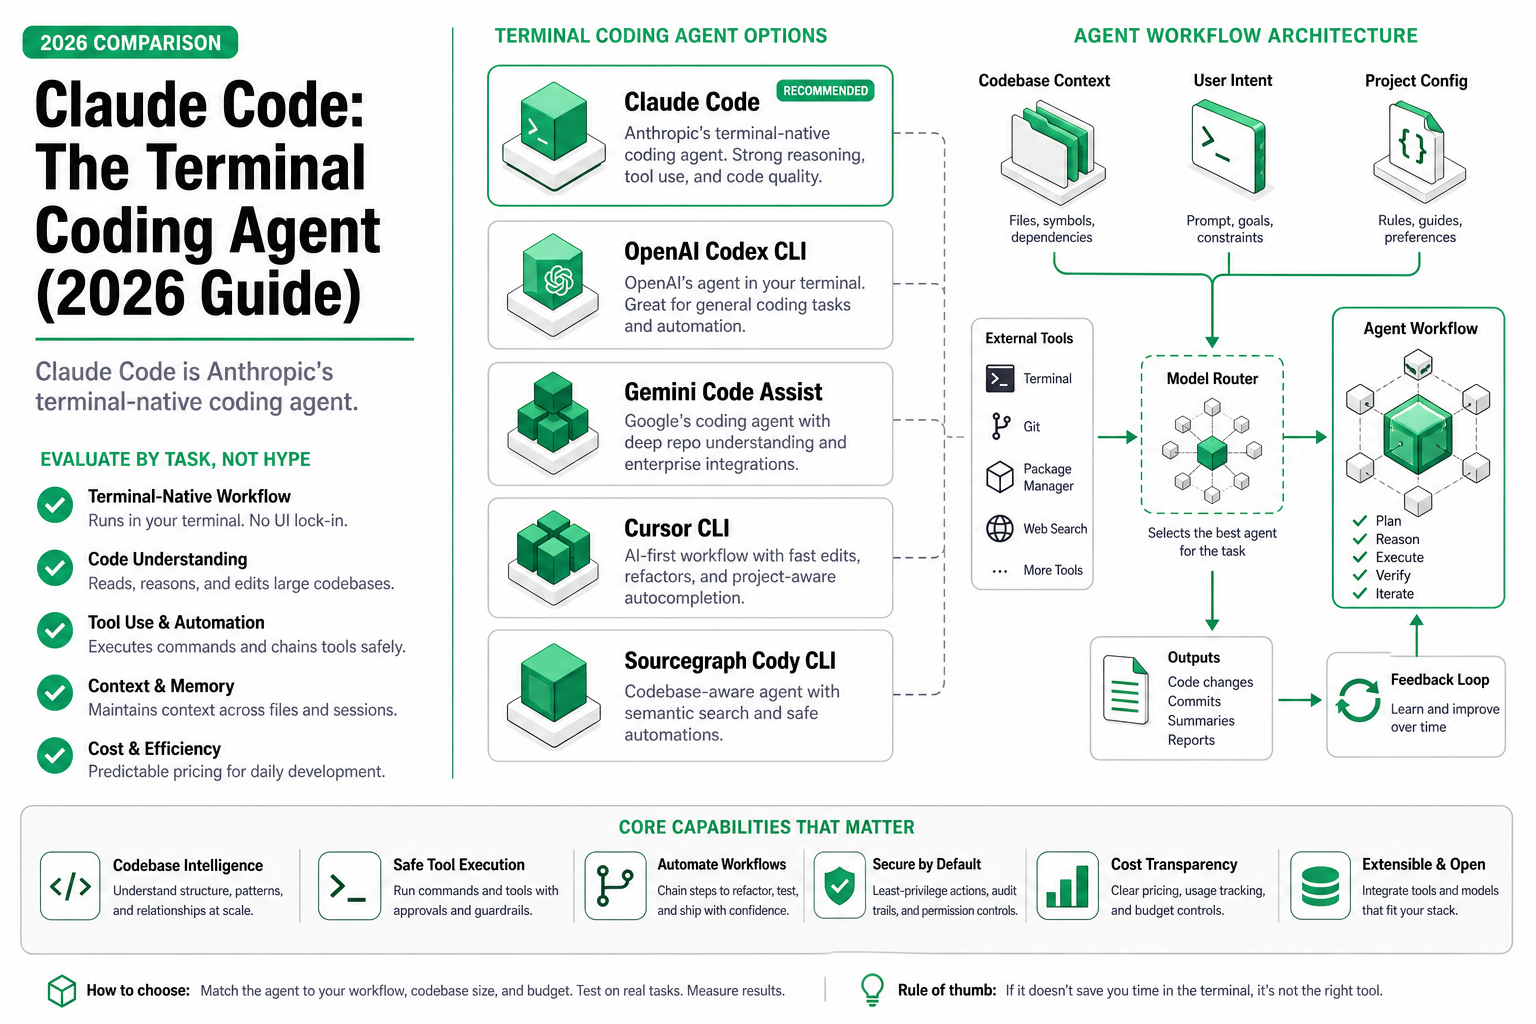
Claude Code is Anthropic's terminal-native coding agent. This guide covers how it works, real usage patterns, costs, and when to use it in 2026.
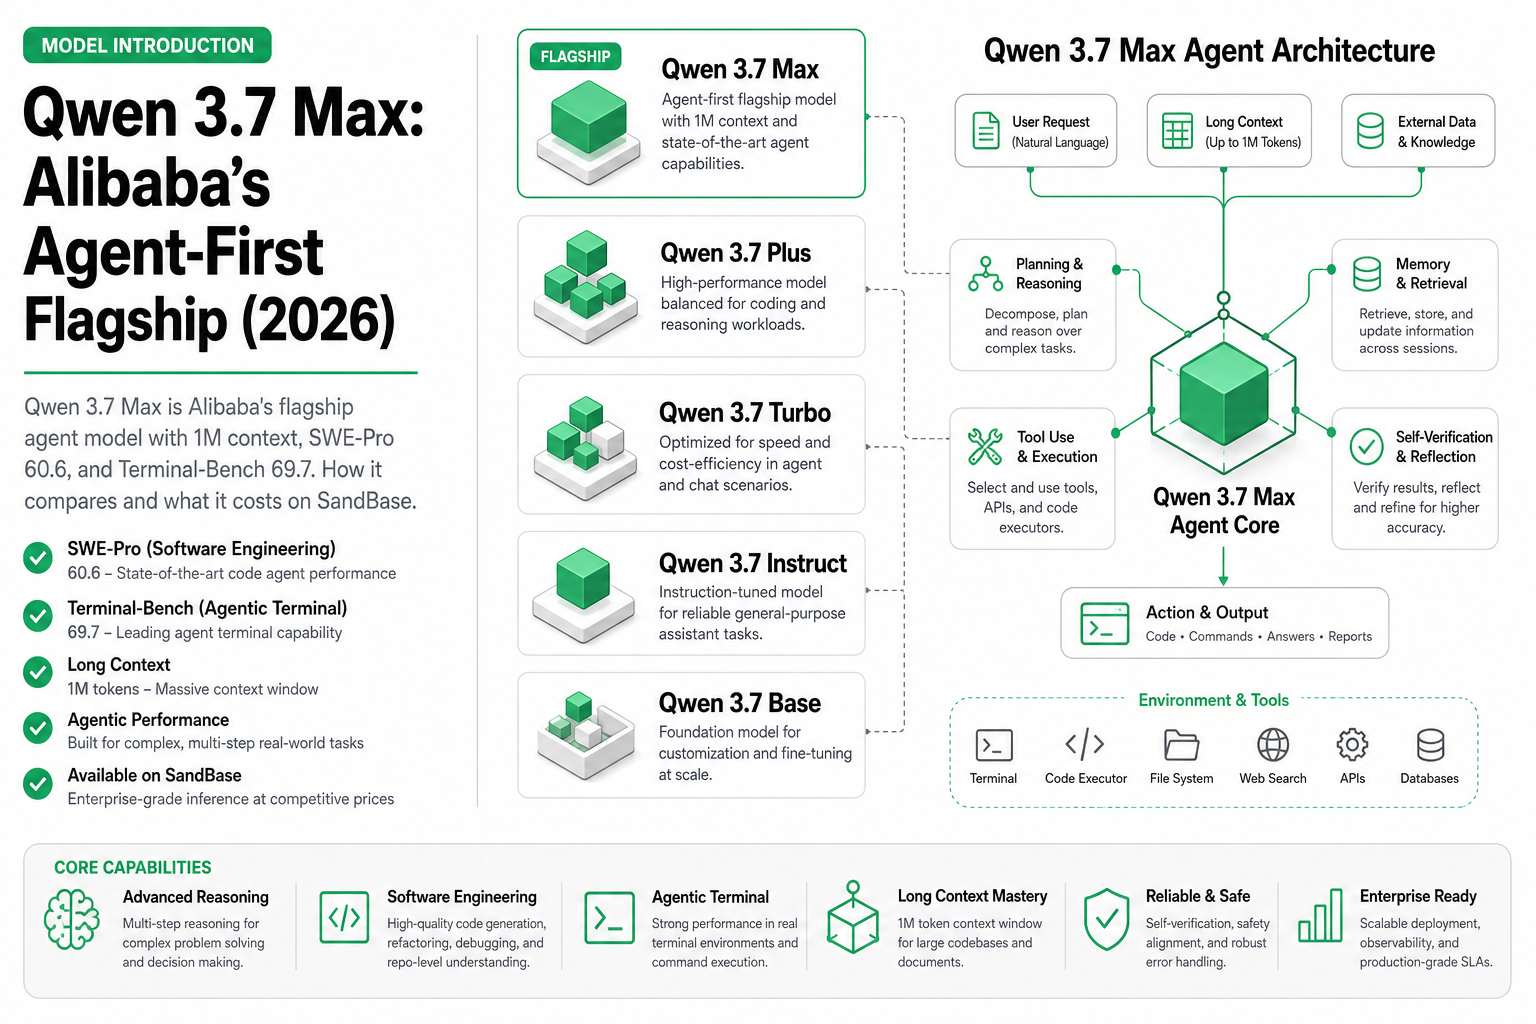
Qwen 3.7 Max is Alibaba's flagship agent model with 1M context, SWE-Pro 60.6, and Terminal-Bench 69.7. How it compares and what it costs on SandBase.

Ranked comparison of the 10 best AI coding assistants in 2026. Covers agents (Claude Code, OpenHands) and copilots (Cursor, Copilot) with pricing, benchmarks, and honest trade-offs.
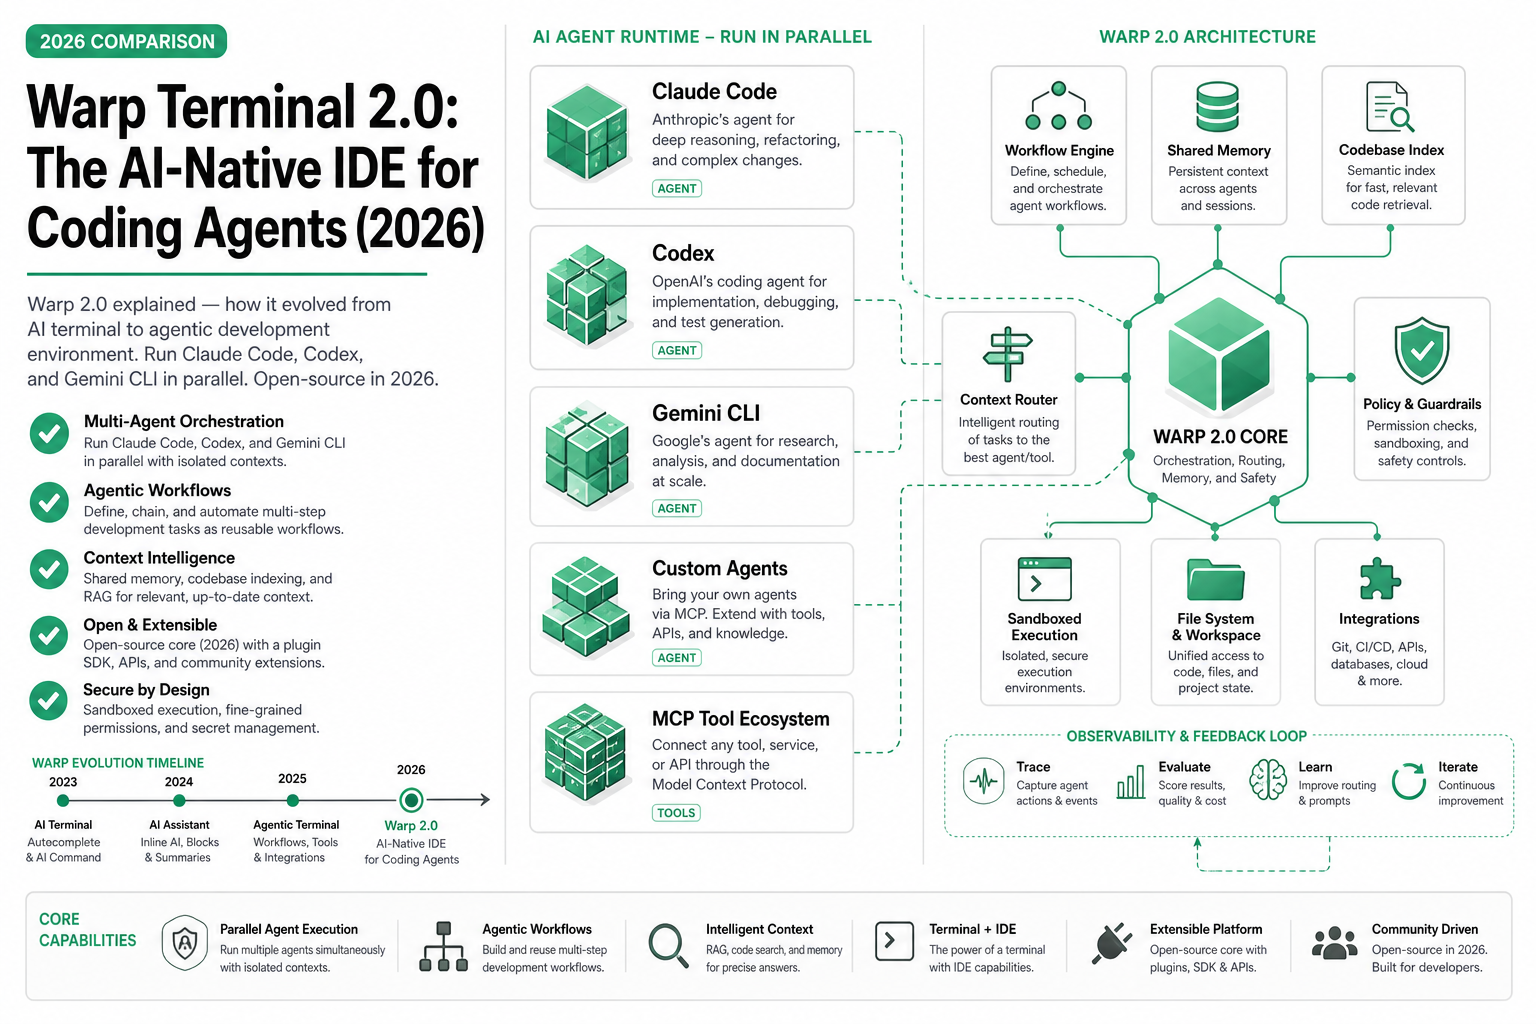
Warp 2.0 explained - how it evolved from AI terminal to agentic development environment. Run Claude Code, Codex, and Gemini CLI in parallel. Open-source in 2026.
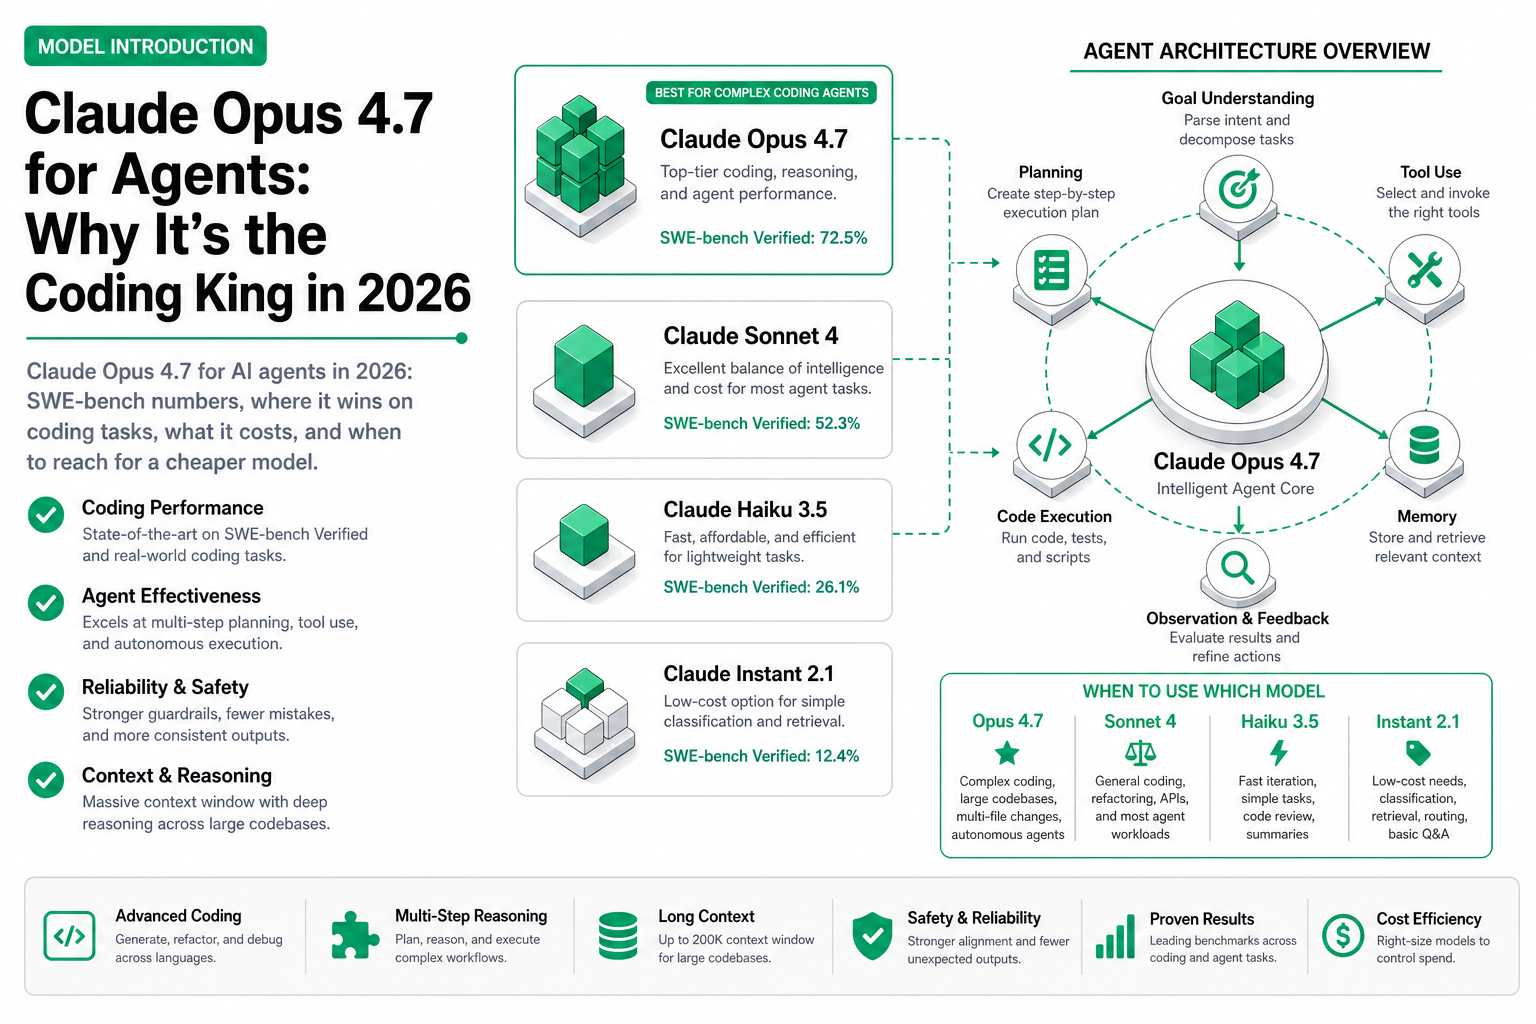
Claude Opus 4.7 for AI agents in 2026: SWE-bench numbers, where it wins on coding tasks, what it costs, and when to reach for a cheaper model.
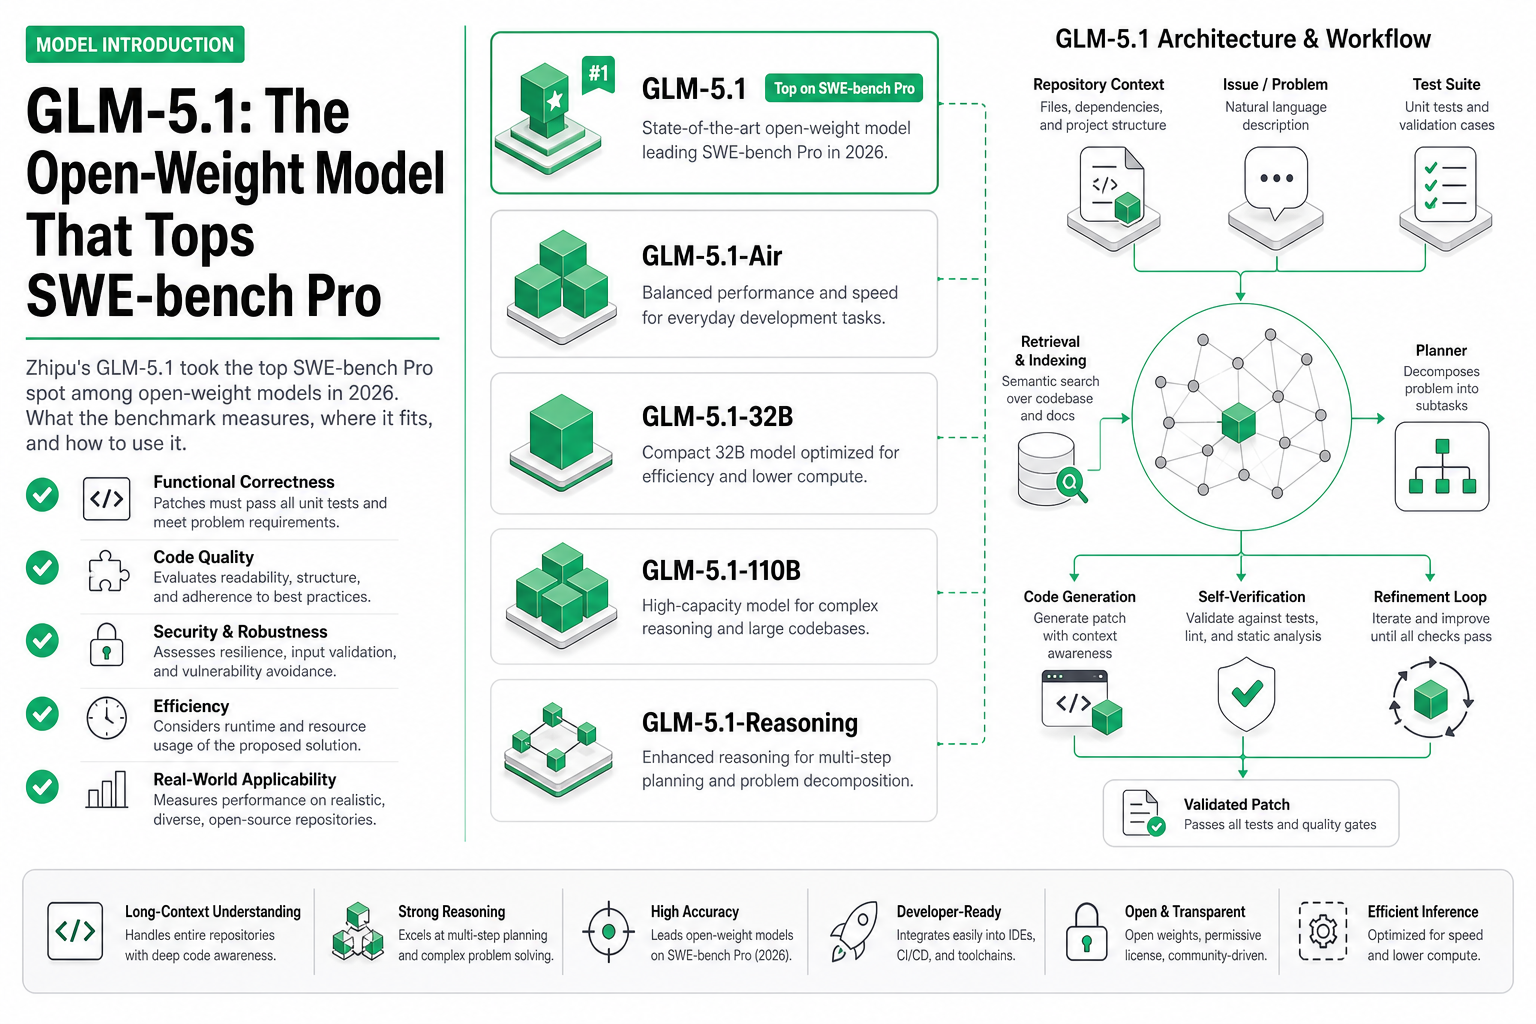
Zhipu's GLM-5.1 took the top SWE-bench Pro spot among open-weight models in 2026. What the benchmark measures, where it fits, and how to use it.
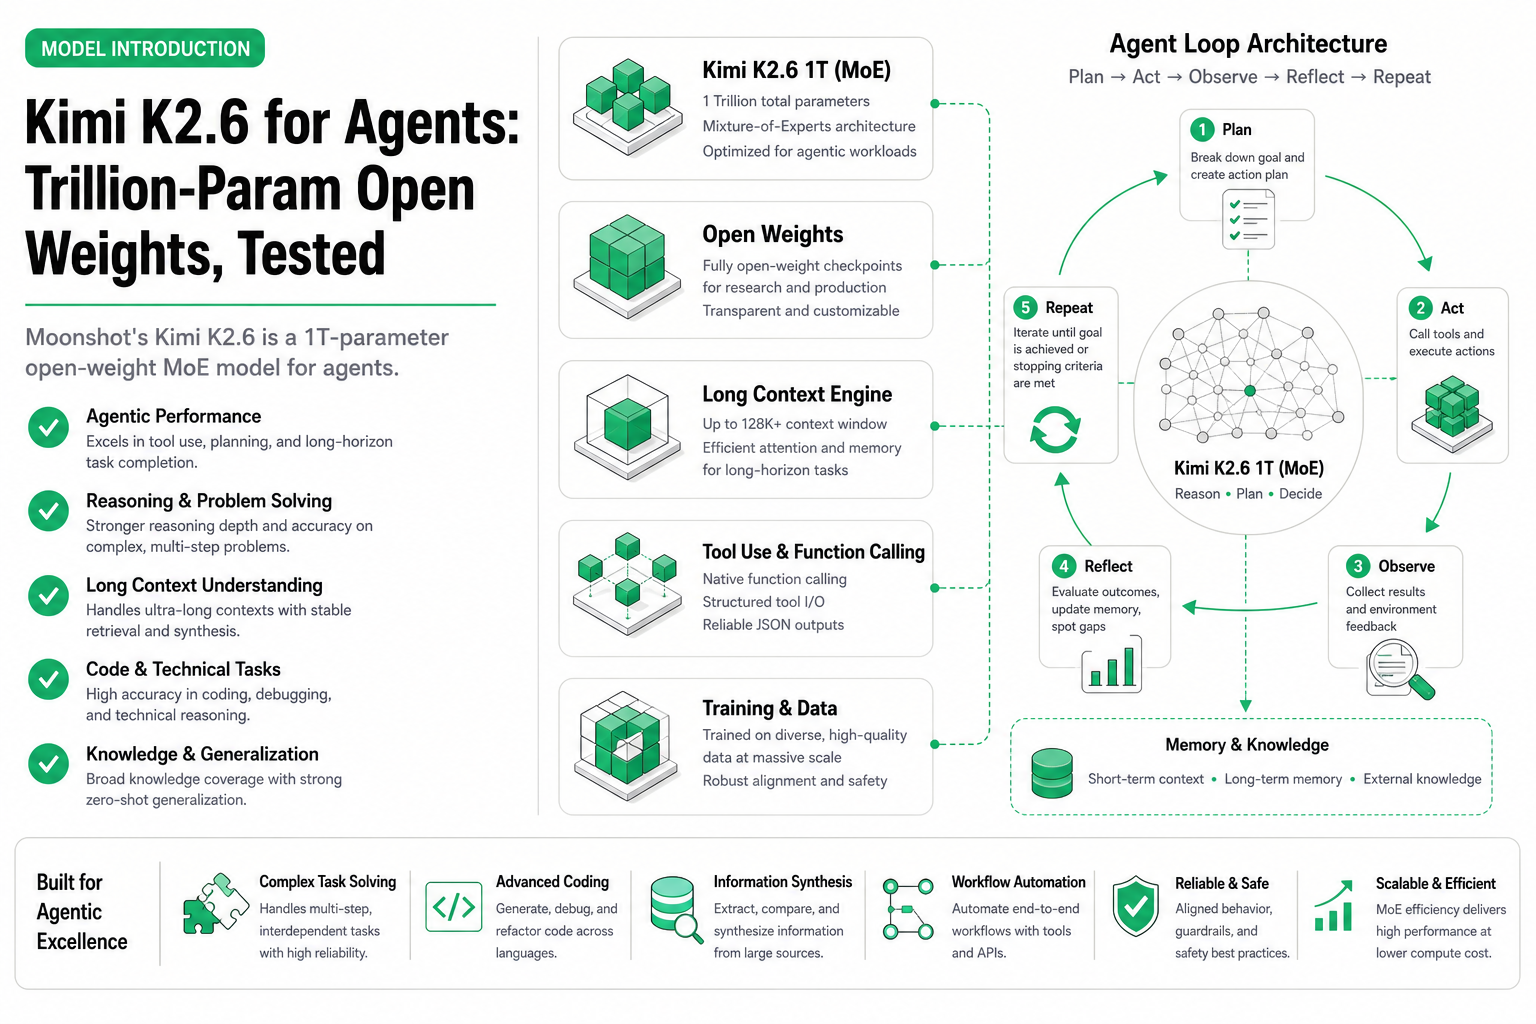
Moonshot's Kimi K2.6 is a 1T-parameter open-weight MoE model for agents. What it's good at, where the params help, and how to wire it into a loop.
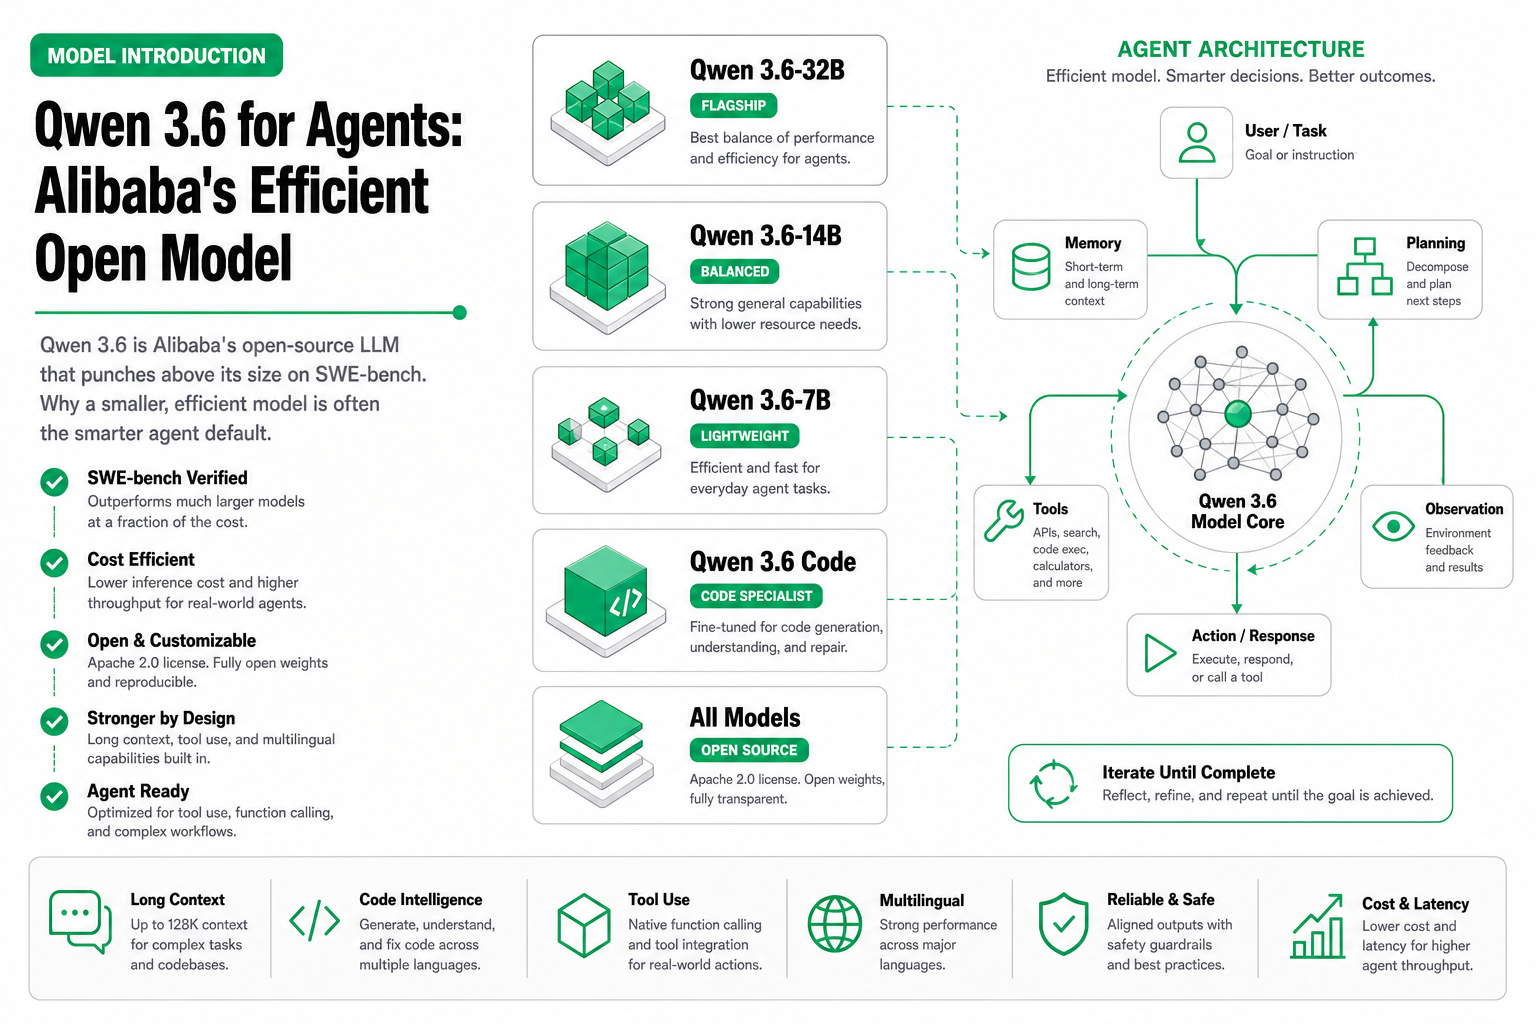
Qwen 3.6 is Alibaba's open-source LLM that punches above its size on SWE-bench. Why a smaller, efficient model is often the smarter agent default.
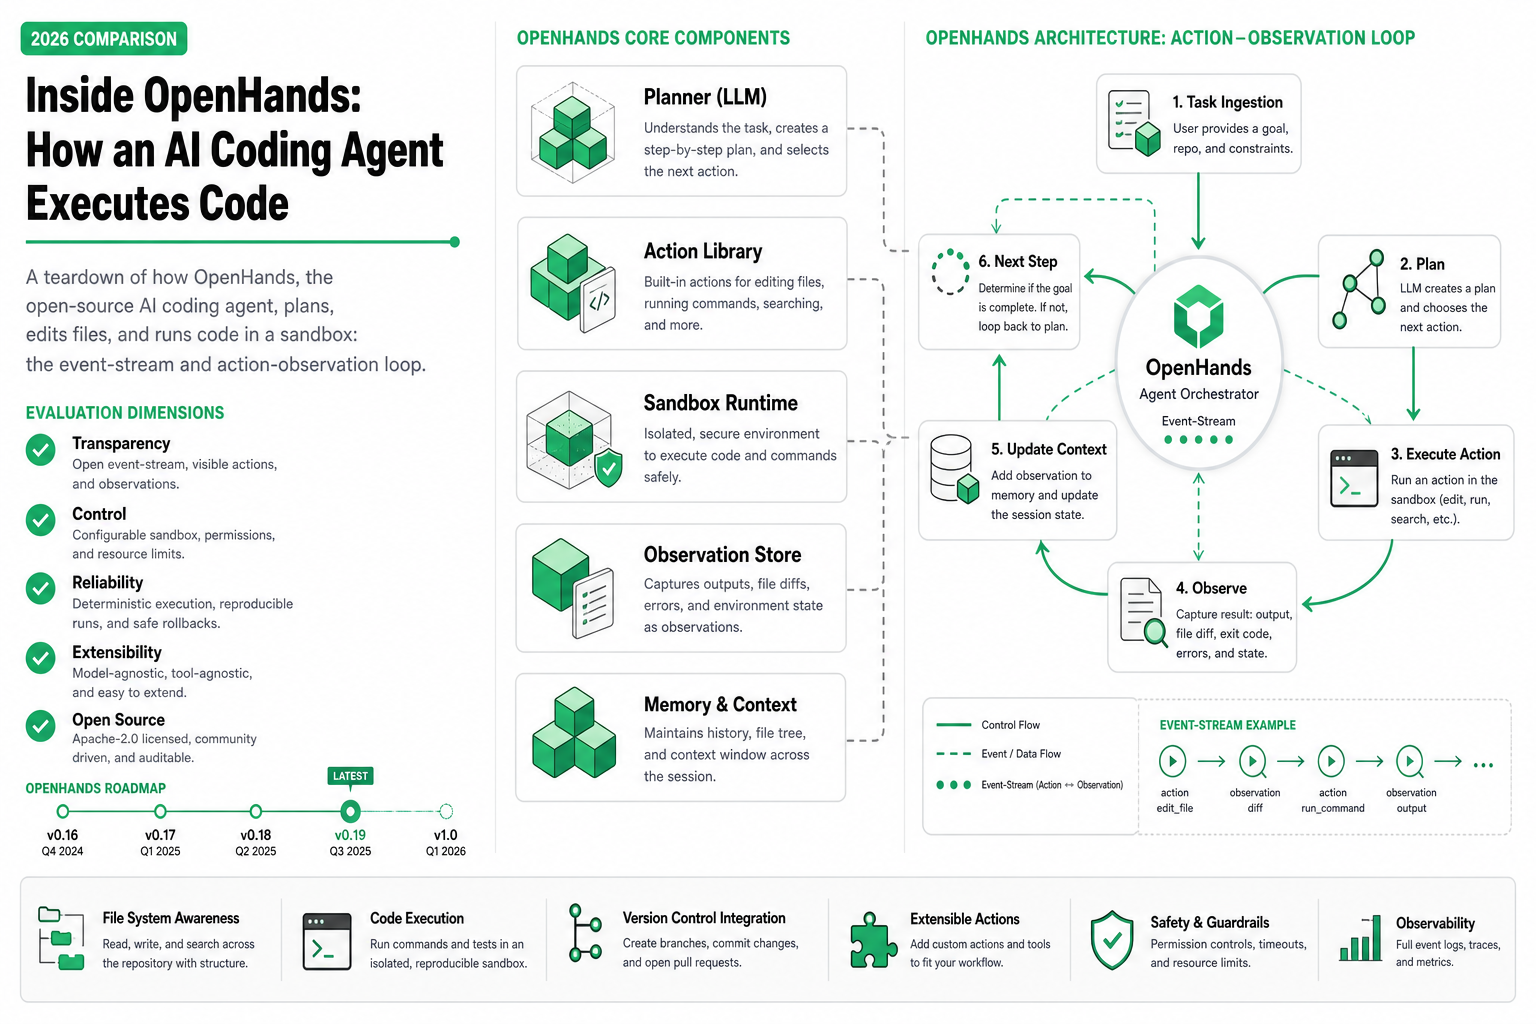
A teardown of how OpenHands, the open-source AI coding agent, plans, edits files, and runs code in a sandbox: the event-stream and action-observation loop.
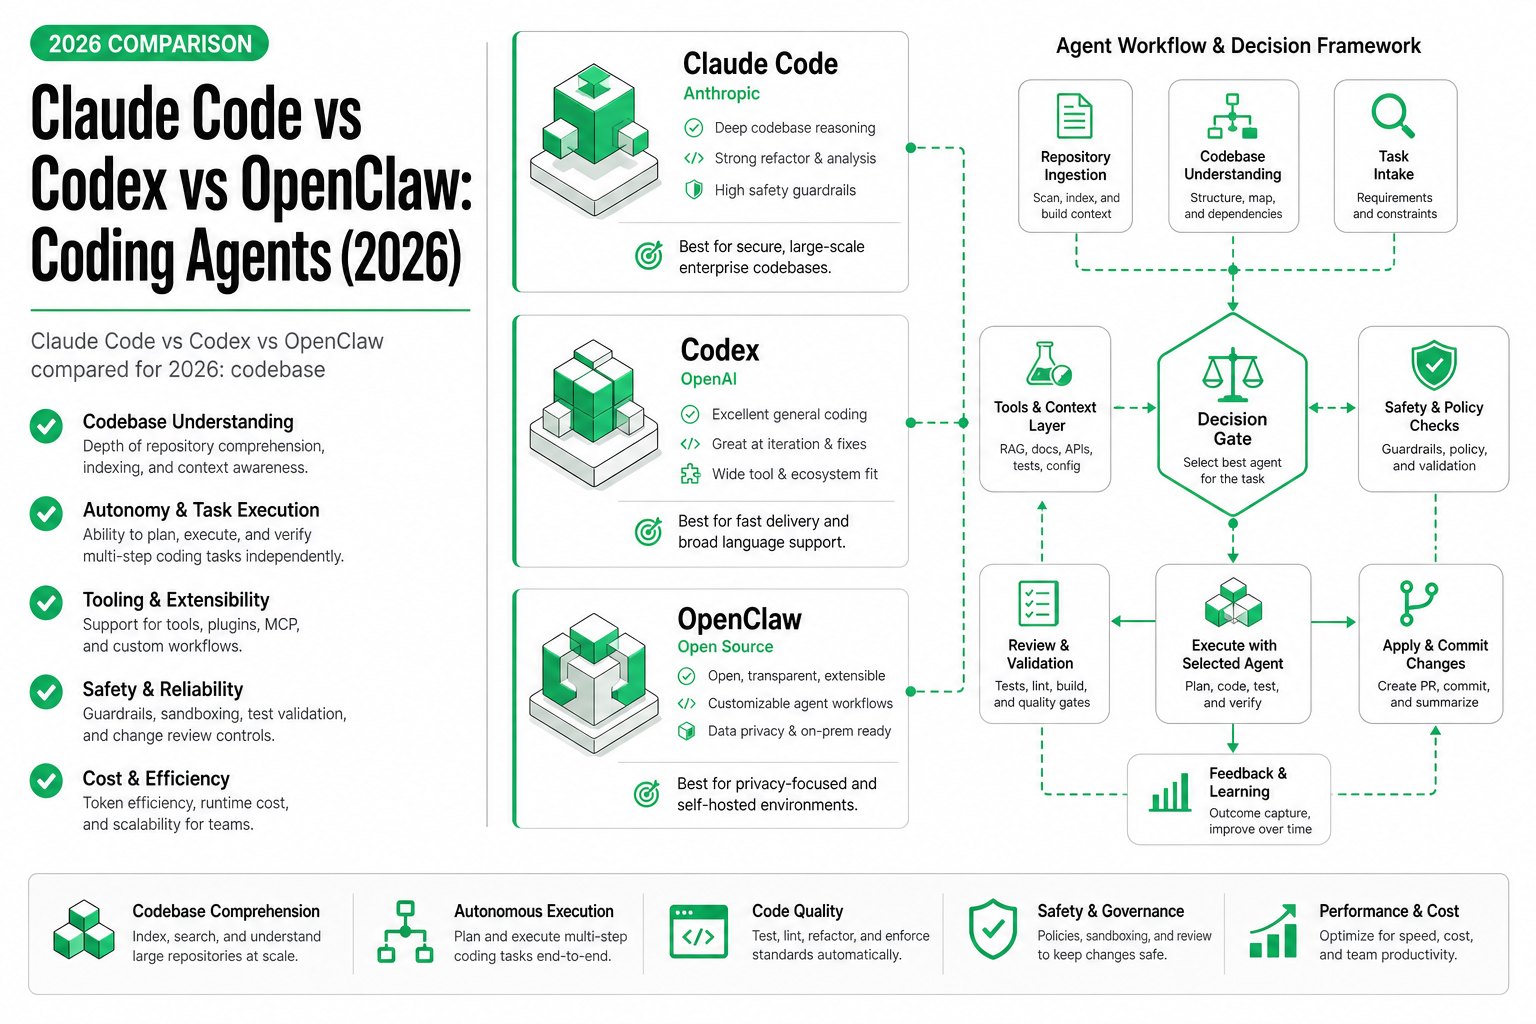
Claude Code vs Codex vs OpenClaw compared for coding agents in 2026. Benchmark results, pricing, context handling, and which to pick for your codebase size.