Build a Social Listening Agent: Weibo + Douyin
Tutorial: an agent that checks Weibo hot search and the Douyin hot account billboard every 15 minutes, flags brand mentions and posts Slack alerts.
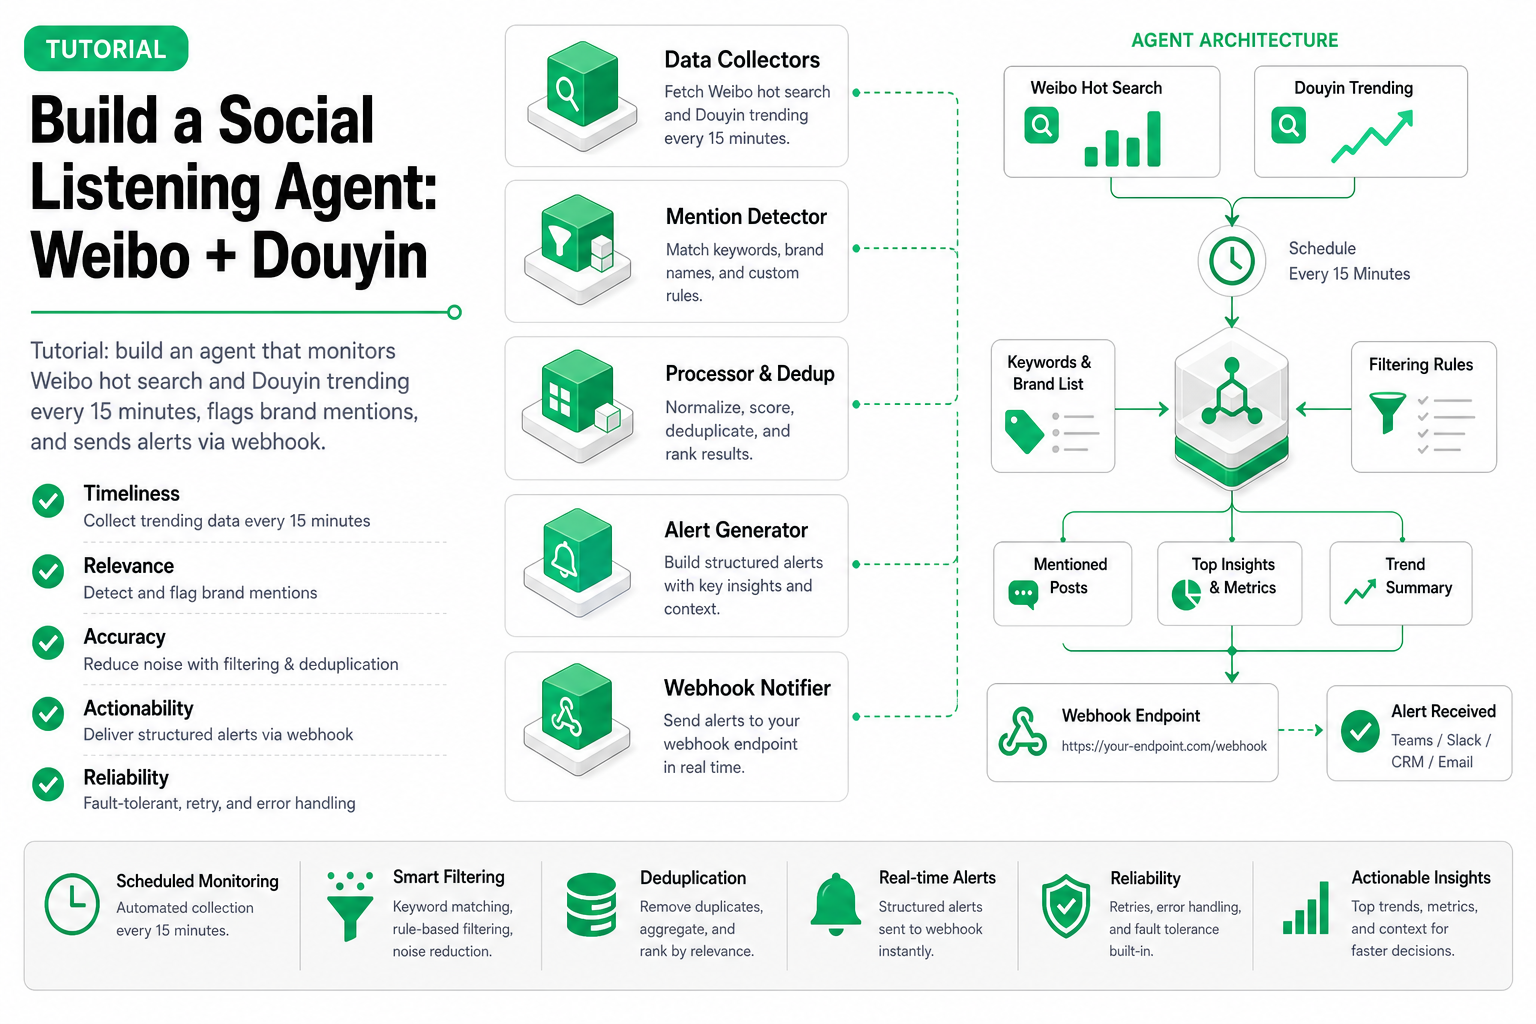
Key takeaway (TL;DR) — A Python agent that pulls Weibo hot search and the Douyin hot account billboard every 15 minutes, asks an LLM which items matter to your brand or industry, and posts a Slack alert when it finds any. Each cycle is 2 data calls plus 1 LLM call: 192 data calls and 96 LLM calls a day. Each organization gets 100 free data API calls per UTC day across eligible APIs, and the data calls beyond that are billed per call at the SandBase catalog price; the LLM side is roughly $0.72 a day at the token assumptions below (an estimate). Full code included, tested on 2026-10-01 (UTC).
Brand crises don’t wait for your morning check-in. A negative post that starts trending at 2 AM has seven hours to spread before a team that checks at 9 AM sees it. That gap is the difference between “we responded quickly” and “we were blindsided.”
This social listening agent narrows it to one 15-minute polling interval, plus the few seconds the API, LLM and Slack calls take.
What the agent does
Every 15 minutes, 24/7:
- Pulls Weibo’s current hot search list (50–51 topics with heat scores across my 2026-10-01 runs)
- Pulls Douyin’s hot account billboard (accounts ranked by the billboard, with follower counts and new followers; it is an account list, not a hot-search topic list)
- Sends both lists to an LLM with your brand and industry keywords and classification rules
- If anything is flagged as a brand mention or an industry signal: posts a message to a Slack incoming webhook
- Appends a log line per cycle with counts, the flagged items and the LLM summary
What data this uses
Weibo hot search and the Douyin hot account billboard are public, read-only lists that anyone can see in the apps. You need a SandBase API key. SandBase is not an official partner of Weibo or Douyin, and this agent cannot read private-account data, DMs or owner-only analytics, and cannot publish or take account actions.
| This tutorial (SandBase public-data APIs) | Official developer platforms (Weibo Open Platform, Douyin Open Platform) | |
|---|---|---|
| Access | One SandBase API key | App registration and platform review |
| Scope | Public lists and public posts: hot search, hot account billboard, keyword search | Authorized, account-linked workflows for accounts that grant your app access |
| Account actions (publish, reply, DMs) | No | Where the platform grants the permission |
| Owner analytics | No | For authorized accounts |
| Choose it when | You want to watch what is trending publicly and catch your brand in it | You need to act on, or read private data of, accounts you manage |
Neither platform offers a general unauthenticated API for arbitrary public data, which is the gap this approach fills.
Architecture
┌─────────────────┐     ┌──────────────┐     ┌─────────────┐     ┌──────────────┐
│ Scheduler       │────▶│ Data Fetch   │────▶│ LLM Classify│────▶│ Slack        │
│ (every 15 min)  │     │ Weibo+Douyin │     │ Relevant?   │     │ webhook      │
└─────────────────┘     └──────────────┘     └─────────────┘     └──────────────┘
                                                    │
                                                    ▼
                                             ┌────────────┐
                                             │ Cycle log  │
                                             │ (JSONL)    │
                                             └────────────┘
Calls per cycle in the code below: 2 data calls + 1 LLM call. Per day at 96 cycles: 192 data calls + 96 LLM calls.
Complete code
Every data call uses POST https://api.sandbase.ai/v1/api/<endpoint> with a JSON body of only that endpoint’s parameters. Endpoint references:
weibo/web-v2/hot-search(no parameters)douyin/billboard/hot-account-list(page_num,page_size)weibo/web-v2/realtime-search(query; used by the optional follow-up helper)
The reference documents a completed response as {id, status, model, outputs: [{data: ...}]}, so the code reads only outputs[0].data and raises when a call doesn’t complete. These are the Model API POST routes, not the GET routes shown on the Weibo and Douyin catalog pages.
The two references the cycle depends on confirm the request bodies in the code: Weibo hot search has no request fields, which is why fetch_weibo_hot_search() sends {}, and the Douyin billboard takes optional page_num and page_size.
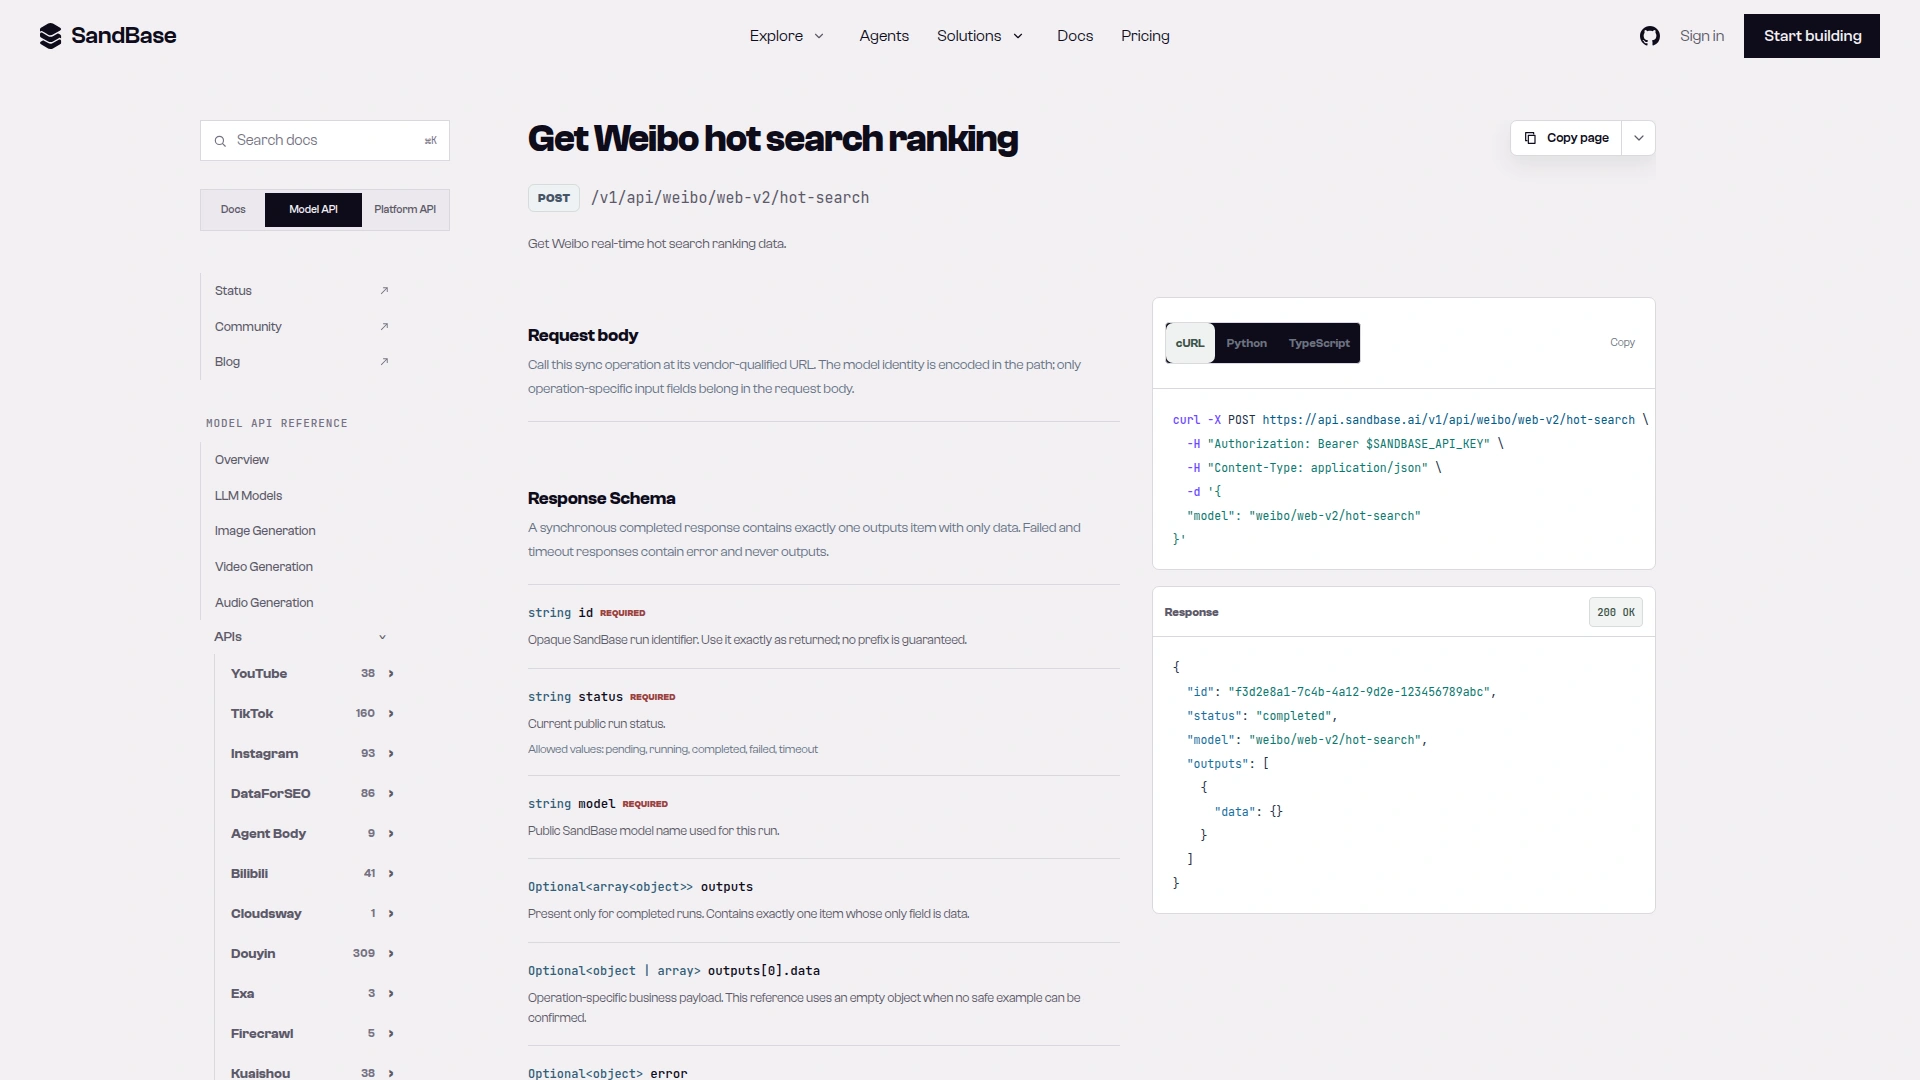
Caption: The weibo/web-v2/hot-search reference: a POST /v1/api/weibo/web-v2/hot-search route with no operation fields and a response with id, status, model and outputs (captured 2026-10-02).
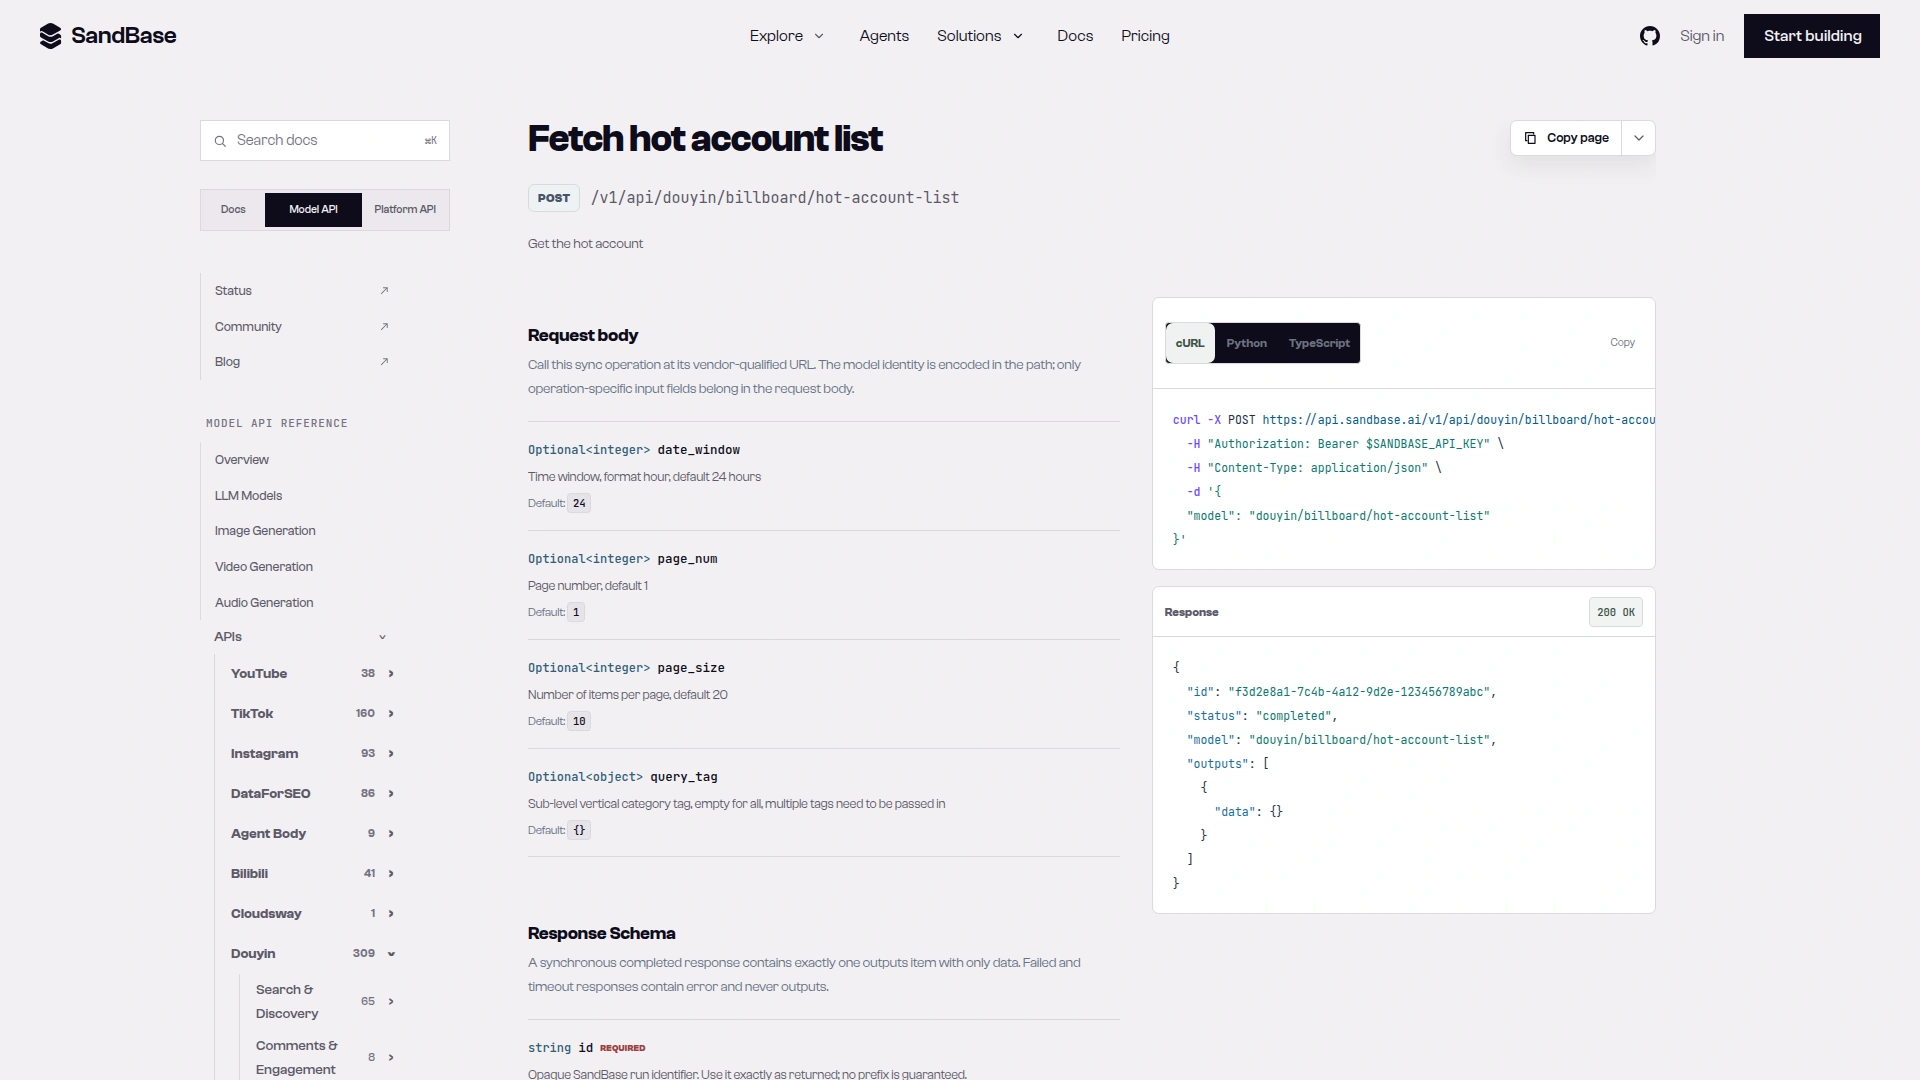
Caption: The douyin/billboard/hot-account-list reference, listing optional date_window, page_num, page_size and query_tag; the agent sets only page_num and page_size (captured 2026-10-02).
#!/usr/bin/env python3
"""Social listening agent: Weibo + Douyin.

Checks Weibo hot search and the Douyin hot account billboard every 15 minutes,
classifies relevance with an LLM, posts alerts to a Slack incoming webhook.
Run as a long-running process, or via cron with --once.
"""

import json
import os
import sys
import time
from datetime import datetime, timezone
from pathlib import Path

import requests
from openai import OpenAI

# --- Configuration ---
BRAND_KEYWORDS = ["你的品牌名", "YourBrand", "竞品A", "竞品B"]
INDUSTRY_KEYWORDS = ["AI", "大模型", "agent", "智能体"]
SLACK_WEBHOOK_URL = os.environ.get("SLACK_WEBHOOK_URL", "")  # Slack incoming webhook
CHECK_INTERVAL = 900  # 15 minutes in seconds
LOG_DIR = Path("./listening_logs")
LOG_DIR.mkdir(exist_ok=True)

SANDBASE_API_KEY = os.environ["SANDBASE_API_KEY"]
API_BASE = "https://api.sandbase.ai/v1/api"
HEADERS = {
    "Authorization": f"Bearer {SANDBASE_API_KEY}",
    "Content-Type": "application/json",
}

# OpenAI client for LLM calls only
client = OpenAI(
    base_url="https://api.sandbase.ai/v1",
    api_key=SANDBASE_API_KEY,
    timeout=60,
)


# --- Data fetching: POST /v1/api/<endpoint>, read outputs[0].data ---
def call_data_api(endpoint: str, params: dict | None = None, retries: int = 3) -> dict:
    """Call one SandBase data endpoint; retry HTTP 429/5xx with 1s, 2s backoff."""
    for attempt in range(retries):
        resp = requests.post(f"{API_BASE}/{endpoint}", headers=HEADERS, json=params or {}, timeout=90)
        if (resp.status_code == 429 or resp.status_code >= 500) and attempt < retries - 1:
            time.sleep(2 ** attempt)
            continue
        resp.raise_for_status()
        body = resp.json()
        outputs = body.get("outputs") or []
        if body.get("status") != "completed" or not outputs:
            raise RuntimeError(f"SandBase call did not complete: {body.get('status')} {body.get('error')}")
        return outputs[0].get("data") or {}


def fetch_weibo_hot_search() -> list:
    """Get current Weibo hot search list as [{title, heat}]."""
    data = call_data_api("weibo/web-v2/hot-search")
    # Observed-only field names (tested 2026-10-01): realtime[].word / .num
    return [
        {"title": t.get("word") or t.get("note"), "heat": t.get("num")}
        for t in data.get("realtime") or []
    ]


def fetch_douyin_hot_accounts() -> list:
    """Get Douyin hot account list (accounts ranked on the billboard, not topics)."""
    data = call_data_api("douyin/billboard/hot-account-list", {"page_num": 1, "page_size": 10})
    # Observed-only field names (tested 2026-10-01): data.user_list[].nick_name / .fans_cnt / .new_fans_cnt
    users = (data.get("data") or {}).get("user_list") or []
    return [
        {"title": u.get("nick_name"), "fans": u.get("fans_cnt"), "new_fans": u.get("new_fans_cnt")}
        for u in users
    ]


def fetch_weibo_keyword_posts(keyword: str) -> list:
    """Optional follow-up, not called by run_cycle: recent Weibo posts for a flagged keyword."""
    data = call_data_api("weibo/web-v2/realtime-search", {"query": keyword})
    # Observed-only field names (tested 2026-10-01): parsed_data.results[].content / .post_url
    return (data.get("parsed_data") or {}).get("results") or []


# --- Classification ---
def classify_relevance(weibo_topics: list, douyin_accounts: list) -> dict:
    """Use LLM to classify which topics are relevant to our brand/industry."""
    prompt = f"""You are a brand monitoring analyst. Review these Weibo trending topics and Douyin hot accounts and classify each as:
- "brand_mention": directly mentions our brand or competitors
- "industry_relevant": relevant to our industry but not a direct mention
- "irrelevant": not related

Brand keywords: {json.dumps(BRAND_KEYWORDS, ensure_ascii=False)}
Industry keywords: {json.dumps(INDUSTRY_KEYWORDS, ensure_ascii=False)}

WEIBO HOT SEARCH (top 20):
{json.dumps(weibo_topics[:20], ensure_ascii=False, indent=2)}

DOUYIN HOT ACCOUNTS (top 10):
{json.dumps(douyin_accounts[:10], ensure_ascii=False, indent=2)}

Respond in JSON format only, no markdown:
{{
  "brand_mentions": [{{"source": "weibo|douyin", "title": "...", "heat": N, "reason": "..."}}],
  "industry_relevant": [{{"source": "weibo|douyin", "title": "...", "heat": N, "reason": "..."}}],
  "summary": "One sentence overall assessment"
}}

Only include items that are genuinely relevant. Empty lists are fine if nothing matches."""

    resp = client.chat.completions.create(
        model="anthropic/claude-sonnet-4",
        messages=[{"role": "user", "content": prompt}],
        max_tokens=1500,
    )
    if resp.usage:  # log real token counts so you can check the cost estimate
        print(f"  LLM tokens: {resp.usage.prompt_tokens} in / {resp.usage.completion_tokens} out")
    text = (resp.choices[0].message.content or "").strip()
    if text.startswith("`" * 3):  # tolerate a fenced reply
        text = text.strip("`").removeprefix("json").strip()
    try:
        return json.loads(text)
    except json.JSONDecodeError:
        return {"brand_mentions": [], "industry_relevant": [], "summary": "Parse error"}


# --- Alerting (Slack incoming webhook payload: {"text": ...}) ---
def send_slack_alert(classification: dict, timestamp: str):
    """Post brand mentions and industry signals to Slack."""
    if not SLACK_WEBHOOK_URL:
        print("  No Slack webhook configured, skipping alert")
        return

    brand_mentions = classification.get("brand_mentions") or []
    industry = classification.get("industry_relevant") or []
    if not brand_mentions and not industry:
        return  # Nothing to alert

    blocks = []
    if brand_mentions:
        blocks.append("🚨 *Brand mentions*\n" + "\n".join(
            f"• [{m.get('source', '?').upper()}] {m.get('title')} (heat: {m.get('heat', '?')}) — {m.get('reason', '')}"
            for m in brand_mentions
        ))
    if industry:
        blocks.append("📡 *Industry signals*\n" + "\n".join(
            f"• [{i.get('source', '?').upper()}] {i.get('title')} — {i.get('reason', '')}"
            for i in industry[:5]  # Cap industry items
        ))

    message = {
        "text": f"Social Listening Alert — {timestamp}\n\n" + "\n\n".join(blocks)
                + f"\n\n_{classification.get('summary', '')}_"
    }
    try:
        resp = requests.post(SLACK_WEBHOOK_URL, json=message, timeout=10)
        resp.raise_for_status()
        print(f"  Alert sent: HTTP {resp.status_code}")
    except requests.RequestException as e:
        print(f"  Alert failed: {e}")


# --- Logging ---
def log_cycle(timestamp: str, weibo: list, douyin: list, classification: dict):
    """Append one JSON line per cycle: counts, flagged items, summary."""
    log_entry = {
        "timestamp": timestamp,
        "weibo_count": len(weibo),
        "douyin_count": len(douyin),
        "brand_mentions": classification.get("brand_mentions") or [],
        "industry_relevant": classification.get("industry_relevant") or [],
        "summary": classification.get("summary", ""),
    }
    log_file = LOG_DIR / f"listening-{timestamp[:10]}.jsonl"
    with open(log_file, "a", encoding="utf-8") as f:
        f.write(json.dumps(log_entry, ensure_ascii=False) + "\n")


# --- Main loop ---
def run_cycle():
    """Execute one monitoring cycle: 2 data calls + 1 LLM call."""
    timestamp = datetime.now(timezone.utc).strftime("%Y-%m-%dT%H:%M:%SZ")
    print(f"\n[{timestamp}] Running social listening cycle...")

    weibo = fetch_weibo_hot_search()
    print(f"  Got {len(weibo)} Weibo topics")
    douyin = fetch_douyin_hot_accounts()
    print(f"  Got {len(douyin)} Douyin accounts")

    classification = classify_relevance(weibo, douyin)
    brand_count = len(classification.get("brand_mentions") or [])
    industry_count = len(classification.get("industry_relevant") or [])
    print(f"  Found: {brand_count} brand mentions, {industry_count} industry signals")

    # Brand mentions and industry-only signals both go to Slack
    if brand_count > 0:
        print("  ⚠️ Brand mention detected! Sending alert...")
        send_slack_alert(classification, timestamp)
    elif industry_count > 0:
        print("  📡 Industry signal detected, sending digest...")
        send_slack_alert(classification, timestamp)
    else:
        print("  ✓ Nothing relevant this cycle")

    log_cycle(timestamp, weibo, douyin, classification)
    return classification


def run_continuous():
    """Run as a long-lived process with 15-minute intervals."""
    print("Social Listening Agent started")
    print(f"  Brand keywords: {BRAND_KEYWORDS}")
    print(f"  Industry keywords: {INDUSTRY_KEYWORDS}")
    print(f"  Check interval: {CHECK_INTERVAL}s")
    print(f"  Slack webhook: {'configured' if SLACK_WEBHOOK_URL else 'NOT configured'}")

    while True:
        try:
            run_cycle()
        except Exception as e:
            print(f"  ERROR: {e}")
        time.sleep(CHECK_INTERVAL)


if __name__ == "__main__":
    if "--once" in sys.argv:
        run_cycle()  # Single cycle for testing / cron
    else:
        run_continuous()
Tested on 2026-10-01 (UTC)
I ran the code above with the LLM stubbed and the data calls live. Both list endpoints take no keyword; the requests below are exactly what the code sends. Field names come from these calls and are observed-only, not documented guarantees, which is why every read uses .get(). Responses are trimmed.
POST https://api.sandbase.ai/v1/api/weibo/web-v2/hot-search
{}

{"id": "1e56f2e0-3eca-4242-b371-0a4e2f4cc060", "status": "completed", "model": "weibo/web-v2/hot-search",
 "outputs": [{"data": {"realtime": [
   {"word": "鸿蒙智行问界业务升级", "num": 1116159, "realpos": 1, "label_name": "新", ...},
...], "hotgov": {...}, "hotgovs": [...]}}]}POST https://api.sandbase.ai/v1/api/douyin/billboard/hot-account-list
{"page_num": 1, "page_size": 10}
{"id": "c38e0333-4f1d-4104-b5bc-f41dbb8a06ad", "status": "completed", "model": "douyin/billboard/hot-account-list",
"outputs": [{"data": {"code": 0, "message": "", "data": {"has_more": true, "user_list": [
{"nick_name": "人民日报", "fans_cnt": 203210991, "new_fans_cnt": 51760, ...},
{"nick_name": "央视新闻", "fans_cnt": 187596558, "new_fans_cnt": 38735, ...},
...]}}}]}That run returned 51 hot search topics and 10 accounts (the top of the billboard was official media accounts such as People’s Daily and CCTV News). Across five test cycles the agent alerted on a brand mention and on an industry-only signal, skipped the alert when nothing was flagged, and the pre-filter version skipped the LLM when no keyword matched. The Slack payload was posted to a local test endpoint, not to a live Slack workspace.
Cost breakdown
The first 100 data API calls each day are free for your organization (on eligible APIs) and the rest are billed per call, so the data side is roughly the 92 calls a day beyond that × each endpoint’s catalog price (check with sandbase inspect), on top of the LLM cost. anthropic/claude-sonnet-4 is $3 per million input tokens and $15 per million output tokens on SandBase as of 2026-10-01.
Token assumptions (illustrative): the classification prompt built from my 2026-10-01 data was about 2,300–2,700 characters across the EN and ZH prompts (mostly JSON whitespace and ASCII, ~250 CJK characters in the EN one), which I round to ~1,000 input tokens; I assume ~300 output tokens for a typical reply. Per call: 1,000 × $3/M + 300 × $15/M = $0.003 + $0.0045 = $0.0075.
| Component | Per cycle | Per day (96 cycles) |
|---|---|---|
| Weibo hot search | 1 data call | 96 calls |
| Douyin hot accounts | 1 data call | 96 calls |
| LLM classification | 1 call, ~$0.0075 (estimate) | 96 calls, ~$0.72 |
| Total | 2 data calls + 1 LLM call | 192 data calls + ~$0.72 LLM |
That is about $21.60 in LLM tokens over a 30-day month, plus the per-call data charges for calls beyond the 100 free ones each day. Output is capped by max_tokens=1500; if every reply hit the cap, a call would cost $0.003 + 1,500 × $15/M = $0.0255, or $2.45 a day. The LLM tokens: line the code prints gives you the real numbers to redo this math.
Optimized version: keyword pre-filter
The LLM call is effectively the whole dollar cost, so skip it when no keyword appears in the raw lists:
def quick_keyword_check(items: list, keywords: list) -> bool:
    """Fast check: does any keyword appear in any item? No API call."""
    text = " ".join(json.dumps(i, ensure_ascii=False) for i in items).lower()
    return any(kw.lower() in text for kw in keywords)


def run_cycle_optimized():
    """Same as run_cycle, but only calls the LLM when a keyword shows up."""
    timestamp = datetime.now(timezone.utc).strftime("%Y-%m-%dT%H:%M:%SZ")
    weibo = fetch_weibo_hot_search()
    douyin = fetch_douyin_hot_accounts()

    if quick_keyword_check(weibo + douyin, BRAND_KEYWORDS + INDUSTRY_KEYWORDS):
        classification = classify_relevance(weibo, douyin)
        send_slack_alert(classification, timestamp)  # sends for brand or industry items
    else:
        classification = {"brand_mentions": [], "industry_relevant": [], "summary": "No keyword match"}
    log_cycle(timestamp, weibo, douyin, classification)
    return classification
The trade-off: the pre-filter only matches literal keywords, so an industry topic that doesn’t contain one of your words never reaches the LLM. The saving depends on how often your keywords show up. If, for illustration, 30% of cycles had a match, that is about 29 LLM calls a day instead of 96, or roughly 28.8 × $0.0075 × 30 ≈ $6.48 a month at the same token assumptions.
Deployment options
Option 1: Always-on process (VPS/container)
SANDBASE_API_KEY=sk-... SLACK_WEBHOOK_URL=https://hooks.slack.com/services/... python3 listener.pyKeep it alive with systemd or a Docker restart policy.
Option 2: Cron every 15 minutes
*/15 * * * * SANDBASE_API_KEY=sk-... SLACK_WEBHOOK_URL=... python3 listener.py --onceSimpler. Each invocation starts fresh; the JSONL log on disk is the only state, so the agent alerts again if an item stays on the list across cycles. Deduplicate against the last log line if that’s noisy.
Option 3: GitHub Actions
on:
  schedule:
    - cron: '*/15 * * * *'  # Every 15 minutes
GitHub documents that scheduled workflows can be delayed during periods of high load, so this is not a good fit for time-sensitive alerts.
What to do when an alert fires
The agent detects. A human decides. Recommended response flow:
- Brand mention alert → Marketing/PR team reviews within 30 minutes
- Negative sentiment + high heat → Escalate to crisis protocol
- Industry signal → Add to weekly strategy briefing
- Competitor mention → Log for competitive intelligence review
Extending the agent
Add sentiment depth: When a brand mention is detected, call fetch_weibo_keyword_posts() (weibo/web-v2/realtime-search, takes a query) to pull recent posts for that keyword and run sentiment analysis on them. In a 2026-10-01 call with {"query": "小米"} (run 973c3249-af8e-462c-b001-34e2fbf1ffac) it returned 10 posts under parsed_data.results (observed-only field names). It is not called in run_cycle; wiring it in adds one data call plus one sentiment LLM call per alert, not per cycle.
The reference for that follow-up endpoint shows query as its only required field, with page defaulting to 1.
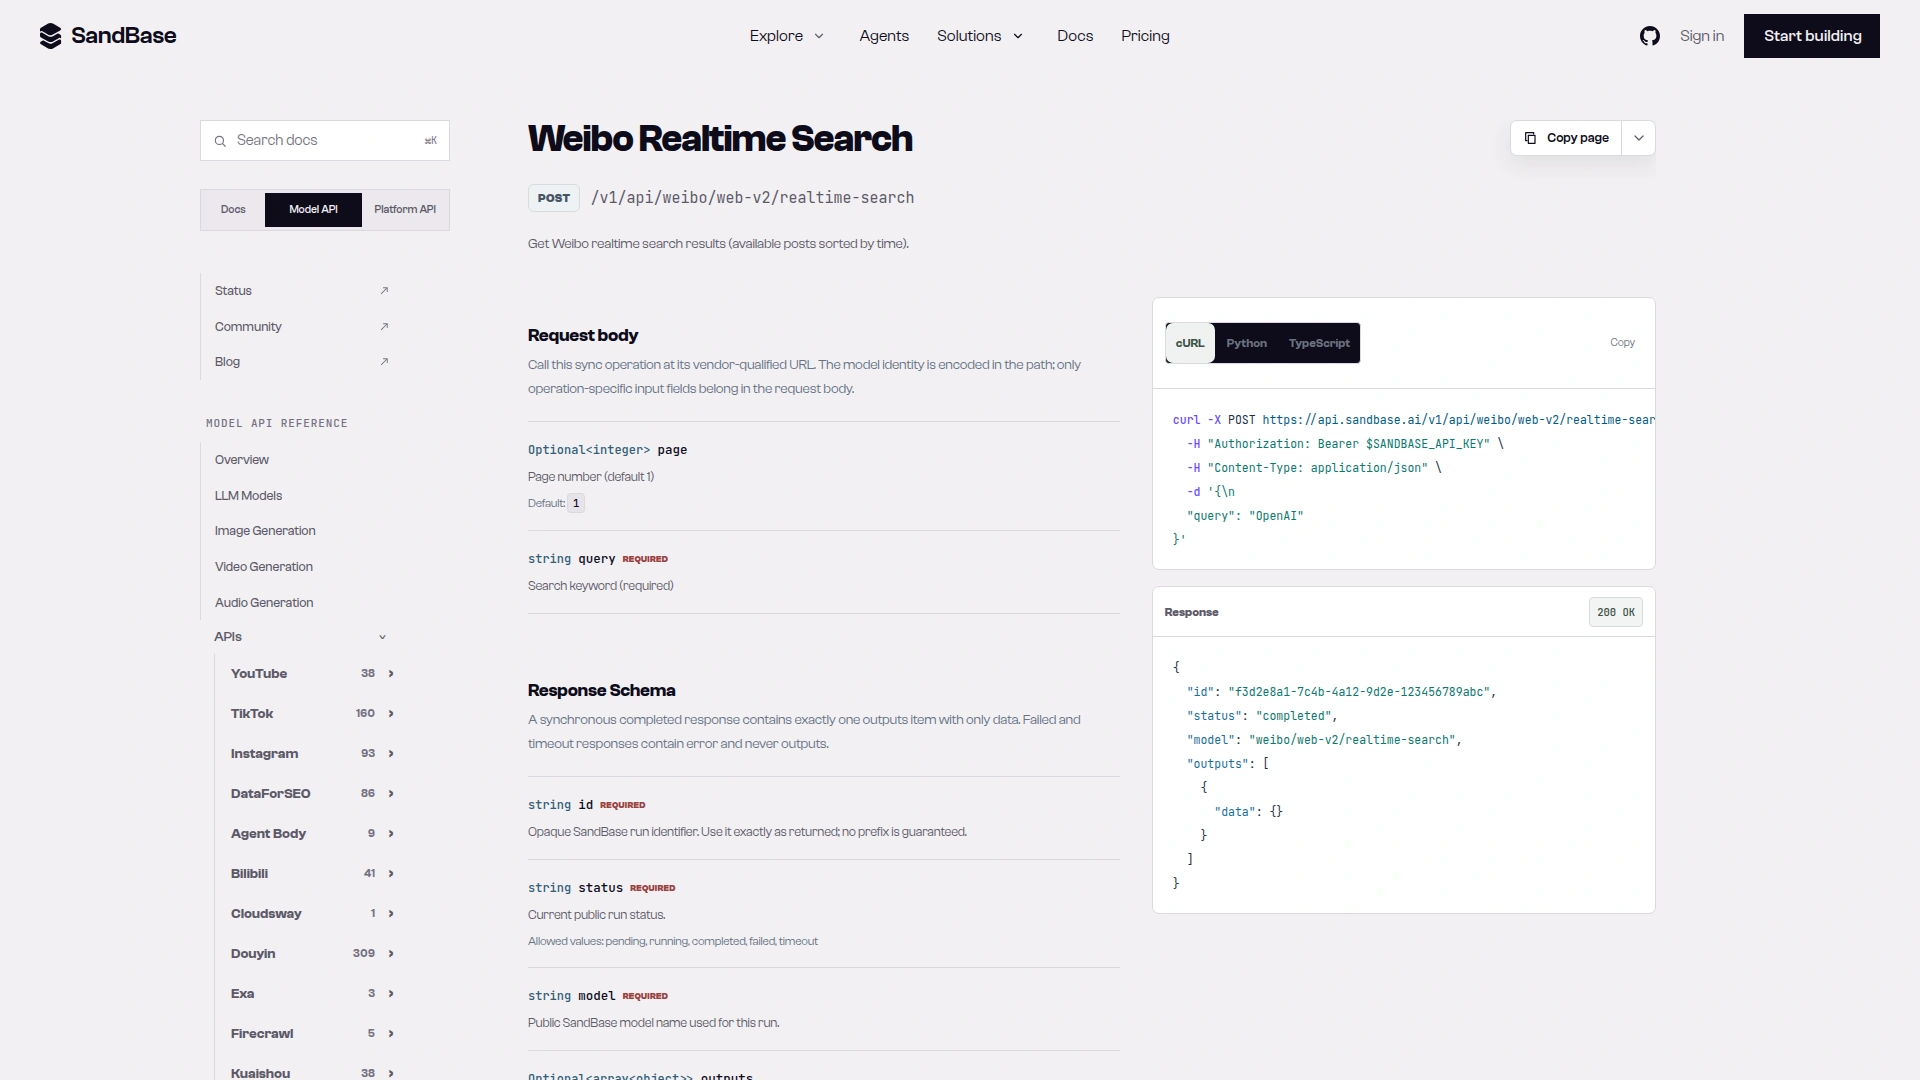
Caption: The weibo/web-v2/realtime-search reference used by fetch_weibo_keyword_posts(): query is required and page defaults to 1 (captured 2026-10-02).
Add Xiaohongshu: Keyword search via xiaohongshu/app-v2/search-notes (takes a keyword) works as a third source: in a 2026-10-01 call with {"keyword": "小米"} (run eae32bb2-f69c-4c98-8091-e60a139240cc) it returned 20 notes under data.items[].note (observed-only field names). Same pattern, one more data call per cycle (+96 calls/day).
Historical trend analysis: Because each log line keeps the flagged items, after 30 days you can ask an LLM which industry topics keep coming back week over week.
Limitations
- 15-minute granularity: Not real-time. A crisis can gain traction within one interval. For higher urgency, reduce to 5-minute intervals (3× the calls and LLM cost).
- LLM classification is imperfect: False positives happen. The prompt leans toward over-alerting; a human makes the final call.
- Weibo hot search is not exhaustive: Topics rotate quickly, and a brand complaint that never trends never shows up. Add keyword searches (see FAQ) for deeper coverage.
- No Douyin video content analysis: The agent sees hot account metadata, not video content. For a video you care about,
douyin/app-v3/one-video(takes anaweme_id) returns the video detail; in a 2026-10-01 call (run8d56b7aa-d98d-4559-b6da-cc2d17a47a2c) the payload sat underaweme_detail(observed-only).
FAQ
Can I monitor specific keywords instead of hot search?
Yes. Use weibo/web-v2/advanced-search (keyword goes in q; in a 2026-10-01 call with {"q": "小米"}, run 93a2caa9-42fe-497a-8dbf-3ffabfbc6fd4, it returned 20 posts under parsed_data.results, observed-only) or weibo/web-v2/realtime-search (keyword goes in query) with your own keywords instead of, or in addition to, the hot search list. This catches mentions that are not trending but still relevant.
How fast does this catch a brand crisis?
Only once the topic is on Weibo hot search or the account is on the Douyin billboard. From that point, the worst case is one full interval (15 minutes) plus the time the two data calls, the LLM call and the Slack post take; the data calls took 1.5–5.2 seconds each across the 22 hot-search and hot-account calls in my 2026-10-01 test runs.
What webhook services work?
The code sends Slack’s incoming-webhook payload, {"text": "..."}. I checked the request against a local test endpoint, not a live Slack workspace. Discord, PagerDuty, Feishu/Lark and DingTalk each expect a different JSON body, so they need their own payload builder.
Can I run this for multiple brands?
Yes. Either maintain separate instances with different keyword lists, or expand the keywords array and have the LLM classify per brand. The latter makes one LLM call per cycle instead of one per brand.
For more on the data available, see Weibo & Xiaohongshu Data APIs Now on SandBase and Douyin Public Data API.
Get a SandBase API key · Browse the Weibo API catalog · Browse the Douyin API catalog