Xiaohongshu KOL Screening Agent (Tutorial)
Build a Python agent that ranks Xiaohongshu KOL candidates from public PGY and note data: interactions per note, save share, 30-day growth, and LLM content fit.
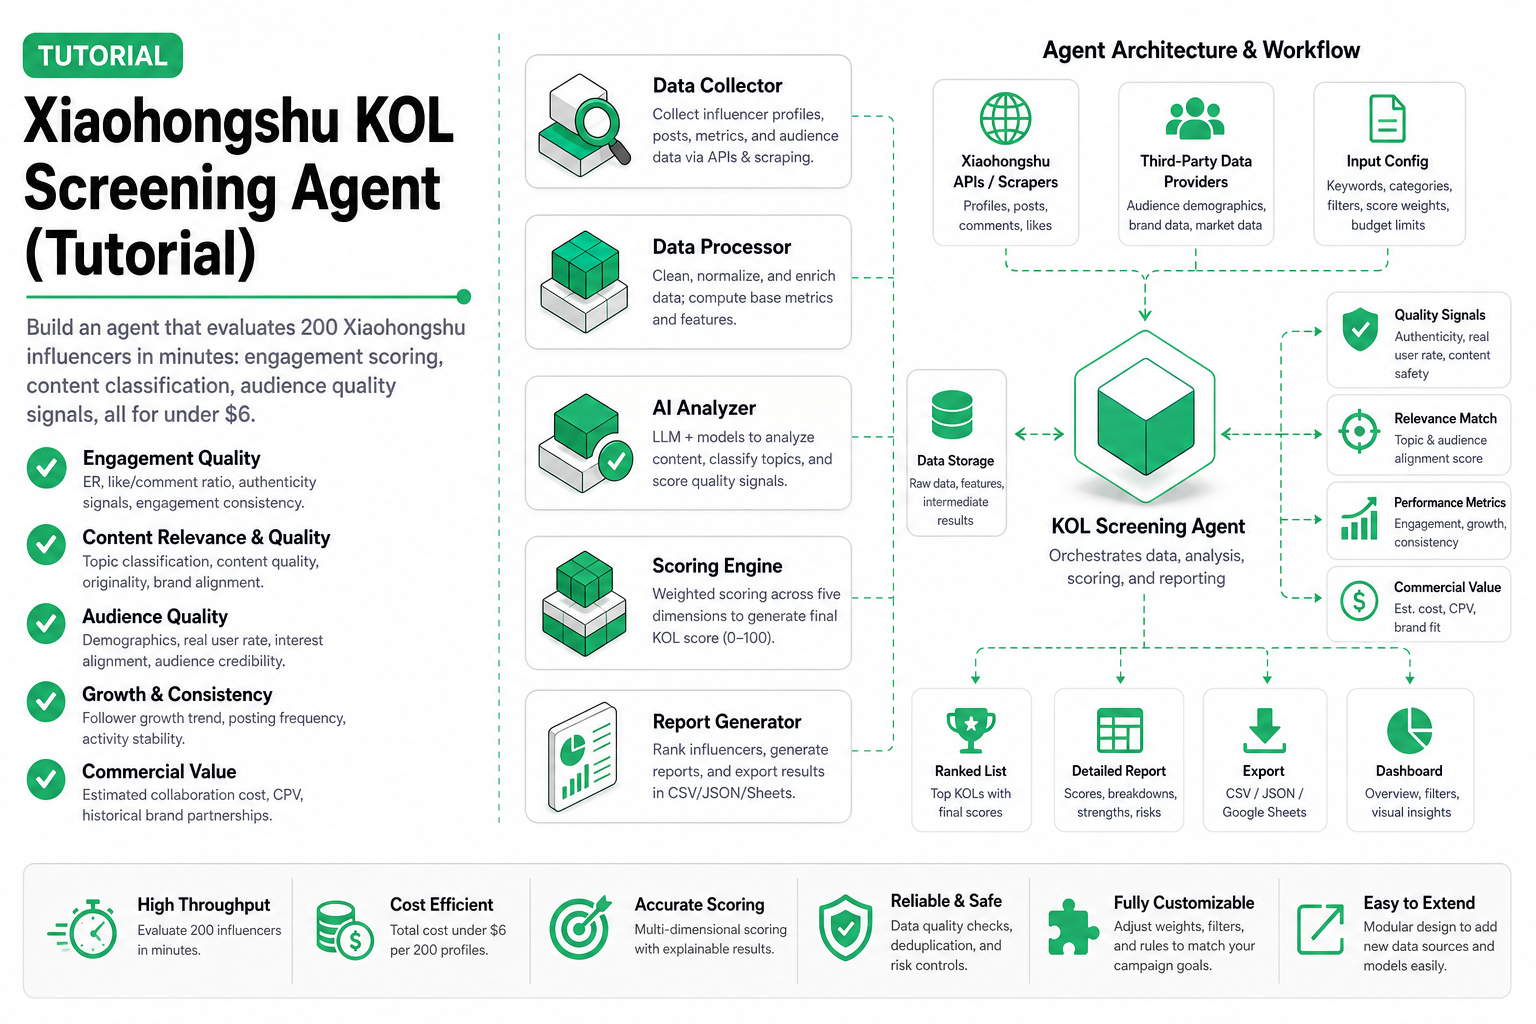
Key takeaway (TL;DR) — A Python agent that pulls Xiaohongshu KOL candidates from PGY (Pugongying), samples each one’s recent notes, and ranks them on average interactions per sampled note, 30-day follower growth, a PGY median-interactions signal, and an LLM content-fit score. For 200 candidates that is about 610 data calls. The 410 PGY calls are not covered by the daily free calls and are billed from the first call at the SandBase catalog price; only the 200
app-v2/user-posted-notescalls can draw on the organization’s 100 free calls a day, then they are billed per call too. The run also makes 200 short LLM calls, which are estimated at about $0.50 to $1.20 depending on token counts.
Screening KOLs for a Xiaohongshu campaign by hand means opening each profile, scrolling through posts, eyeballing engagement, and ranking candidates against each other. This agent does the repetitive part: it fetches the same public numbers for every candidate, scores them the same way, and writes a ranked CSV your team can review.
What the agent produces
For each KOL candidate:
| Output | Source | Price on SandBase |
|---|---|---|
Candidate list (userId) | xiaohongshu/pgy/blogger-list | Billed per call (see catalog) |
PGY profile (name, fansNum, median interactions interMidNum) | xiaohongshu/pgy/blogger-detail | Billed per call (see catalog) |
| Follower series (last 30 daily points) | xiaohongshu/pgy/blogger-fans-history | Billed per call (see catalog) |
| Sampled recent-note text and counts (first page, up to 10 notes) | xiaohongshu/app-v2/user-posted-notes | Billed per call (see catalog) |
| Average interactions per sampled note, save share | Computed from the note sample | — |
| LLM content-fit score (1–10) with one-sentence reasoning | anthropic/claude-sonnet-4 | Token-based (see costs) |
Final output: a ranked CSV with those metrics, the total score, the LLM’s reasoning, and red flags.
The scoring model
Total Score = 0.3 × Engagement score
            + 0.25 × Content fit
            + 0.25 × Growth score
            + 0.2 × Audience signal
Each component is on a 0–10 scale, exactly as the code computes it:
- Engagement score: average interactions per sampled note, where interactions =
likes + comments_count + collected_count, divided by 500 and capped at 10. This is a raw average, not a rate: there is no impressions or follower denominator. - Content fit: the LLM reads up to 10 sampled note titles (or descriptions) and returns a 1–10 score for your brand category. It sees text only, not images.
- Growth score:
(last − first) / firstover the last 30 daily points of the PGY follower series, × 100, clamped to 0–10 (10% growth or more = 10; shrinking accounts score 0). - Audience signal: PGY
interMidNum(median interactions) divided byfansNum, × 200, capped at 10 (5% or more = 10).
Red flags written to the CSV:
- more than 100,000 followers but fewer than 100 average interactions per sampled note
- any single-day follower change larger than 10% of the first point in the 30-day window
- saves below 5% of sampled interactions
Data boundary
This uses public, read-only Xiaohongshu data. It needs a SandBase API key and is not an official Xiaohongshu partnership. It does not access private accounts, DMs, owner-only analytics, or any publishing or account actions.
| SandBase public data endpoints | Official Xiaohongshu open platform | |
|---|---|---|
| Auth | One SandBase API key | Xiaohongshu developer or account authorization |
| Scope | Public creator, note, and PGY listing data | Accounts and businesses you are authorized for |
| Writes (publish, message, place orders) | None | Depends on the authorized integration |
| Use it when | Research and shortlisting across many public creators | You need owner-level data or to act on an account |
Endpoints and test evidence
Every data call goes to SandBase’s Model API route, POST https://api.sandbase.ai/v1/api/<vendor>/<path>, with only that endpoint’s parameters in the JSON body and Authorization: Bearer $SANDBASE_API_KEY. Endpoint references:
xiaohongshu/pgy/blogger-list(brand_user_idrequired;page_numfrom 1,page_size1–100; for the follower-range filter see “Whichblogger-listfilter fields work” below)xiaohongshu/pgy/blogger-detail(user_id)xiaohongshu/pgy/blogger-fans-history(user_id,date_type: 1 ≈ 7d, 2 ≈ 30d, 3 ≈ 90d)xiaohongshu/app-v2/user-posted-notes(user_id;cursorempty on the first request)
The Xiaohongshu catalog lists 34 endpoints as of 2026-10-01. It displays a separate GET /apis/v1/... surface; this tutorial uses the POST routes above.
The catalog page shows the 34 count and lists the PGY endpoints this agent calls, with the selected card marked Available.
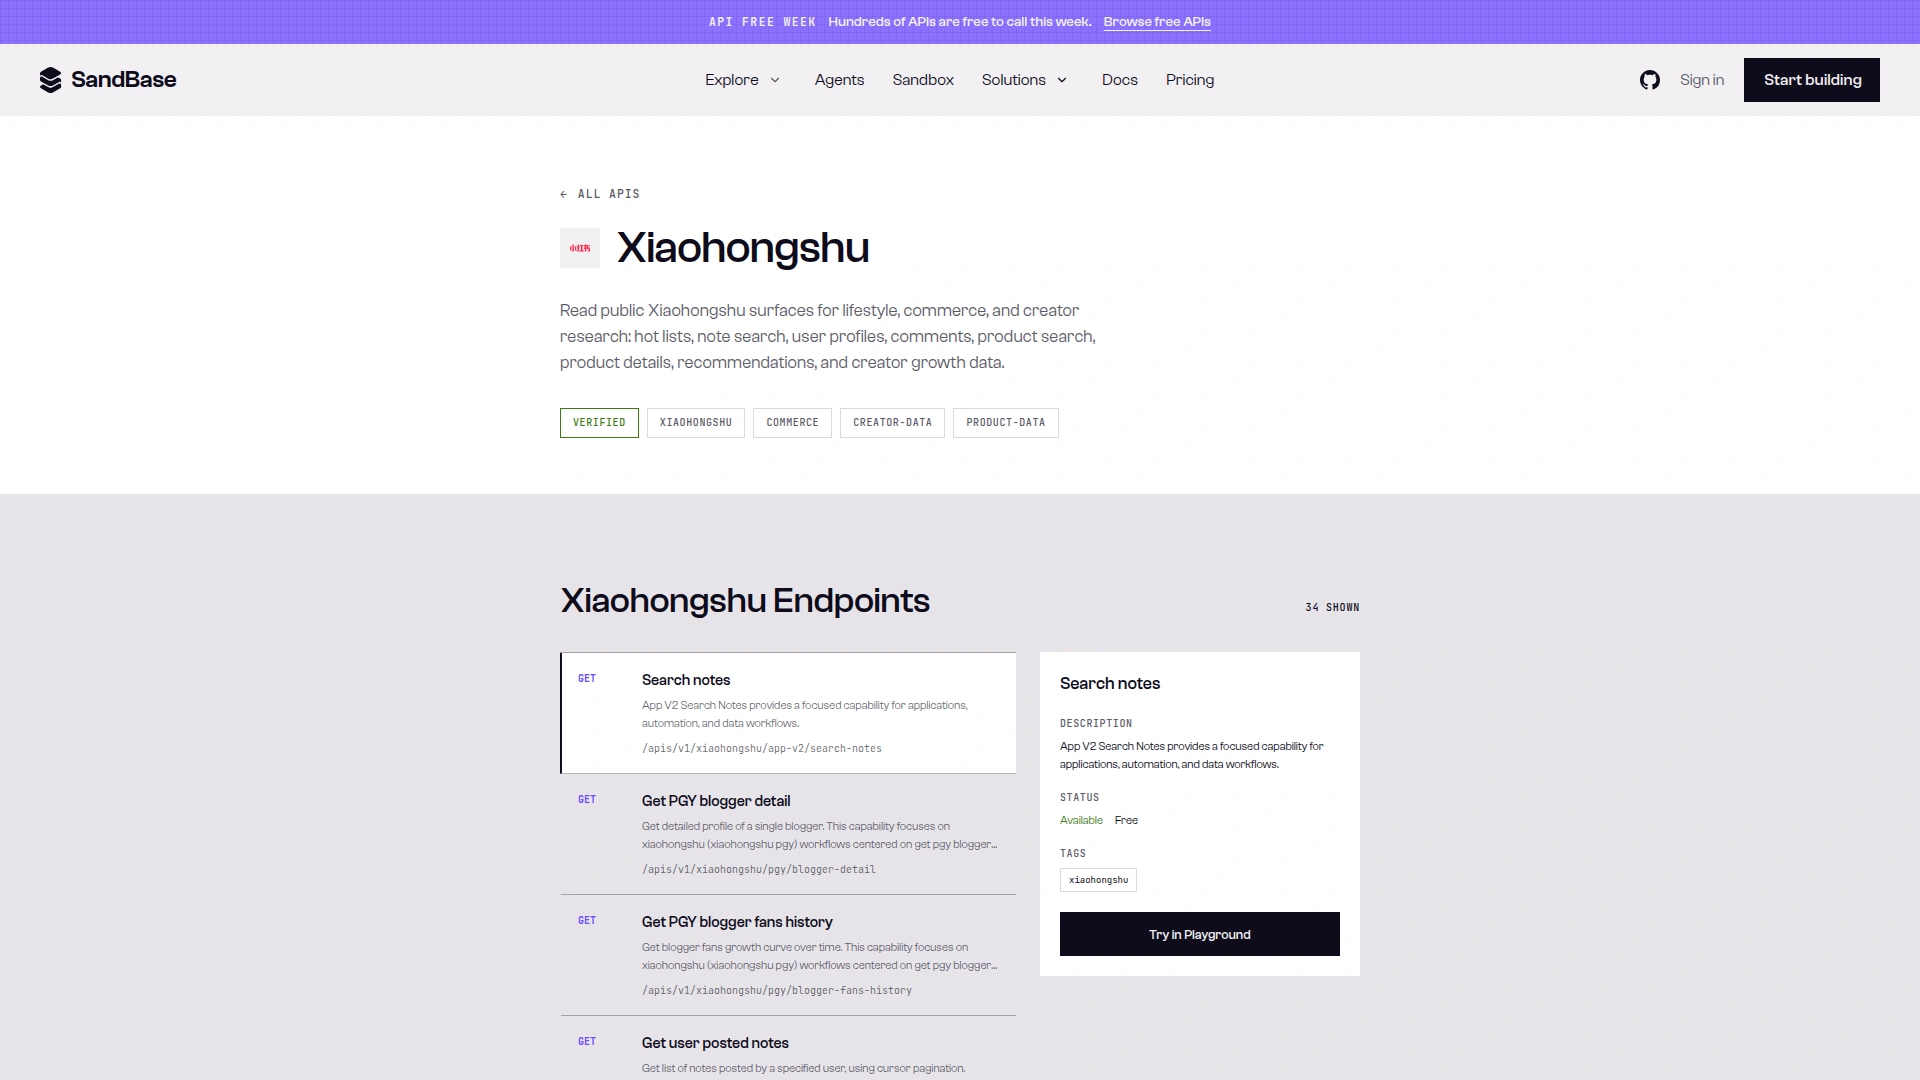
Caption: The SandBase Xiaohongshu catalog lists 34 endpoints, including pgy/blogger-detail and pgy/blogger-fans-history, and the selected card shows Available and Free (captured 2026-10-02). The Free label is from API Free Week, which has since ended; data API calls now include 100 free calls per organization per day on eligible APIs, then are billed per call.
Tested on 2026-10-01 (UTC)
Public resource: the Perfect Diary official brand account, user id 59ae4dfc5e87e72475fb3bf3.
curl -s https://api.sandbase.ai/v1/api/xiaohongshu/pgy/blogger-detail \
  -H "Authorization: Bearer $SANDBASE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"user_id": "59ae4dfc5e87e72475fb3bf3"}'
Trimmed response (run id 7476e66a-35d3-4e41-8c8d-a345ca4c7237):
{
  "id": "7476e66a-35d3-4e41-8c8d-a345ca4c7237",
  "status": "completed",
  "model": "xiaohongshu/pgy/blogger-detail",
  "outputs": [{"data": {"code": 0, "data": {
    "userId": "59ae4dfc5e87e72475fb3bf3",
    "name": "Perfect Diary完美日记",
    "fansNum": 1835170,
    "interMidNum": 0
  }}}]
}
blogger-fans-history with {"user_id": "59ae4dfc5e87e72475fb3bf3", "date_type": 2} (run id 2b0cdf3e-6597-47c3-8ca3-60fed77ef5c3) returned 60 daily points, so the code keeps the last 30:
{"code": 0, "data": {"fansNumInc": -9214, "list": [
  {"dateKey": "2026-08-02", "num": 1842991}, "…",
  {"dateKey": "2026-09-30", "num": 1833777}
]}}
user-posted-notes with {"user_id": "59ae4dfc5e87e72475fb3bf3"} (run id f30a6744-3ef2-4204-8081-bc64645e3fc5) returned 20 notes and has_more: true. One trimmed note:
{"id": "6abcd6f600000000020115f9", "cursor": "6abcd6f600000000020115f9",
 "title": "🦌新成员集结|小鹿限定线上开售",
 "likes": 37, "comments_count": 33, "collected_count": 22}
Which blogger-list filter fields work
The two public pages disagree on how to pass a follower range. The endpoint reference lists flat string params fans_number_lower / fans_number_upper. The model page lists 16 input fields, including nested blogger (creator attributes such as content_tag) and fans (audience filters such as count: {min, max}), and no fans_number_*. I sent both shapes on 2026-10-01 (UTC), each with brand_user_id = Perfect Diary, page_num: 1, page_size: 20, and compared fansNum across the 20 returned kols[]:
| Extra fields sent | Run id | data.total | fansNum range in the 20 results |
|---|---|---|---|
| none (baseline) | b9923cbd-a6ac-43a5-864a-d733835c5eaa | 5000 | 10,394 – 679,562 |
"fans_number_lower": "100000", "fans_number_upper": "200000" | 82513a86-a5ea-457d-a427-80a8e420bc63 | 5000 | 10,394 – 679,562 |
"fans": {"count": {"min": 100000, "max": 200000}} | 81e9474f-220b-4673-9a8f-2cc9afddb1c3 | 10000 | 100,253 – 199,199 |
"fans_number_lower": "10000", "fans_number_upper": "500000" + "blogger": {"content_tag": ["美妆"]} | 6890bd60-e050-48d4-b642-2ccd064f1af0 | 10000 | 6,486 – 2,654,665 |
"fans": {"count": {"min": 10000, "max": 500000}} + "blogger": {"content_tag": ["美妆"]} | 3e77814e-7fe1-4a09-9de9-c3b0e427995c | 10000 | 13,525 – 331,423 |
The two pages behind that disagreement look like this. The endpoint reference lists the flat fans_number_lower / fans_number_upper strings next to brand_user_id, page_num and page_size:
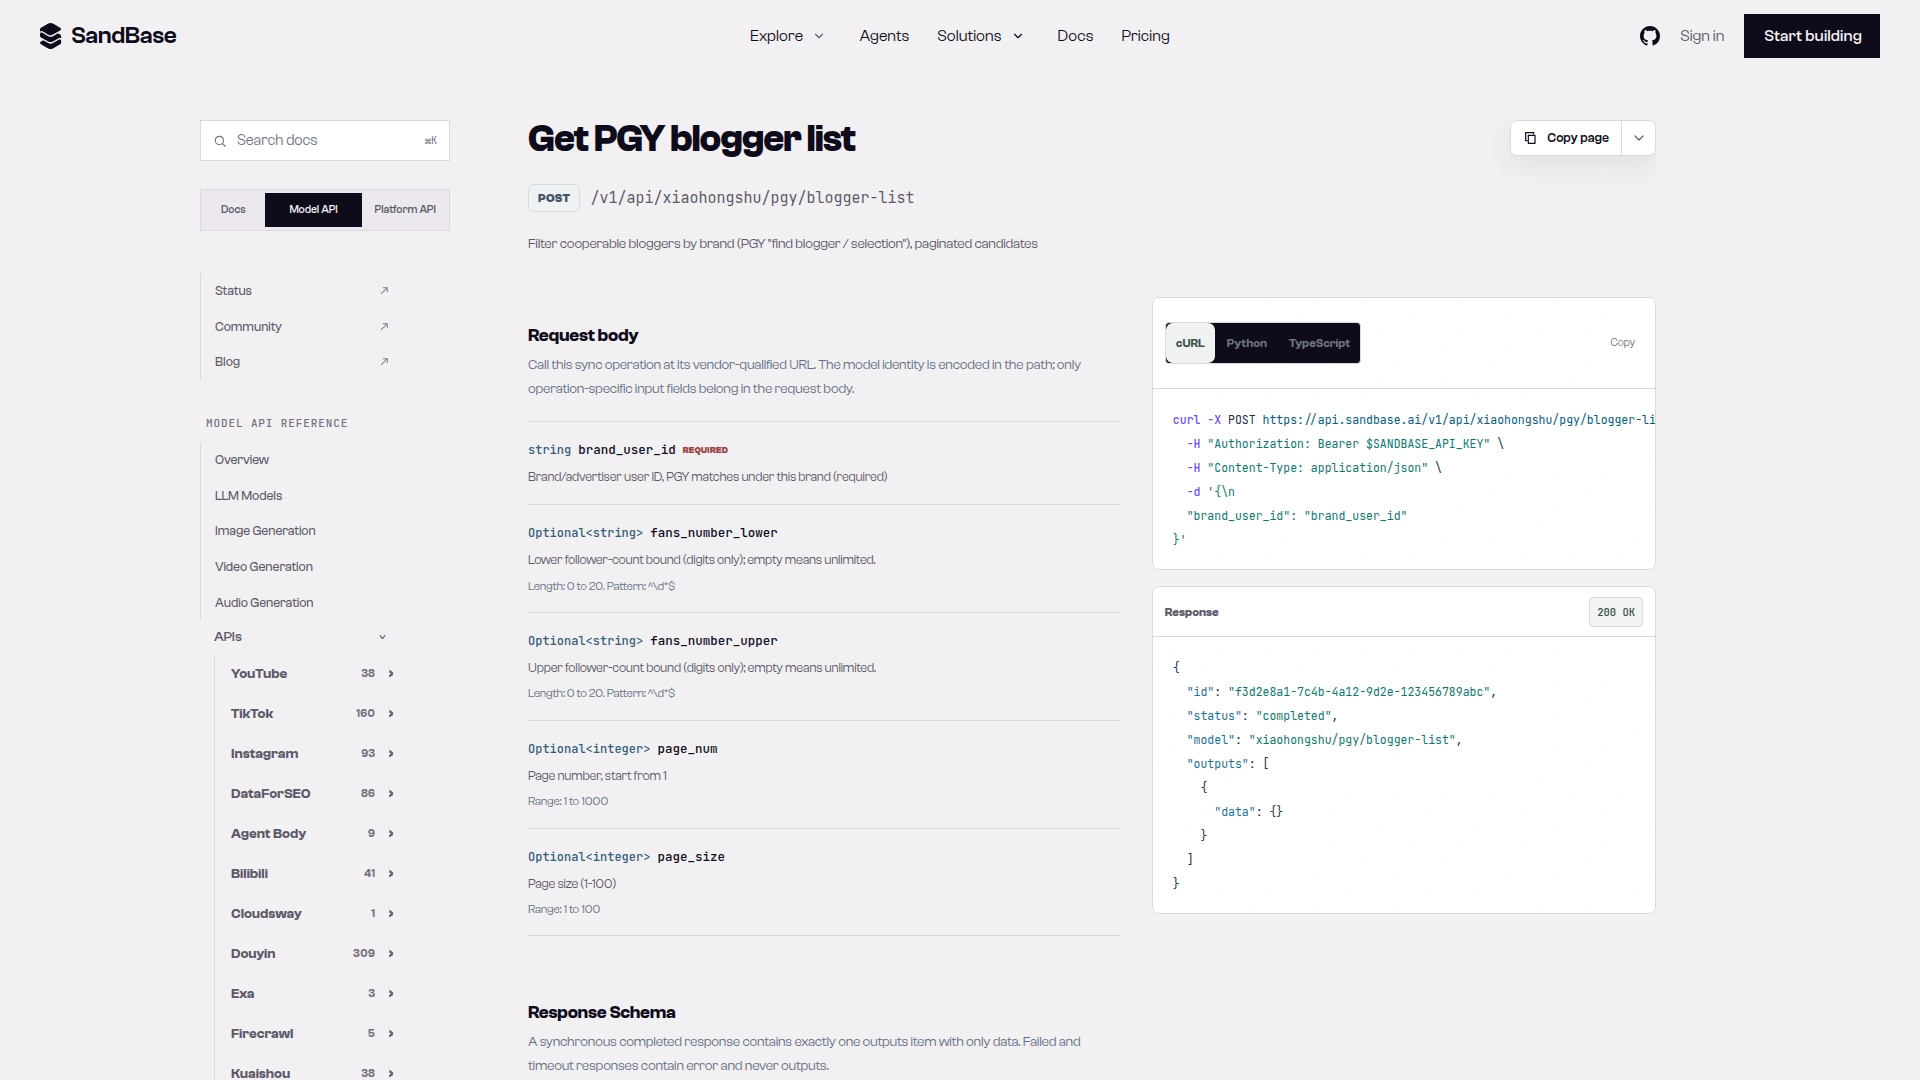
Caption: The xiaohongshu/pgy/blogger-list reference shows POST /v1/api/xiaohongshu/pgy/blogger-list with the flat fans_number_lower / fans_number_upper params that the test above found to be ignored (captured 2026-10-02).
The model page, by contrast, reports 16 input fields:
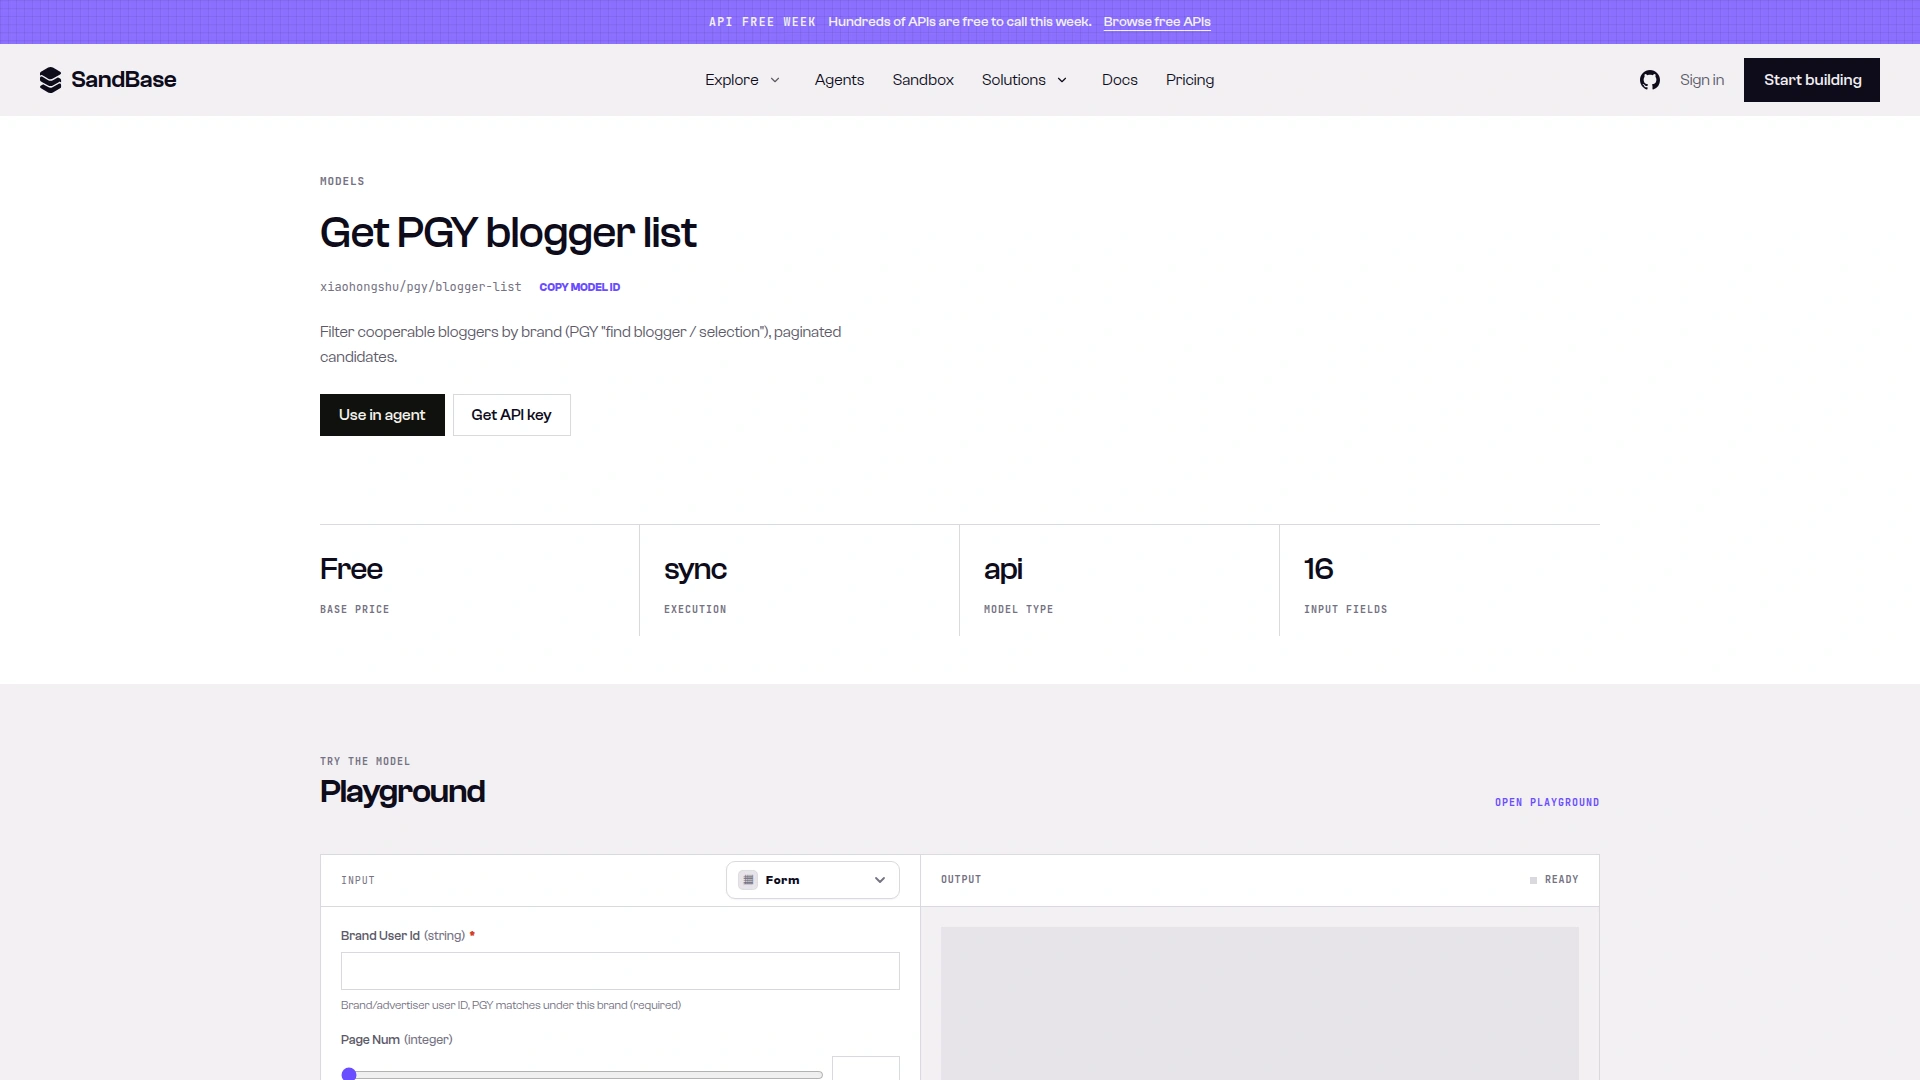
Caption: The xiaohongshu/pgy/blogger-list model page shows Base price Free, sync execution and 16 input fields, the schema that carries the nested fans and blogger filters (captured 2026-10-02). The Free label is from API Free Week, which has since ended; data API calls now include 100 free calls per organization per day on eligible APIs, then are billed per call.
The fans_number_* params were accepted (status completed) but did not filter: results matched the baseline. The nested fans.count object did filter, with every result inside the range. So the code below uses blogger.content_tag and fans.count. This is observed behavior from these runs, not a documented guarantee; if the reference and the endpoint are reconciled later, re-check before relying on either shape. The results are individual creators, so only aggregate numbers are shown; each item carried userId, fansNum, interMidNum, and contentTags.
What is documented versus observed: the endpoint references document the request parameters (for blogger-list’s nested blogger / fans filters, the model page) and the envelope (id, status, model, outputs[0].data). The business fields inside data (name, fansNum, interMidNum, list[].num, notes[].likes, comments_count, collected_count, kols[].userId) come from these calls and are observed-only, not documented guarantees. The code reads each one with .get(). Note that a brand account like this one is not a PGY creator, which is likely why interMidNum is 0; for listed creators it was non-zero in the blogger-list results.
Complete code
#!/usr/bin/env python3
"""Xiaohongshu KOL screening agent.

Pulls KOL candidates from PGY, samples their notes, scores them, and writes a ranked CSV.
"""

import csv
import json
import os
import time
from dataclasses import dataclass

import requests
from openai import OpenAI

SANDBASE_API_KEY = os.environ["SANDBASE_API_KEY"]
HEADERS = {
    "Authorization": f"Bearer {SANDBASE_API_KEY}",
    "Content-Type": "application/json",
}

# OpenAI client for LLM calls only
client = OpenAI(
    base_url="https://api.sandbase.ai/v1",
    api_key=SANDBASE_API_KEY,
)


@dataclass
class KOLScore:
    blogger_id: str
    nickname: str
    follower_count: int
    avg_interactions_per_note: float
    save_share: float
    growth_30d: float
    audience_score: float
    content_fit: float
    total_score: float
    reasoning: str
    red_flags: list[str]


def run_model(model: str, **params) -> dict:
    """POST /v1/api/<model> and return the upstream `data` object inside outputs[0].data."""
    resp = requests.post(
        f"https://api.sandbase.ai/v1/api/{model}",
        headers=HEADERS,
        json=params,
        timeout=90,
    )
    resp.raise_for_status()
    body = resp.json()
    outputs = body.get("outputs") or []
    if body.get("status") != "completed" or not outputs:
        raise RuntimeError(f"SandBase call did not complete: {body.get('status')} {body.get('error')}")
    payload = outputs[0].get("data") or {}
    return payload.get("data") or {}


def fetch_candidates(brand_user_id: str, content_tag: str, min_fans: int, max_fans: int,
                     pages: int = 10, page_size: int = 20) -> list[str]:
    """Page through PGY blogger-list and return candidate userIds."""
    ids = []
    for page in range(1, pages + 1):
        data = run_model(
            "xiaohongshu/pgy/blogger-list",
            brand_user_id=brand_user_id,
            blogger={"content_tag": [content_tag]},
            fans={"count": {"min": min_fans, "max": max_fans}},
            page_num=page,
            page_size=page_size,
        )
        kols = data.get("kols") or []
        ids += [k["userId"] for k in kols if k.get("userId")]
        if not kols:  # a short page isn't a reliable end signal; stop on an empty one
            break
    return ids


def fetch_blogger_detail(blogger_id: str) -> dict:
    """PGY blogger overview (name, fans, median interactions)."""
    return run_model("xiaohongshu/pgy/blogger-detail", user_id=blogger_id)


def fetch_fans_history(blogger_id: str) -> dict:
    """Follower history (date_type=2 is the ~30-day option in the reference)."""
    return run_model("xiaohongshu/pgy/blogger-fans-history", user_id=blogger_id, date_type=2)


def fetch_recent_notes(blogger_id: str, count: int = 10) -> list:
    """Sample the first page of the creator's own notes (no cursor = first page)."""
    data = run_model("xiaohongshu/app-v2/user-posted-notes", user_id=blogger_id)
    return (data.get("notes") or [])[:count]


def compute_engagement_metrics(notes: list) -> dict:
    """Average interactions per sampled note and the share of interactions that are saves."""
    if not notes:
        return {"avg_interactions_per_note": 0, "save_share": 0}

    total_likes = sum(n.get("likes") or 0 for n in notes)
    total_comments = sum(n.get("comments_count") or 0 for n in notes)
    total_saves = sum(n.get("collected_count") or 0 for n in notes)
    total_interactions = total_likes + total_comments + total_saves

    return {
        "avg_interactions_per_note": total_interactions / len(notes),
        "save_share": total_saves / max(total_interactions, 1),
    }


def compute_growth(fans_history: dict) -> dict:
    """Follower growth over the last 30 daily points, plus a single-day spike check."""
    data_points = (fans_history.get("list") or [])[-30:]
    if len(data_points) < 2:
        return {"growth_30d": 0, "spike_detected": False}

    first = data_points[0].get("num") or 0
    last = data_points[-1].get("num") or 0
    growth_rate = (last - first) / max(first, 1)

    max_daily_change = 0
    for i in range(1, len(data_points)):
        daily_change = abs((data_points[i].get("num") or 0) - (data_points[i - 1].get("num") or 0))
        max_daily_change = max(max_daily_change, daily_change)

    spike_threshold = first * 0.1  # a >10% move in one day is treated as suspicious
    return {
        "growth_30d": growth_rate,
        "spike_detected": max_daily_change >= spike_threshold > 0,
    }


def score_content_fit(notes: list, brand_category: str) -> dict:
    """LLM rates content fit from sampled note titles/descriptions."""
    if not notes:
        return {"score": 0, "reasoning": "No notes available"}

    note_descriptions = [(n.get("title") or n.get("desc") or "")[:100] for n in notes[:10]]

    resp = client.chat.completions.create(
        model="anthropic/claude-sonnet-4",
        messages=[{
            "role": "user",
            "content": f"""Rate this KOL's content fit for a brand in the "{brand_category}" category.

Their recent note titles/descriptions (up to 10):
{json.dumps(note_descriptions, ensure_ascii=False)}

Score 1-10 where:
- 1-3: Completely unrelated content
- 4-6: Some overlap but not core focus
- 7-9: Strong category alignment
- 10: Perfect fit, exact target audience

Respond in JSON: {{"score": N, "reasoning": "one sentence"}}"""
        }],
        max_tokens=200,
    )
    try:
        return json.loads(resp.choices[0].message.content)
    except json.JSONDecodeError:
        return {"score": 5, "reasoning": "Could not parse LLM response"}


def screen_kol(blogger_id: str, brand_category: str) -> KOLScore:
    """Full screening of a single KOL candidate (3 data calls + 1 LLM call)."""
    detail = fetch_blogger_detail(blogger_id)
    fans = fetch_fans_history(blogger_id)
    notes = fetch_recent_notes(blogger_id, count=10)

    engagement = compute_engagement_metrics(notes)
    growth = compute_growth(fans)
    content = score_content_fit(notes, brand_category)

    red_flags = []
    follower_count = detail.get("fansNum") or detail.get("fansCount") or 0
    if follower_count > 100000 and engagement["avg_interactions_per_note"] < 100:
        red_flags.append("Very low interactions for follower count")
    if growth.get("spike_detected"):
        red_flags.append("Single-day follower spike over 10%")
    if engagement["save_share"] < 0.05:
        red_flags.append("Saves under 5% of interactions")

    # Each component on a 0-10 scale
    engagement_score = min(engagement["avg_interactions_per_note"] / 500, 10)
    growth_score = max(0, min(growth["growth_30d"] * 100, 10))  # 10% growth = 10, shrinking = 0
    median_interactions = detail.get("interMidNum") or 0
    audience_score = min(median_interactions / max(follower_count, 1) * 200, 10)  # 5% = 10
    content_score = content.get("score", 5)

    total = (
        0.3 * engagement_score
        + 0.25 * content_score
        + 0.25 * growth_score
        + 0.2 * audience_score
    )

    return KOLScore(
        blogger_id=blogger_id,
        nickname=detail.get("name") or "Unknown",
        follower_count=follower_count,
        avg_interactions_per_note=engagement["avg_interactions_per_note"],
        save_share=engagement["save_share"],
        growth_30d=growth["growth_30d"],
        audience_score=round(audience_score, 2),
        content_fit=content_score,
        total_score=round(total, 2),
        reasoning=content.get("reasoning", ""),
        red_flags=red_flags,
    )


def run_screening(blogger_ids: list[str], brand_category: str, output_path: str):
    """Screen all candidates and write a ranked CSV."""
    results: list[KOLScore] = []

    for i, blogger_id in enumerate(blogger_ids):
        print(f"[{i+1}/{len(blogger_ids)}] Screening {blogger_id}...")
        try:
            results.append(screen_kol(blogger_id, brand_category))
        except Exception as e:
            print(f"  Error: {e}")
        time.sleep(0.5)  # small pause between candidates (not a documented limit)

    results.sort(key=lambda x: x.total_score, reverse=True)

    with open(output_path, "w", newline="", encoding="utf-8-sig") as f:
        writer = csv.writer(f)
        writer.writerow([
            "Rank", "Nickname", "Blogger ID", "Followers", "Avg Interactions/Note",
            "Save Share", "30d Growth", "Audience Signal", "Content Fit",
            "Total Score", "Reasoning", "Red Flags"
        ])
        for rank, r in enumerate(results, 1):
            writer.writerow([
                rank, r.nickname, r.blogger_id, r.follower_count,
                f"{r.avg_interactions_per_note:.0f}", f"{r.save_share:.2%}",
                f"{r.growth_30d:.1%}", r.audience_score, r.content_fit,
                r.total_score, r.reasoning, "; ".join(r.red_flags) or "None"
            ])

    print(f"\nScreening complete. {len(results)} KOLs scored.")
    print(f"Output: {output_path}")
    print("Top 5:")
    for r in results[:5]:
        print(f"  {r.nickname}: {r.total_score} ({r.reasoning})")


if __name__ == "__main__":
    # Perfect Diary's public brand account id, used as brand_user_id in the test run above.
    # Replace it with your own brand's account id.
    BRAND_USER_ID = "59ae4dfc5e87e72475fb3bf3"
    candidate_ids = fetch_candidates(BRAND_USER_ID, "美妆", 10_000, 500_000, pages=10)  # up to 200
    run_screening(candidate_ids, brand_category="beauty & skincare", output_path="kol_ranking.csv")
I re-ran this program on 2026-10-01 (UTC) with pages=1, page_size=5 and the LLM call stubbed; everything else is the code above. blogger-list (run id ae88f94c-acc6-48e2-a9d8-49875396ef5f, sending blogger.content_tag: ["美妆"] and fans.count: {min: 10000, max: 500000}) returned 4 candidates for a page_size of 5, which is why the loop stops on an empty page rather than a short one. Their blogger-detail follower counts were 30,070 to 241,830, all inside the requested range. The 12 per-candidate calls that followed all came back completed through /v1/api/... (for example 71abb82d-3659-4398-b7aa-11143b97c24d, a7739dd3-990a-4997-ae38-e66367b536c8, 44fbe915-4469-47a9-a386-1da7faa99cc0), and the CSV had 4 ranked rows. user-posted-notes is cursor-paginated; the code reads only the first page on purpose, since 10 recent notes is the sample. To go further back, pass the last note’s cursor as cursor on the next request, as the reference describes.
Next steps: Get a SandBase API key, browse the Xiaohongshu catalog, or open the blogger-detail reference.
Cost estimate for 200 KOLs
| Operation | Calls | Price on SandBase |
|---|---|---|
pgy/blogger-list (20 per page) | 10 | Billed from the first call, not covered by free calls (see catalog) |
pgy/blogger-detail | 200 | Billed from the first call, not covered by free calls (see catalog) |
pgy/blogger-fans-history | 200 | Billed from the first call, not covered by free calls (see catalog) |
app-v2/user-posted-notes | 200 | Eligible for the daily free calls, then billed per call (see catalog) |
anthropic/claude-sonnet-4 content fit | 200 | $3/M input tokens, $15/M output tokens |
Each organization gets 100 free data API calls per UTC day across eligible APIs. The three PGY endpoints (410 of the 610 calls) are not eligible, so they are billed from the first call at the catalog price. Only the 200 app-v2/user-posted-notes calls draw on the free calls, which covers at most 100 of them a day; the rest are billed per call. Multiply the call counts above by each endpoint’s price in the Xiaohongshu catalog (or from sandbase inspect) before a large run.
LLM estimate (not a quote; billing follows measured tokens). Each scoring prompt carries up to 10 note titles of at most 100 characters plus a short instruction. In my test run the four prompts were 564 to 594 characters. Two scenarios, with the reply being a JSON score and one sentence (max_tokens=200 caps it):
| Scenario | Input tokens | Output tokens | Per call | 200 calls |
|---|---|---|---|---|
| Short titles, like the test run | ~500 | ~60 | 500 × $3/M + 60 × $15/M = $0.0024 | ~$0.48 |
| Long titles, reply hits the cap | ~1,000 | 200 | 1,000 × $3/M + 200 × $15/M = $0.006 | ~$1.20 |
Ways to trim:
- Skip fans history on the first pass. Rank on engagement and content fit, then fetch fans history only for the top 50. That needs a small change to
screen_koland cuts data calls from ~610 to ~460. - Use a cheaper model for content fit. With
openai/gpt-4.1-mini($0.40/M input, $1.60/M output), the long-title scenario is 1,000 × $0.40/M + 200 × $1.60/M ≈ $0.0007 per call, about $0.14 for 200. - Batching 10 KOLs per prompt cuts the call count to 20, but it only saves the repeated instruction text; the note titles and replies still scale with the number of KOLs.
Limitations
- PGY coverage: Not every creator is on PGY. For accounts that aren’t (like the brand account in the test),
interMidNumcame back as 0, which zeroes the audience signal. Useblogger-listresults, which are PGY creators, as the candidate pool. - Raw averages, not rates: The engagement score is average interactions per sampled note. It favors larger accounts. If you want a per-follower rate, divide by
fansNumyourself and rescale. - Small sample: 10 notes from the first page, which may include pinned or older notes.
- Content fit is subjective: The LLM sees titles only. Calibrate with 10 known-good and 10 known-bad KOLs before a full run.
- No fake-follower detection: The single-day spike check is a heuristic. Use a dedicated audit tool for high-stakes campaigns.
FAQ
How do I get 200 candidate blogger IDs?
fetch_candidates() above pages through xiaohongshu/pgy/blogger-list with a content tag and follower range. The reference marks brand_user_id as required; in my test the public Perfect Diary account id worked. Candidates came back under data.kols[], each with a userId the other functions accept (observed-only).
Can I run this for categories other than beauty?
Yes. Change the content_tag passed to fetch_candidates() (for example 美食 for food or 母婴 for mother and baby) and the brand_category string the LLM sees.
How long does screening 200 KOLs take?
It depends on upstream response times, which vary. The program makes about 610 sequential data calls and 200 LLM calls, with a 0.5-second pause per candidate. In 38 data calls I made on 2026-10-01 (LLM stubbed), the median was about 2.6 seconds and the slowest about 16 seconds; one call returned a transient HTTP 503, which the loop logs and skips. Add a retry in run_model if you can’t afford to drop candidates. Time a small run (pages=1) yourself and extrapolate.
What is a “good” total score?
There’s no universal cutoff. Score 10 KOLs you already know are good fits and use their range as your benchmark.
For more on Xiaohongshu data coverage, see Xiaohongshu (RED) Public Data API on SandBase. For the broader social data landscape, see our social media data API guide.
Related Reading
- Xiaohongshu (RED) Public Data API on SandBase
- Weibo & Xiaohongshu Data APIs Now on SandBase
- Build a Social Listening Agent: Weibo + Douyin
- Build a Social Monitor Agent (OpenAI SDK)
- Top 5 Social Media Data APIs for AI Agents (2026)
- China Social Commerce Data: The Agent Opportunity
- Social Data API vs Web Scraping for Agents (2026)