Weibo & Xiaohongshu Data APIs Now on SandBase
As of 2026-10-01 the SandBase catalog shows 52 Weibo and 34 Xiaohongshu public-data endpoints: hot search, realtime search, PGY creator research, note details.
Key takeaway (TL;DR) — As of 2026-10-01 the SandBase catalog shows 52 Weibo endpoints (hot search, realtime search, public timelines, app-level user data) and 34 Xiaohongshu endpoints (PGY-labelled creator research, note details, product recommendations). Each organization gets 100 free data API calls per UTC day, shared across eligible APIs; beyond that, the Weibo and Xiaohongshu
app-v2/web-v3endpoints this article calls are billed per call. The Xiaohongshu PGY (xiaohongshu/pgy/*) endpoints are not covered by the daily free calls and are billed from the first call at the catalog price. Check each endpoint’s catalog card (orsandbase inspect) for the current price. The catalog pages display aGET /apis/v1/...surface; this article uses the Model APIPOST /v1/api/...routes documented on each endpoint reference. Every Weibo and Xiaohongshu data call in this article isPOST https://api.sandbase.ai/v1/api/<vendor>/<path>with one SandBase API key; the LLM step usesPOST /v1/chat/completionswith the same key.
Two platforms, two fundamentally different data profiles. Weibo is China’s real-time public square: breaking news, trending opinions, and brand crises surface here first. Xiaohongshu is China’s consumption decision engine: product reviews, lifestyle content, and KOL recommendations drive purchase behavior. SandBase’s Weibo & Xiaohongshu Data APIs give an agent read access to the public side of both.
An agent that monitors both captures the full spectrum: what people are talking about (Weibo) and what they are buying (Xiaohongshu).
Scope. These are public, read-only data endpoints. Every call in this article needs a SandBase API key. SandBase is not an official partner of Weibo or Xiaohongshu, and these endpoints don’t cover private-account data, DMs, owner-only analytics, publishing, or account actions.
Weibo: 52 endpoints, 2 channels
Counts are what the Weibo catalog page shows as of 2026-10-01.
The catalog itself is the evidence for the 52 count: the header reads “52 SHOWN”, and the selected endpoint card shows Available.
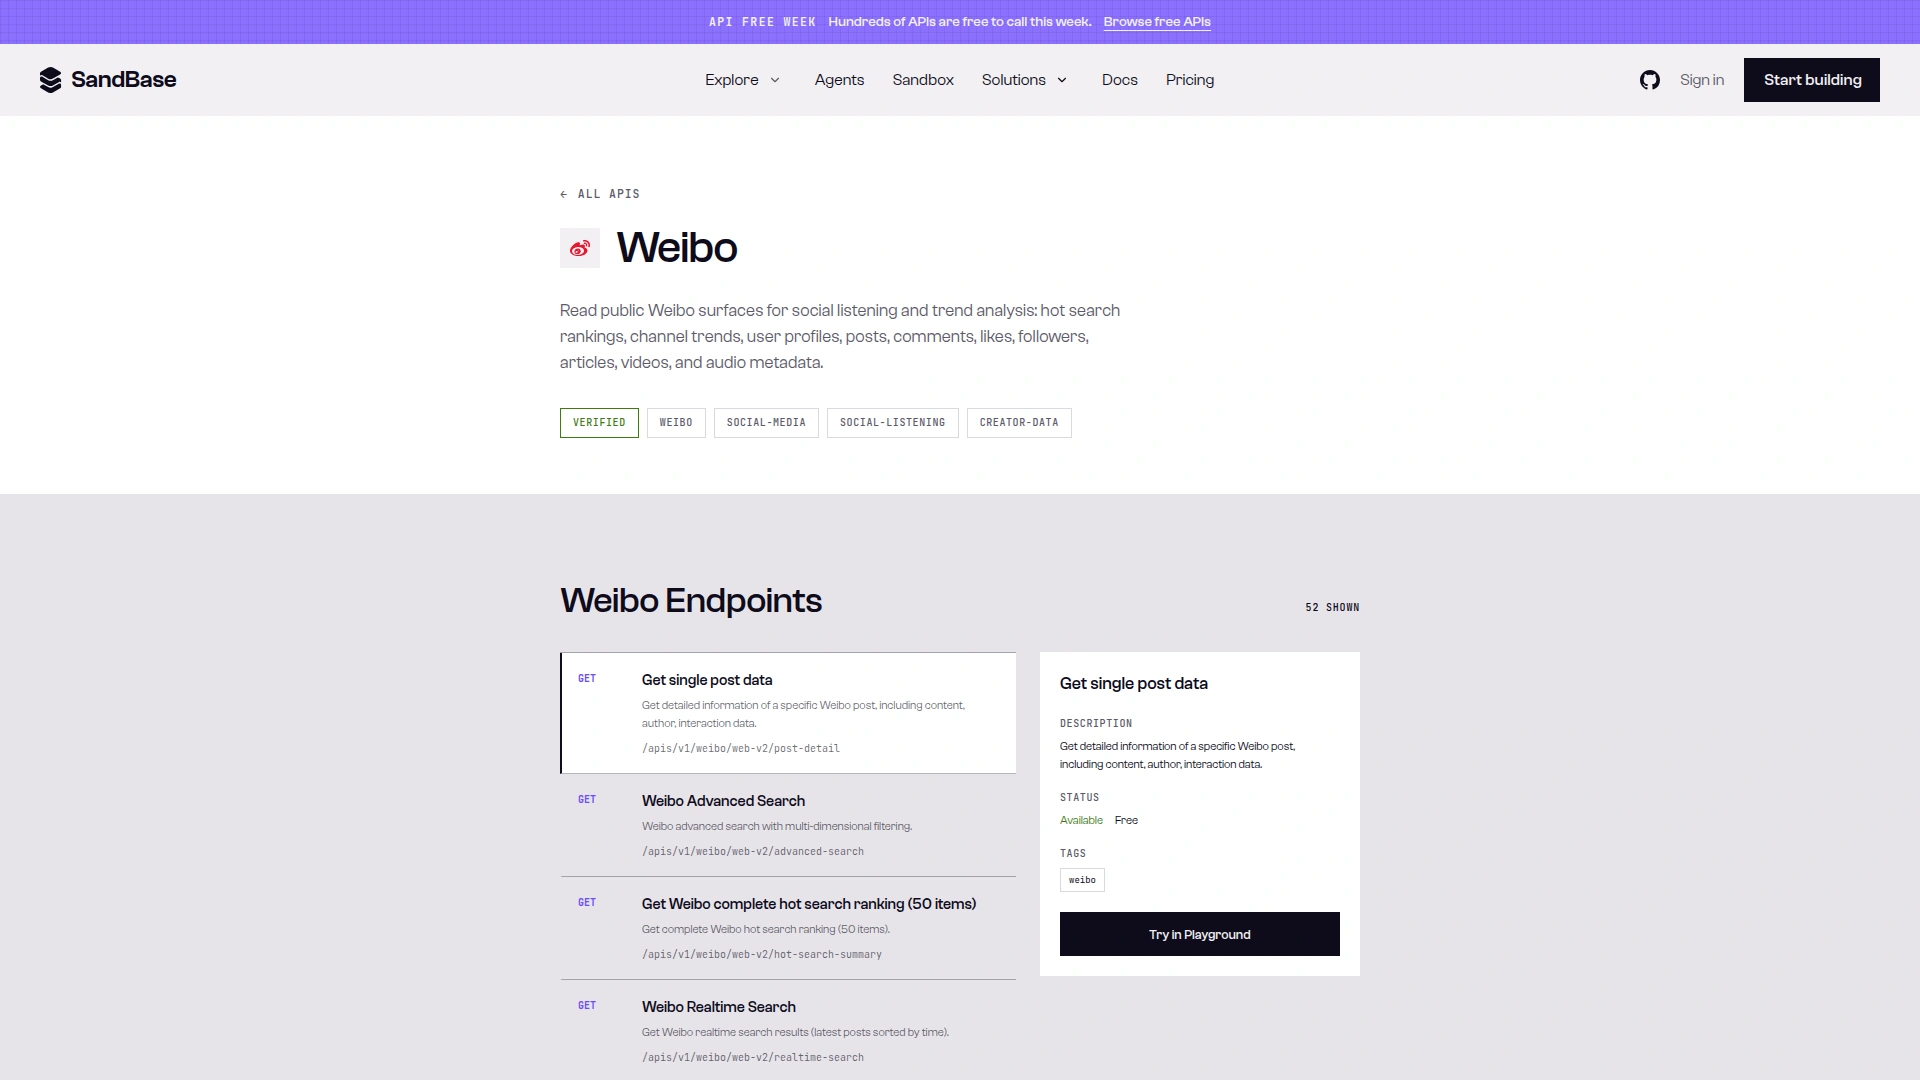
Caption: The SandBase Weibo catalog lists 52 endpoints, and the selected web-v2/post-detail card shows Available and Free (captured 2026-10-02). The Free label is from API Free Week, which has since ended; data API calls now include 100 free calls per organization per day on eligible APIs, then are billed per call.
| Channel | Endpoints | What it covers |
|---|---|---|
weibo/web-v2/* | 33 | Hot search, topic trends, public posts, user timelines |
weibo/app/* | 19 | App-level user data, relationship graphs, post details |
Older weibo/web/* endpoints are not in the catalog as of that date; use weibo/web-v2/* or weibo/app/*. The Weibo endpoints used here are billed per call at the catalog price after the 100 free daily calls.
What Weibo data enables for agents
Real-time trend detection: weibo/web-v2/hot-search takes no inputs and returns the current hot search list. In the tested call below each entry has a word and a heat number num. An agent polling every 15 minutes catches brand mentions, industry trends, or crisis signals within one cycle.
Sentiment sampling: Combine hot search detection with weibo/web-v2/realtime-search (required query, optional page, default 1) to pull recent posts for a flagged topic keyword. Feed into an LLM for sentiment classification.
Competitive positioning: Track how competitors are discussed on Weibo. weibo/app/user-timeline gives you a competitor’s official Weibo post history; weibo/web-v2/post-comments gives you public reactions.
Example: brand crisis detection workflow
The hot-search reference documents the route this workflow calls: POST /v1/api/weibo/web-v2/hot-search, with a response envelope of id, status, model and outputs[0].data.
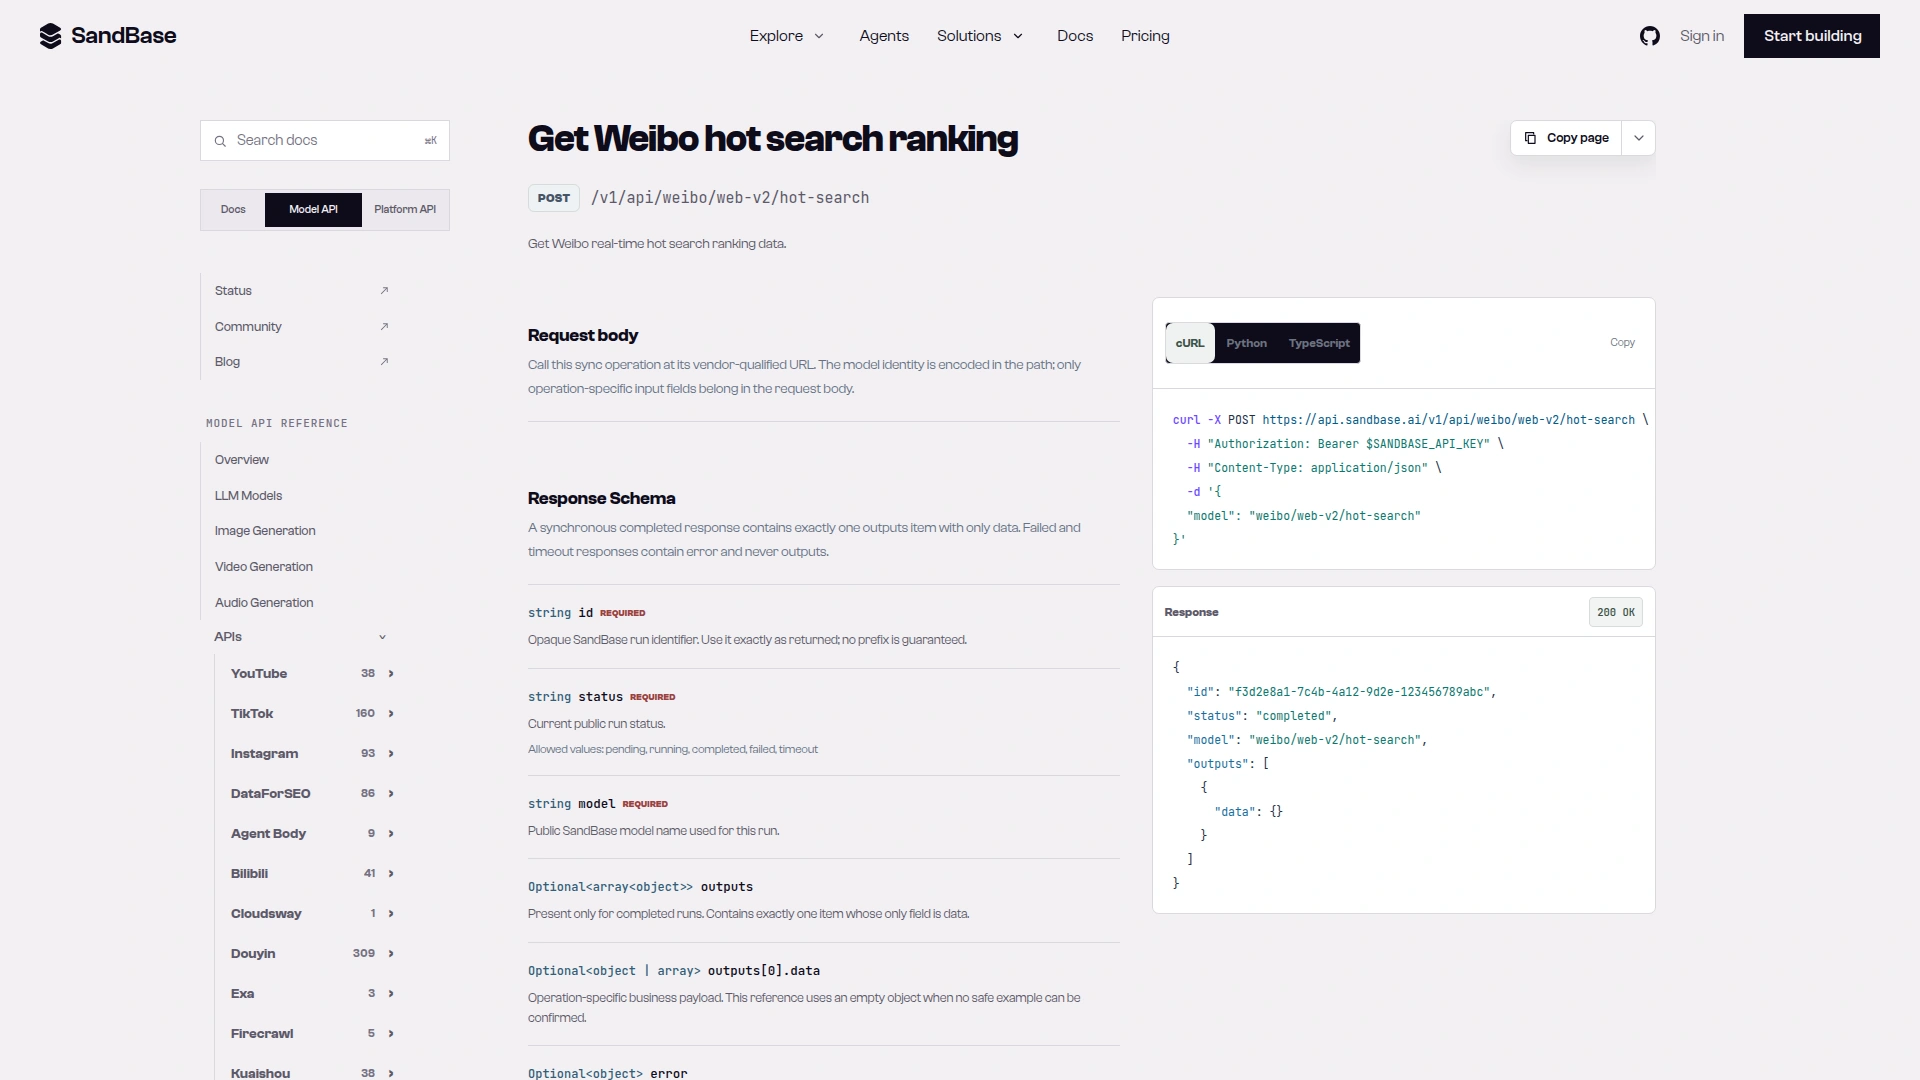
Caption: The weibo/web-v2/hot-search reference shows the POST /v1/api/weibo/web-v2/hot-search route and the outputs[0].data response envelope the code reads (captured 2026-10-02).
Endpoint references for the calls below: weibo/web-v2/hot-search, weibo/web-v2/realtime-search. The LLM step uses SandBase’s OpenAI-compatible chat endpoint.
import os
import requests
from openai import OpenAI

SANDBASE_API_KEY = os.environ["SANDBASE_API_KEY"]
HEADERS = {
    "Authorization": f"Bearer {SANDBASE_API_KEY}",
    "Content-Type": "application/json",
}

# OpenAI client for LLM calls only
client = OpenAI(base_url="https://api.sandbase.ai/v1", api_key=SANDBASE_API_KEY)


def call_sandbase(model: str, params: dict):
    """POST /v1/api/<model> with only that endpoint's params; return outputs[0].data."""
    body = requests.post(
        f"https://api.sandbase.ai/v1/api/{model}", headers=HEADERS, json=params, timeout=90
    ).json()
    outputs = body.get("outputs") or []
    if body.get("status") != "completed" or not outputs:
        raise RuntimeError(f"SandBase call did not complete: {body.get('status')} {body.get('error')}")
    return outputs[0].get("data") or {}


# Step 1: Check hot search for brand mentions
hot_search = call_sandbase("weibo/web-v2/hot-search", {})
topics = [t.get("word") for t in hot_search.get("realtime", []) or []]
flagged = [w for w in topics if w and "华为" in w]  # replace with your brand keywords

# Step 2: For each flagged topic, pull recent posts by keyword
posts = []
for word in flagged[:3]:
    result = call_sandbase("weibo/web-v2/realtime-search", {"query": word})
    for p in (result.get("parsed_data") or {}).get("results", []) or []:
        posts.append(p.get("content", ""))

# Step 3: LLM sentiment analysis (OpenAI SDK, for the LLM call only)
if posts:
    analysis = client.chat.completions.create(
        model="openai/gpt-4.1-mini",
        messages=[{
            "role": "user",
            "content": "Analyze sentiment of these Weibo posts about our brand:\n" + "\n".join(posts[:30])
        }]
    )
The LLM step uses SandBase’s OpenAI-compatible Chat Completions endpoint (guide) with openai/gpt-4.1-mini; a 2026-10-02 (UTC) test call with this request shape returned HTTP 200. Claude models use the /v1/messages protocol instead, per the LLM reference.
Tested on 2026-10-01 (UTC)
Public resources: Weibo’s public hot search list, and the brand keyword 华为 (Huawei) for realtime search. Requests:
curl -s -X POST https://api.sandbase.ai/v1/api/weibo/web-v2/hot-search \
  -H "Authorization: Bearer $SANDBASE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{}'

curl -s -X POST https://api.sandbase.ai/v1/api/weibo/web-v2/realtime-search \
  -H "Authorization: Bearer $SANDBASE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"query": "华为"}'
Trimmed real responses. Hot search (run id ae42ad80-b743-4e61-9bfc-ea373edeff6f; 51 entries in realtime, four shown, other keys removed):
{
  "status": "completed",
  "model": "weibo/web-v2/hot-search",
  "outputs": [{"data": {"realtime": [
    {"word": "鸿蒙智行问界业务升级", "num": 1106725, "rank": 0},
    {"word": "国庆假期流动的中国具象化了", "num": 618715, "rank": 2},
    {"word": "Mate90系列今日发布即开售", "num": 526587, "rank": 2},
    {"word": "央视国庆晚会", "num": 517475, "rank": 3}
  ]}}]
}
Realtime search for 华为 (run id 295b5c3f-d101-44d4-99b4-5bb914c66bff; 10 results, one shown; post text and user fields redacted because the posters are individuals):
{
  "status": "completed",
  "model": "weibo/web-v2/realtime-search",
  "outputs": [{"data": {"parsed_data": {
    "parse_success": true,
    "result_count": 10,
    "results": [
      {"content": "<post text redacted>", "interaction": {"comment_count": 0, "like_count": 0, "repost_count": 0}}
    ]
  }}}]
}
The envelope (status, model, outputs) is documented in the endpoint references. The payload field names the code reads (realtime[].word, parsed_data.results[].content) are observed-only, not documented guarantees.
Calls per cycle: 1 hot search + up to 3 keyword searches + at most 1 LLM call (only when something is flagged). Running every 15 minutes: up to 384 data calls and up to 96 LLM calls per day.
Xiaohongshu: 34 endpoints, 3 channels
Counts are what the Xiaohongshu catalog page shows as of 2026-10-01.
The Xiaohongshu catalog backs the 34 count and lists the PGY creator endpoints used later in this article.
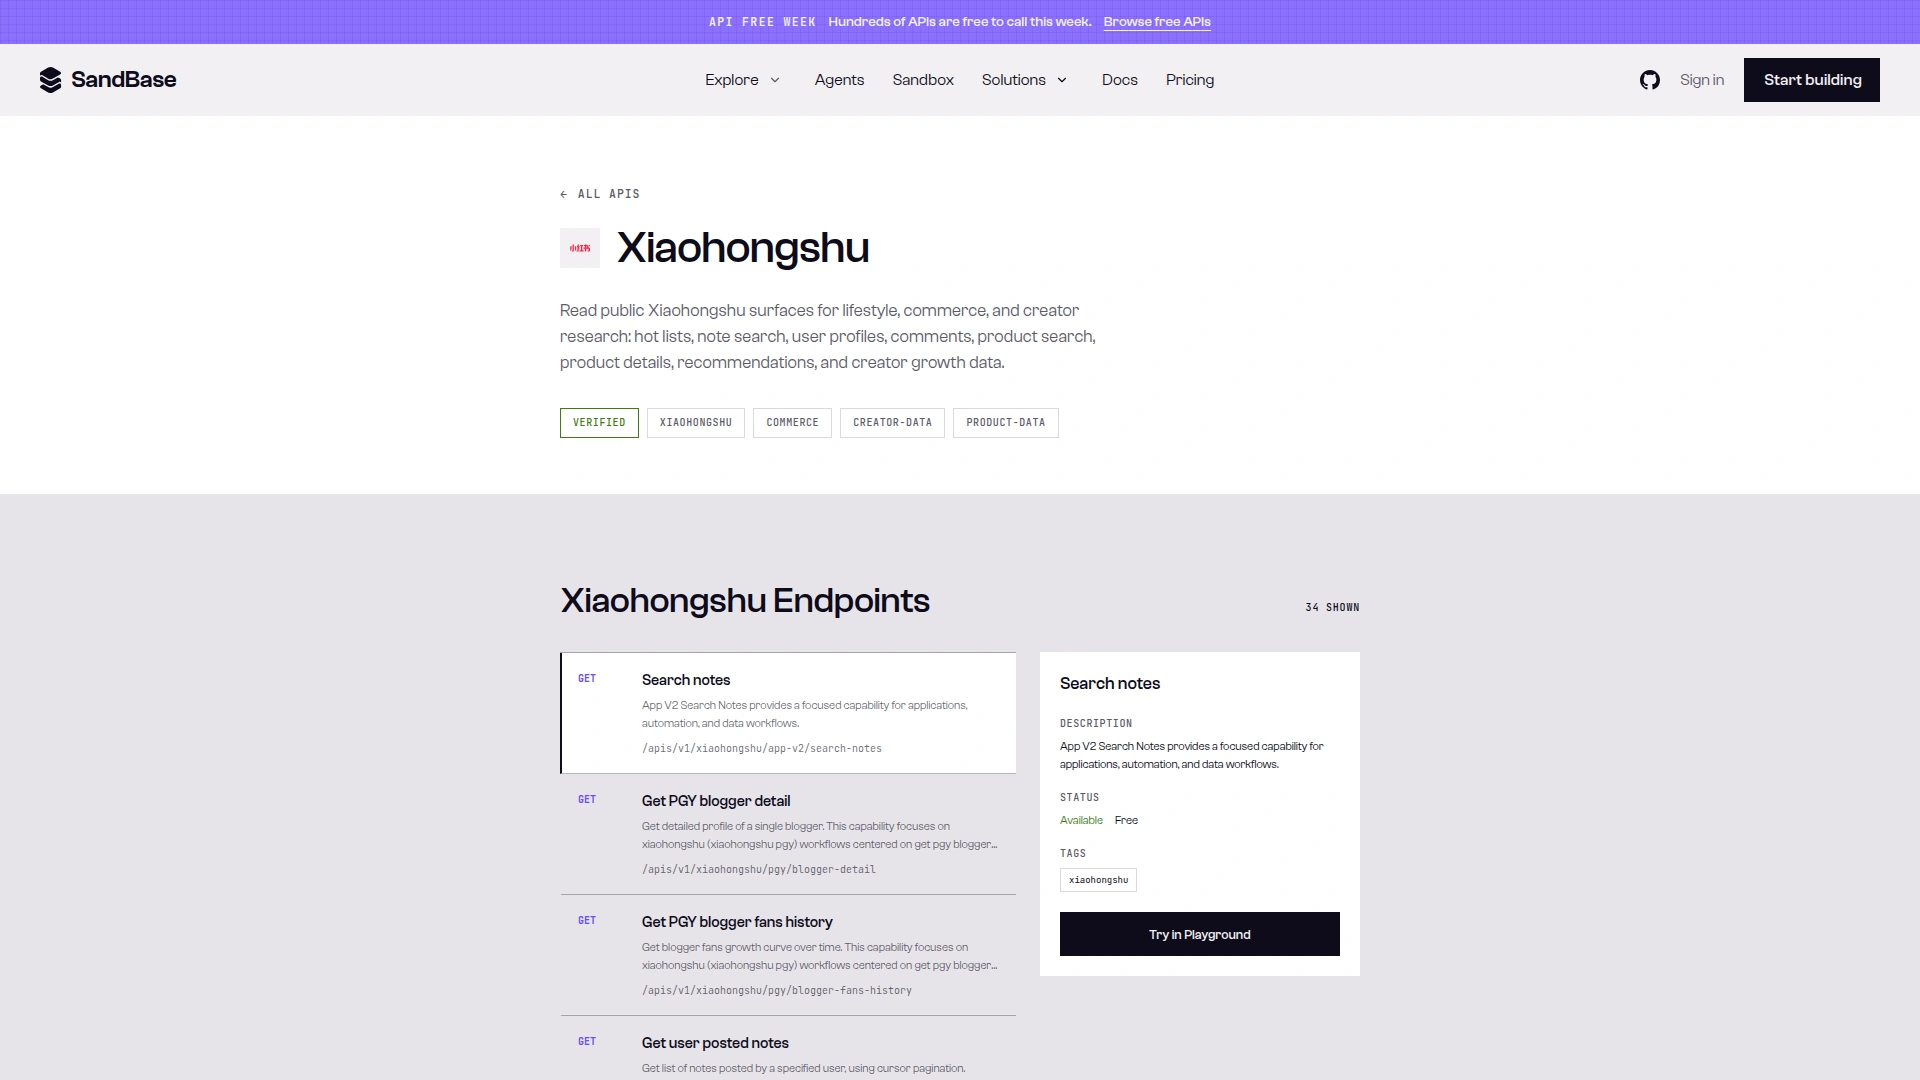
Caption: The SandBase Xiaohongshu catalog lists 34 endpoints, including pgy/blogger-detail and pgy/blogger-fans-history, with the selected card showing Available and Free (captured 2026-10-02). The Free label is from API Free Week, which has since ended; data API calls now include 100 free calls per organization per day on eligible APIs, then are billed per call.
| Channel | Endpoints | What it covers |
|---|---|---|
xiaohongshu/app-v2/* | 19 | Note details, user profiles, search, product recommendations, faved notes |
xiaohongshu/pgy/* | 10 | PGY-labelled (Pugongying) creator research: blogger lists, detail, fans history |
xiaohongshu/web-v3/* | 5 | Homepage feed, note detail, search suggestions |
The Xiaohongshu app-v2 and web-v3 endpoints used here are billed per call at the catalog price after the 100 free daily calls. The PGY-labelled xiaohongshu/pgy/* endpoints are not covered by the daily free calls; they are billed from the first call at the catalog price.
What Xiaohongshu data enables for agents
KOL screening: xiaohongshu/pgy/blogger-list requires a brand_user_id (creators are matched under that brand) and paginates with page_num (from 1) and page_size (1–100). Its reference also lists fans_number_lower / fans_number_upper, but in a dated test on 2026-10-01 those were accepted and ignored, while the nested fans.count and blogger.content_tag filters from the model page did filter; see which blogger-list filter fields work for the runs. xiaohongshu/pgy/blogger-detail and xiaohongshu/pgy/blogger-fans-history then take each creator’s user_id. Screening 200 candidates is 2 list calls at page_size 100, plus 400 detail/history calls: about 402 calls.
Content trend analysis: xiaohongshu/web-v3/homefeed (homepage recommended notes, paginated with cursor_score per its reference) is in the catalog as a trend signal; it was not tested for this article. Combine it with xiaohongshu/app-v2/search-images to find visual content patterns in your product category.
Product intelligence: xiaohongshu/app-v2/product-recommendations shows what products are being recommended alongside yours. xiaohongshu/app-v2/user-faved-notes shows what content a public profile has saved (a high-intent signal).
Example: KOL evaluation per candidate
References: blogger-detail, blogger-fans-history. The user_id below is Perfect Diary’s public brand account; swap in a userId from blogger-list.
# Creator overview
curl -s -X POST https://api.sandbase.ai/v1/api/xiaohongshu/pgy/blogger-detail \
  -H "Authorization: Bearer $SANDBASE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"user_id": "59ae4dfc5e87e72475fb3bf3"}'

# Fans trend (date_type 2 ≈ 30 days)
curl -s -X POST https://api.sandbase.ai/v1/api/xiaohongshu/pgy/blogger-fans-history \
  -H "Authorization: Bearer $SANDBASE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"user_id": "59ae4dfc5e87e72475fb3bf3", "date_type": 2}'
Tested on 2026-10-01 (UTC) with exactly these requests. Trimmed real responses (most keys removed).
blogger-detail (run id e34c2ff1-0001-45fe-acc4-e78b5a29094c):
{"code": 0, "data": {"userId": "59ae4dfc5e87e72475fb3bf3", "name": "Perfect Diary完美日记",
  "fansCount": 1835170, "likeCollectCountInfo": 7664542, "location": "广东"}}
blogger-fans-history (run id 4c229f0e-f79f-49bc-bc7d-0385ec662fbe; 60 points in list, two shown):
{"code": 0, "data": {"fansNumInc": -9214, "list": [
  {"dateKey": "2026-08-02", "num": 1842991},
  {"dateKey": "2026-09-30", "num": 1833777}
]}}
Both are outputs[0].data; the field names are observed-only. Both PGY endpoints take user_id (not blogger_id). date_type is optional; the reference allows 1–12, with 1 ≈ 7 days, 2 ≈ 30 days, 3 ≈ 90 days as the common values. In earlier runs some attempts returned an upstream 400, so build in a retry.
Calls per KOL evaluation: blogger-detail + blogger-fans-history = 2 calls. Screening 100 candidates: 1 blogger-list call at page_size 100 + 200 = 201 calls.
Cross-platform scenarios
Scenario: product launch monitoring
A consumer brand launches a new product. The agent monitors both platforms in parallel. Call volumes are an illustrative estimate, not a measurement:
| Platform | What to monitor | Endpoints | Calls/day (illustrative) |
|---|---|---|---|
| Brand mentions in hot search, post sentiment | hot-search + realtime-search | ~100 | |
| Xiaohongshu | Product-related notes, competitor recommendations | xiaohongshu/app-v2/search-notes + xiaohongshu/app-v2/product-recommendations | ~50 |
| Total | ~150 calls/day (~4,500/month) |
Scenario: influencer campaign performance
After a KOL campaign launch, track performance:
| Metric | Weibo endpoint | Xiaohongshu endpoint |
|---|---|---|
| Post engagement | weibo/web-v2/post-comments | xiaohongshu/app-v2/image-note-detail / video-note-detail |
| Audience reaction | weibo/app/status-reposts | xiaohongshu/app-v2/note-comments |
| Creator growth | weibo/app/user-info | xiaohongshu/pgy/blogger-fans-history |
SandBase vs the official platform APIs
Neither platform offers a general unauthenticated public-data API for arbitrary data. Their official developer programs are for authorized, account-linked workflows. A rough split:
| Need | SandBase public-data endpoints | Official platform API / OAuth |
|---|---|---|
| Public read data (hot search, public posts, public notes) | Yes | Depends on program and approval |
| Publishing, comments, DMs, account actions | No | Possibly, with account authorization; varies by platform* |
| Private or owner-only analytics | No | Possibly, for your own authorized account; varies by platform* |
| Authentication | One SandBase API key | Platform app credentials; user authorization (OAuth on Weibo) for account data |
| Good fit | Research, monitoring, creator discovery | Managing your own accounts |
* Which of these the official programs actually offer differs between Weibo and Xiaohongshu and depends on the approved product, granted scopes and account type. Check each platform’s developer documentation before planning around a specific capability.
What SandBase adds
- One contract: every Weibo and Xiaohongshu Model API call in this article is made the same way,
POST /v1/api/<model>with only that endpoint’s parameters, and the result is read fromoutputs[0].data - One key: the same SandBase API key covers both platforms and the LLM step
- Cross-platform composition: a single workflow can call Weibo hot search → Xiaohongshu search → LLM analysis without switching APIs or auth methods
Limitations
- Weibo: The endpoints are read-only. No posting, no direct messaging. Write operations need Weibo’s official API with OAuth.
- Xiaohongshu: The endpoints cover public analytics and content discovery, not account management. The PGY-labelled endpoints return creator-research data through SandBase’s public-data catalog; they aren’t a view into any brand’s own PGY account.
- Both: Public data access through third-party infrastructure, not official platform authorization. Data freshness varies: hot search is near-real-time, historical analytics may lag.
FAQ
How does Weibo data pricing compare to Douyin?
Once your organization’s 100 free data API calls for the day are used, the Weibo and non-PGY Xiaohongshu endpoints used in this article are billed per call. The Xiaohongshu PGY endpoints are not covered by the daily free calls and are billed from the first call at the catalog price (sandbase_inspect shows an endpoint’s free_quota, sandbase_account shows today’s remaining free calls). Check each endpoint’s catalog page, or run sandbase inspect, for the current price before you build.
What can I learn from Xiaohongshu PGY-labelled data?
In the tested calls above: a creator’s follower count (fansCount), combined likes and saves (likeCollectCountInfo), location, and a daily follower series (list[].dateKey / num) with the net change (fansNumInc). These are observed field names, not documented guarantees.
Can I track a specific Xiaohongshu note’s performance over time?
Yes. Call xiaohongshu/app-v2/image-note-detail (or video-note-detail for video notes) with note_id (or share_text) periodically. On 2026-10-01 I called it for a Perfect Diary note, {"note_id": "6abcdadd0000000002012523"} (run id ac60ce27-9c88-4c42-a5e1-ee30aae1300e). The counts sat at data[0].note_list[0] (observed-only):
{"id": "6abcdadd0000000002012523", "liked_count": 19, "comments_count": 2, "collected_count": 2, "shared_count": 1}Tracking 50 notes daily is 50 calls/day.
Is there overlap between Weibo and Douyin coverage?
Minimal. They serve different platforms with different user behaviors. Weibo is text + opinion-first (trending topics, comments, reposts). Douyin is video-first (creators, engagement metrics, commerce). Most monitoring agents use both.
Next steps
- Get a SandBase API key (authentication docs)
- Browse Weibo APIs · Browse Xiaohongshu APIs
- Open the references used here:
weibo/web-v2/hot-search,weibo/web-v2/realtime-search,xiaohongshu/pgy/blogger-detail
For the complete picture of social media data options, see our social media data API guide. For Douyin-specific coverage, see Douyin Public Data API.