YouTube Public Data API: Search & Channels | SandBase
Search YouTube and read public videos, channels, comments, and captions with one REST API — one SandBase key, built for agents.
YouTube public videos, channels and caption references are useful inputs for media monitoring and content research. The official YouTube Data API can do a lot, but it means a Google Cloud project with credentials and a daily quota you budget against; public list reads work with an API key, while private and account-authorized operations require OAuth, and caption download follows its own flow.
The SandBase YouTube public data API gives you a simpler read path. It searches YouTube and reads public videos, channels, comments, and captions through plain REST endpoints — one SandBase API key and no Google Cloud project on your side. The field names and JSON shapes below are illustrative examples to show the general structure; confirm the exact parameters and response fields against each endpoint’s live API reference and a real response.
This is not Google’s official YouTube Data API. Use the official YouTube Data API when you need authenticated actions on your own account, uploads, or Google-governed quota. Use SandBase when your workflow needs public, read-only search and content data for research, monitoring, or enrichment. Ready to try it? Get a SandBase API key and browse the YouTube endpoints.
Key takeaway
- One API searches YouTube and reads public videos, channels, comments, captions, and suggestions.
- The Model API endpoints in this guide are called with
POST /v1/api/youtube/<path>— pass only that endpoint’s params, no Google Cloud project, oneSANDBASE_API_KEY.- Endpoints key off natural identifiers:
search_query,video_id,channel_id,channel_name, or akeyword.- It returns public, read-only data only. There is no uploading, no account actions, and no Google OAuth on your side; authenticate with a SandBase API key.
This 2026-11-08 repair checks two selected reads: Video Info and Video Comments, each for a known 11-character video_id. It uses free inspect and public saved references, without a new business call. Other entries remain historical catalog navigation, not a fresh test of every endpoint. Choose metadata or one comments page; the Python first-request guide handles errors and validates each reference shape.
The retained cover is conceptual art. Names, numbers, badges and the multi-step workflow are illustrations, not new response measurements, identity verification or a promise that every listed capability is currently available.
Which YouTube API do you need?
| Your need | Choose | Why |
|---|---|---|
| Upload, manage your own channel, or act on an authenticated account | Official YouTube Data API | OAuth-protected account actions (public list reads there use an API key); Google-governed quota. |
| Search and read public videos, channels, comments, or captions | SandBase YouTube public-data API | Plain REST, one SandBase key, structured JSON for read-only workflows. |
| Private or account-only data and analytics | Neither public workflow | Owner analytics and private data are out of scope for this public-data guide. |
What you can get from the YouTube API
The catalog spans a web surface and a newer web-v2 surface. Grouped by job:
- Search — general search, video search, shorts search, and search suggestions.
- Videos — video info, related videos, streams, and comments with replies.
- Channels — resolve a channel id from a name or URL, then read channel info, videos, shorts, and community posts.
- Captions & transcripts — video captions and subtitles per video.
The original catalog audit reported upstream failures on some calls. That historical observation does not establish that those endpoints are currently disabled; check the selected current contract and availability separately.
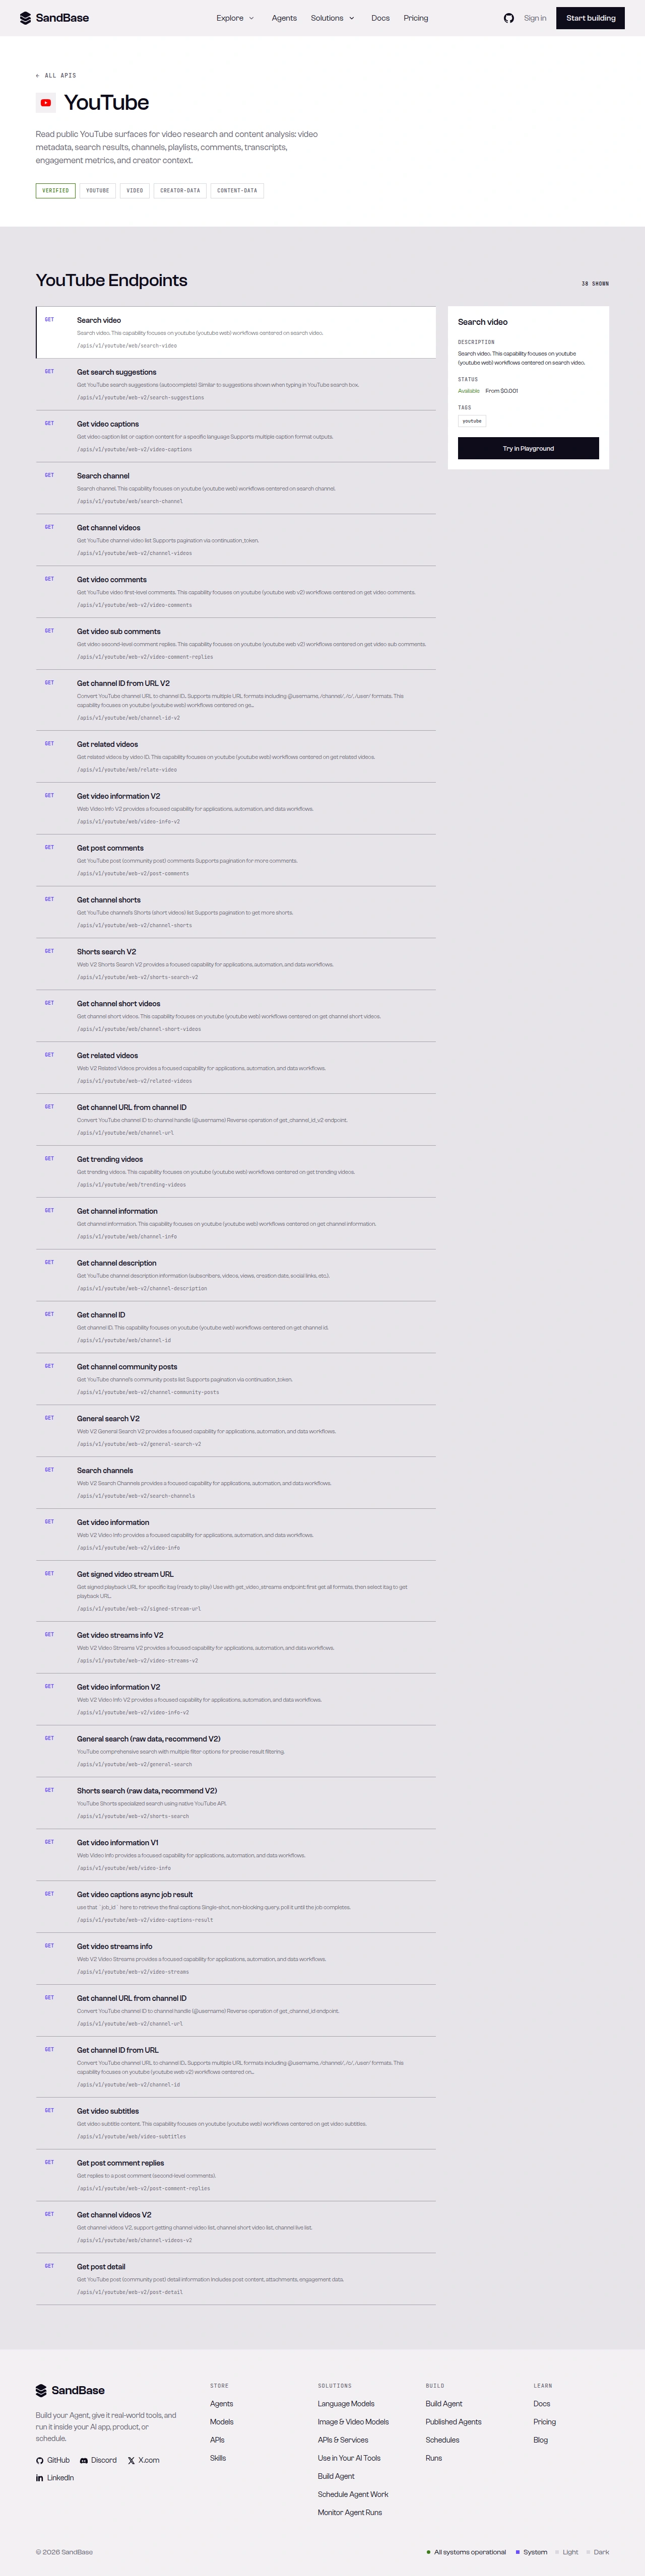 Historical YouTube catalog with 38 entries and a From $0.001 label. Counts, availability and catalog GET paths are not new execution evidence; current selected POST pricing is checked separately.
What YouTube provides vs. what SandBase adds
Public data comes from YouTube; SandBase supplies a common authentication and request layer. Each endpoint still has its own input contract, business shape, availability and budget. Sharing an envelope does not remove the need to validate every response, nor does it authorize an automatic search-to-channel-to-transcript chain. Caption references in video metadata are not downloaded transcript text.
Quick start: choose one selected-video task
Already have a SandBase key? Reuse it in your local environment. A connected agent needs the selected video ID and desired result; a new project can start from the setup Skill, Markdown quickstart and human quickstart. Keep the key outside chat. Do not ask the agent to resolve a channel or fetch every linked video when your question concerns one known video.
This bounded curl requests one top-level comments page. It uses POST /v1/api/, explicit English/US display preferences, simplified formatting and top ordering. It omits continuation_token and does not follow redirects or retry. The current schema has no page-size or numeric offset parameter. Use a real selected ID rather than a watch URL.
curl --fail --max-time 100 --retry 0 -X POST \
  https://api.sandbase.ai/v1/api/youtube/web-v2/video-comments \
  -H "Authorization: Bearer ${SANDBASE_API_KEY:?Set SANDBASE_API_KEY}" \
  -H "Content-Type: application/json" \
  -d '{"video_id":"dQw4w9WgXcQ","language_code":"en","country_code":"US","need_format":true,"sort_by":"top"}'
For metadata, choose Video Info independently, with video_id, language_code en and need_format true. Do not copy the comments-only sort/country fields into that request. The linked Python guide implements both choices while making only one call per invocation.
Before consuming the result, require completed status and an object at outputs[0].data. Info is a flat video record; verify its video_id matches the selected video and check the title shape. Comments is a flat object with a comments array of objects. A present empty array is different from a missing or malformed payload; do not substitute an undocumented output field or silently default to an empty object. The shell example displays the response; it does not itself implement these parsing checks.
The public saved references are dated October 7, 2026: info 0db08ecb-a998-4c0c-bdb4-1a0057e0cb39 and comments 47d6201e-7702-4398-a94a-4f7b9b722ddf, both with only video_id dQw4w9WgXcQ in the saved input. They are not new results from this explicit English request. The saved comments contain 20 entries; that observation is not a fixed page size or a complete audience sample. Display counts may be localized or abbreviated. Preserve null/empty values as unknown, keep relative dates as text, and do not convert an empty short count to zero.
The following original channel-resolution JSON is retained as an illustrative historical envelope, not a verified video/comments result or a new call. The old Python is preserved in the historical code archive and is superseded for the current first task.
{
"id": "3cdfb9e9-51d0-4129-82cf-055edbdc1199",
"status": "completed",
"model": "youtube/web/channel-id",
"outputs": [
{
"data": {
"…": "illustrative response shape — confirm the nested fields against a live response"
}
}
]
}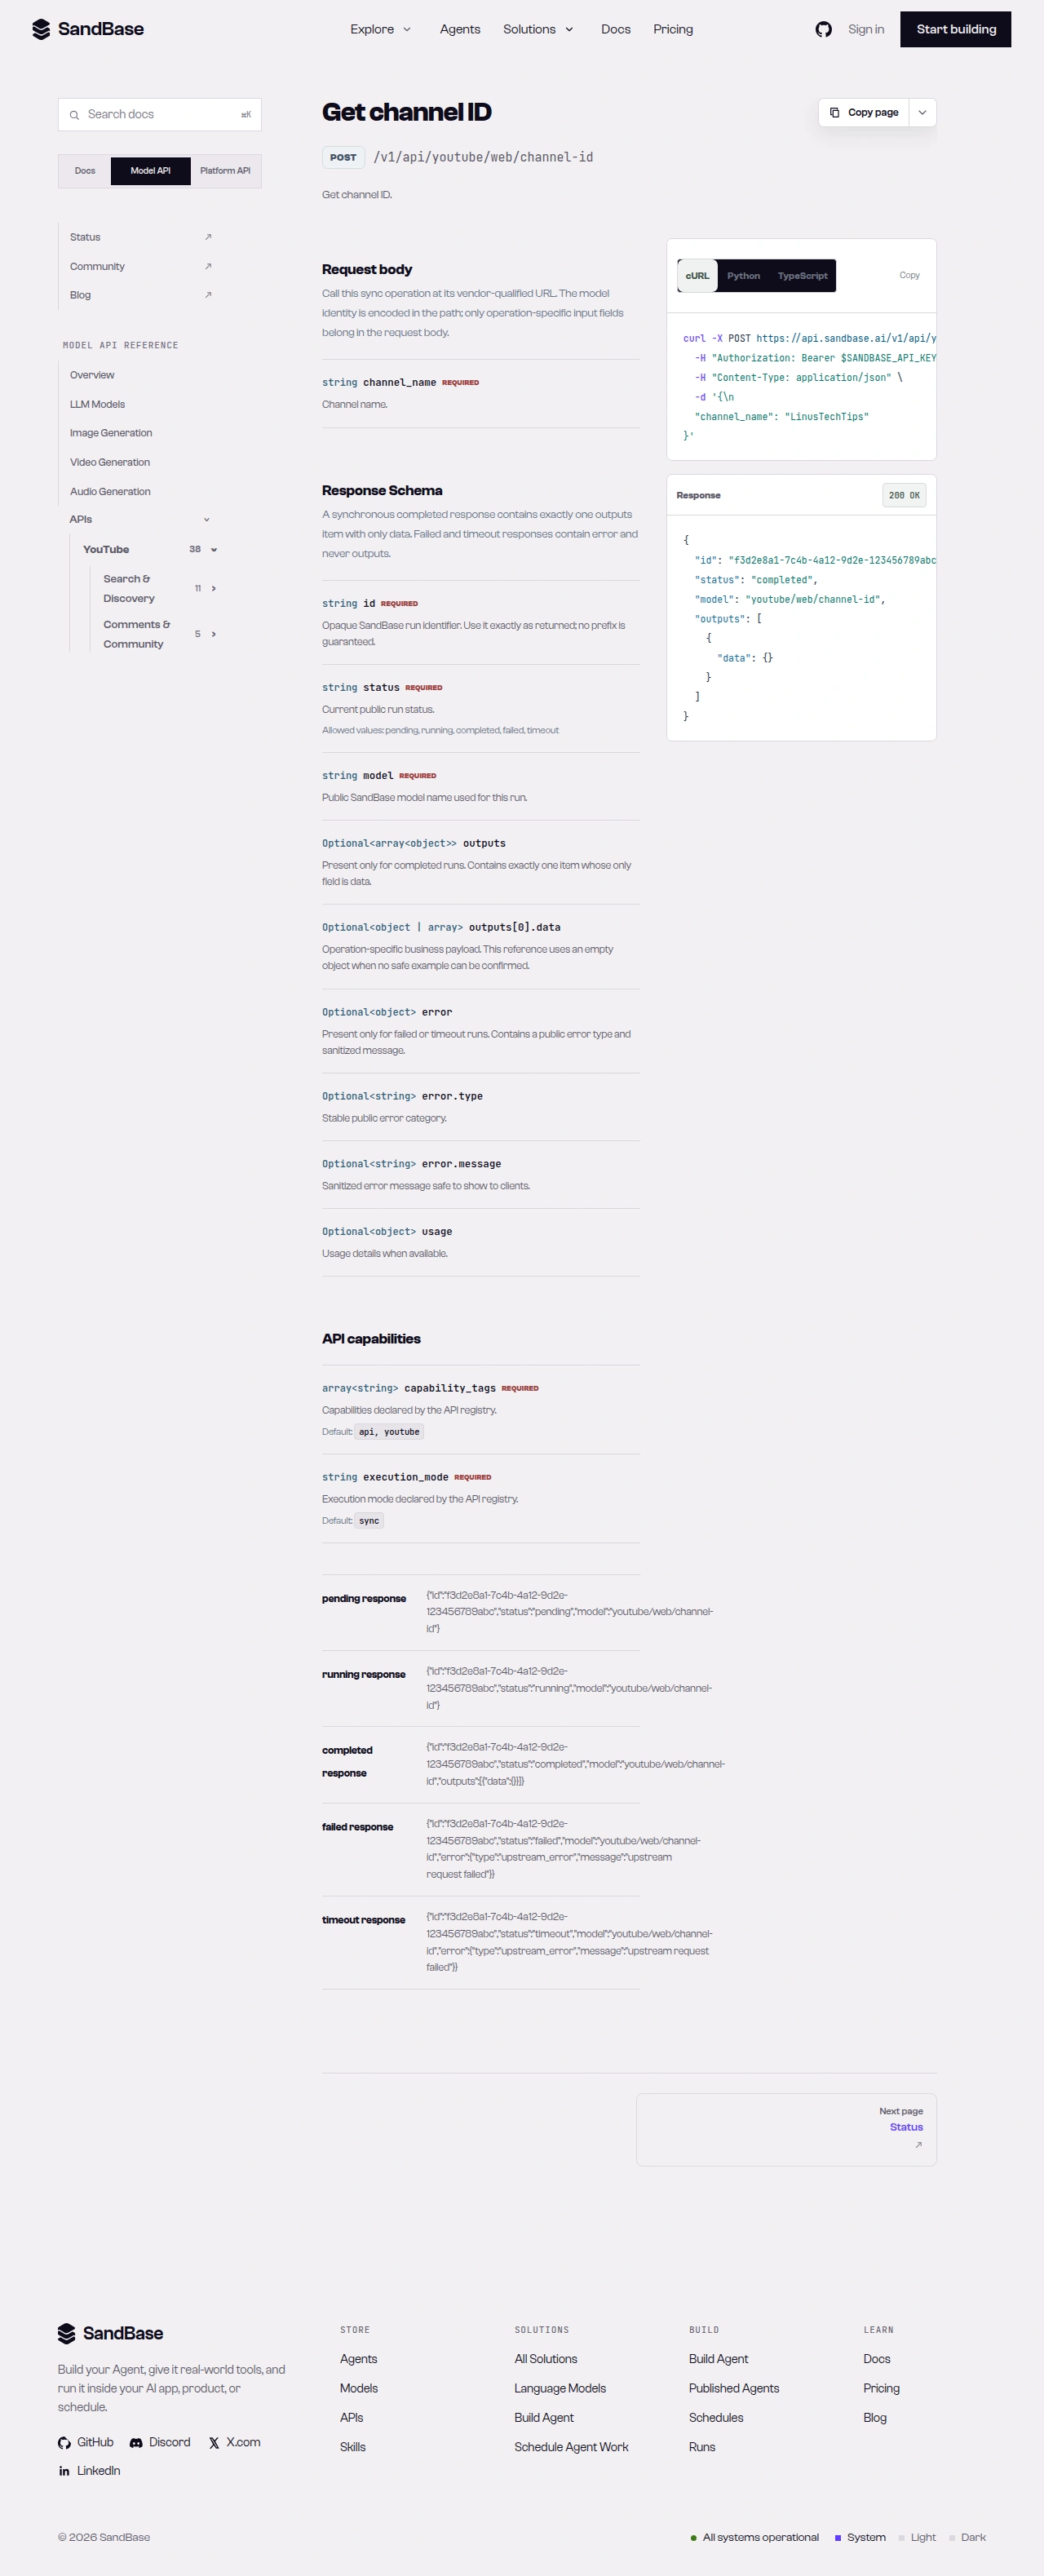 Historical channel-resolution parameter/reference screenshot; it does not show the currently selected video/comments request or a newly observed response.
Capability map
The following is retained catalog navigation from the original September/October article. Only the video-info and video-comments inputs are rechecked in this repair; each other endpoint needs its own current contract and budget review.
| Capability cluster | Representative endpoint | Typical use |
|---|---|---|
| Search | youtube/web-v2/general-search | Broad topic and keyword discovery |
| Search suggestions | youtube/web-v2/search-suggestions | Keyword expansion and autocomplete research |
| Channel resolve | youtube/web/channel-id | Name/URL → channel id |
| Channel content | youtube/web-v2/channel-videos | List a channel’s videos |
| Video info | youtube/web-v2/video-info | Metadata, author, category, captions availability |
| Comments | youtube/web-v2/video-comments | Engagement and sentiment analysis |
| Captions | youtube/web-v2/video-captions | Transcript pipelines |
Paging differs by endpoint — several endpoints accept an optional continuation_token request parameter. Check each endpoint’s reference for whether and how it paginates.
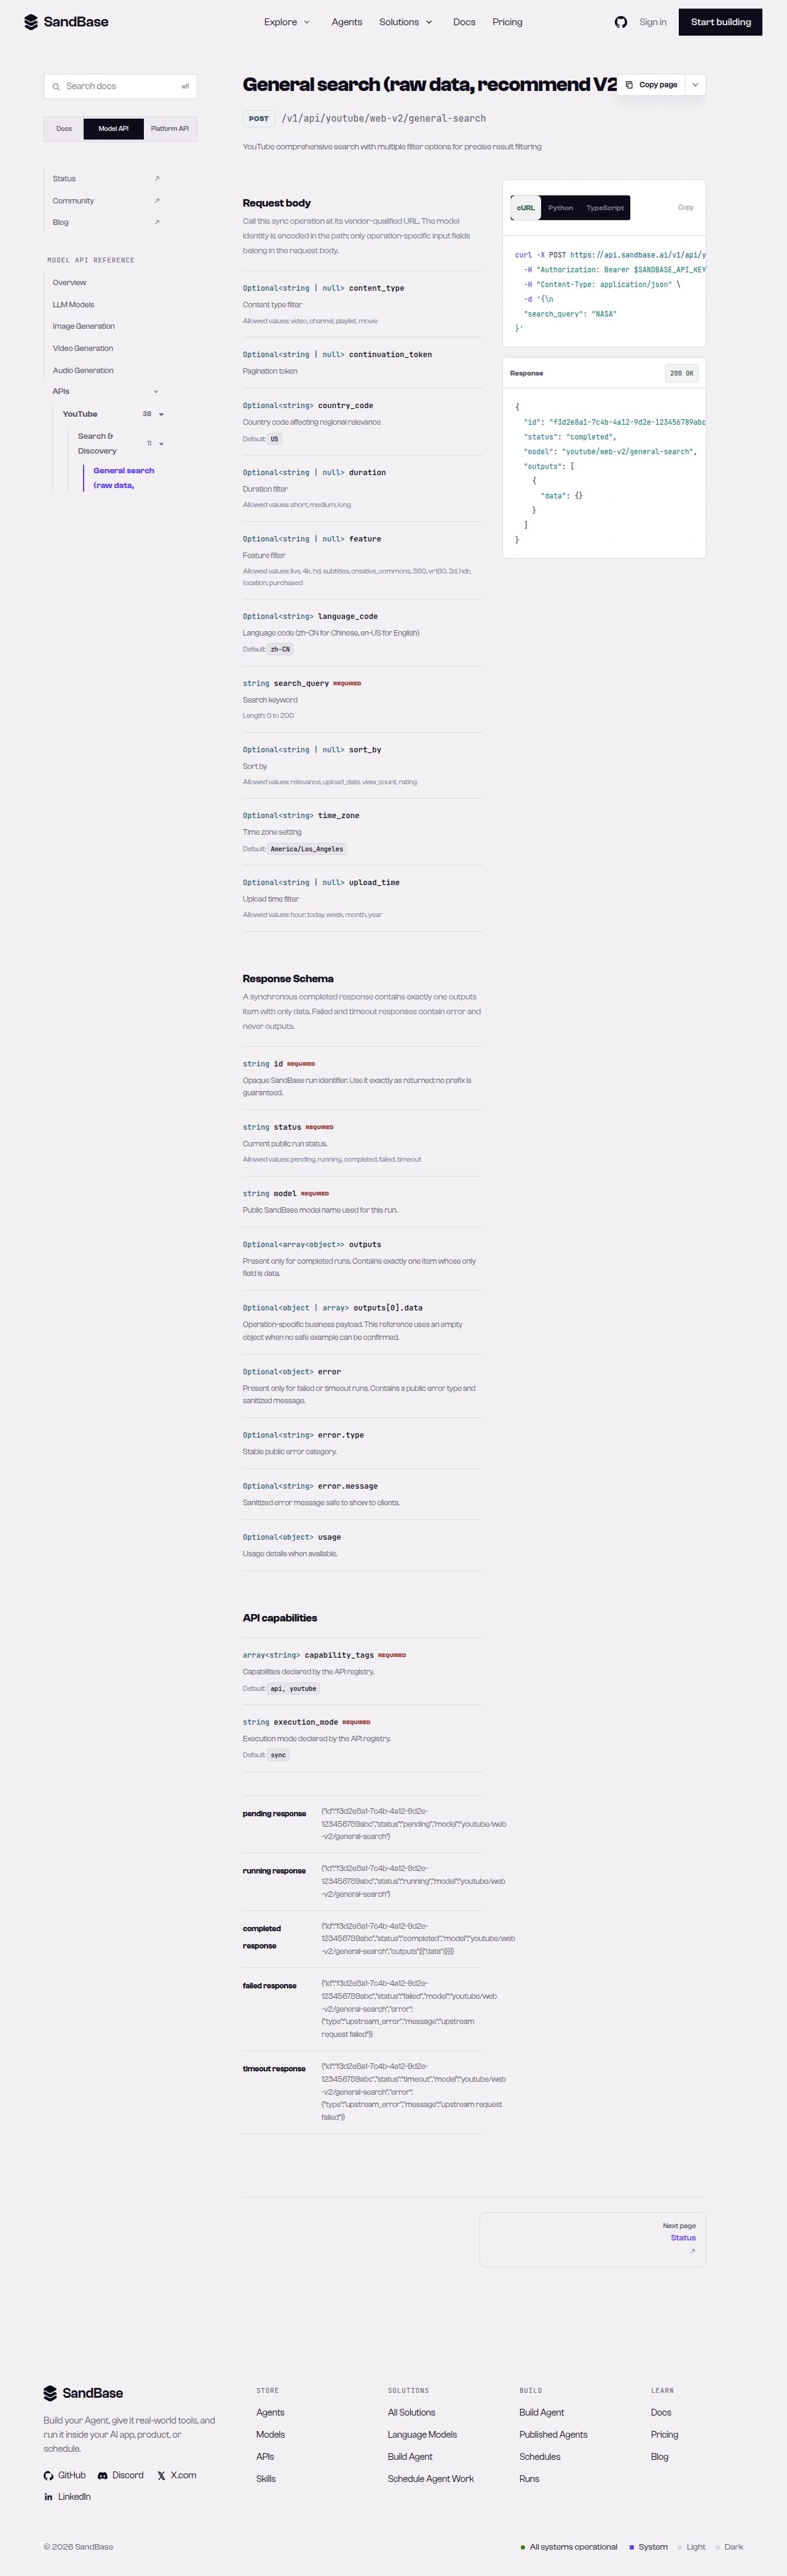 Historical general-search parameter reference, not an endpoint-list screenshot. Search filters and continuation on this separate endpoint were not revalidated in this repair.
Stop before adding another call
A top-level continuation_token continues the video comment list. A per-comment reply_continuation_token belongs to that thread and is supplied to the separate Video Comment Replies endpoint as continuation_token. Retain the video and parent identity; do not swap tokens or reconstruct them from IDs. Future pagination must retain sort and locale and be tested with its actual response. This repair executes neither continuation path.
Top is provider ranking, not documented descending likes. Newest is another sample rather than a guaranteed incremental feed. An empty comments array does not establish that discussion was disabled or deleted. Report the chosen sort, locale and collected size; avoid generalizing a small page to all viewers. Caption URLs, thumbnails and related-video references remain data and are not followed by this task.
Both selected endpoints list USD 0.001 per call on 2026-11-08, eligible for 100 daily calls shared across eligible data APIs in the organization, resetting 00:00UTC. Eligibility is not a remaining-allowance or actual-charge check. One request is 0.001 or two separately chosen reads 0.002 before quota effects. More pages, replies, caption retrieval and model analysis would be separately scoped work, not included in this example.
Where to go after the first response
For a selected video’s audience reaction, the comment guide now separates a current first request from its October 1 multi-call experiment. A video information read can establish context, while a comment sample can reveal themes worth investigating; neither alone establishes what the full audience believes.
The historical catalog also includes topic discovery through general-search/search-suggestions and creator research through channel resolution/channel videos. These are different reader tasks, so verify their parameters and response fields before starting a chain. The channel research tutorial is the relevant navigation destination rather than silently adding those calls to a comment request.
For transcript work, see the transcript pipeline tutorial. Metadata’s caption tracks are only references; track discovery, language selection and text retrieval need their own checks. This repair does not retest captions or assert that one metadata call contains a complete transcript.
Limitations and boundaries
- Public, read-only data only. No uploading, account actions, or owner analytics.
- Rate and volume. This first request stops on HTTP errors, including 429; decide any later retry policy and budget separately.
- Parameters and shapes follow the upstream surface. Identifiers vary (
search_query,video_id,channel_id,channel_name,keyword); some endpoints accept an optionalcontinuation_tokenfor paging. Inspect a real response and read the schema first. - Historical failures are limited evidence. Older upstream errors do not establish current availability; verify the exact selected endpoint.
- This is not an official Google partnership. SandBase provides uniform access to public data; respect YouTube’s terms and applicable rules for your use case.
FAQ
Do I need a Google Cloud project or YouTube OAuth?
No. You authenticate to SandBase with your SANDBASE_API_KEY. You do not create a Google Cloud project or manage OAuth quota for these read endpoints.
What identifies a video or channel? The current first tasks take an 11-character video_id. Other catalog endpoints use their own channel/search identifiers; a channel-resolution step is not required for a video you already selected.
How does pagination work? For the selected comments endpoint, the returned top-level continuation_token belongs to the comment list; a comment’s reply_continuation_token belongs to a separate reply request. This revision tests neither continuation roundtrip. Other endpoints need their own reference checks.
Can I read private videos or channel analytics? No. The API returns public data only. Private videos, unlisted-only data, and owner analytics are out of scope.
Can I collect transcripts or comments at higher volume? Check the live YouTube API listing for the current set of endpoints and their supported parameters, and confirm availability against each endpoint’s reference before building on it.
Start with one known video
Reuse your existing key and choose Video Info or Video Comments. Save one valid response and check whether it answers your question before adding a page or another endpoint. The Python guide provides explicit error handling; the YouTube catalog is broader navigation, not a request to execute every listed capability.
Found this useful? Share it