YouTube Channel Research API Tutorial | SandBase
Read one YouTube channel profile or upload page with Python. Validate channel identity, preserve localized counts, and separate advanced-info and pagination tokens.
A channel profile and a page of uploads answer different research questions. The profile can help confirm who you selected and which public display metrics are available. An upload page shows a sample of that channel’s videos. Neither is a growth report, and you do not need to search a topic or visit every video before reading one known channel.
This 2026-11-08 repair starts from a selected channel_id and offers two independent requests: Channel Description or Channel Videos. It checks current free inspect and public saved references, without a new business call. The original 2026-09-28 UTC search-to-channel experiment remains clearly dated below; its older web routes are not silently substituted for the current web-v2 choices.
Key takeaway
- Send channel_id for the first profile read, even though that schema also supports a later token-based request and marks fields optional.
- Choose profile or uploads once; validate completed status and outputs[0].data, then check the returned channel identity.
- Keep localized counts and null values unchanged. One snapshot cannot measure growth, and a business-email flag is not an email address.
- Channel Description’s advanced-info token and Channel Videos’ page token have different purposes. Neither continuation is executed here.
The retained cover illustrates the original search-to-profile idea. Its channel name, verification badge, display figures, growth chart and agent chain are conceptual, not verified identity, a measured growth series or a workflow automatically executed by this revision.
Pick the task before the endpoint
| What you need now | Current destination | Selected first input |
|---|---|---|
| Public identity and available profile metrics | Channel Description | channel_id, language_code en, country_code US, need_format true |
| One returned page of uploads | Channel Videos | same selected channel and locale; omit continuation_token |
A display name, @handle and channel URL are not interchangeable with channel_id. If you do not yet have an ID, resolve it as a separate task using the appropriate current reference. The example does not guess a channel from a search result or automatically choose the first matching creator. That selection changes the meaning of the research and should remain visible.
The YouTube API hub is broader navigation. For reactions under a video you already selected, use the comments first-request tutorial. Short-form discovery is covered separately in the Shorts tutorial; an uploads page here is not a promised Shorts inventory.
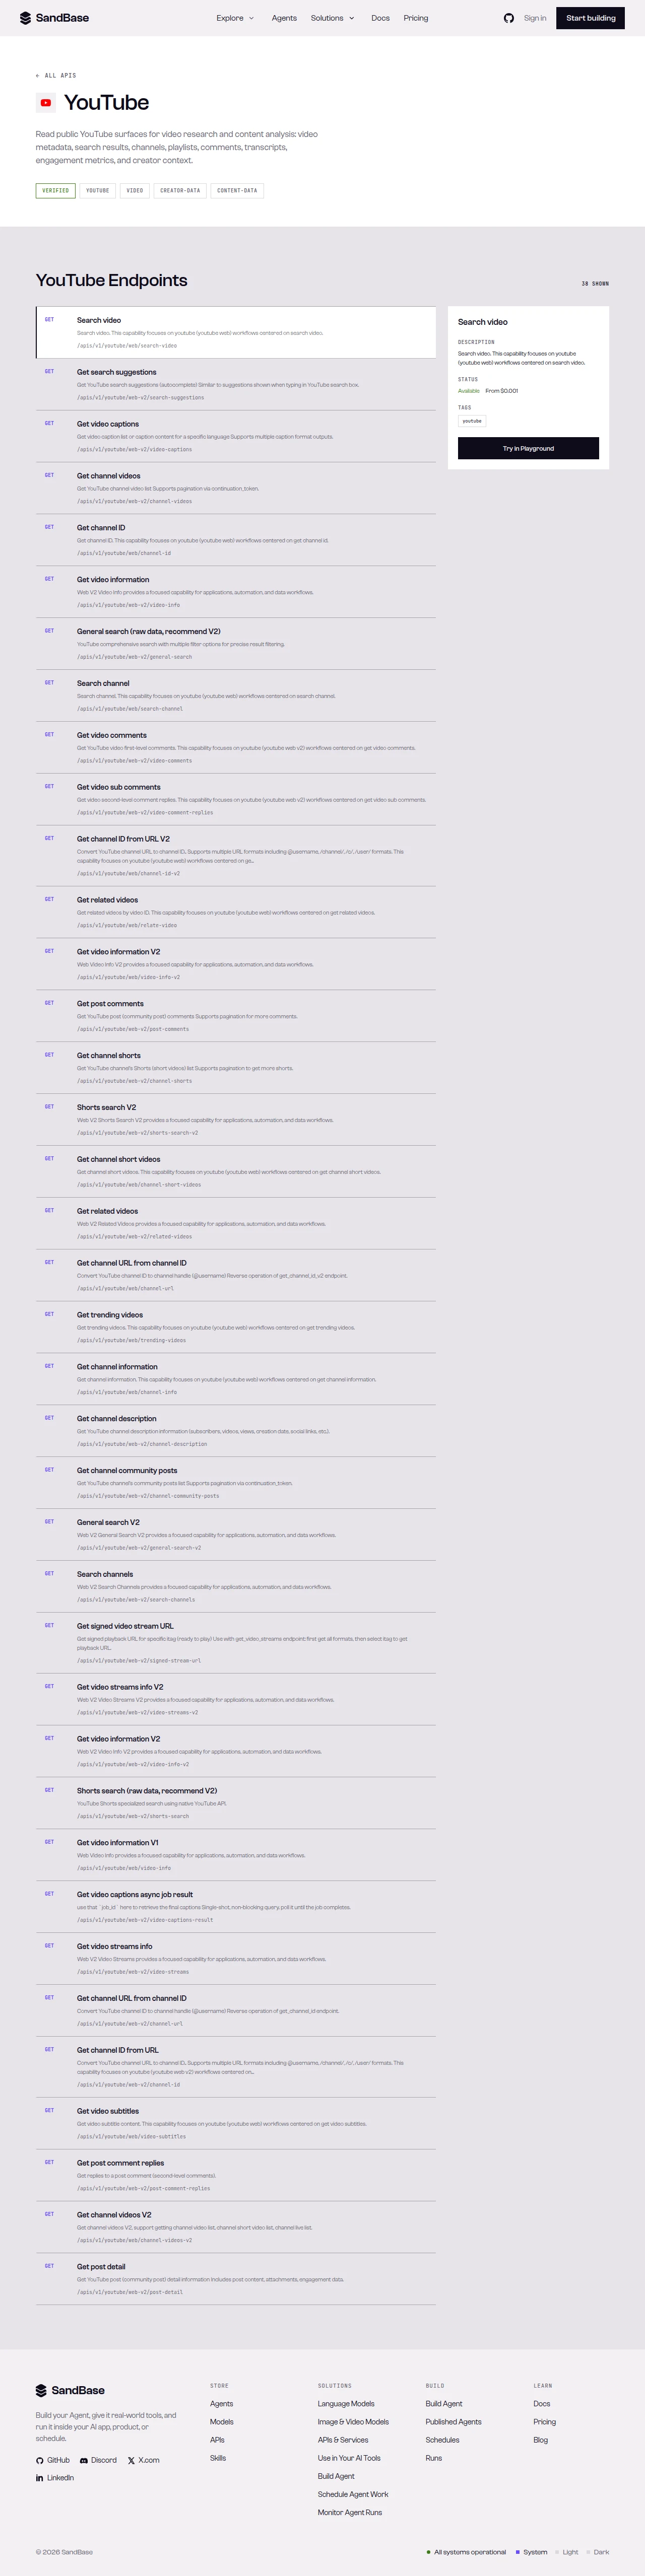 Historical YouTube catalog retained from the original article. Its 38-entry count, From $0.001 label and search-video/channel-info navigation are historical; they are not a fresh availability check for the two selected web-v2 requests.
Setup for an existing key or a new project
If your project already has SANDBASE_API_KEY, reuse its environment or secret-manager configuration. A connected agent only needs the channel ID, selected task and desired output. Do not paste a key into chat or ask it to create another account before a read it is already configured to make.
For a new integration, share the setup Skill, Markdown quickstart and the chosen endpoint. The human quickstart explains account setup. A useful instruction is: “Read one profile record for this channel. Preserve raw counts and unknown values, verify the returned ID, and stop after one response. Do not contact the creator or follow links.” Choose an upload page instead when that is the actual question.
Install requests in your Python environment. This helper uses a local UC-plus-22-characters guard to reject names, URLs and obvious ID mistakes. The registry describes channel_id as a string rather than declaring this exact regular expression; the guard is an explicit local first-request restriction, not an additional upstream schema claim.
import os
import re
import requests

API = "https://api.sandbase.ai/v1/api/youtube/web-v2"


def first_request(task, channel_id):
    if task not in ("profile", "uploads"):
        raise ValueError("Choose profile or uploads")
    if not isinstance(channel_id, str) or not re.fullmatch(r"UC[A-Za-z0-9_-]{22}", channel_id):
        raise ValueError("Provide a selected UC channel ID, not a name, handle or URL")
    payload = {"channel_id": channel_id, "language_code": "en",
               "country_code": "US", "need_format": True}
    route = "channel-description" if task == "profile" else "channel-videos"
    key = os.environ.get("SANDBASE_API_KEY", "").strip()
    if not key:
        raise ValueError("Set SANDBASE_API_KEY in your environment")
    try:
        response = requests.post(
            f"{API}/{route}",
            headers={"Authorization": f"Bearer {key}", "Content-Type": "application/json"},
            json=payload, timeout=(10, 90), allow_redirects=False,
        )
        if not 200 <= response.status_code < 300:
            raise RuntimeError(f"SandBase HTTP {response.status_code}; request stopped")
        body = response.json()
    except requests.RequestException:
        raise RuntimeError("Network request failed; inspect locally before another call") from None
    except ValueError:
        raise RuntimeError("SandBase returned invalid JSON") from None
    if not isinstance(body, dict) or body.get("status") != "completed":
        raise RuntimeError("SandBase request did not complete")
    outputs = body.get("outputs")
    if not isinstance(outputs, list) or not outputs or not isinstance(outputs[0], dict):
        raise RuntimeError("Missing documented outputs[0]")
    data = outputs[0].get("data")
    if not isinstance(data, dict):
        raise RuntimeError("Missing documented outputs[0].data object")
    if task == "profile":
        if data.get("channel_id") != channel_id or not isinstance(data.get("title"), str):
            raise RuntimeError("Profile reference shape or selected channel ID does not match")
    else:
        channel = data.get("channel")
        if not isinstance(channel, dict) or channel.get("id") != channel_id:
            raise RuntimeError("Uploads channel identity does not match")
        videos = data.get("videos")
        if not isinstance(videos, list) or any(not isinstance(v, dict) for v in videos):
            raise RuntimeError("Missing videos array of objects")
    return data


if __name__ == "__main__":
    result = first_request("profile", "UCeu6U67OzJhV1KwBansH3Dg")
    print("Received fields:", sorted(result))
To choose uploads, replace the main assignment with result = first_request("uploads", "UCeu6U67OzJhV1KwBansH3Dg"). Do not append that line if you only intended one call. The helper omits continuation_token, makes no automatic retries, follows no redirects and stops on HTTP, JSON, incomplete-status or reference-shape errors. It does not expose the key or copy upstream error bodies into its exception text.
These are conservative checks for the simplified reference shapes. Profile fields sit directly in the business object; uploads have videos plus a channel object whose id must match the requested one. A valid empty videos list passes, while a missing list or a mismatched channel does not. Optional fields are returned unchanged instead of being converted into a smaller record that invents values for absent metrics.
Why an optional channel_id still belongs in the first profile request
Channel Description describes two stages: use channel_id for basic information, then use a returned continuation_token for advanced information. The unified schema marks its fields optional because it describes both stages. That is not a useful reason to send an empty first body. This tutorial only implements the selected-channel first stage; it neither invents a token nor tests an advanced-info request.
Channel Videos separately requires channel_id. Both routes document country_code US, language_code zh-CN and need_format true as defaults. The new helper explicitly chooses English/US simplified output. Language is a display preference: it does not establish that a channel description or video title has been translated, nor make abbreviated counts exact.
A dated profile reference, not a new measurement
The public saved Channel Description example has ID 2052034d-9439-4c44-92db-3db9579d6579, created_at 2026-10-07T17:36:23.063Z. Its input used channel_id UCeu6U67OzJhV1KwBansH3Dg, country_code US, language_code zh-CN and need_format true. This trimmed excerpt retains actual saved fields; it is not a result obtained by running the English example above:
{
  "channel_id": "UCeu6U67OzJhV1KwBansH3Dg",
  "title": "CozyCraft",
  "subscriber_count": "12万位订阅者",
  "video_count": "222 个视频",
  "view_count": null,
  "creation_date": null,
  "country": null,
  "has_business_email": false
}
Keep subscriber_count and video_count as their original display strings with locale and observation time. A conversion from an abbreviated subscriber display remains approximate; it should not acquire extra precision in a spreadsheet or comparison. The null view_count, creation_date and country mean unavailable in this sample. They are not zero lifetime views, today’s creation date or a location you can infer from the channel’s language.
A single profile snapshot cannot establish growth. Even two records need compatible fields, scope and dates before comparison. Do not join the October profile and the differently dated upload reference below into a manufactured performance trend. They are independent references for different tasks, not a matched longitudinal experiment.
The has_business_email field is a flag, not an address. It also does not authorize outreach. A verified flag is the response’s assertion, not independent identity verification. Empty links and absent flags must stay distinct from verified negatives. Avatar, banner and RSS URLs remain references; this script does not download them, subscribe to a feed or message anyone.
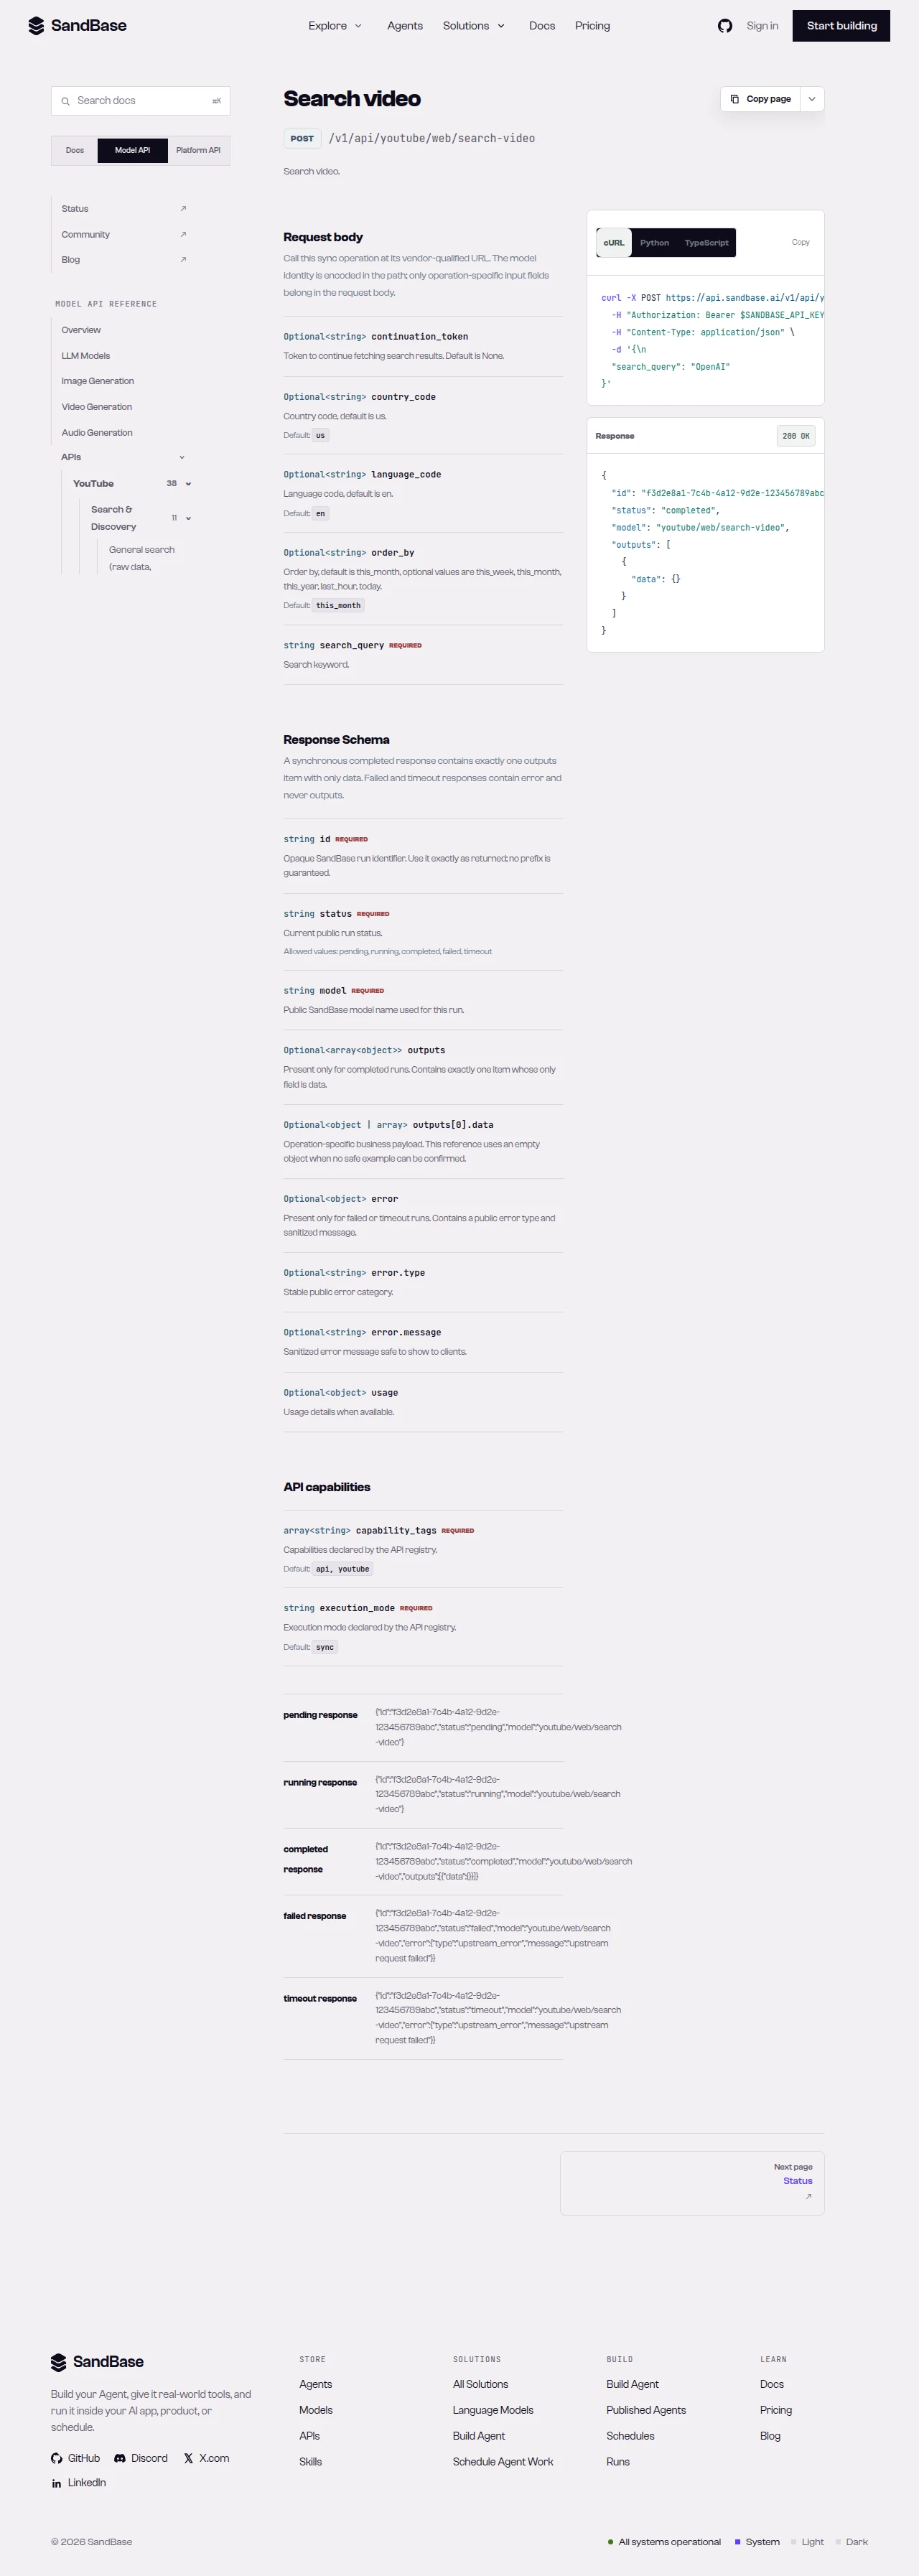 Historical web/search-video parameter reference. It belongs to the September 28 experiment, not the current Channel Description first request; search and continuation were not re-executed in this repair.
Read uploads as a page sample
The saved Channel Videos example is 270ee769-7d3b-44e0-8e91-cb2cc6304832, created_at 2026-08-20T09:38:28.973Z. It used the same channel ID with US/zh-CN and simplified formatting. Its full saved payload contains 30 videos; the following excerpt retains just the associated channel and one video, omitting media and token fields:
{
  "channel": {
    "id": "UCeu6U67OzJhV1KwBansH3Dg",
    "name": "CozyCraft"
  },
  "videos": [
    {
      "video_id": "Y30C0VjUT78",
      "title": "you don't have to worry tonight… (minecraft music & ambience)",
      "published_time": "2天前",
      "duration": "11:00:00",
      "duration_accessibility": "11小时",
      "is_live": false
    }
  ]
}
Thirty is an observed count, not a fixed page size. The selected schema declares no numeric page, limit or sort parameter. Do not add them or promise newest-first ordering from the first result. The response is a sample of returned uploads, not a full archive, private channel analytics or an inventory of all video types.
Keep the video’s ID and source URL associated with the returned channel. View fields and published_time may be localized display text. Missing views remain unknown; a relative publication label is not an exact timestamp. Duration and duration_accessibility describe length, not age: the displayed eleven hours in this reference does not mean the video was published eleven hours before retrieval. An is_live flag does not grant private access or permission to download a playback URL.
Channel Videos may return its own continuation_token for a separately selected next page. Keep the route, channel and locale with that token; do not substitute Channel Description’s advanced-info token or another channel’s token. No continuation roundtrip occurred in this repair, and an empty page alone does not prove the entire channel lacks uploads. Inspect what the response actually establishes before designing another request.
The original September 28 experiment
The old tutorial searched machine learning tutorial through youtube/web/search-video and used returned channel IDs with youtube/web/channel-info. Search run a8b82dc1-190d-4560-9fa2-3c98878bfad4, dated 2026-09-28 UTC, recorded a videos list, continuation_token and number_of_videos. Its observed video fields included video_id, title, author, channel_id, number_of_views, published_time and video_length.
Channel-info run eca232e4-ce65-45eb-ab7f-6da2c99c16bc recorded title, subscriber_count, video_count, view_count, verified, creation_date and country as observed fields. The original article contained these run IDs and field descriptions but no JSON response fence. This repair preserves that limitation rather than inventing a historical payload or assigning the current web-v2 sample to the older web endpoint.
The old Python helper preferred an undocumented output fallback and silently defaulted missing data to an empty object; its research function could visit several channels selected from one search. All original blocks are preserved verbatim in the historical Python archive. They are a record of the previous article, not current recommended code. Use the bounded helper above for a selected profile or uploads page.
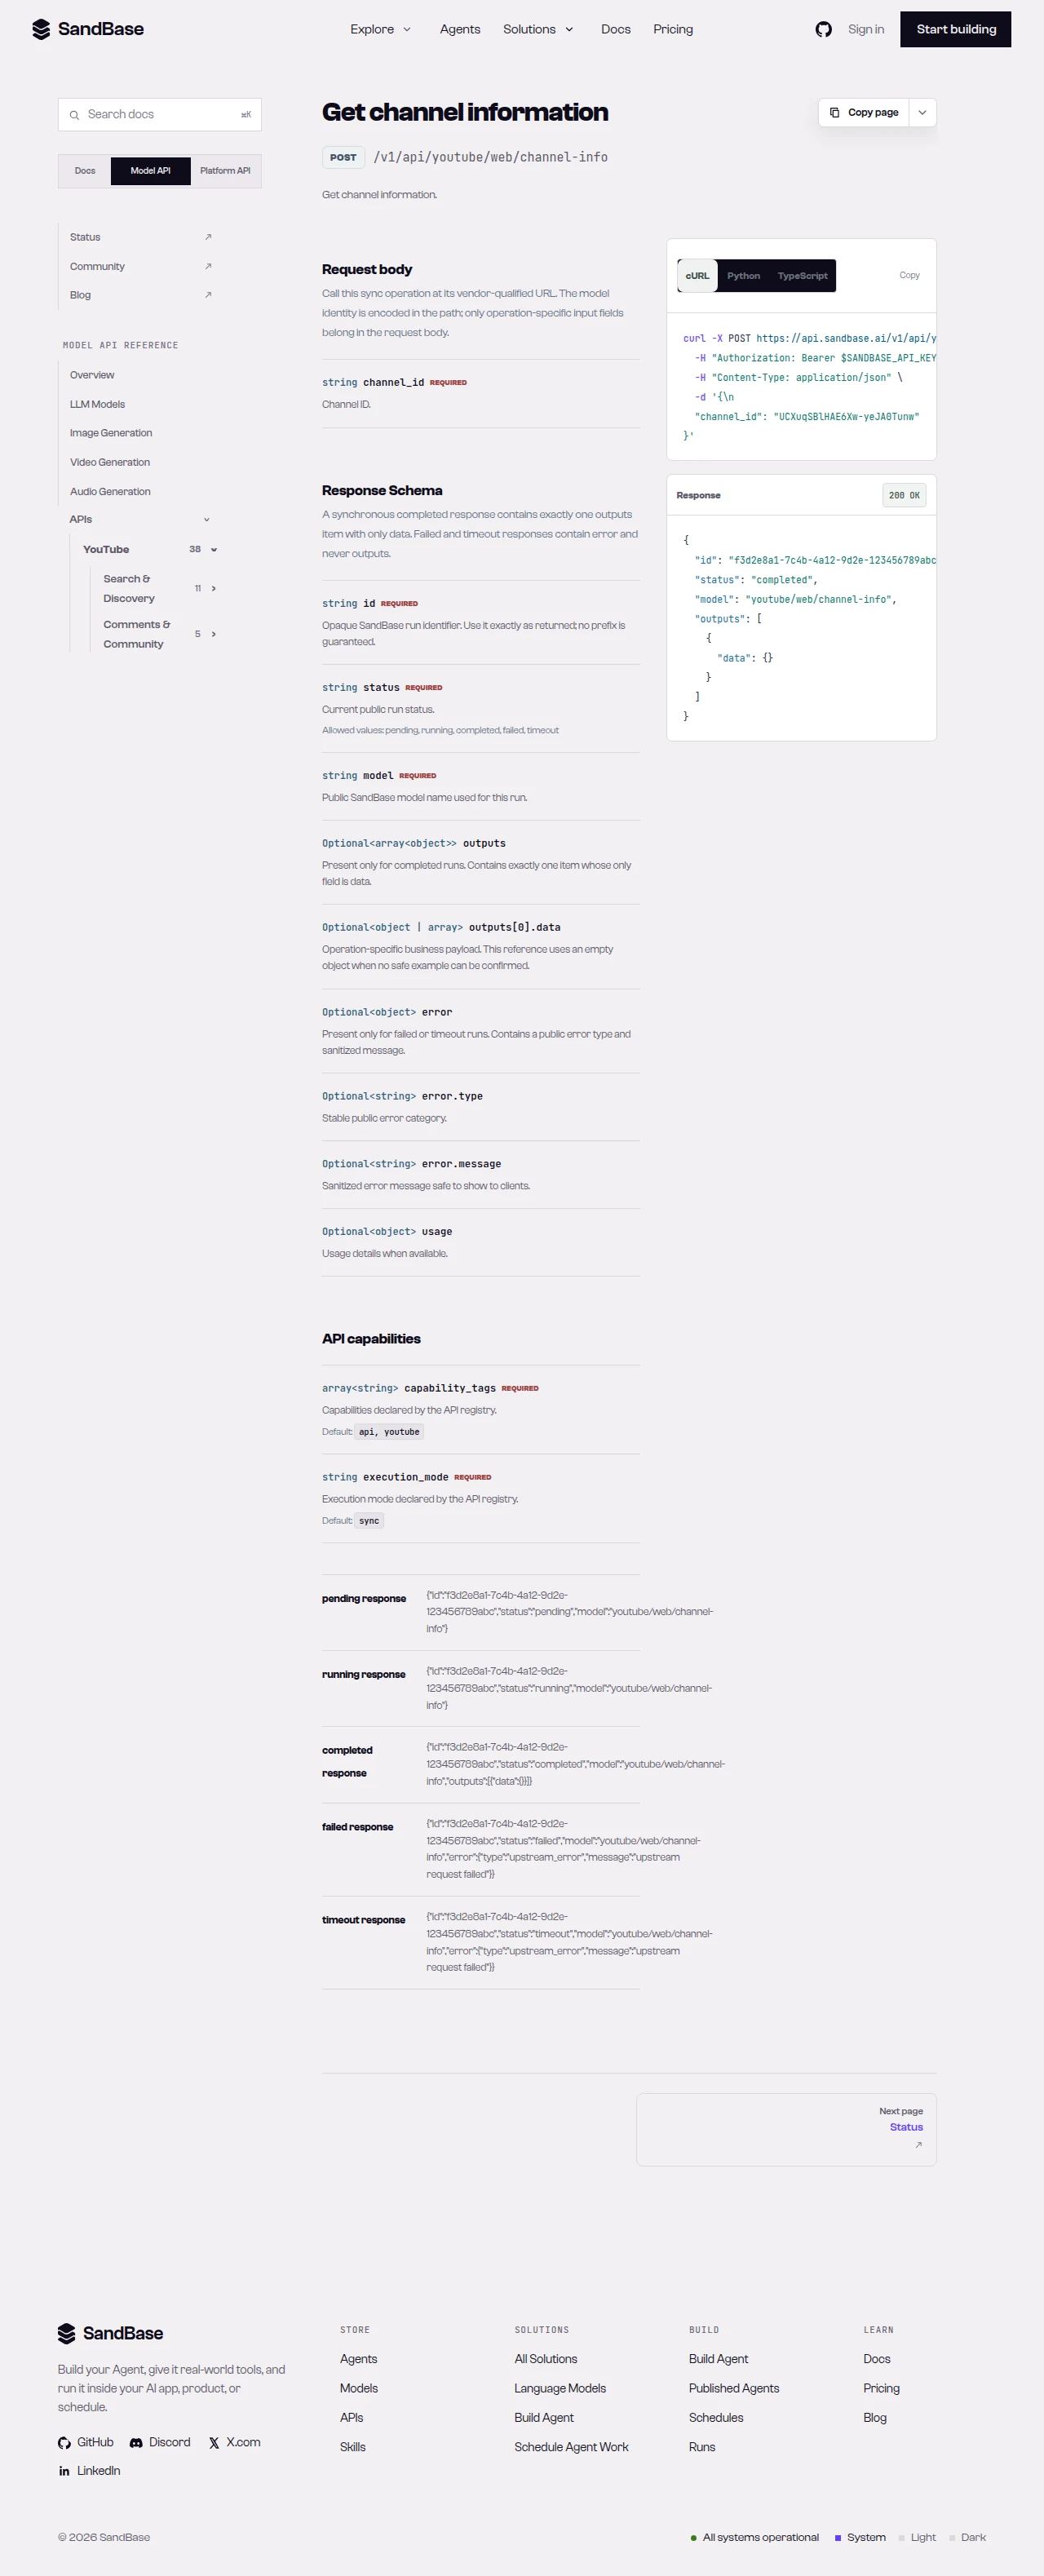 Historical web/channel-info reference from the original experiment. This is a different route from the current web-v2/channel-description choice; the screenshot does not prove a new profile lookup.
Price, scope and research quality
Free inspect checked on 2026-11-08 lists both selected endpoints at USD 0.001 per call, eligible for the organization’s shared 100 daily eligible-data-API calls, reset at 00:00 UTC. Eligibility does not reveal remaining allowance, account balance or actual charge, and it does not promise a free successful response. One selected request is 0.001 before quota effects; independently choosing both is 0.002.
After saving a valid response, ask whether more data would answer a defined question. A profile can support a basic creator shortlist when unknown values remain visible. A video page can show the kinds of titles returned for that channel, but cannot establish exhaustive topic coverage. Competitor growth analysis needs comparable observations over time; the current first request does not manufacture that history. Do not silently expand to every video, its comments, captions and a model summary.
FAQ
Can I send a handle instead of channel_id? This first-request helper expects a selected UC channel ID. Resolve names or URLs separately using the appropriate current endpoint; it does not guess the first matching creator.
Why not send an empty profile body when the fields are optional? The route supports a first ID-based request and a later token-based advanced-info request. This example implements the first stage and requires your selected channel.
Will advanced info fill the null metrics? No such guarantee is established. The current reference has null view_count, creation_date and country, and this revision did not execute the advanced-info request.
Can I request the newest ten uploads? The selected schema has no limit, numeric page or sort field. Read one returned page and inspect its order; the example makes no newest-ten promise.
Does a business-email flag give me contact details? No. It is a flag rather than an address or permission to contact the creator.
Wrap up
Start with a known channel ID and choose one profile read or uploads page. Validate the returned identity, preserve raw values, and stop before another channel or continuation. The YouTube hub helps find a separately scoped next task.
Found this useful? Share it