Gemini 4 Argon API: Access, Price and Our Gemini Tests
Gemini 4 Argon API: who can use it now, what the $2/$10 intro price means, and how five Gemini models available today did on our agent and coding tests.
Google announced Gemini 4 Argon on September 30, 2026, with a price ($2 per million input tokens, $10 per million output) and no date for developers. On 2026-10-04 at 00:13 UTC, SandBase’s GET /v1/models/google/gemini-4-argon still answered HTTP 404, “model not found”. So the useful question today isn’t “how good is Argon”. It’s what you can plan and run while you wait.
This post covers what Google said about the Gemini 4 Argon API, what the announced price means per task, and what we measured on five Gemini models you can call today, using the harnesses from our 12-model tool-calling benchmark and our Claude Code coding benchmark. It’s for developers deciding whether to wait for Argon or build on Gemini 3.x now.
Key takeaway
- Argon is announced, not generally available. Google is rolling it out to trusted cyber defenders first, then developers, “starting with paid API customers and Google AI Ultra subscribers”, with no date. SandBase doesn’t list it yet.
- The introductory price, $2 / $10 per million tokens with cached input 95% off, is the same per-token rate as GPT-6.1 Sol on SandBase. Real cost will depend on how many tokens Argon uses, which nobody outside the testers knows.
- On 17 agent tool tasks run 3 times each, Gemini 3.1 Pro preview scored 47/51 and the four Flash models 42 to 46. GPT-6.1 Sol, Claude Opus 5.5 and GPT-6 Luna scored 51/51.
- Every Gemini Flash model missed the same average-of-20-numbers task in all three runs. Gemini 3.1 Pro preview got it right but truncated a long filtered list three times.
- In Claude Code, Gemini 3.8 Flash and 3.1 Pro preview passed 12/12 coding tasks at a median $0.29 and $0.45 per task. Gemini 3.5 Flash-Lite passed 3/12; all 12 of its runs ended on a stream error.
What Google announced
Everything in this table comes from Google’s announcement, re-read on 2026-10-04. Benchmark scores are Google-reported; we haven’t reproduced any of them.
| Item | What Google’s post says |
|---|---|
| Announced | Sep 30, 2026 |
| Who has it now | ”a set of trusted cyber defenders through our Fairwind Program” |
| Who gets it next | developers, enterprises and consumers, “starting with paid API customers and Google AI Ultra subscribers”; no date given |
| Price | ”an introductory price of $2 per million input tokens and $10 per million output tokens” |
| Cached input | ”priced at 95% off input token price” |
| Output limit | 1M tokens, “up from the previous 64K tokens” |
| DeepSWE v1.1 (long-horizon software engineering) | 77.9% (Google-reported) |
| AutomationBench (Zapier) | 51.3% (Google-reported) |
| LVBench (long video) | 91.7% (Google-reported) |
| CWE-bench v1 (vulnerability remediation) | 68%, tied for first (Google-reported) |
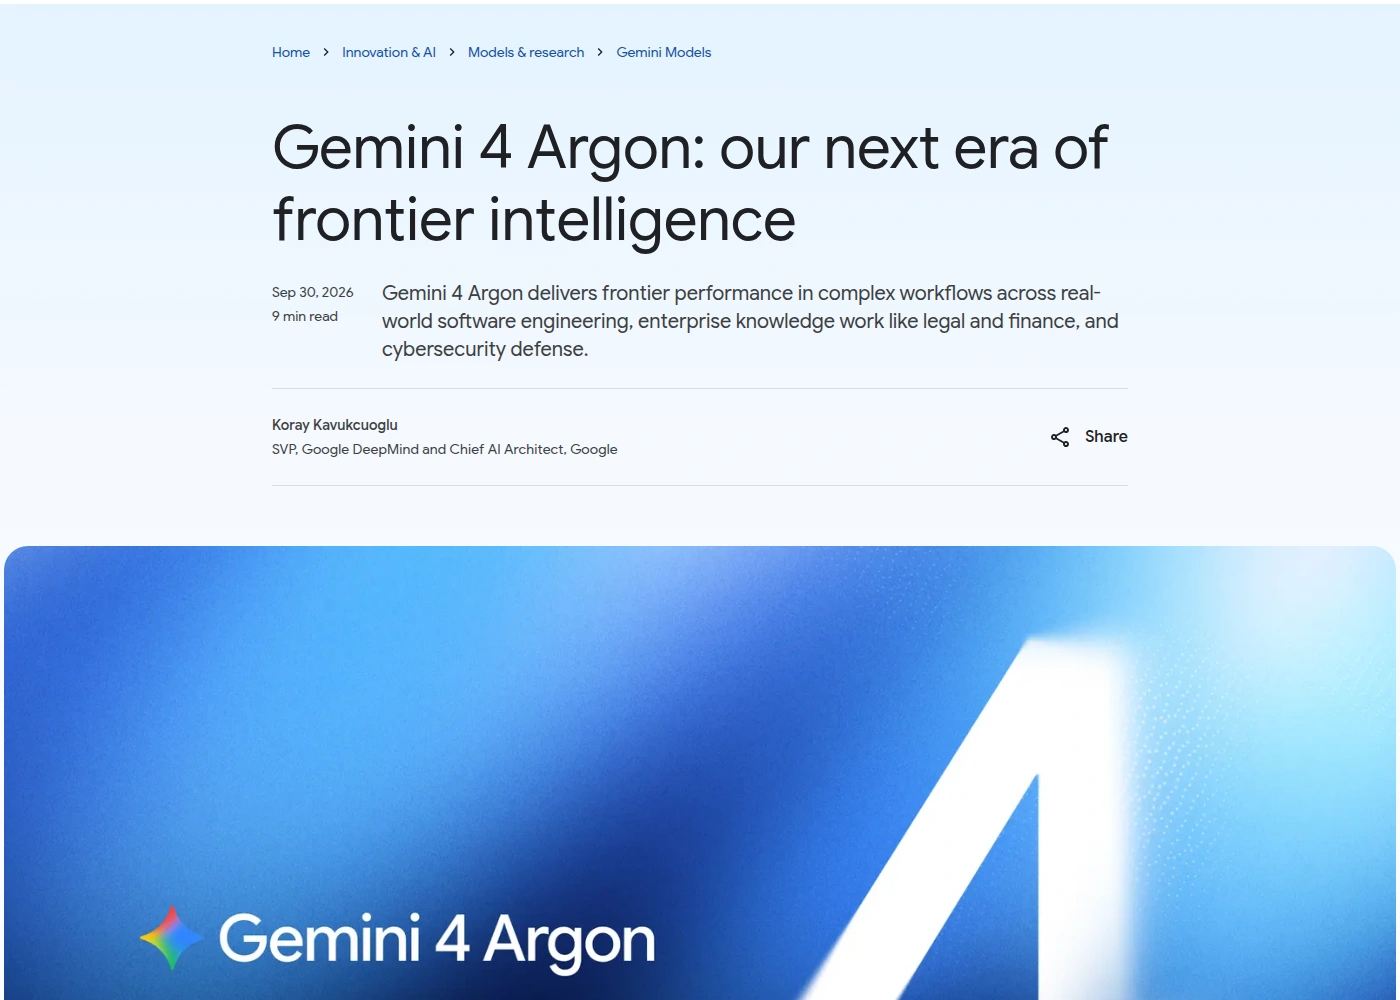
Caption: Google’s official post announcing Gemini 4 Argon on Sep 30, 2026, the only source used for the facts table above (captured 2026-10-04).
For planning: the price is “introductory” with no end date or follow-on price, and the rollout is phased, with safeguards strengthened “before broad availability”. We won’t guess a date.
Can you use the Gemini 4 Argon API today?
Not unless you’re in Google’s early programs. On 2026-10-04 at 00:13 UTC, SandBase returned 404 “model not found” for google/gemini-4-argon, google/gemini-4-argon-preview and google/gemini-4, while its model list showed 16 Gemini ids, including the five tested below. When Argon opens on SandBase, we’ll run it through the same two harnesses; we can’t promise when.
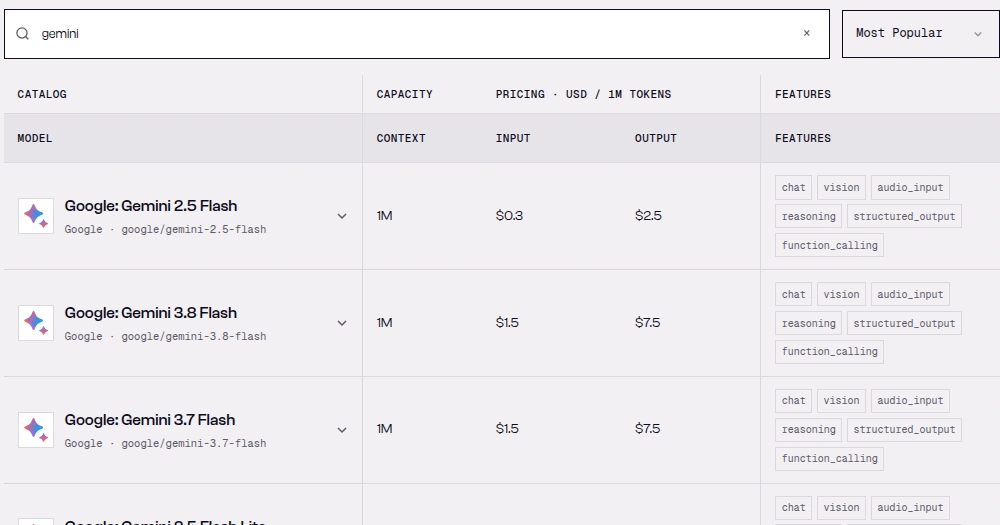
Caption: Searching the SandBase catalog for “gemini” lists the Gemini models you can call today, such as Gemini 3.8 Flash and 3.7 Flash at $1.50 / $7.50 per million tokens; no Argon entry appeared (captured 2026-10-04).
Gemini 4 Argon pricing: what $2 / $10 means per task
Per token, Argon’s intro price matches GPT-6.1 Sol on SandBase ($2 / $10) and undercuts Gemini 3.1 Pro preview’s $12 output rate. Per task, token count decides the bill. The table below is a projection, not a measurement: our measured token counts per tool task, priced at Argon’s announced rate.
| Token profile (measured) | Median in / out tokens | Median cost at its own price | Same tokens at Argon’s $2 / $10 |
|---|---|---|---|
| GPT-6.1 Sol | 2,887 / 110 | $0.0069 | $0.0069 |
| Gemini 3.8 Flash | 2,679 / 235 | $0.0058 | $0.0077 |
| Gemini 3.1 Pro preview | 2,679 / 717 | $0.0129 | $0.0117 |
| Claude Opus 5.5 | 5,041 / 436 | $0.0285 | $0.0143 |
If Argon uses tokens like Sol, it costs what Sol costs. If it writes like Gemini 3.1 Pro preview, whose median output was 6.5x Sol’s, it costs about 1.7x more per task. The 95% cache discount matters most for agents that resend a long prompt every turn, like Claude Code; Google gives no cache-write price.
What we measured on Gemini models available today
Agent tool calling: 17 tasks, 3 runs each
Same harness as our Pro vs Flash tier benchmark: six tools over public Douyin, Weibo and Xiaohongshu data, cached and replayed so every model saw identical tool responses; 17 scored tasks (T1 to T10 lookups, H1 to H8 harder aggregations, H7 excluded); 1,500 output tokens per turn; up to 10 turns; default settings. Gemini 3.8 Flash and the baselines ran on 2026-10-03 between 07:36 and 10:42 UTC. The other four Gemini models ran from 23:55 UTC on 2026-10-03 to about 00:06 UTC on 2026-10-04. Prices are SandBase list prices from GET /v1/models/<id>, which needs the same Authorization: Bearer key as the calls; the public model pages show the same prices.
| Model | $/M in / out | T (30) | H (21) | Total (51) | Median cost / task | Median time |
|---|---|---|---|---|---|---|
| Gemini 3.1 Pro preview | $2 / $12 | 30 | 17 | 47 | $0.0129 | 12.6 s |
| Gemini 3.8 Flash | $1.50 / $7.50 | 27 | 19 | 46 | $0.0058 | 6.3 s |
| Gemini 3.7 Flash | $1.50 / $7.50 | 27 | 16 | 43 | $0.0064 | 7.4 s |
| Gemini 3.5 Flash-Lite | $0.30 / $2.50 | 27 | 16 | 43 | $0.0013 | 5.4 s |
| Gemini 3.5 Flash | $1.50 / $9 | 27 | 15 | 42 | $0.0071 | 6.5 s |
| GPT-6.1 Sol | $2 / $10 | 30 | 21 | 51 | $0.0069 | 9.5 s |
| Claude Opus 5.5 | $4 / $20 | 30 | 21 | 51 | $0.0285 | 10.1 s |
| GPT-6 Luna | $0.10 / $0.50 | 30 | 21 | 51 | $0.00035 | 7.6 s |
| Claude Sonnet 5.5 | $2 / $10 | 27 | 17 | 44 | $0.0130 | 13.6 s |
No Gemini model made a schema-invalid tool call. The misses were nearly all arithmetic or long lists:
- T5, average likes over 20 videos (correct: 422,764). Every Flash model missed it in 3 of 3 runs. Gemini 3.8 Flash answered 422,739 each time, 25 short. Gemini 3.1 Pro preview got all three right.
- H2, filtered list of four video IDs. Flash models added or dropped IDs (2 to 3 misses each). Gemini 3.1 Pro preview ran out of output budget here: all three runs stopped at the 1,500-token cap with no
FINALline. Its fourth miss was an H3 run that ended without aFINALline. - H4 and H3, sums of 10 to 20 numbers. Gemini 3.5 Flash and 3.7 Flash missed H4 in all three runs; Flash-Lite missed H3 twice, both times by exactly 20,000.
Our Gemini 3.7 Flash launch note cites a $0.75 / $3.75 intro price; SandBase listed $1.50 / $7.50 on 2026-10-04. Gemini 3.5 Flash also made 11 tool requests that weren’t in the cache (one with a mistyped account ID), and Flash-Lite made one; those went to the live API. No expected answer depends on them.
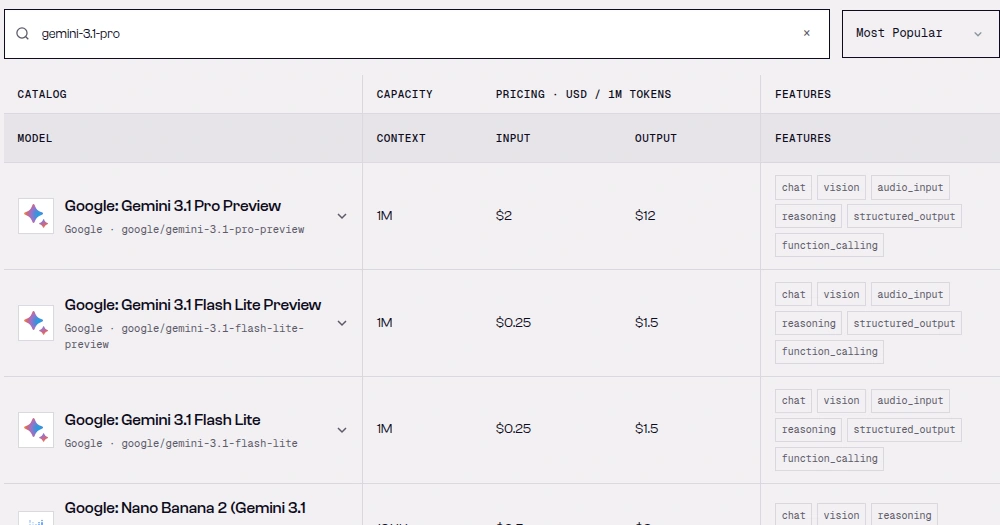
Caption: Gemini 3.1 Pro preview lists at $2 input and $12 output per million tokens, the price behind its $0.0129 median per tool task (captured 2026-10-04).
Coding agent: Claude Code, 6 tasks, 2 runs each
Same six small Python repo tasks as our Claude Code benchmark, graded by hidden tests copied in after the agent exits. Claude Code 2.1.246 reached Gemini through SandBase’s Anthropic-compatible POST /v1/messages; for each Gemini id it printed [claude-code:unrecognized_model] on stderr (12 of 12 runs per model), and the runs still worked. The Gemini runs took place between 23:57 UTC on 2026-10-03 and 00:09 UTC on 2026-10-04; the baselines ran on 2026-10-03 from 13:40 to about 14:15 UTC.
| Model | Pass (12) | Median turns | Median time | Median cost / task | Claude Code reported (12 runs) |
|---|---|---|---|---|---|
| Gemini 3.8 Flash | 12 | 10.5 | 68 s | $0.293 | $14.21 |
| Gemini 3.1 Pro preview | 12 | 10.5 | 98 s | $0.446 | $14.99 |
| Gemini 3.5 Flash-Lite | 3 | 9 | 46 s | $0.037 | $8.05 |
| GPT-6.1 Sol | 12 | 23.5 | 114 s | $0.117 | $4.55 |
| Claude Sonnet 5.5 | 12 | 9 | 109 s | $0.124 | $1.56 |
| Claude Opus 5.5 | 12 | 5 | 44 s | $0.540 | $7.64 |
| GPT-6 Luna | 11 | 22 | 100 s | $0.0071 | $4.33 |
Cost is our estimate: Claude Code’s cumulative usage × SandBase list price, cache reads at each card’s cache_read_multiplier (0.1 for Gemini), cache writes at the normal input rate because the Gemini cards list no write multiplier. Claude Code’s own total_cost_usd doesn’t know these models. /v1/messages ids don’t resolve in GET /v1/tasks/<id>/cost, so billing wasn’t reconciled per run.
Two results need context. First, Gemini 3.8 Flash has cheaper rates than GPT-6.1 Sol but cost 2.5x more per task, because only 11% of its tokens were cache reads, against 93% for Sol. Most of its input was billed at full rate. Second, Flash-Lite’s 3/12 isn’t a coding verdict. Every one of its 12 runs ended with “API Error: stream closed before completion” after 3 to 14 turns; three happened to leave passing code behind. We didn’t rerun it.
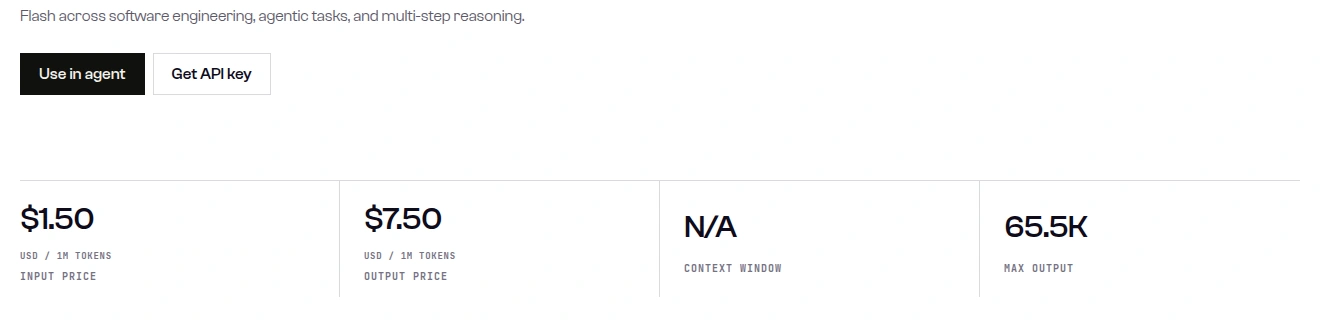
Caption: The Gemini 3.8 Flash model page on SandBase shows $1.50 / $7.50 per million tokens and a 65.5K max output, against the 1M output limit Google announced for Argon (captured 2026-10-04).
What this suggests about Argon
Nothing about its quality: these are different models, and Google’s Argon numbers come from different benchmarks. The data only tells you what to test first when Argon opens: arithmetic over tool output (where every Gemini Flash slipped), long answers under a token cap (where 3.1 Pro preview truncated), and caching inside a coding agent (which drove Gemini’s cost per task). Until then, do sums in code, give long answers enough max_tokens, and measure cost per task, not per token.
Switch an agent to Gemini on SandBase today
SandBase serves the Gemini models above through the OpenAI-compatible Chat Completions API with the same key as every other model, so switching is one string. The program below gives Gemini 3.8 Flash one tool that wraps a public Douyin endpoint and does the averaging in Python, the exact step Flash missed in T5. aweme_list and statistics.digg_count are field names observed in our responses, not documented guarantees, so the code reads them with .get().
import os
import re
import json
import requests

BASE = "https://api.sandbase.ai/v1"
HEADERS = {"Authorization": f"Bearer {os.environ['SANDBASE_API_KEY']}"}
# Swap the model by changing one string. $/M input, output: SandBase list price, 2026-10-04.
MODEL = os.environ.get("AGENT_MODEL", "google/gemini-3.8-flash")
PRICE = {"google/gemini-3.8-flash": (1.5, 7.5), "google/gemini-3.1-pro-preview": (2, 12),
         "openai/gpt-6.1-sol": (2, 10), "openai/gpt-6-luna": (0.1, 0.5)}
SYSTEM = "Use the tools to answer; never guess numbers. Finish with one line: FINAL: {json}."


def call_data_api(model: str, params: dict) -> dict:
    """Call a SandBase data endpoint and return outputs[0].data, failing loudly otherwise."""
    resp = requests.post(f"{BASE}/api/{model}", headers=HEADERS, json=params, timeout=120)
    resp.raise_for_status()
    body = resp.json()
    outputs = body.get("outputs") or []
    if body.get("status") != "completed" or not outputs:
        raise RuntimeError(f"SandBase call did not complete: {body.get('status')} {body.get('error')}")
    return outputs[0].get("data") or {}


def douyin_video_stats(sec_user_id: str) -> dict:
    """First page of an account's videos, with the arithmetic done here, not by the model."""
    data = call_data_api("douyin/app-v3/user-post-videos",
                         {"sec_user_id": sec_user_id, "max_cursor": 0, "count": 20})
    likes = [(item.get("statistics") or {}).get("digg_count") or 0  # observed field names
             for item in data.get("aweme_list") or []]
    if not likes:
        return {"videos": 0, "found": False}
    return {"videos": len(likes), "likes_sum": sum(likes), "likes_mean_floor": sum(likes) // len(likes)}


TOOLS = [{"type": "function", "function": {
    "name": "douyin_video_stats",
    "description": "Like statistics for the first page (up to 20) of a Douyin account's videos.",
    "parameters": {"type": "object", "properties": {"sec_user_id": {"type": "string"}},
                   "required": ["sec_user_id"]}}}]


def run(task: str, model: str = MODEL, max_tokens: int = 1500) -> dict:
    """One agent run over Chat Completions. Returns the parsed FINAL json plus usage and list-price cost."""
    messages = [{"role": "system", "content": SYSTEM}, {"role": "user", "content": task}]
    usage, ids = [0, 0], []
    for _ in range(6):
        resp = requests.post(f"{BASE}/chat/completions", headers=HEADERS, timeout=240,
                             json={"model": model, "max_tokens": max_tokens,
                                   "tools": TOOLS, "messages": messages})
        resp.raise_for_status()
        body = resp.json()
        ids.append(body.get("id"))
        usage[0] += body["usage"]["prompt_tokens"]
        usage[1] += body["usage"]["completion_tokens"]
        choice = body["choices"][0]
        msg = choice["message"]
        messages.append({k: v for k, v in msg.items() if k in ("role", "content", "tool_calls")})
        if choice.get("finish_reason") == "length":
            raise RuntimeError(f"output cut at max_tokens={max_tokens}")
        calls = msg.get("tool_calls") or []
        if not calls:
            found = re.search(r"FINAL:\s*(\{.*\})", msg.get("content") or "", re.S)
            if not found:
                raise RuntimeError("no FINAL line")
            price_in, price_out = PRICE[model]
            cost = usage[0] / 1e6 * price_in + usage[1] / 1e6 * price_out
            return {"model": model, "answer": json.loads(found.group(1)), "turns": len(ids),
                    "tokens": usage, "cost_usd": round(cost, 6), "completion_ids": ids}
        for call in calls:
            args = json.loads(call["function"].get("arguments") or "{}")
            messages.append({"role": "tool", "tool_call_id": call["id"],
                             "content": json.dumps(douyin_video_stats(**args))})
    raise RuntimeError("turn limit reached")


if __name__ == "__main__":
    task = ("For the Douyin account with sec_user_id "
            "MS4wLjABAAAA8U_l6rBzmy7bcy6xOJel4v0RzoR_wfAubGPeJimN__4, what is the average like count "
            "on the first page, rounded down? Keys: videos, average_likes.")
    print(json.dumps(run(task), ensure_ascii=False))
Tested on 2026-10-04 (UTC). We ran the program above verbatim at 00:14 UTC. Input: the public People’s Daily Douyin account used in T5. Data request: POST https://api.sandbase.ai/v1/api/douyin/app-v3/user-post-videos with {"sec_user_id": "MS4wLjABAAAA8U_l6rBzmy7bcy6xOJel4v0RzoR_wfAubGPeJimN__4", "max_cursor": 0, "count": 20}. Trimmed response:
{"id": "f013c20f-8f09-449b-a7a4-8a17462a2ea3", "status": "completed",
 "model": "douyin/app-v3/user-post-videos",
 "outputs": [{"data": {"aweme_list": [
   {"aweme_id": "7692418769125199138", "statistics": {"digg_count": 42839}},
   {"aweme_id": "7692417622113111323", "statistics": {"digg_count": 10500}}],
  "has_more": 1}}]}
First 2 of 20 items in aweme_list shown; inside each item only aweme_id and statistics.digg_count are kept, and all other keys of the items, data and the envelope are omitted. The envelope (id, status, model, outputs[0].data) is documented; aweme_list, aweme_id, statistics.digg_count and has_more are field names we observed, not documented ones.
Gemini 3.8 Flash called the tool once and answered on its second turn. The program printed:
{"model": "google/gemini-3.8-flash", "answer": {"videos": 20, "average_likes": 442266}, "turns": 2, "tokens": [365, 192], "cost_usd": 0.001988, "completion_ids": ["280ed183-bcf5-4f31-ba4e-335f79181841", "a3b50716-e388-450a-a82f-dc73475e0bcc"]}The answer matches the floor of the mean we recomputed from the 20 digg_count values in that response. 112 of the 192 output tokens were reasoning tokens (observed in completion_tokens_details). GET /v1/tasks/<id>/cost, which needs the same Bearer key, billed the two completions $0.001485 and $0.000503, matching the program’s $0.001988, and the data call $0. The average differs from the benchmark’s 422,764 because the account has posted since the cache was recorded: the two videos above aren’t in it.
The endpoint’s fields are in the Douyin user-post-videos API reference. Set AGENT_MODEL to compare another model on the same task, and get a SandBase API key to run it.
Scope: public, read-only lookups that need a SandBase API key. SandBase isn’t an official Douyin, Weibo or Xiaohongshu partner, and nothing here touches private accounts, DMs, owner analytics or account actions. Tasks, grading rule and aggregates are in this article and the linked benchmarks; cached tool responses and run logs stay internal because they contain third-party content.
FAQ
Is the Gemini 4 Argon API available?
Not publicly as of 2026-10-04. Google is rolling it out to trusted cyber defenders first, then to developers starting with paid API customers and Google AI Ultra subscribers, with no date. SandBase returned “model not found” for it that day.
How much does Gemini 4 Argon cost?
Google announced an introductory price of $2 per million input tokens and $10 per million output tokens, with cached input 95% off. The post doesn’t say how long the introductory price lasts.
Gemini 4 Argon vs GPT-6.1 Sol: which is cheaper?
Per token, they’re the same: Sol lists at $2 / $10 on SandBase. Per task, it depends on how many tokens Argon uses. With Sol’s token profile from our tool tasks, both come to $0.0069; with Gemini 3.1 Pro preview’s longer outputs, Argon would cost $0.0117. We can’t compare quality until Argon is callable.
Which Gemini model should I use for agents today?
On our tests, Gemini 3.1 Pro preview for accuracy on tool tasks (47/51) and Gemini 3.8 Flash for coding through Claude Code (12/12, $0.29 per task) or fast, cheaper tool calls (46/51). Keep arithmetic in code with any of them.
Can Claude Code use Gemini models?
Yes, through SandBase’s Anthropic-compatible /v1/messages. Gemini 3.8 Flash and 3.1 Pro preview passed 12/12 here. Gemini 3.5 Flash-Lite’s runs all ended on a stream error, so test your route before you rely on it.
Limitations
Nothing here measures Argon; its facts are Google’s claims from one post. Our runs used one task family per harness, N=3 (tool tasks) and N=2 (coding), default settings and a 1,500-token cap that hurt the most verbose model. Gemini runs and baselines ran hours apart, so latency is rough. Costs are usage × list price, not reconciled bills. Flash-Lite’s coding result reflects a stream error we didn’t diagnose. Rerun your own tasks when Argon opens; we will too.