Instagram 话题标签研究 API 教程 | SandBase
选择一次 Instagram V3 标签搜索或已选标签帖子查询,核对不同响应结构,区分历史 V2 实验与当前参考。
Instagram 标签研究的第一步可以是两种不同问题:某个词能找到哪些标签名,或者一个已选标签的一页帖子是什么样。本文用 V3 接口实现其中一次请求,不自动打开所有候选、排序帖子或补查作者。
2026-11-08 修订依据免费 inspect 和公开参考,没有新执行业务调用。原 2026-10-01 UTC 实验及 V2 翻页结果保留为历史,不能拿来验证 V3 续页、排序或当前投放效果。Instagram 总览和账号研究是独立任务。
先说结论
- V3 搜索传 query;标签帖子传 tag,不带 #。
- 业务数据直接在 outputs[0].data。搜索参考没有业务成功标记;帖子参考有 status ok。
- 搜索的 hashtags、items 重复放了同一组 20 条记录,选一个读取,不拼接计数。
- 保存的 27 条帖子 taken_at 全为空,不能据此认定最新、热门或完整覆盖。
保留封面是旧种子词到帖子排名流程的概念图。逐级图片堆栈和“rank engagement”等文字不是实测表现,新 helper 不执行这条链路。
选一个任务,别混用版本参数
| 目的 | 当前接口 | 首次请求 |
|---|---|---|
| 找候选标签名 | V3 标签搜索 | query: openai |
| 读已选标签的一页帖子 | V3 标签帖子 | tag: veganrecipes |
query、tag 都是必填字符串,后者传标签名,不传搜索结果里的数字标签 ID。首次省略 rank_token、max_id。这两个 schema 没有 page size、feed_type、keyword 或 pagination_token,不能照搬 V2 参数。两个参考输入是独立样本,并非搜索自动选出下一步标签的证据。
 历史目录截图显示 81 个端点、GET 目录路径和 Available/Free 活动标签,不代表当前价格或免费成功。本教程使用 POST /v1/api/ 路径,价格见下文有日期的 inspect。
复用已有接入
已有 SANDBASE_API_KEY 就复用环境变量或密钥管理器。Agent 已连接时,只需给它选定任务和 query 或 tag,不必重新开户,也不要把 key 发进聊天。新项目可提供 setup Skill、Markdown quickstart及端点链接;人工步骤见接入指南。
让 agent 只读一次响应,报告未知字段,然后停止,不继续翻页或取帖子详情。这是经 SandBase 鉴权的公开读取,不是账号操作或私密内容访问授权;本文不推断当前官方 Instagram 产品的账号要求。
安装 requests 后在本地配置密钥。下面关于空白和标签格式的限制是本地保守校验,不是声称 registry 自带相同规则。
import os
import requests

API = "https://api.sandbase.ai/v1/api/instagram/v3"


def first_request(task, value):
    if task not in ("search", "posts"):
        raise ValueError("Choose search or posts")
    if not isinstance(value, str) or not value.strip() or value != value.strip():
        raise ValueError("Provide a nonempty selected query or tag without surrounding spaces")
    if task == "posts" and ("#" in value or any(c.isspace() for c in value) or "/" in value):
        raise ValueError("Provide the selected tag name without #, spaces or a URL")
    route, field = ("search-hashtags", "query") if task == "search" else ("hashtag-posts", "tag")
    key = os.environ.get("SANDBASE_API_KEY", "").strip()
    if not key:
        raise ValueError("Set SANDBASE_API_KEY locally")
    try:
        response = requests.post(
            f"{API}/{route}",
            headers={"Authorization": f"Bearer {key}", "Content-Type": "application/json"},
            json={field: value}, timeout=(10, 90), allow_redirects=False,
        )
        if not 200 <= response.status_code < 300:
            raise RuntimeError(f"SandBase HTTP {response.status_code}; request stopped")
        body = response.json()
    except requests.RequestException:
        raise RuntimeError("Network request failed; no automatic retry made") from None
    except ValueError:
        raise RuntimeError("SandBase returned invalid JSON") from None
    if not isinstance(body, dict) or body.get("status") != "completed":
        raise RuntimeError("SandBase request did not complete")
    outputs = body.get("outputs")
    if not isinstance(outputs, list) or not outputs or not isinstance(outputs[0], dict):
        raise RuntimeError("Missing documented outputs[0]")
    data = outputs[0].get("data")
    if not isinstance(data, dict):
        raise RuntimeError("Missing documented outputs[0].data object")
    if data.get("error") or data.get("errors") or ("success" in data and data["success"] is not True):
        raise RuntimeError("Explicit business failure; inspect before another request")
    if task == "posts" and data.get("status") != "ok":
        raise RuntimeError("Posts response is not the supported ok shape")
    if task == "search" and "status" in data and data["status"] != "ok":
        raise RuntimeError("Unexpected search status; inspect changed shape")
    collection = "hashtags" if task == "search" else "items"
    rows = data.get(collection)
    if not isinstance(rows, list) or any(not isinstance(row, dict) for row in rows):
        raise RuntimeError("Missing or malformed reference collection")
    required = ("id", "name") if task == "search" else ("id", "code")
    for row in rows:
        if any(not isinstance(row.get(k), str) or not row[k].strip() for k in required):
            raise RuntimeError("Missing identity fields in the supported record shape")
    return data


if __name__ == "__main__":
    result = first_request("search", "openai")
    print("Candidate records:", len(result["hashtags"]))
读取帖子时,将主程序两行替换为 result = first_request("posts", "veganrecipes") 和 print("Returned records:", len(result["items"])),不要追加成第二次调用。示例不重试、不跟随重定向、不翻页、不取详情或媒体,也不自动选候选。
搜索解析器明确选择 hashtags,不把重复的 items 当成备用或另一页。每条搜索记录要求参考里的字符串 id/name,帖子要求 id/code;可选字段原样保留。有效空数组与字段缺失、null、错误类型不同。显式错误或矛盾的可选标记会停止解析,但搜索不要求不存在的 status;帖子单独检查 ok。
当前保存参考能说明什么
搜索样本 10109988-3410-46f7-a52c-a677d47b5e59 保存于 2026-10-07T17:36:14.040Z,输入 query openai。count 为 20,hashtags/items 是相同的 20 条记录,rank_token 为空。首条记录按原值裁剪:
{
  "id": "17841553213093056",
  "name": "openai",
  "media_count": 2319697,
  "profile_pic_url": null
}
无日期 README 展示相同首条 ID/名称,但 media_count 为 2360486,保存记录则是 2319697。它们不能拼成增长区间。README 只展示一条,也不能把 count 20 解释为完整单条页面或固定页大小。
帖子样本 c1e42793-0f20-4fbe-830b-64ae472a86a4 保存于 2026-10-07T17:35:58.687Z,输入 tag veganrecipes,返回 status ok、count 27 和 27 条记录。下面只保留首条部分字段,不复制账号或长正文:
{
  "pk": "3997939143571340043",
  "id": "3997939143571340043_27565475186",
  "code": "Dd7iHgWMvsL",
  "media_type": 1,
  "taken_at": null,
  "like_count": 0,
  "comment_count": 1,
  "view_count": 0
}
27 条 taken_at 全为空,media_type 观察到 1 和 8,无法据此确认发布时间、最新优先、热门表现或完整归档。另一个 README 用的是 cat,count 21、一个裁剪条目和截断游标,不能与 veganrecipes 混为一条记录,更不能拿截断 token 执行。
字符串 pk、复合 id、code/shortcode 要分开保留。复合 ID 可能拼接帖子和作者标识,不是 shortcode。首条的零点赞、零浏览和一条评论是已返回的值;以后遇到缺失或 null 仍应保持未知。一页里的重复作者,也不能证明谁在整个标签下发得最多。
续页要另做决定
搜索接受 rank_token,但选定保存样本没有提供;这不证明 Instagram 再无匹配标签。帖子有 more_available 和 next_max_id,若另外决定续页,应将完整 next_max_id 原样作为 max_id,与相同 tag 一起发送。本轮没有测试 V3 下一页往返。
不要按数字递增页码、交换两种 token,或补全截断游标。后续采集需要页数/调用预算,并检查重复游标和记录。一次观察内去重,与因为 post code 已存在而丢弃以后刷新得到的新观察,是两回事。
指标不能直接选出投放赢家
media_count 是返回的标签帖子量,不是搜索需求、近期增长、独立创作者数或预测触达。相似名称可能属于不同主题;没搜到不代表不存在、没有归属或可注册。量大也不自动适合某个活动。
点赞、评论、浏览是不同信号。这里没有曝光窗口或粉丝分母,新代码不计算互动率;再查账号并相除,也仍是分析口径选择,不是通用有效答案。V3 参考没有确立旧 V2 的隐藏计数标记,不能看到 null 就认定作者隐藏了点赞。
当前字段是 caption_text,不是旧的 caption_hashtags 列表。把正文和链接当作原始数据,不能当成代码或 agent 指令。后续本地抽标签需说明规则。媒体 URL、类型和认证标记也不等于已下载、取得使用权或完成独立身份/合作审核。
保留 10 月 1 日的原实验
旧文记录的是 2026-10-01 UTC 的 V2 研究流程,此前于 10 月 24 日修订。它保留为历史,不再作为当前 V3 代码。原 12 段 Python 已逐字放入历史归档,附哈希。
作者先试 V3 帖子:在系列更早一次空结果后,run e0a2628b-a7b9-4dc7-b678-a6a83989af9b 返回 27 条、more_available 和 next_max_id。旧观察描述这一页来自前几小时,多为 0–8 个赞,因此选择 V2。那是当时的选择理由,不代表 V3 永远按时间排序或不适合表现分析;当前保存 V3 页没有可用日期。旧 V1 尝试则是 data.hashtag.edge_hashtag_to_media.edges[].node 结构,作者只有 ID。
V2 top run ef34d367-313d-4470-a4d9-505e238103cc 返回 24 条,跨度约三个月,部分点赞上千,带 Reel 播放量、用户名、认证和已解析标签。V2 搜索 0ae668b6-3580-498d-ae55-55e34a7fb84c 返回 55 个相关标签,原 JSON 不变:
{
  "data": {
    "count": 55,
    "items": [
      {"id": "17843646523025713", "name": "veganrecipeshare", "media_count": 332329, "allow_following": false},
      {"id": "17842274242068426", "name": "veganrecipes", "media_count": 9249683, "allow_following": false},
      {"id": "17842769464147759", "name": "veganrecipesforhealth", "media_count": 7781, "allow_following": false}
    ]
  }
}
旧代码用 1000 条阈值筛选,veganrecipes 约 920 万,随后 veganrecipeshare、easyveganrecipes、alkalineveganrecipes、rawveganrecipes 均超过 10 万。另一旧 V3 搜索得到 20 个标签,观察到相同 ID/计数及空 rank_token;没有可用续页令牌不代表全平台没有更多标签。
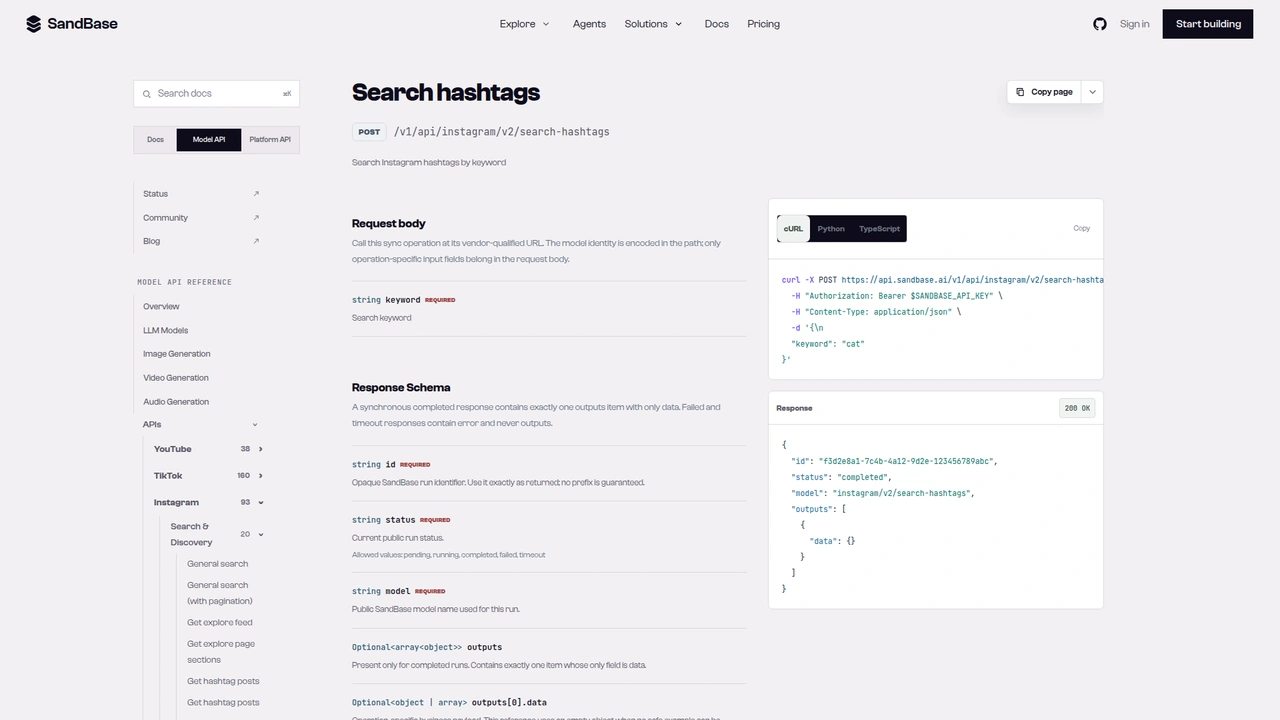 历史 V2 search-hashtags 的 keyword 参数与空业务占位响应,不是当前 V3 query schema,也不是新搜索执行的证据。
旧 V2 pagination_token 与内层 data 并列。传回后,第二页 run 4c96135e-d0c9-4642-8979-bd47599fe0be 返回 30 条,与首屏不重合,并带新 token;只测试了两页。原 Reel 裁剪保留:
{
  "code": "DcZlsXtzS-X",
  "media_type": 2,
  "product_type": "clips",
  "like_count": 5719,
  "comment_count": 1763,
  "play_count": 661027,
  "taken_at": "2026-08-23T22:44:44Z",
  "taken_at_ts": 1787525084,
  "is_paid_partnership": false,
  "like_and_view_counts_disabled": false,
  "caption_hashtags": ["#pineapplechutney", "#spicychutney", "#easyrecipes", "#veganrecipes"]
}
原 24 条中两条 like_count 为 null,同时 like_and_view_counts_disabled 为 true,原文解释为隐藏计数;不能把这种组合套到没有相应标记的 V3。V2 top 时间是 ISO 字符串,recent run a249ddfd-f55a-4f94-809f-f4cf42482341 却是 Unix 秒;观察到媒体类型 1、2、8,轮播播放数为零。这些都只是历史,不能当成当前 V3 归一化规则。
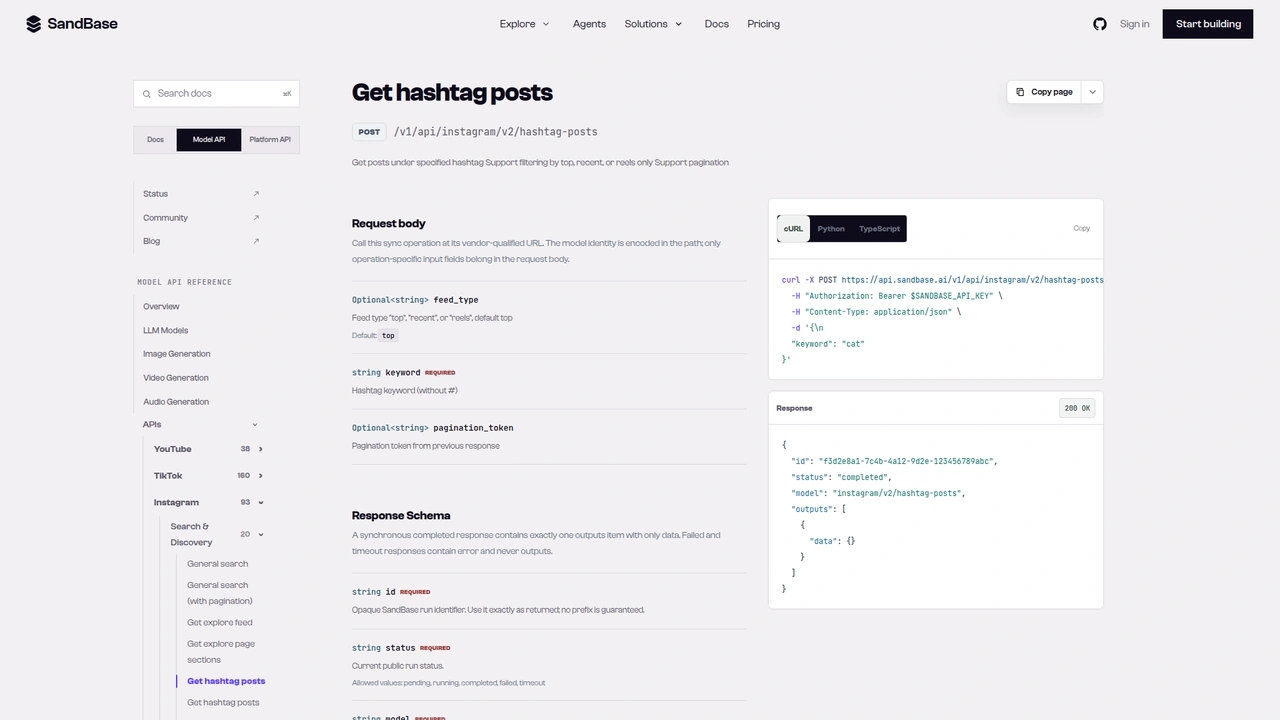 历史 V2 hashtag-posts 的 keyword、feed_type、pagination_token 参数。当前 V3 使用 tag 和可选 max_id;旧 V2 翻页成功不等于 V3 续页已验证。
原 post-info run f714c418-01ef-4074-9cf1-94f6241169d8 读取品牌轮播,修正为从 metrics 取计数。原 JSON 保留:
{
  "data": {
    "code": "Dd7t9arlwZC",
    "product_type": "carousel_container",
    "carousel_media_count": 3,
    "taken_at_date": "2026-10-01T01:22:00+00:00",
    "metrics": {"like_count": 4, "comment_count": 0, "play_count": null, "share_count": null},
    "caption": {
      "text": "Yes, ice cream can be vegan. We tested it - and it works perfectly. ...",
      "hashtags": ["#instantpot", "#instantchill", "#veganicecream", "#vegan", "#veganrecipes"]
    },
    "user": {"username": "instantpotofficial", "full_name": "Instant Pot®", "is_verified": true}
  }
}
原文记下帖子当时发布数小时、计数较小,但年龄不能独立解释原因。另一次 V3 post-info-by-code 尝试 bc654757-6209-44de-9ff6-de74b144316c 得到不同的 items 结构;本轮没有重跑这两条详情接口。
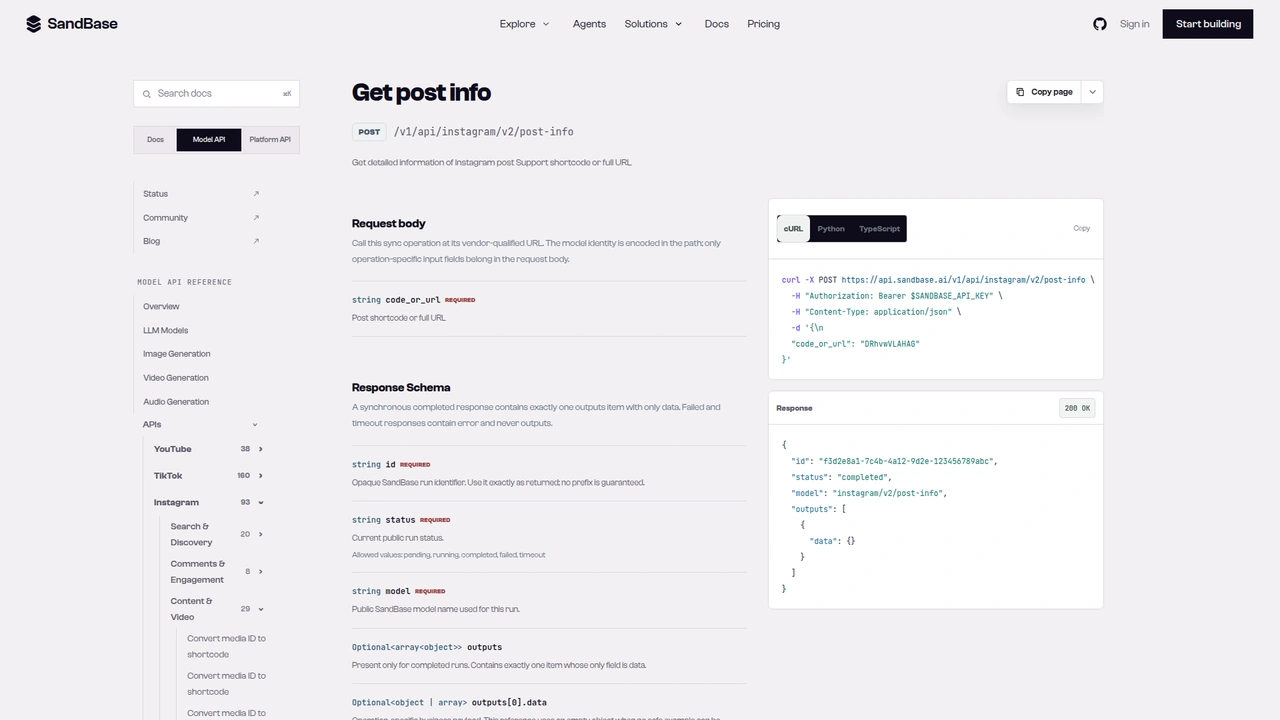 历史 V2 post-info 的 code_or_url 参数参考。复查帖子不在当前两个独立首请求的范围内。
原整份文件记录搜索 4323d2d9-d773-447b-adaa-297cc5982320、两页 45830a7e-d588-4674-b629-5e2a5b5d9309 与 27d391bb-1aeb-4af4-a9fa-a88a9bcc1bcd,再做同一个 f714c418 复查。不计重试是四次业务调用,不能因为只有三种接口就算三次;旧 helper 会重试,当前 V3 价格也不能倒算旧 V2 实验账单。
两页共 54 条,按旧点赞加评论绝对分数排出的前五有四条 Reel,第一约 2 万分、约 50 万播放。伴随标签 vegan 11、plantbased 10、plantbasedrecipes 6、easyrecipes 6。范围只是一个标签、一个下午,分数不是互动率、受众质量或全平台排序。旧默认零筛选、null 即隐藏的排名和仅按 code 缓存都已归档,不在新解析器复用。
价格与常见问题
2026-11-08 inspect 显示两条 V3 接口各 0.008 美元/次,分别选择两次为 0.016 美元,尚未考虑额度。两者具有组织共享每日 100 次合资格数据 API 调用的资格,00:00 UTC 重置;资格不表示剩余次数、余额、实际扣费或保证免费成功。
搜索也要求 status ok 吗? 不要求,其选定业务参考没有这个标记。帖子是另一种结构,helper 单独要求 ok。
帖子接口可以传数字标签 ID 或 V2 keyword 吗? 传已选名称作为 tag,不带 #。当前 V3 使用 query/tag,不使用旧 keyword/feed_type/pagination_token 组合。
这一页能证明热度或近期表现吗? 不能。报告计数和没有帖子日期的一页结果,不能确立增长、近期性、投放效果或完整覆盖。
从一个标签问题开始
选择候选搜索或已选标签的帖子,按各自结构验证、保留未知字段,一次后停止。Instagram 总览提供更广的导航。
觉得有用?分享给更多人