Bilibili Public Data API | SandBase
Read public Bilibili videos, search, hot search, and user profiles with one REST API. No Bilibili login, no SDK — one SandBase key, built for agents.
Bilibili is the center of gravity for Chinese video culture — long-form uploads, danmaku comment streams, a hot-search board, and creator profiles that map directly onto content research, trend detection, and creator analytics. Getting at it programmatically usually means reverse-engineering the app, managing cookies, and rebuilding a scraper every time the site changes.
The SandBase Bilibili public data API removes that setup tax. It reads public Bilibili videos, search results, the hot-search board, and user profiles through plain REST endpoints — one SandBase API key, no Bilibili login and no SDK. The endpoint API reference is the source of truth for each parameter and for the response envelope; the business-payload field names shown below are an illustrative shape, not a guaranteed schema, so confirm them against a live response for the endpoint you call.
This is not Bilibili’s official open platform. Use Bilibili’s official APIs when you need authenticated member actions or a licensed data agreement. Use SandBase when your workflow needs public, read-only data for research and monitoring. Ready to try it? Get a SandBase API key and browse the Bilibili endpoints.
Key takeaway
- One API reads public Bilibili videos, search, hot search, user profiles, and comments.
- The Model API endpoints in this guide are called with
POST /v1/api/bilibili/<path>— pass only that endpoint’s params, no SDK, oneSANDBASE_API_KEY.- Endpoints key off natural identifiers: a
bv_id/aidfor videos, auid/user_idfor creators, or akeywordfor search.- It returns public, read-only data only. No posting and no private data. No Bilibili login or OAuth is required for this public-data workflow; a SandBase API key is still required.
Which Bilibili API do you need?
| Your need | Choose | Why |
|---|---|---|
| Post, act as a member, or use account-authorized data | Bilibili’s official platform | Member and account operations run through Bilibili directly. |
| Read public videos, search, hot search, or profiles | SandBase Bilibili public-data API | Plain REST, one SandBase key, structured JSON for read-only workflows. |
| Private or account-only data | Neither public workflow | That data is out of scope for this public-data guide. |
What you can get from the Bilibili API
The catalog spans an app surface and a web surface. Grouped by job:
- Search & discovery — all-in-one search, search by type, and the hot-search board.
- Videos — video detail, parts, play info, danmaku, and subtitles by
bv_id/aid. - Creators — public profile, posted videos, dynamics, and relation stats by
uid. - Comments — video comments and reply threads.
Check each endpoint’s live API reference for the exact surface and parameters before you build; availability differs by endpoint.
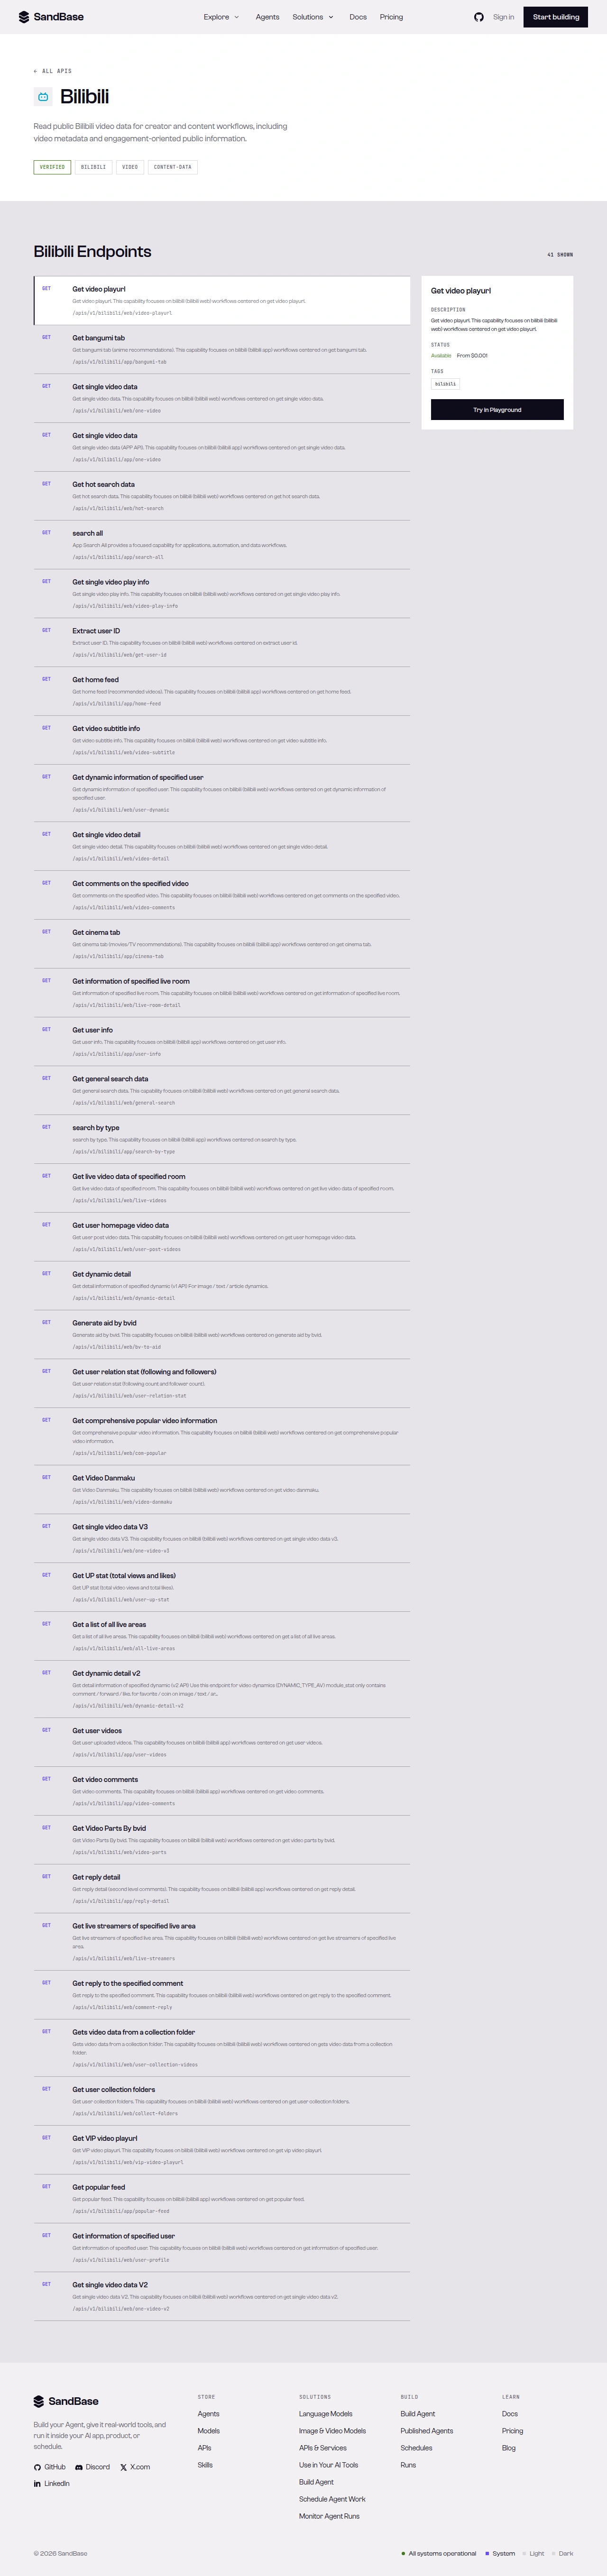 The Bilibili API page on SandBase — a tagged overview and the endpoint list, each with its path.
What Bilibili provides vs. what SandBase adds
Public data comes from Bilibili. SandBase does not own or operate Bilibili; it provides a uniform API layer for eligible public-data workflows. Each capability becomes one stable endpoint, auth collapses to a single key, and responses come back as predictable JSON — so an agent can chain “read the hot-search board → search a keyword → read a creator’s profile” along one convention instead of maintaining a scraper.
Quick start: your first call
SandBase exposes more than one API surface. The catalog may show GET paths under /apis/v1/...; this guide uses the vendor-qualified Model API path on each endpoint’s API reference. Do not swap the HTTP method or URL — follow the reference for the endpoint you choose.
Read the hot-search board:
import os
import requests

resp = requests.post(
    "https://api.sandbase.ai/v1/api/bilibili/web/hot-search",
    headers={
        "Authorization": f"Bearer {os.environ['SANDBASE_API_KEY']}",
        "Content-Type": "application/json",
    },
    json={"limit": 10},
)
resp.raise_for_status()
body = resp.json()
if body.get("status") != "completed":
    error = body.get("error", {})
    raise RuntimeError(error.get("message", "Bilibili request did not complete"))

# The reference guarantees only the envelope; business fields vary by
# endpoint, so use .get() and confirm against a live response.
data = body["outputs"][0]["data"]
trending = data.get("data", {}).get("trending", {}).get("list", [])
for item in trending[:5]:
    print(item.get("keyword"), item.get("heat_score"))
curl -X POST https://api.sandbase.ai/v1/api/bilibili/web/hot-search \
-H "Authorization: Bearer $SANDBASE_API_KEY" \
-H "Content-Type: application/json" \
-d '{"limit": 10}'Every response uses the same envelope: an id, a status, the model name, and an outputs array whose single item carries the payload under data. Branch on status before reading outputs[0].data, and check each endpoint’s reference for its run mode. Note that Bilibili endpoints often wrap their payload in an upstream { code, data, message } object, so the useful fields sit under data.data. The block below is an illustrative response shape — the field names are not a guaranteed schema, so treat them and the values as examples and confirm them against a live response, since payloads vary and change over time:
{
  "id": "8ec19c89-2442-432b-9b05-efa2f4c97ce7",
  "status": "completed",
  "model": "bilibili/web/hot-search",
  "outputs": [
    {
      "data": {
        "code": 0,
        "data": {
          "trending": {
            "list": [
              { "keyword": "…", "show_name": "…", "heat_score": 4414039 }
            ]
          }
        }
      }
    }
  ]
}
A failed or timeout run carries error and never outputs. Response shapes differ by endpoint — inspect one real response and map the exact path per endpoint.
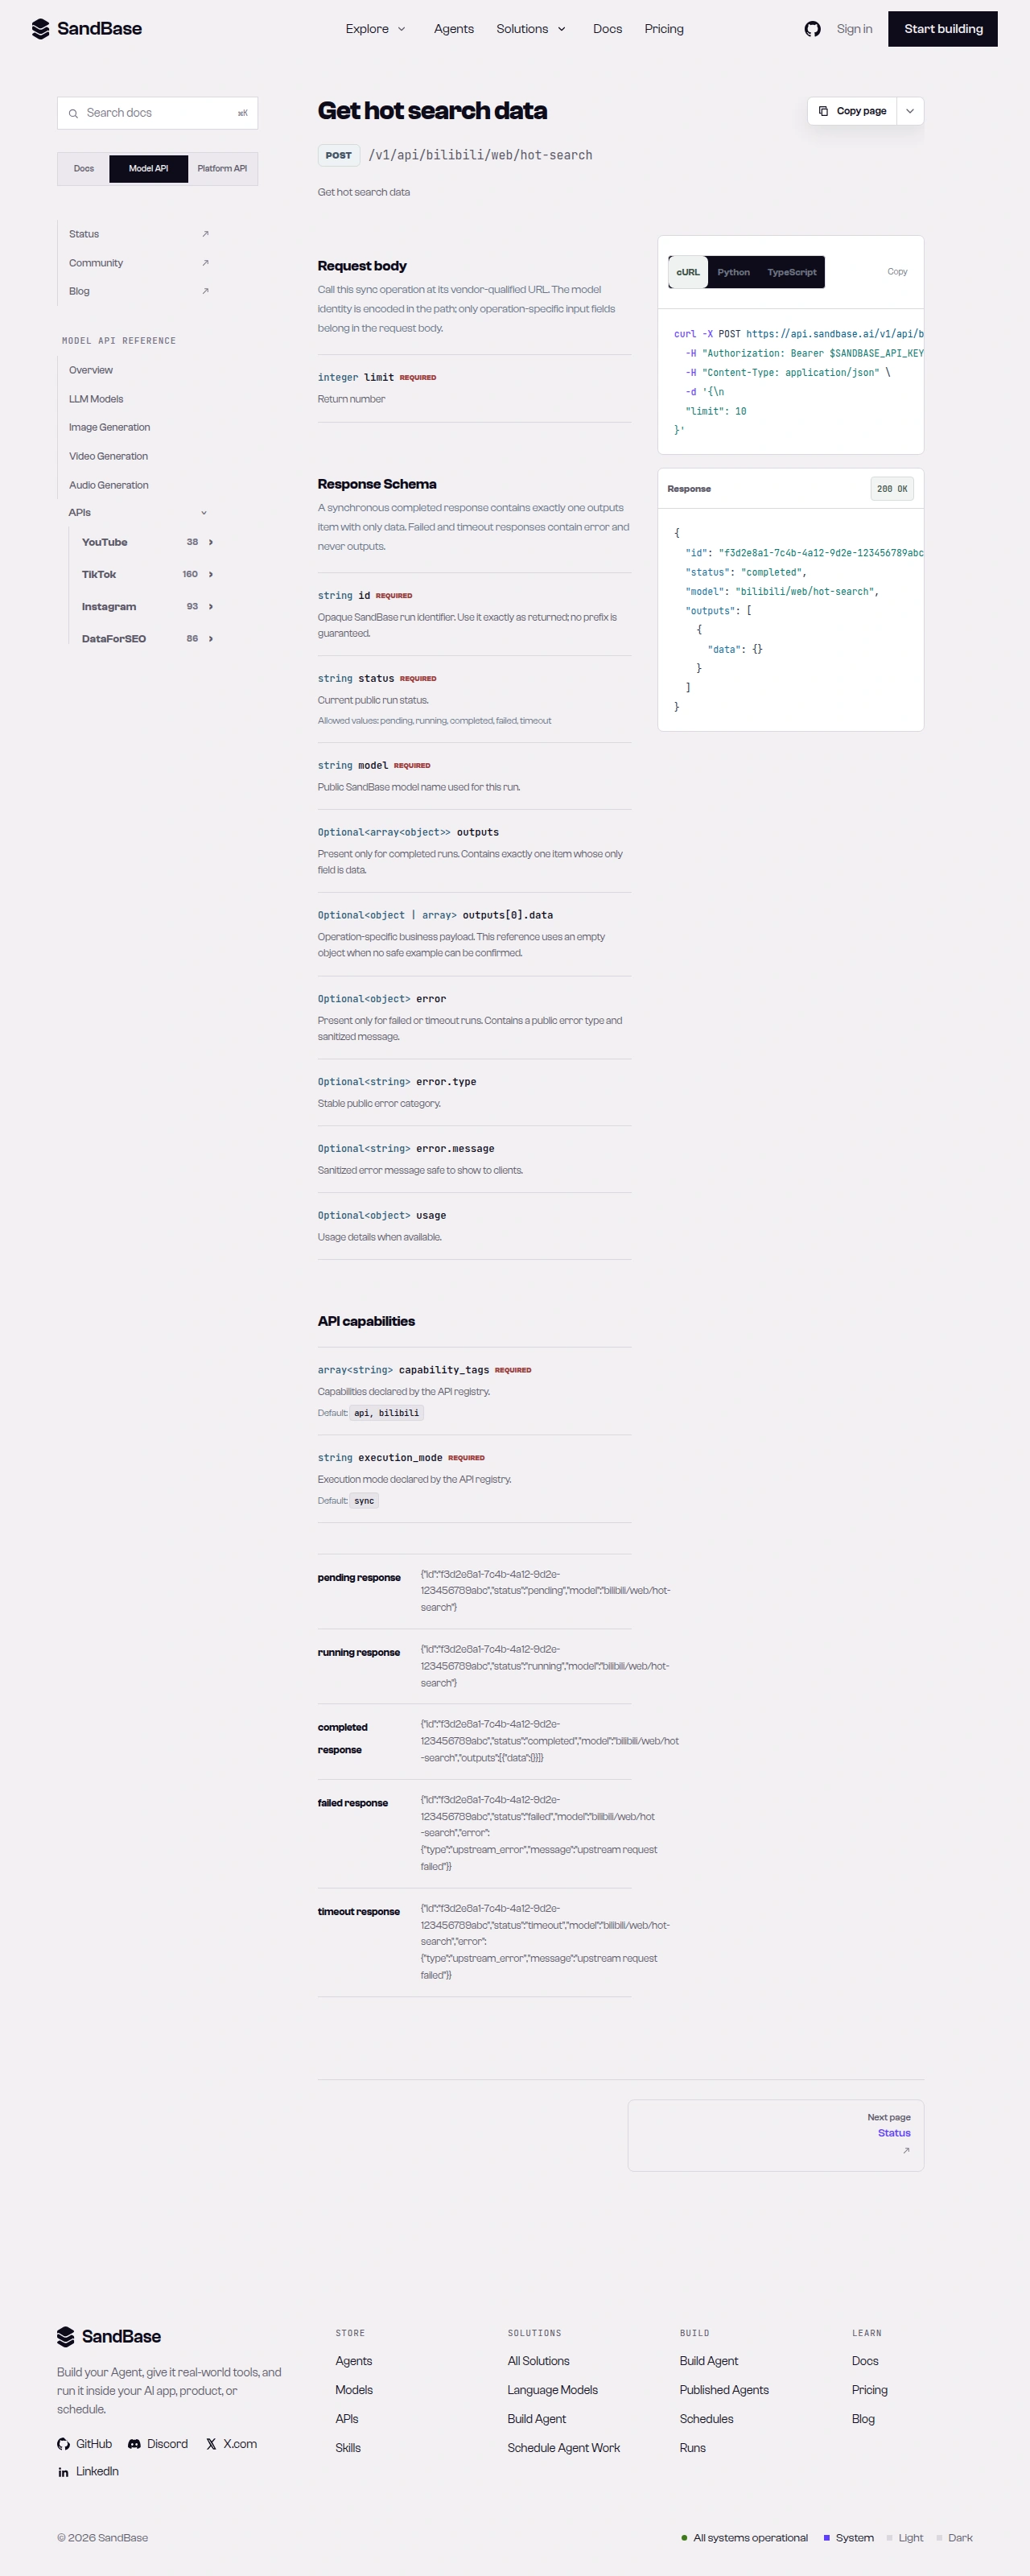 The endpoint API reference is the source of truth for each parameter name and response path.
Capability map
| Capability cluster | Representative endpoint | Typical use |
|---|---|---|
| Hot search | bilibili/web/hot-search | Trending-topic monitoring |
| Search | bilibili/app/search-all | Keyword discovery across content |
| User profile | bilibili/web/user-profile | Public creator signals by uid |
| Video detail | bilibili/web/video-detail | Read a video by aid |
| Video comments | bilibili/web/video-comments | Engagement and sentiment inputs |
Paging differs by endpoint — several endpoints accept a request parameter such as a page or offset value. Read each endpoint’s schema.
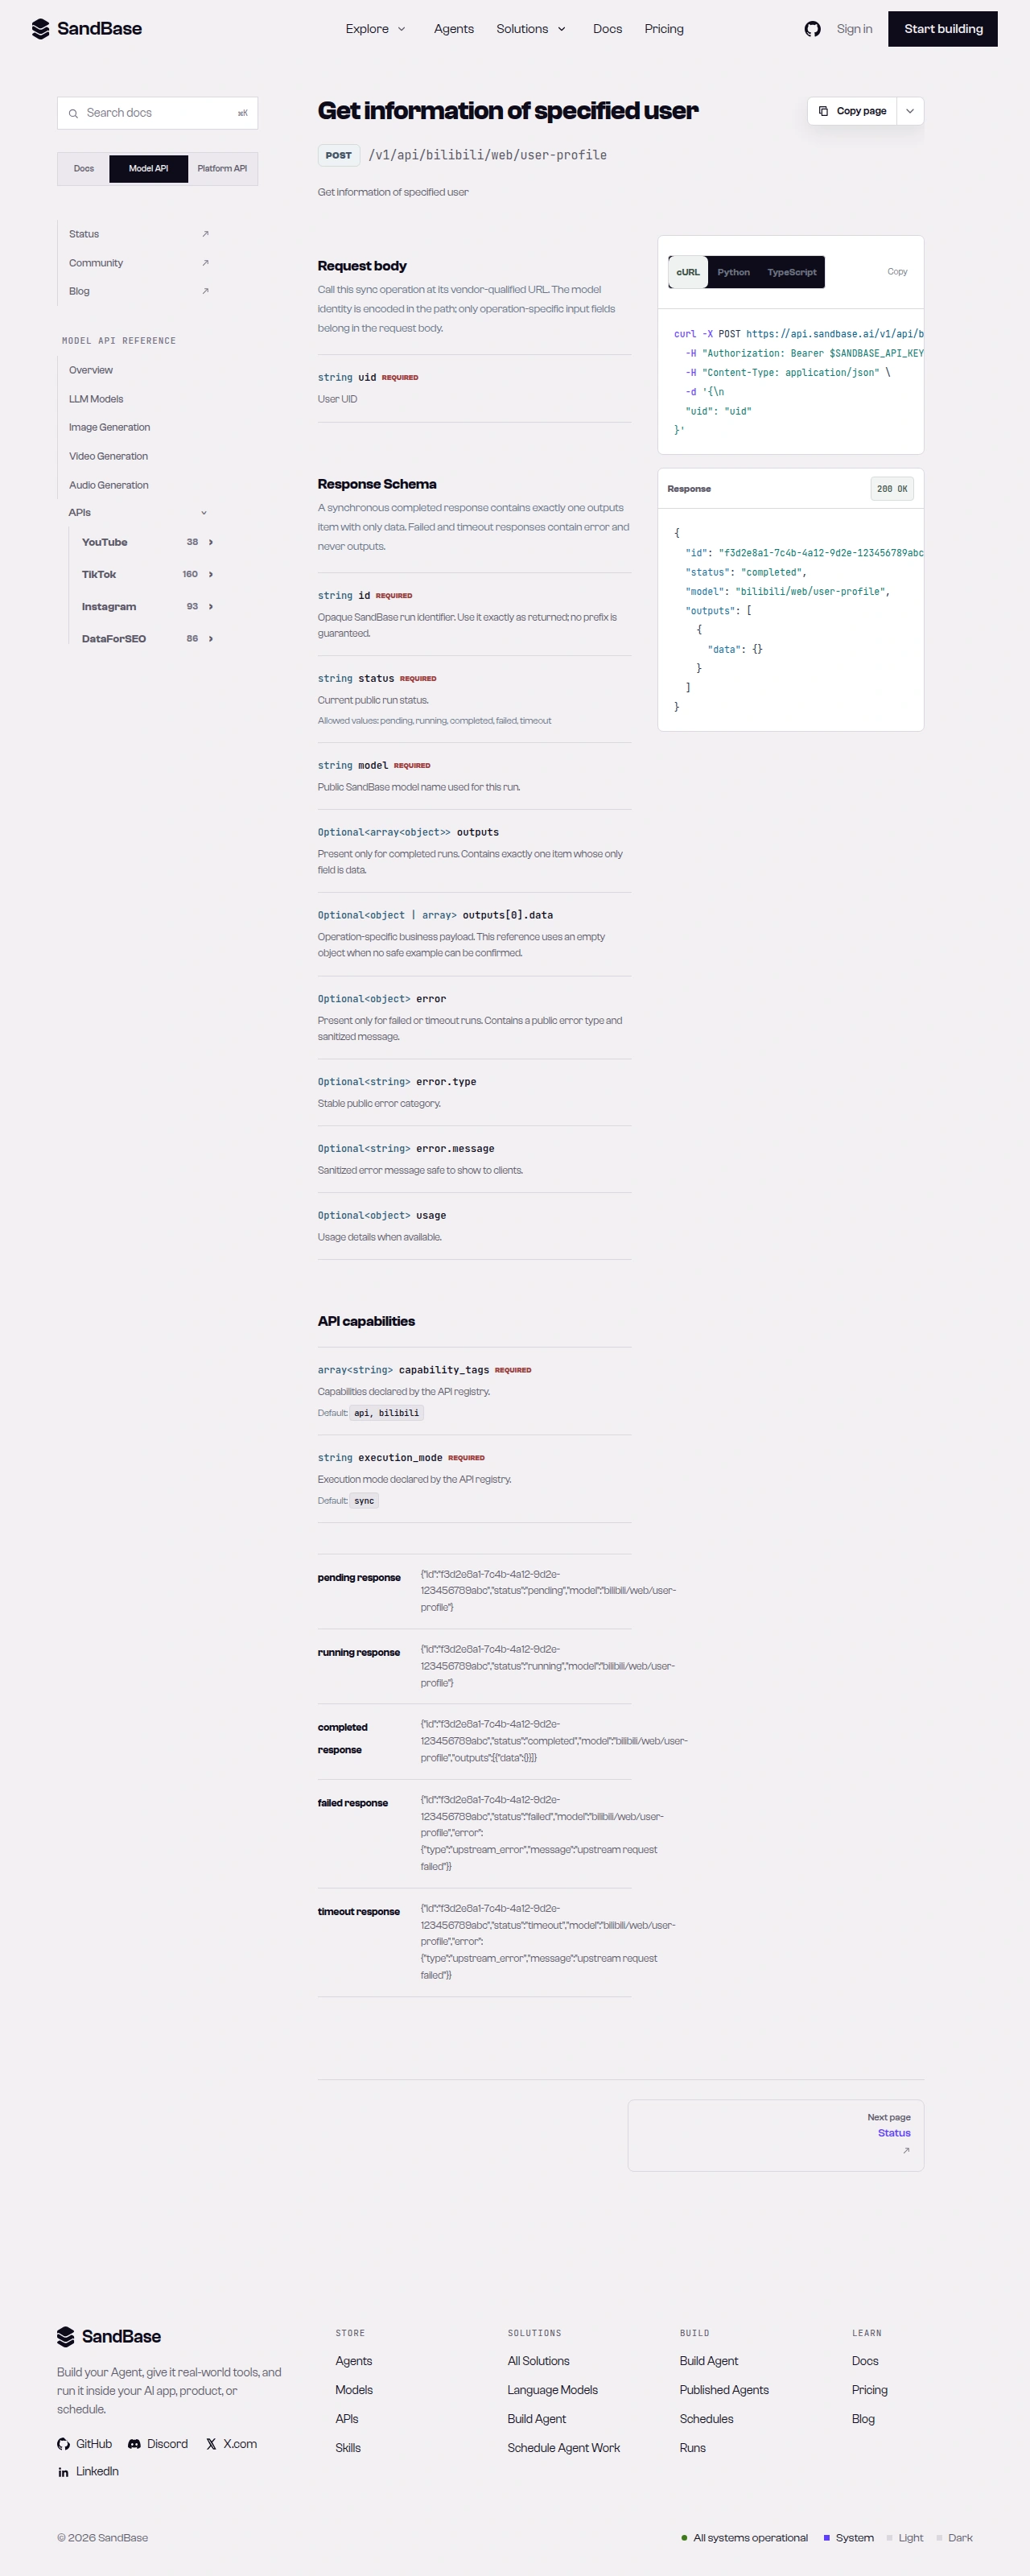 A slice of the Bilibili endpoint list across the app and web surfaces.
Chaining calls in an agent workflow
Because every endpoint shares the same auth and the same response envelope, an agent can walk from a trend to a creator without special-casing each surface. A common content-research pattern looks like this:
- Read the board. Call
bilibili/web/hot-searchto get the trending list, then pick the keywords you care about. - Search the keyword. Call
bilibili/app/search-allwith akeywordto pull matching videos and creators. - Profile the creator. Call
bilibili/web/user-profilewith auidto attach account context like name, level, and sign.
Each step returns the same { id, status, model, outputs } shape, so your agent branches on status once and reuses the same JSON-reading code (including the data.data unwrap) across every step.
Common use cases
Bilibili hot-search API for trend monitoring
Poll bilibili/web/hot-search on a schedule to track the trending board — each item carries a keyword and a heat score. Input: a required limit (integer). Output: a ranked list of trending keywords. Endpoint: hot-search.
Bilibili search API for content discovery
Run bilibili/app/search-all with a keyword to survey videos and creators around a topic. Input: a keyword. Output: matching results. Endpoint: search-all.
Bilibili creator API for channel research
Read a public creator with bilibili/web/user-profile for fields like name, level, and signature. Input: a uid. Output: a structured profile record. Endpoint: user-profile. For a full workflow, see how to do Bilibili creator research.
Why run this at the API layer
You could point a headless browser at Bilibili and parse the HTML, but that path is fragile: the markup changes, the app and web render differently, and you maintain selectors instead of shipping features. Reading through one uniform API means your code depends on named JSON fields and a single response envelope rather than a page layout. Auth is one key instead of rotating cookies, and because every endpoint returns the same { id, status, model, outputs } shape, retries, logging, and error handling live in one helper you write once and reuse everywhere.
That uniformity is what makes the workflow composable for an agent. Swap the hot-search keyword for any topic, swap one uid for another, and the code path is identical. Add a fourth read — a video’s comments, say — and it slots in behind the same status-checking helper. The practical payoff is that your time goes to what the data means for your research, not to keeping a scraper alive against a moving target. When you need more than single reads, check the live listing for the endpoint that fits and confirm its parameters before wiring it in.
Limitations and boundaries
- Public, read-only data only. No posting, following, or private/account-only data.
- Rate and volume. Treat responses as best-effort reads; as a client-side resilience measure, retry with backoff on transient errors such as HTTP 429.
- Parameters and shapes follow the upstream surface. Identifiers vary (
bv_id/aid,uid/user_id,keyword); payloads often nest under an upstreamdataobject; paging is a per-endpoint request parameter. Inspect a real response and read the schema first. - Verify endpoints against the live reference. Availability and fields can change; confirm before building on a specific endpoint.
- This is not an official Bilibili partnership. SandBase provides uniform access to public data; respect Bilibili’s terms and applicable rules for your use case.
FAQ
Do I need a Bilibili developer app or login?
No. You authenticate to SandBase with your SANDBASE_API_KEY. These read endpoints do not require a Bilibili account or OAuth on your side.
What identifies a video or creator?
Natural identifiers: a bv_id or aid for videos and a uid/user_id for creators. Search takes a keyword.
Why is the data nested under data.data?
Bilibili endpoints often pass through the upstream { code, data, message } envelope, so the useful payload sits under data.data. Read each endpoint’s schema for the exact path.
Can I read private or account-only data? No. The API returns public data only. Private and account-authorized content are out of scope.
Start with the hot-search board
Create a SandBase API key, call hot-search, and inspect the returned schema before you expand to search, videos, or creators. When you are ready: