Cross-Platform Trend Dashboard with One API | SandBase
Aggregate Weibo, Bilibili, and Zhihu hot lists into one trend dashboard with one REST API — one SandBase key, no logins, normalized to a shared shape.
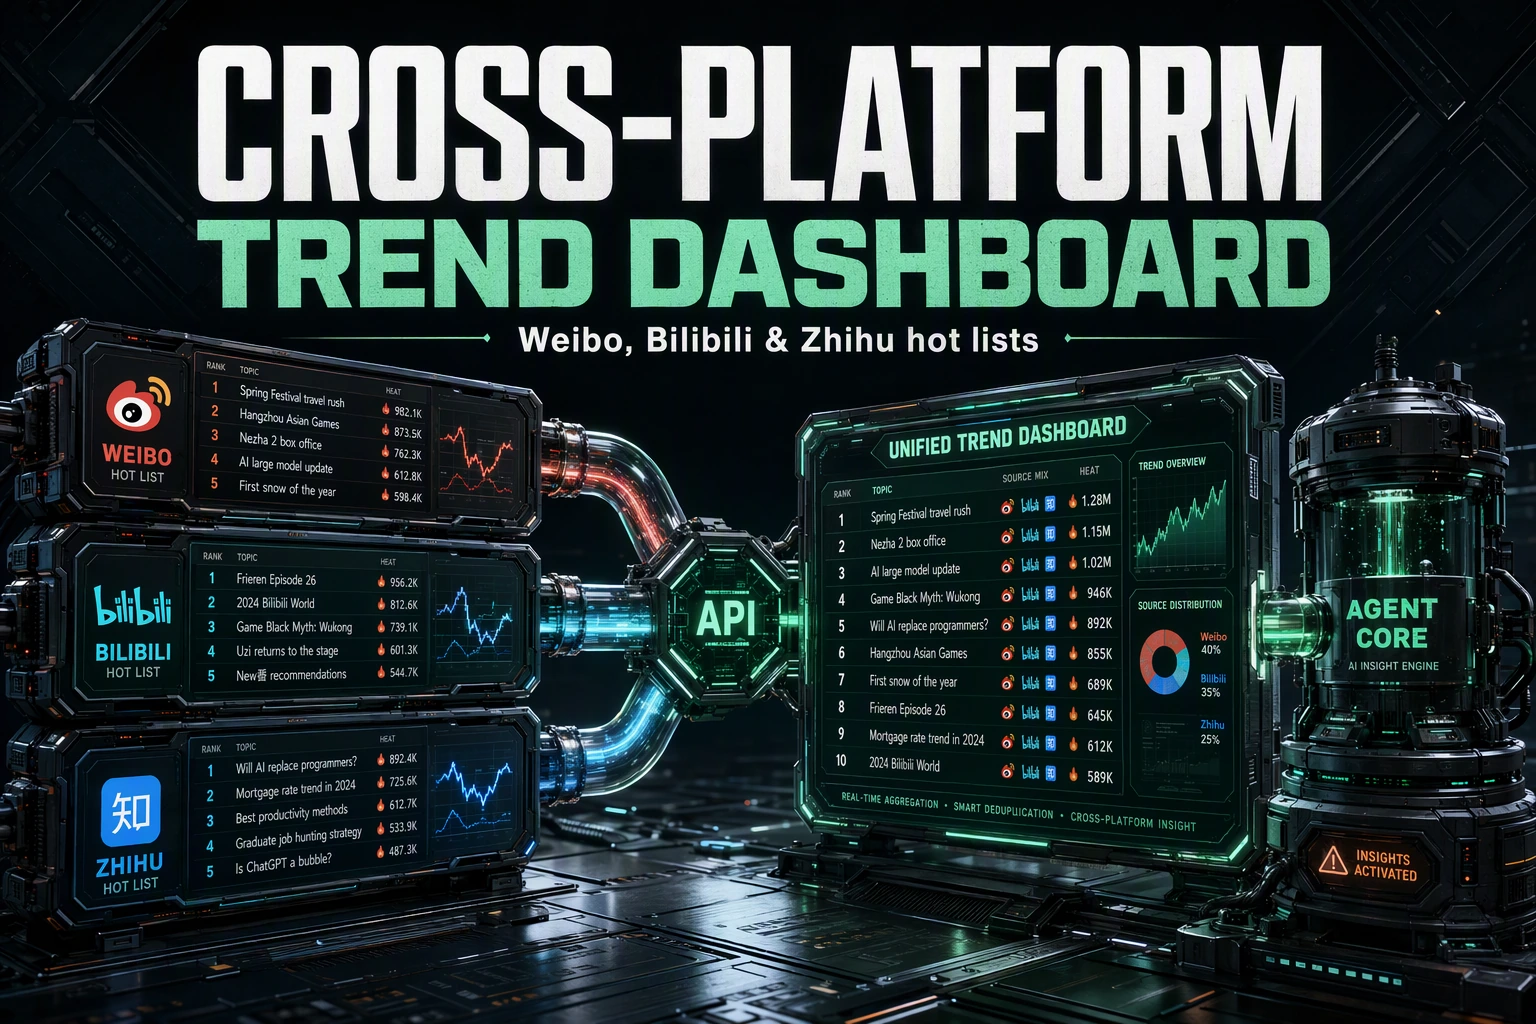
If you track Chinese internet trends, you watch more than one board: Weibo’s hot search for breaking news and celebrity chatter, Bilibili’s for video culture, and Zhihu’s for what people are asking and debating. Reading each one usually means a different scraper and a different data shape. This tutorial builds one cross-platform trend dashboard by reading all three boards through the SandBase API and normalizing them into a shared shape — one SandBase key, no logins. Each endpoint reference guarantees the response envelope (id, status, model, and outputs[0].data); the per-platform business fields shown below are illustrative structure, not a guaranteed schema, so confirm them against a live response.
For the per-platform tours, see the Weibo, Bilibili, and Zhihu hubs. This piece is the applied cross-platform workflow.
Key takeaway
- Read three hot lists —
weibo/web-v2/hot-search,bilibili/web/hot-search,zhihu/web/hot-list— and normalize them into one{ platform, rank, title, score }shape.- Every call is
POST /v1/api/<vendor>/<path>with oneSANDBASE_API_KEY; responses share the{ id, status, model, outputs }envelope.- Each platform nests its list differently, so the work is a small per-platform adapter, not three separate clients.
- Public, read-only data only; there is no login on your side.
The three boards at a glance
| Platform | Endpoint | List path | Title / score fields |
|---|---|---|---|
weibo/web-v2/hot-search | data.realtime | word / num | |
| Bilibili | bilibili/web/hot-search | data.data.trending.list | keyword / heat_score |
| Zhihu | zhihu/web/hot-list | data.data[].target | target.title / detail_text |
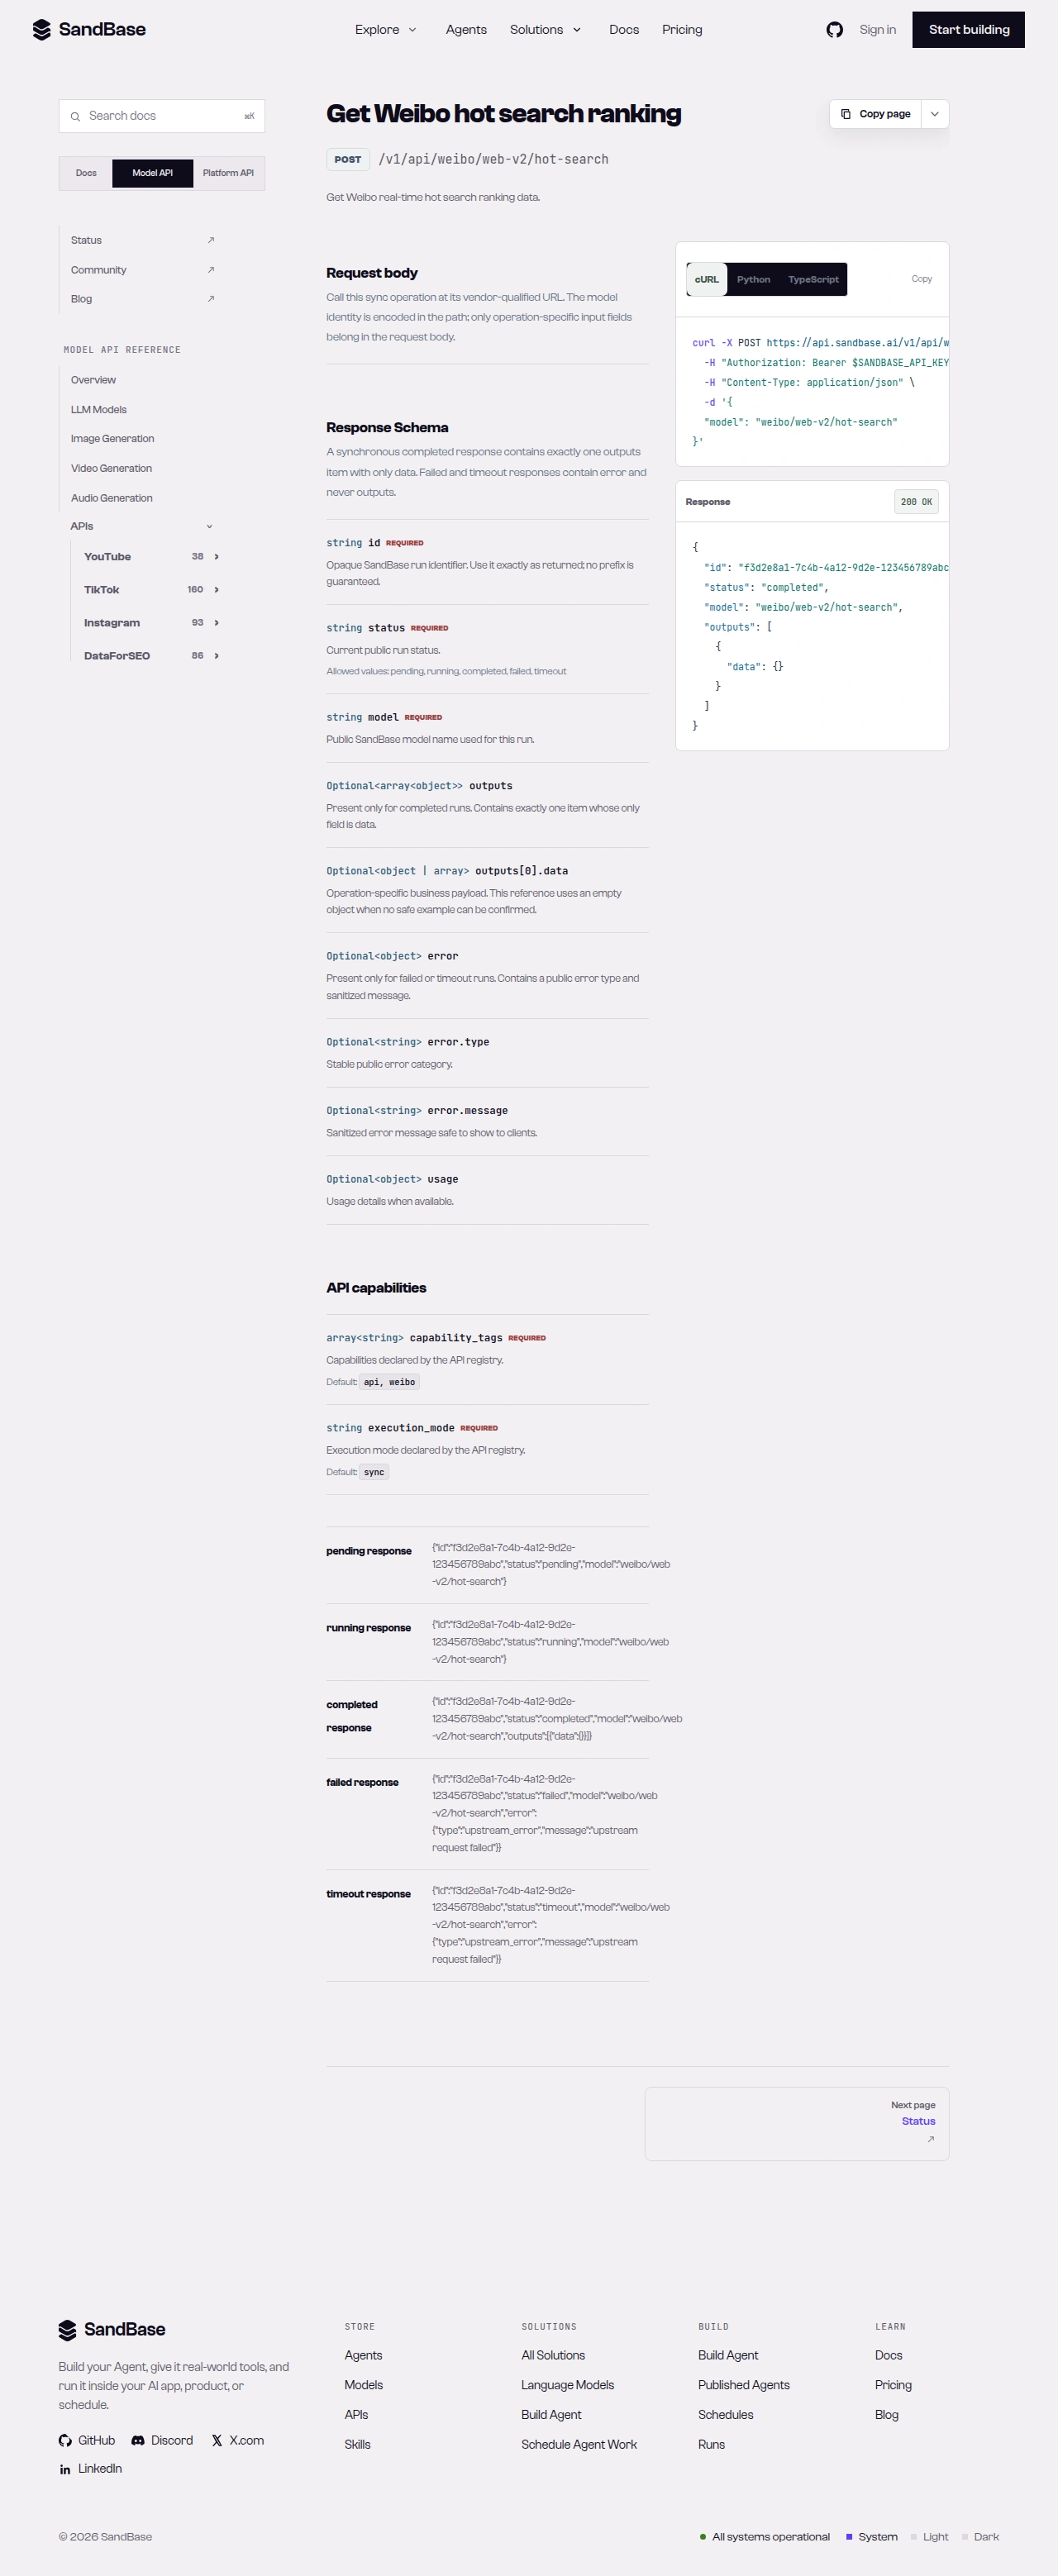 The endpoint API reference is the source of truth for each parameter name and response path.
One helper, three boards
Start with a shared helper that branches on status, then read each board and map it into a common shape. Because each platform nests its list at a different path, each gets a tiny adapter:
import os
import requests

BASE = "https://api.sandbase.ai/v1/api"
HEADERS = {
    "Authorization": f"Bearer {os.environ['SANDBASE_API_KEY']}",
    "Content-Type": "application/json",
}


def call(path: str, payload: dict) -> dict:
    resp = requests.post(f"{BASE}/{path}", headers=HEADERS, json=payload, timeout=90)
    resp.raise_for_status()
    body = resp.json()
    if body.get("status") != "completed":
        raise RuntimeError(body.get("error", {}).get("message", "request did not complete"))
    # Only the envelope is guaranteed; read outputs[0].data defensively.
    return (body.get("outputs") or [{}])[0].get("data", {})


# Each adapter's nested paths (realtime/word/num, trending.list/keyword/heat_score,
# target.title/detail_text) are illustrative structure, not a guaranteed schema,
# so read them defensively with .get().
def weibo_board():
    data = call("weibo/web-v2/hot-search", {})
    return [{"platform": "weibo", "rank": i, "title": it.get("word"), "score": it.get("num")}
            for i, it in enumerate(data.get("realtime", []))]


def bilibili_board():
    # `limit` is a required integer for this endpoint.
    data = call("bilibili/web/hot-search", {"limit": 20}).get("data", {})  # upstream { code, data }
    trending = data.get("trending", {}).get("list", [])
    return [{"platform": "bilibili", "rank": i, "title": it.get("keyword"), "score": it.get("heat_score")}
            for i, it in enumerate(trending)]


def zhihu_board():
    data = call("zhihu/web/hot-list", {}).get("data", [])
    return [{"platform": "zhihu", "rank": i, "title": it.get("target", {}).get("title"), "score": it.get("detail_text")}
            for i, it in enumerate(data)]
Each adapter reads one board and emits the same { platform, rank, title, score } record. The source field paths are illustrative structure rather than a guaranteed schema — confirm them against a live response, since the boards change constantly and payload shapes can shift.
Build the dashboard
Merge the three boards into one ranked feed:
dashboard = weibo_board() + bilibili_board() + zhihu_board()
for row in dashboard:
    print(f"[{row['platform']:8}] #{row['rank']:>2} {row['title']}  ({row['score']})")
Now you have a single list you can store, diff against the previous run, or feed to an agent. Note the score fields are not directly comparable across platforms — Weibo’s num and Bilibili’s heat_score are integers on different scales, and Zhihu’s detail_text is a human-readable string like a heat label. Keep them per-platform and compare rank movement within a platform rather than raw scores across platforms.
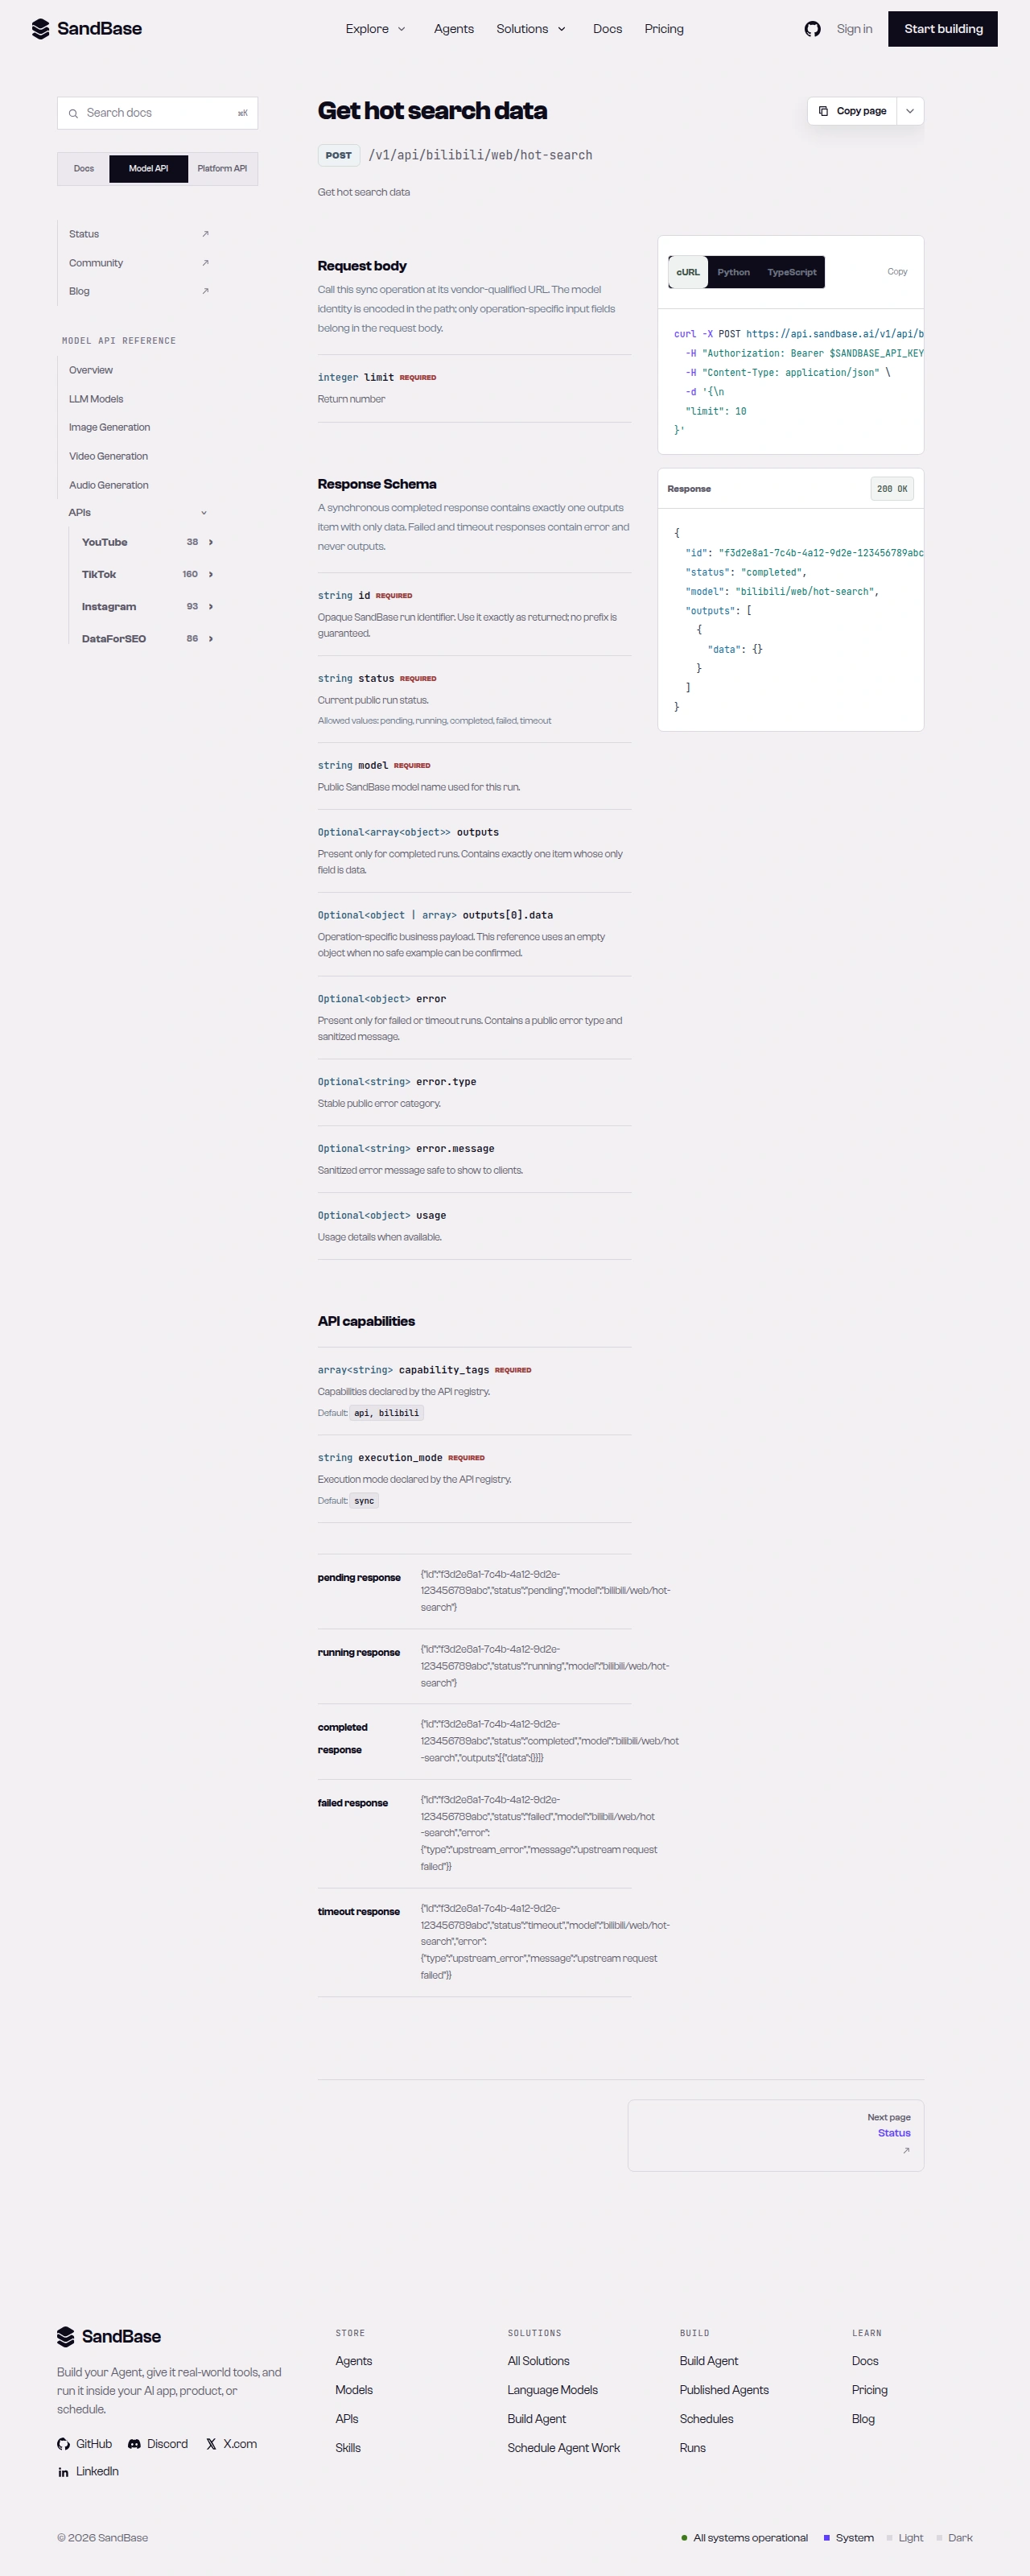 Each platform’s hot-list reference documents the exact list path and fields.
An illustrative merged record
Here is an illustrative shape for one normalized row — treat the values as examples and confirm the source fields against a live response:
{
  "platform": "weibo",
  "rank": 0,
  "title": "…",
  "score": 1172365
}
Because all three reads pass through the same call helper and the same { id, status, model, outputs } envelope, the only platform-specific code is the small unwrap in each adapter. Adding a fourth board later — or swapping one out — is a localized change.
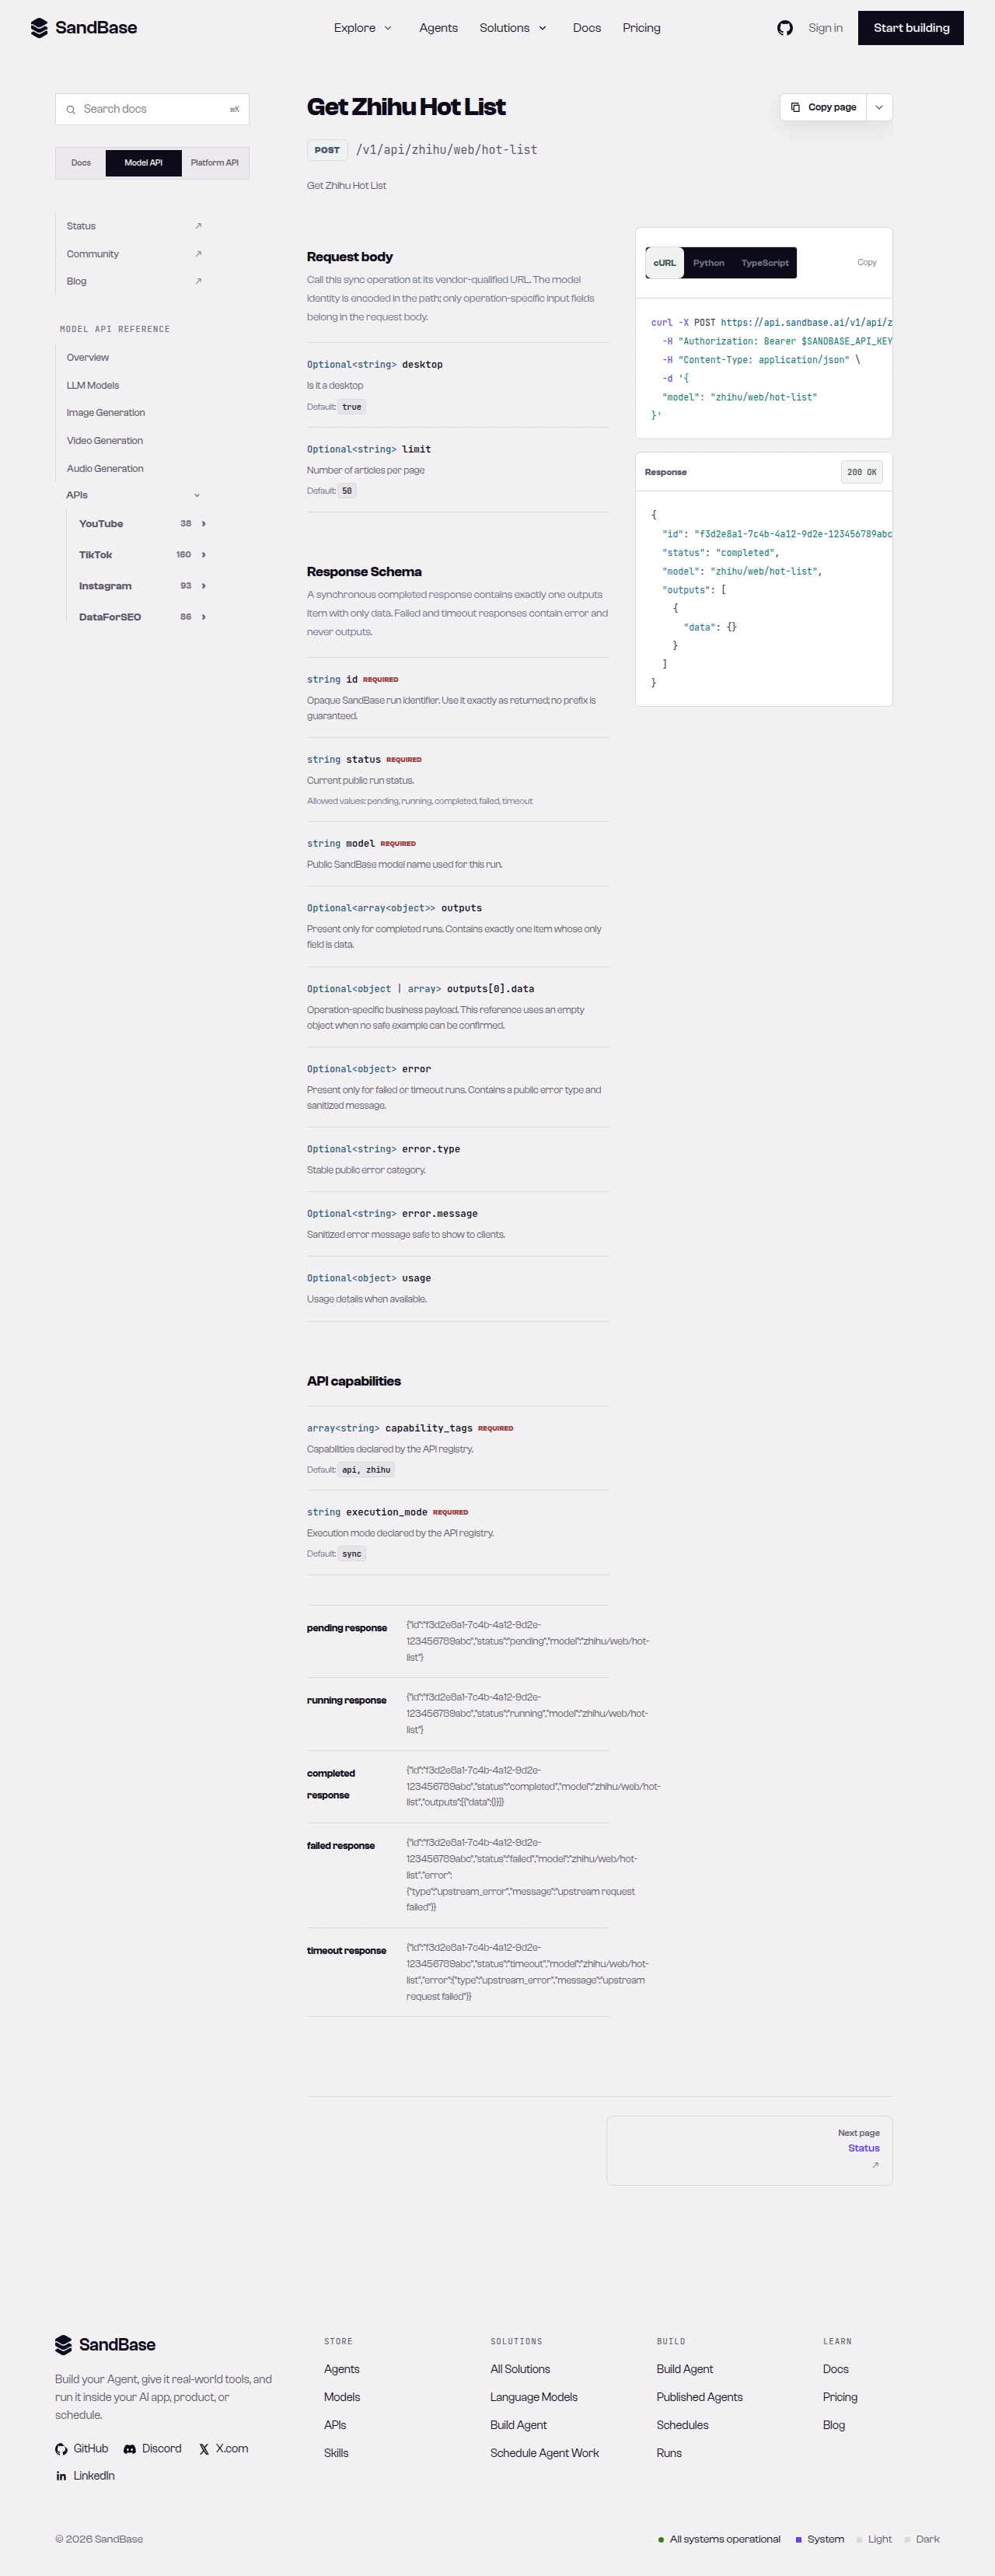 Read each endpoint’s schema; list nesting differs by platform.
Handling the rough edges
- Each platform nests differently. Weibo’s list is
data.realtime, Bilibili’s is under the upstreamdata.data.trending.list, and Zhihu wraps each item’s question undertarget. Keep one adapter per platform. - Scores are not cross-comparable. Compare rank movement within a platform over time; do not rank platforms against each other by raw score.
- Branch on
status. Afailedortimeoutrun carrieserrorand nooutputs. Thecallhelper already enforces this. - Respect rate limits. As a client-side resilience measure, retry with backoff on transient errors such as HTTP 429, and space out scheduled runs.
- Public data only. No login, posting, or private content on any platform.
Why run this at the API layer
Building a cross-platform dashboard by scraping means maintaining three fragile scrapers with three different failure modes. Reading through one API means three short adapters over one consistent envelope, one key instead of three cookie jars, and one place to add retries and logging. Because every board normalizes to { platform, rank, title, score }, each scheduled pass drops cleanly into a table you can diff against the last one — new topics entering a board, rank movement, and topics that trend across more than one platform at once. Turning that into insight — clustering topics, detecting cross-platform spikes — is a separate analysis step you run on top of the collected data.
Scheduling it
Run on a cadence and persist each pass so you can see movement, not just a snapshot:
import time, json

def snapshot():
    return weibo_board() + bilibili_board() + zhihu_board()

while True:
    rows = snapshot()
    with open(f"trends-{int(time.time())}.json", "w") as f:
        json.dump(rows, f, ensure_ascii=False)
    # diff against the previous snapshot to find new entries and rank moves
    time.sleep(1800)  # every 30 minutes; space runs out to respect rate limits
Store each snapshot keyed by platform and title, then diff consecutive runs: titles that appear on more than one platform in the same window are your cross-platform signals, and titles climbing fast within a platform are the ones worth drilling into with that platform’s search endpoint. The dashboard is the collection layer; the ranking and clustering you build on top is where the product value is.
FAQ
Do I need a Weibo, Bilibili, or Zhihu login?
No. You authenticate to SandBase with your SANDBASE_API_KEY. All three hot lists are public, read-only reads and need no platform account or OAuth on your side.
How do I page through each board?
Each board is a per-endpoint read: Weibo’s and Zhihu’s hot lists return their current ranking in one call, and Bilibili’s hot-search takes a required limit request parameter. Set the parameters each endpoint documents rather than expecting a shared cursor across the three.
The three responses have different shapes — how do I normalize them?
Write one tiny adapter per platform that unwraps its list path (data.realtime for Weibo, data.data.trending.list for Bilibili, data.data[].target for Zhihu) and maps it into the shared { platform, rank, title, score } row. The endpoint reference is the source of truth for each path; only the envelope is guaranteed to be uniform.
Next steps
You now have a repeatable cross-platform trend dashboard built on three public, read-only calls and one shared shape. Extend it by adding search on any platform to drill into a trending topic, or a profile read to see who is driving it.
- Platform hubs: Weibo, Bilibili, Zhihu
- Get a SandBase API key
- API references: weibo hot-search, bilibili hot-search, and zhihu hot-list