Qwen4-Max 已正式发布:官方按量计价、输出上限,以及如何在 SandBase 上调用
Qwen4-Max 已于 2026 年 11 月 16 日正式发布。新加坡官方按量 $1.50 / $4.50。SandBase 上以 alibaba/qwen4-max 调用,卡片价 $1.67 / $5.00。
2026 年 11 月 16 日,Qwen4-Max 不再是预览问题。它是 Qwen4 家族的第一个模型,按量付费已经打开,SandBase 上的 alibaba/qwen4-max 卡片也在线。今天要接一条新的生产调用,发这个 ID。预览 ID 还在倒计时里,不该当默认。
官方发布文是 Qwen4-Max: Your New Teammate Has Arrived,日期 2026/11/16,署名 QwenTeam。上下文、输出上限和新加坡免费 token 说明,以 QwenCloud 最新模型页 为准。11 月 15 日的状态文 Qwen 4 发布了吗? 和 11 月 13 日的 接入说明 留作预览档案。要不要把流量从 Qwen3.8 Max 挪走,看 Qwen4-Max 和 Qwen3.8 Max 怎么选。公开计价之后,和 Gemini 4 Carbon、GPT-6 Astra、Claude Fable 5.2 能比什么,看 11 月 16 日的旗舰对照。
先说结论
- Qwen4-Max(
qwen4-max)自 2026 年 11 月 16 日起正式发布,支持按量付费。SandBase ID 是alibaba/qwen4-max,走POST https://api.sandbase.ai/v1/chat/completions。- 官方上下文 1,000,000。非思考模式最大输出 131,072。思考加最终回答合计 262,144。预览期的 393,216 不是正式上限。
- 新加坡(国际)官方按量是每百万 token 输入 $1.50、输出 $4.50。北京与 Global 是 $1.413 / $4.24。SandBase hero 是 $1.67 / $5.00,缓存读取 $0.08,缓存写入 $2.08,没有九折。
- 思考默认开启。
reasoning_effort的默认值现在是high。预览模型qwen4-max-preview仍会在 2026 年 11 月 25 日 24:00(UTC+8)之后下线。- 官方 API 文档仍然没有参数量。这个模型不支持微调、模型部署和批量推理。
更新(2026 年 11 月 16 日): 同一天在 SandBase 上做了一组流式探测,测量了
alibaba/qwen4-max对alibaba/qwen3.8-max的首 token(TTFT)、TPOT、解码吞吐和提示缓存命中率。这是单机、单日、经网关的测量,不是官方厂商延迟。数字和方法见 Qwen4-Max 和 Qwen3.8 Max 实测:SandBase 上的首 token(TTFT)、TPOT、吞吐与缓存命中率。
11 月 16 日实际交付了什么
Qwen4-Max 是 Qwen4 家族的第一个模型。官方模型页写的输入是文本、图像、视频,输出是文本。思考默认开着。按量付费已经是正式入口。Token Plan 产品更新(页面最后更新 2026 年 11 月 16 日)写明 Personal 和 Team 也支持这个正式模型。Model Studio 新发布模型 有一条 2026-11-16 的 International 记录,QwenCloud 模型更新日志 同一天记下了 qwen4-max。
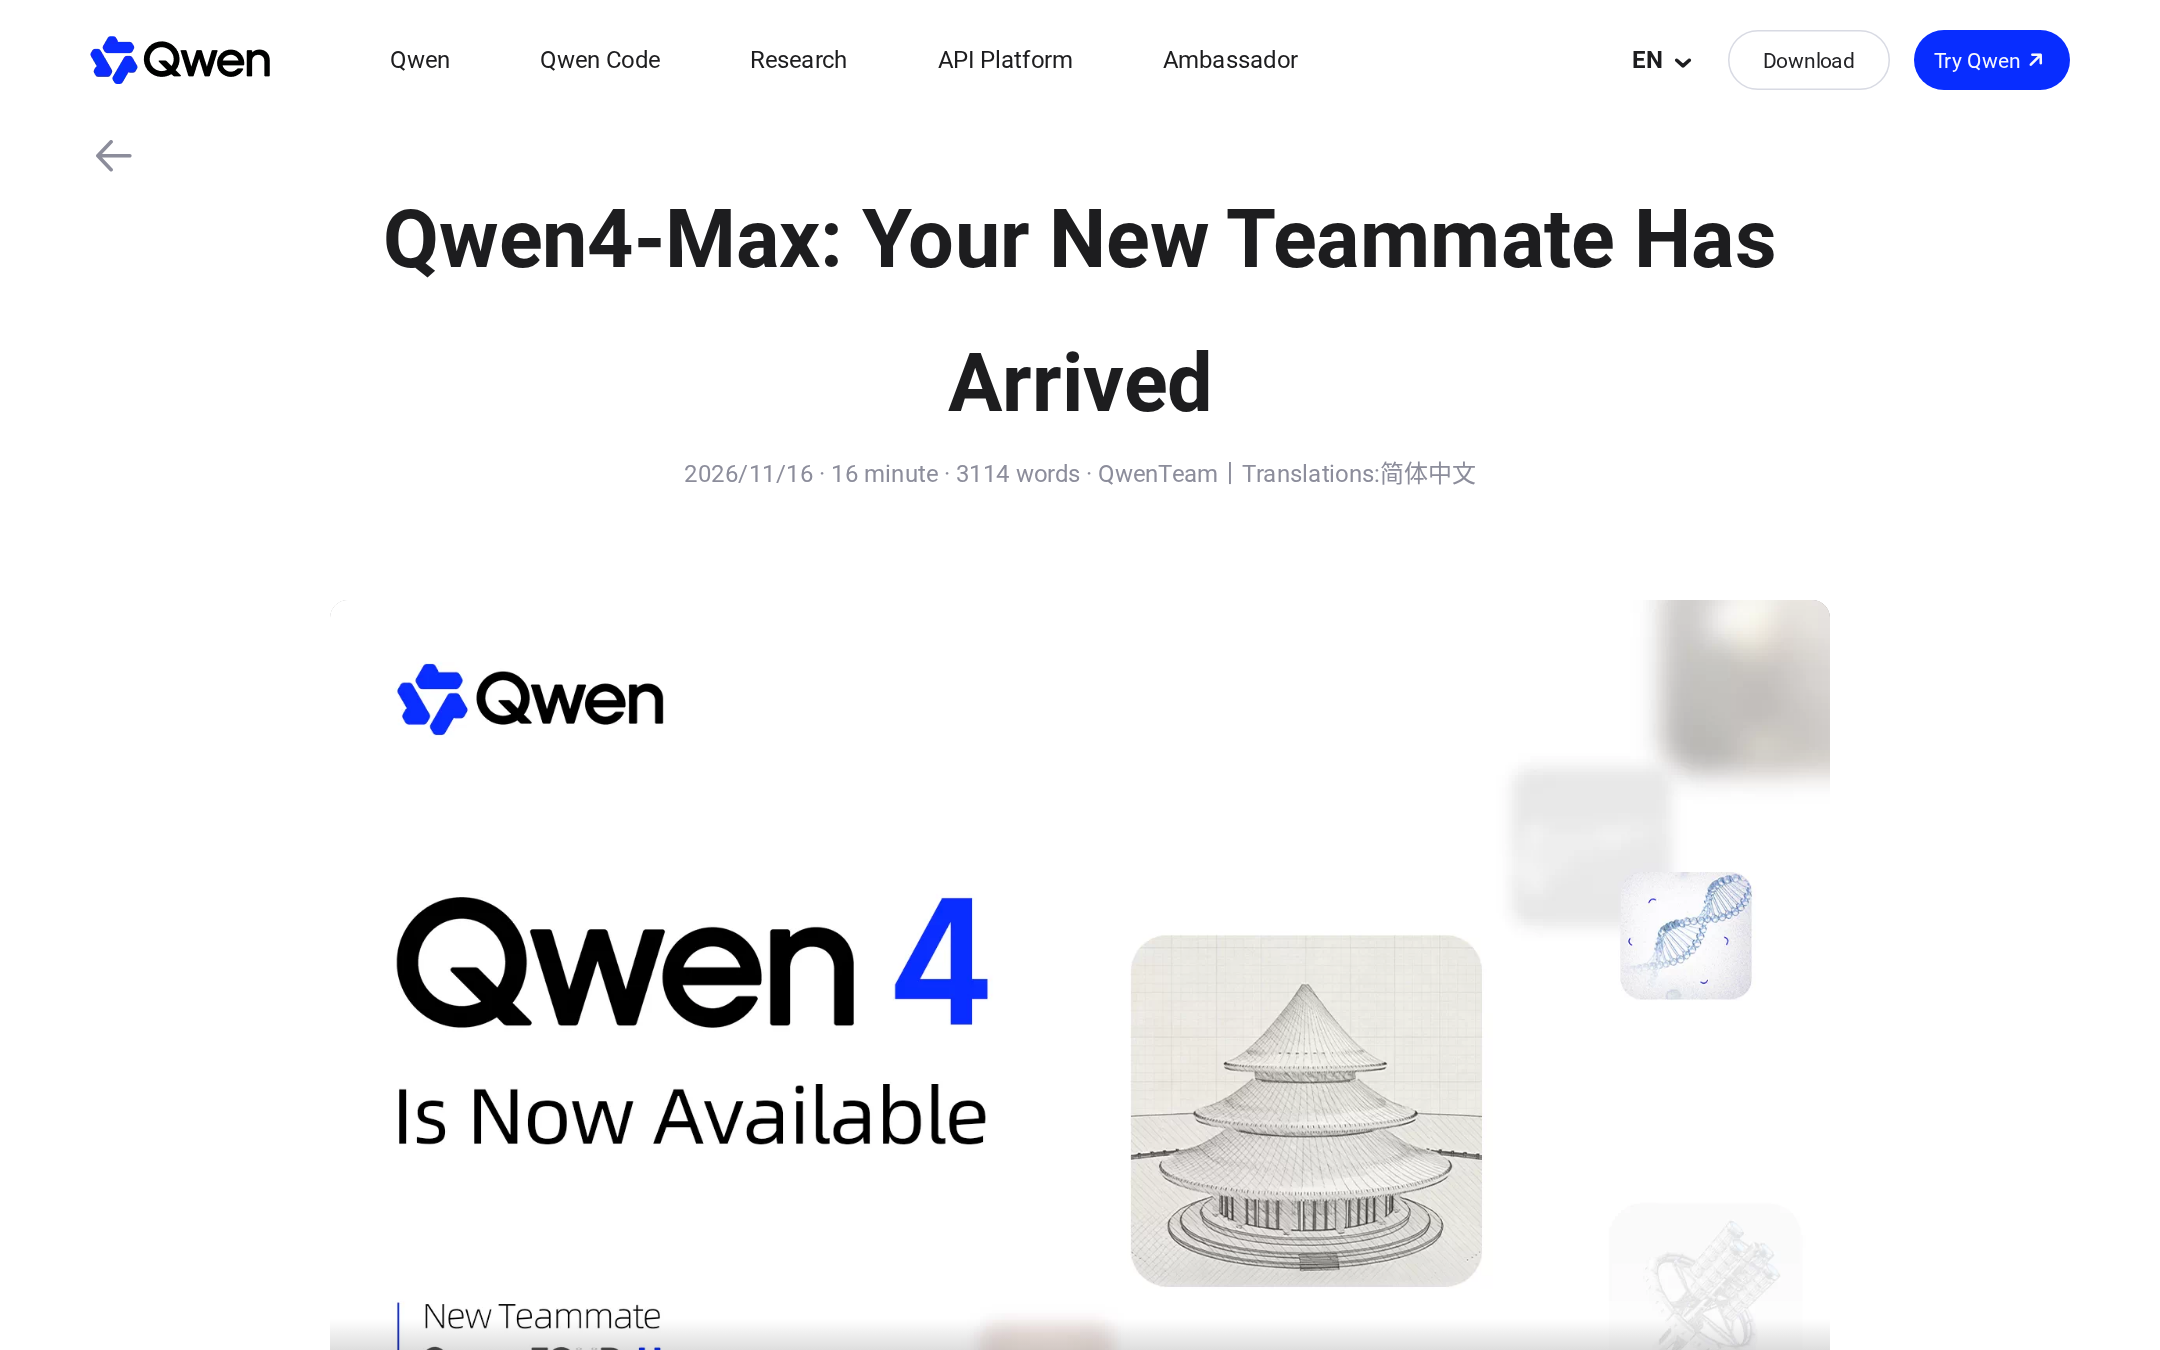
Official Qwen launch blog at qwen.ai/blog?id=qwen4-max, captured 16 Nov 2026, Asia/Shanghai. The post is titled “Qwen4-Max: Your New Teammate Has Arrived,” dated 2026/11/16, and the hero states that Qwen 4 is now available.
发布文是厂商文章,不是 API 参考。它说 Qwen4-Max 建立在新的 Qwen4 架构上,“with a 2.4-trillion-parameter backbone, native vision capabilities, and a one-million-token context window.” 预训练一节另外写了 “2.4T backbone parameters, 71B activated per token, and an additional 328B N-gram Embedding parameters”,以及 GDN + Qwen Sparse Attention(QSA)、Gated Residual 和 N-gram Embedding。这些数字属于这篇博客。阿里云 Qwen4-Max 文档 和 QwenCloud 最新模型页都在 2026 年 11 月 16 日更新过,两边都没有参数量。引用博客,就标明是博客。
同一篇写明模型已经在 QwenCloud 上可用,可以用 Token Plan,也可以用 API。它还点了 QwenWork、Qoder 和 QwenStudio。结尾是将来时:家族里更小的模型 “coming to open source”。这句话不是已上线清单。
最新模型页列出的区域:新加坡(International)、中国华北 2(北京)、法兰克福、香港、东京、美国弗吉尼亚(Global)。北京和 Global 共用一行价格。新加坡单独一行。页上列出的内置工具包括函数调用、结构化输出、网页搜索、PDF 理解、代码解释器(需要思考)、网页抓取、文搜图和图搜图、MCP、显式缓存和 CoT Summary。流式、并行工具调用、前缀补全和隐式缓存也列为支持。微调与模型部署,在该页列出的每个区域都不支持。
在 SandBase 上怎么调用
打开 Qwen4 Max。SandBase ID 是 alibaba/qwen4-max。这张卡的端点是 Chat Completions:
curl -X POST https://api.sandbase.ai/v1/chat/completions \
  -H "Authorization: Bearer $SANDBASE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model": "alibaba/qwen4-max",
  "messages": [
    {"role": "user", "content": "List the official Qwen4-Max output caps, and name which one the SandBase hero matches."}
  ]
}'
注册 会跳到登录页。建好密钥之后,按 第一次调用 文档走。请求体里的模型字符串是 alibaba/qwen4-max,不是裸的官方 ID,也不是预览 ID。
思考默认开着,除非你关掉。官方 reasoning_effort 的取值是 low、high、xhigh,默认现在是 high。medium 映射到 high,minimal 映射到 low,max 映射到 xhigh。预览期的默认是 xhigh,这里已经换了。thinking_budget 默认 131,072。preserve_thinking 默认开启。在 Chat Completions 里,enable_thinking=false 会关掉思考。max_completion_tokens 同时限制思考和最终回答。文档里的默认值是:开思考时 262,144,关思考时 131,072。如果还按短回答的习惯去卡长度,轨迹会在答案出来之前被截断。还在发预览默认 xhigh、或者把 max_tokens 当成只包可见回答的客户端,要重新看一遍。
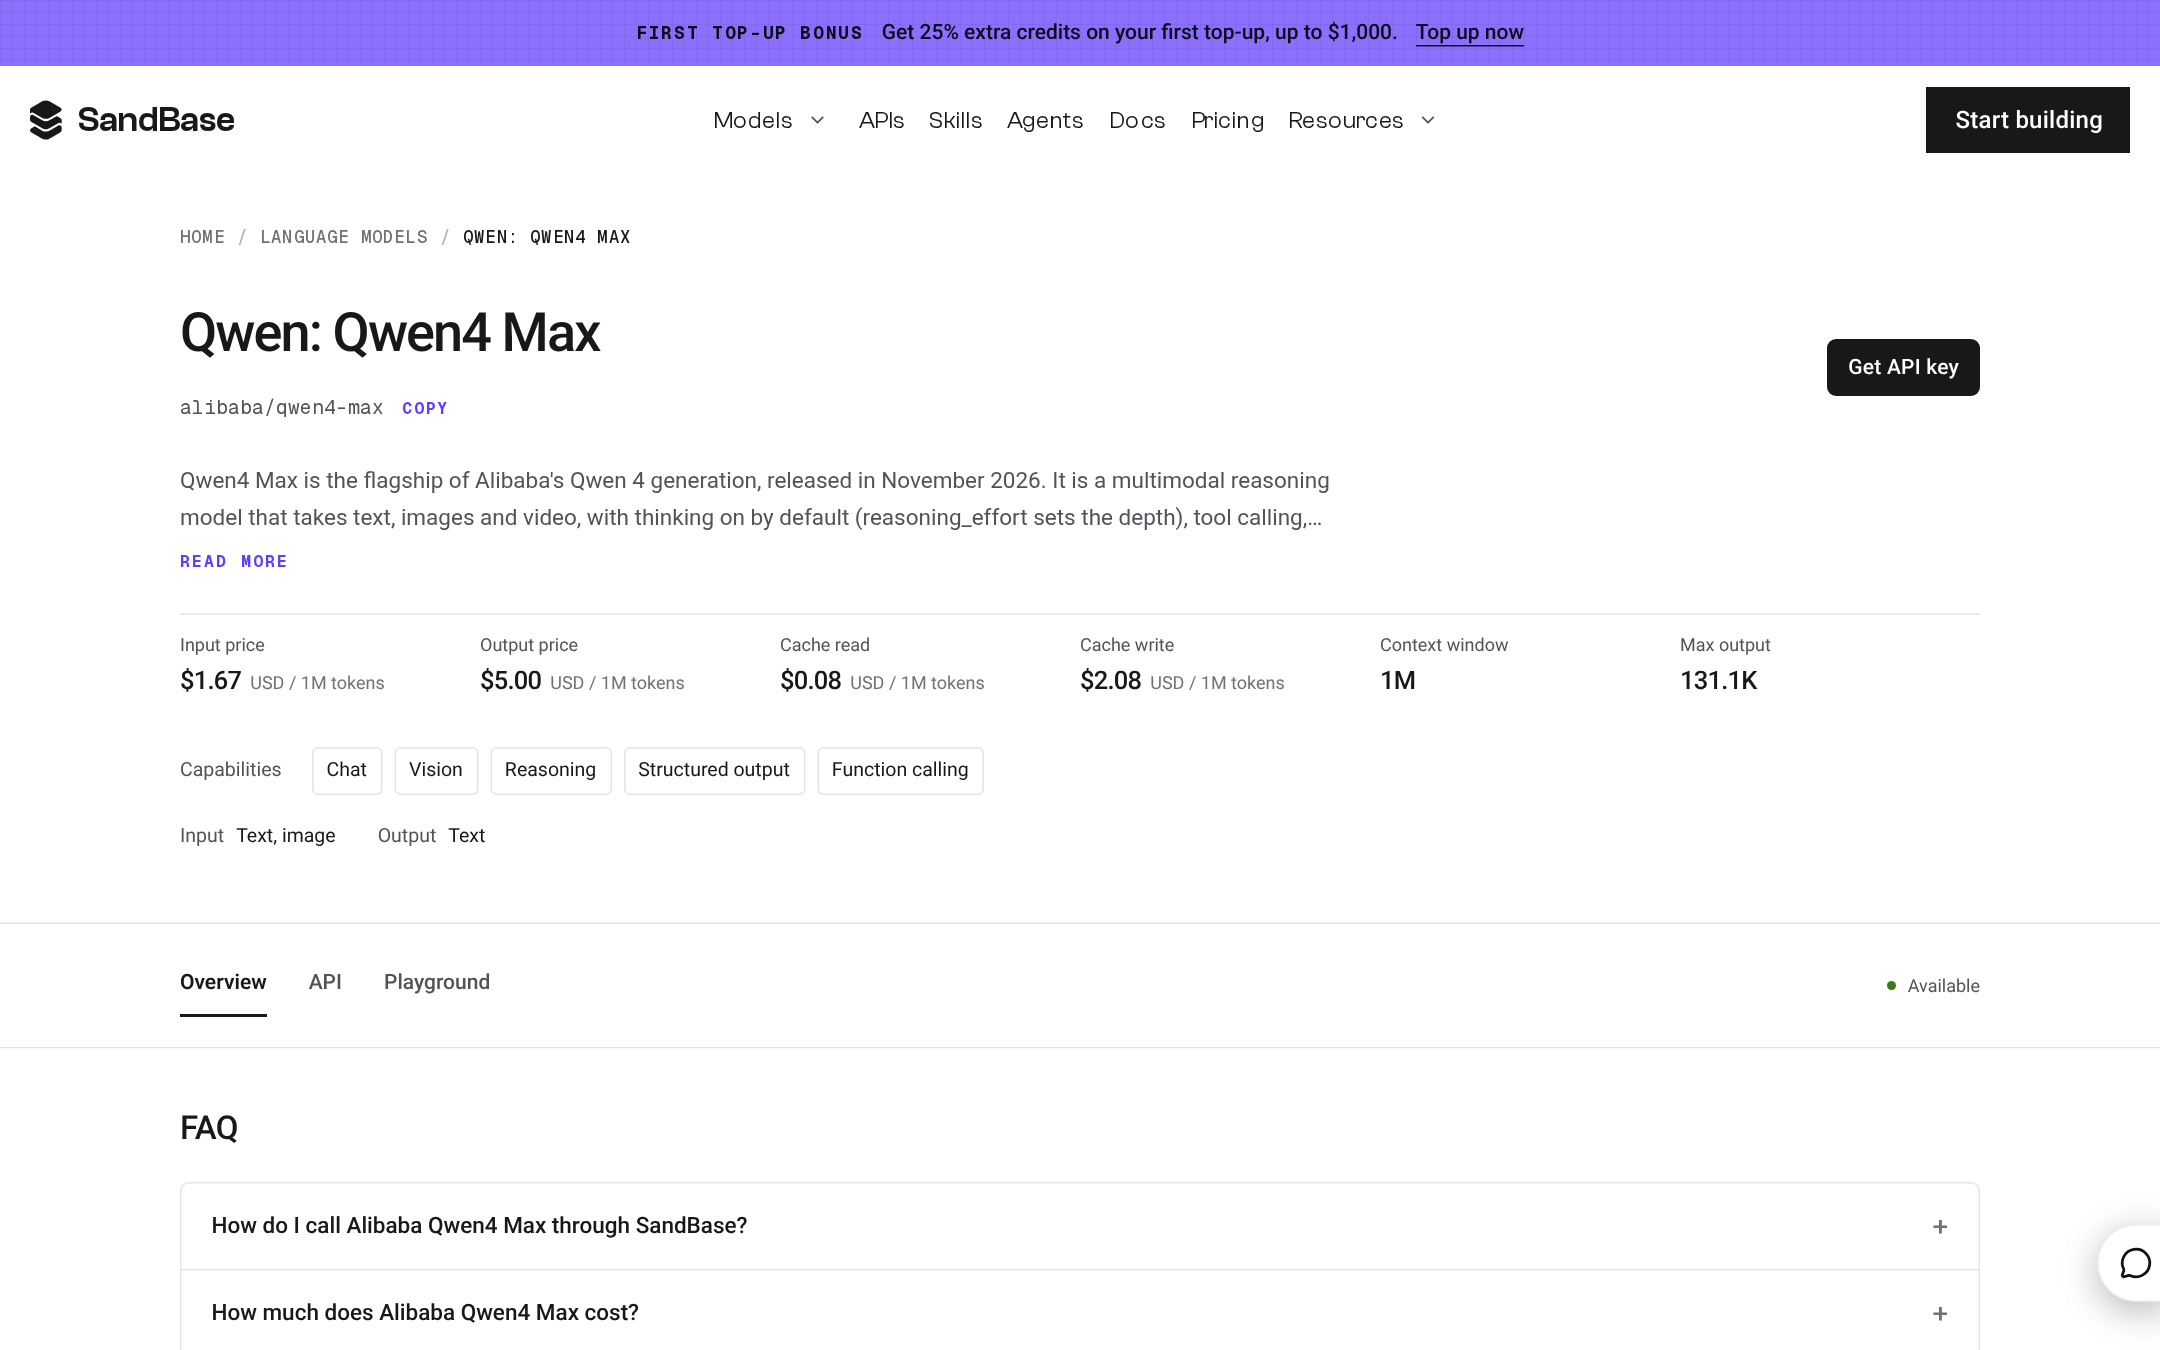
Live SandBase Qwen4 Max card at /models/alibaba/qwen4-max, captured 16 Nov 2026, Asia/Shanghai (HTML and .md both HTTP 200). Hero is $1.67 / $5.00, with cache read $0.08 and cache write $2.08 per 1M tokens, 1M context, and 131.1K max output. There is no 10% off badge. These SandBase prices are above the official Singapore list of $1.50 / $4.50, and above official Beijing / Global $1.413 / $4.24, but still below SandBase Qwen3.8 Max at $1.80 / $5.40. The card hero max output of 131.1K matches the official non-thinking cap; the card description still incorrectly says “up to 393K output tokens shared by thinking and the answer,” which is a preview leftover, not the official GA limit.
卡片标题是 “Alibaba Qwen4 Max API: Pricing & Specs | SandBase”。能力列表:chat、vision、reasoning、structured output、function calling。Hero 上下文 1M,最大输出 131.1K。Schema 输入价是 1.666667,也就是 hero 上的 $1.67。没有划线标价,没有九折标记。这张卡在 sitemap 和 llms-full.txt 里。
如果还没准备好把 agent 重调到新的默认力度,调用先留在 Qwen3.8 Max。那张 hero 仍是 $1.80 / $5.40,标价 $2 / $6 的九折,缓存读取 $0.23,缓存写入 $2.25。它比 Qwen4-Max 的 SandBase 标价更高,也是已经跑通的基线。切换标准在上面那篇对照里。
官方上限,以及 393K 的残留
上限先读最新模型页,再读卡片 hero。还在写 393K 的句子,不要当成正式规格。
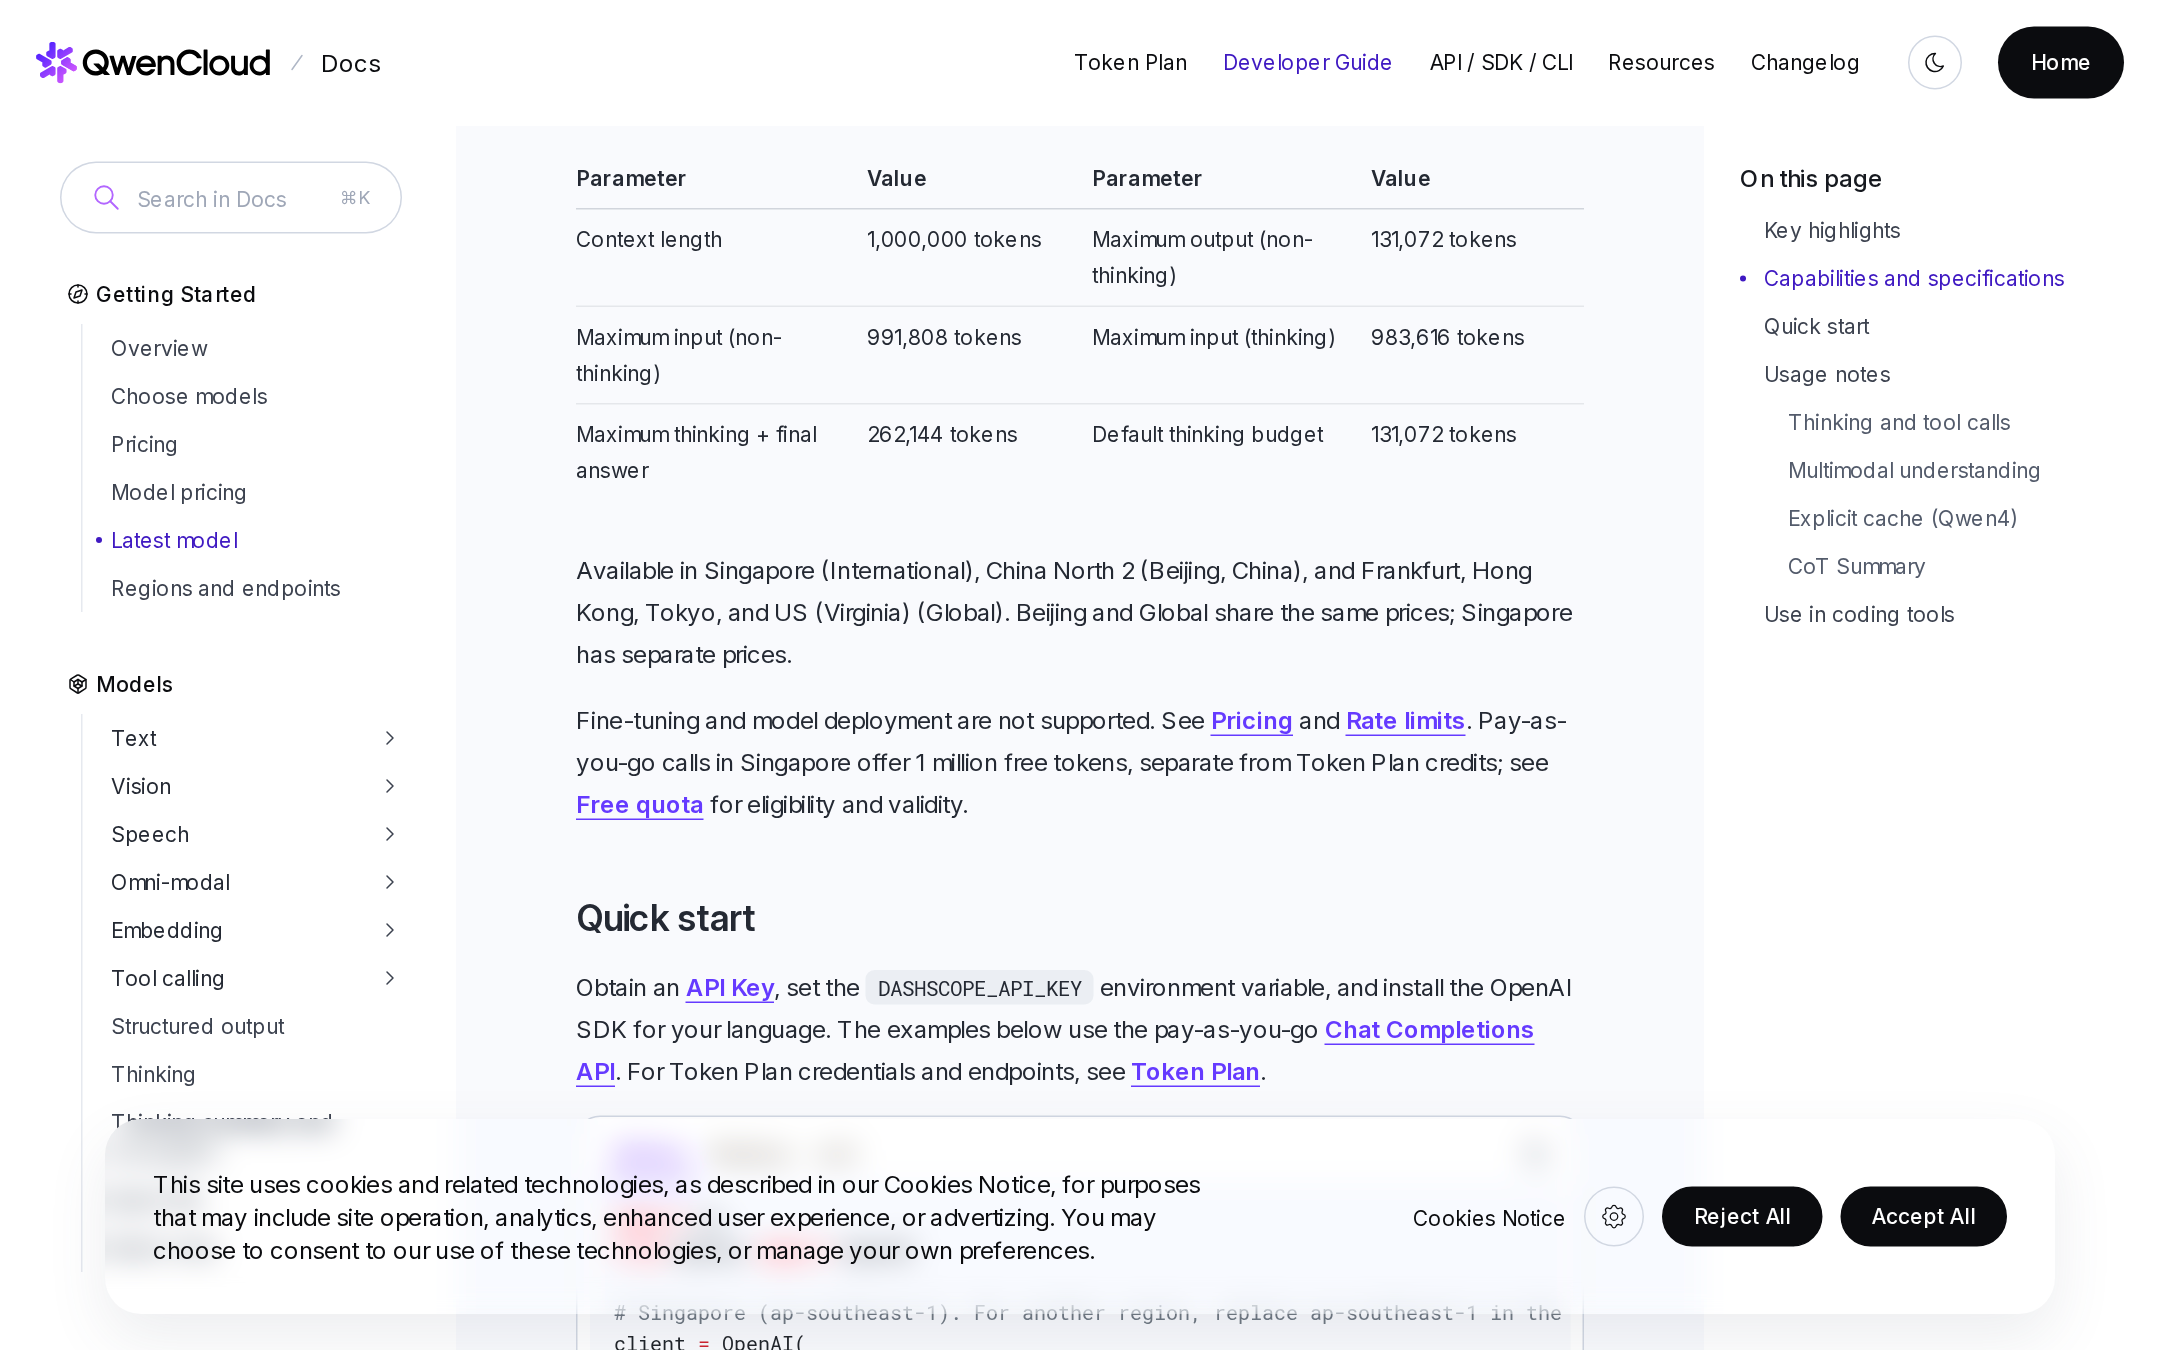
Official QwenCloud latest-model page as of 16 Nov 2026, Asia/Shanghai. Official GA limits are 1,000,000 context, 131,072 maximum output (non-thinking), and 262,144 maximum combined thinking plus final answer. The same page states that fine-tuning and model deployment are not supported, and that pay-as-you-go calls in Singapore offer 1 million free tokens. (A site cookie banner is visible at the bottom of this capture and does not cover the limits table.)
| 上限 | 正式发布后的官方值 |
|---|---|
| 上下文 | 1,000,000 |
| 最大输出,非思考 | 131,072 |
| 思考 + 最终回答合计 | 262,144 |
| 最大输入,非思考 | 991,808 |
| 最大输入,思考 | 983,616 |
| 默认思考预算 | 131,072 |
默认 reasoning_effort | high |
SandBase hero 的 131.1K 对得上官方非思考上限。它没有印出 262,144 的合计天花板。客户端如果开着思考,按 262,144 来留预算,并确认你调用的那一端接受这么高的完成上限。卡片描述仍写着 “up to 393K output tokens shared by thinking and the answer”。这是预览残留,不是正式上限,也和同一张卡的 hero 不一致。
QwenCloud 市场页 仍显示 Max Output 393K、Max Output (Thinking) 393K、Max Reasoning 262K,还有一块 Batches。把那一页当成冲突。权威上限是最新模型页、阿里云 Qwen4-Max 页,以及 2026 年 11 月 16 日更新的 文本生成与视觉理解 表。那张表把 qwen4-max 列为优先质量时的推荐模型,最大输出写的是 “131,072 (Non-thinking); 262,144 (thinking + output)”,上下文 1M,单图最大 16M 像素,视频最长 2 小时。qwen4-max-preview 和 393,216 已经不在这张表里。
qwen4-max 不支持批量推理。阿里云模型页对北京、新加坡,以及列出的每个 Global 区域(法兰克福、弗吉尼亚、东京、香港)都是这么写的。QwenCloud 最新模型页写 “Batch inference: Not supported”,没有区域例外。价格页上那条 “Batch API 按实时价格 50%” 是通用计费说明,不是这个模型接受批量任务的声明。
官方标价和 SandBase 卡片
开思考和关思考用同一单价。没有按输入长度分档。思考 token 按输出计费,官方标签是 “Output (thinking + answer)”。官方页面常印 $1.5 和 $4.5,就是 $1.50 和 $4.50。
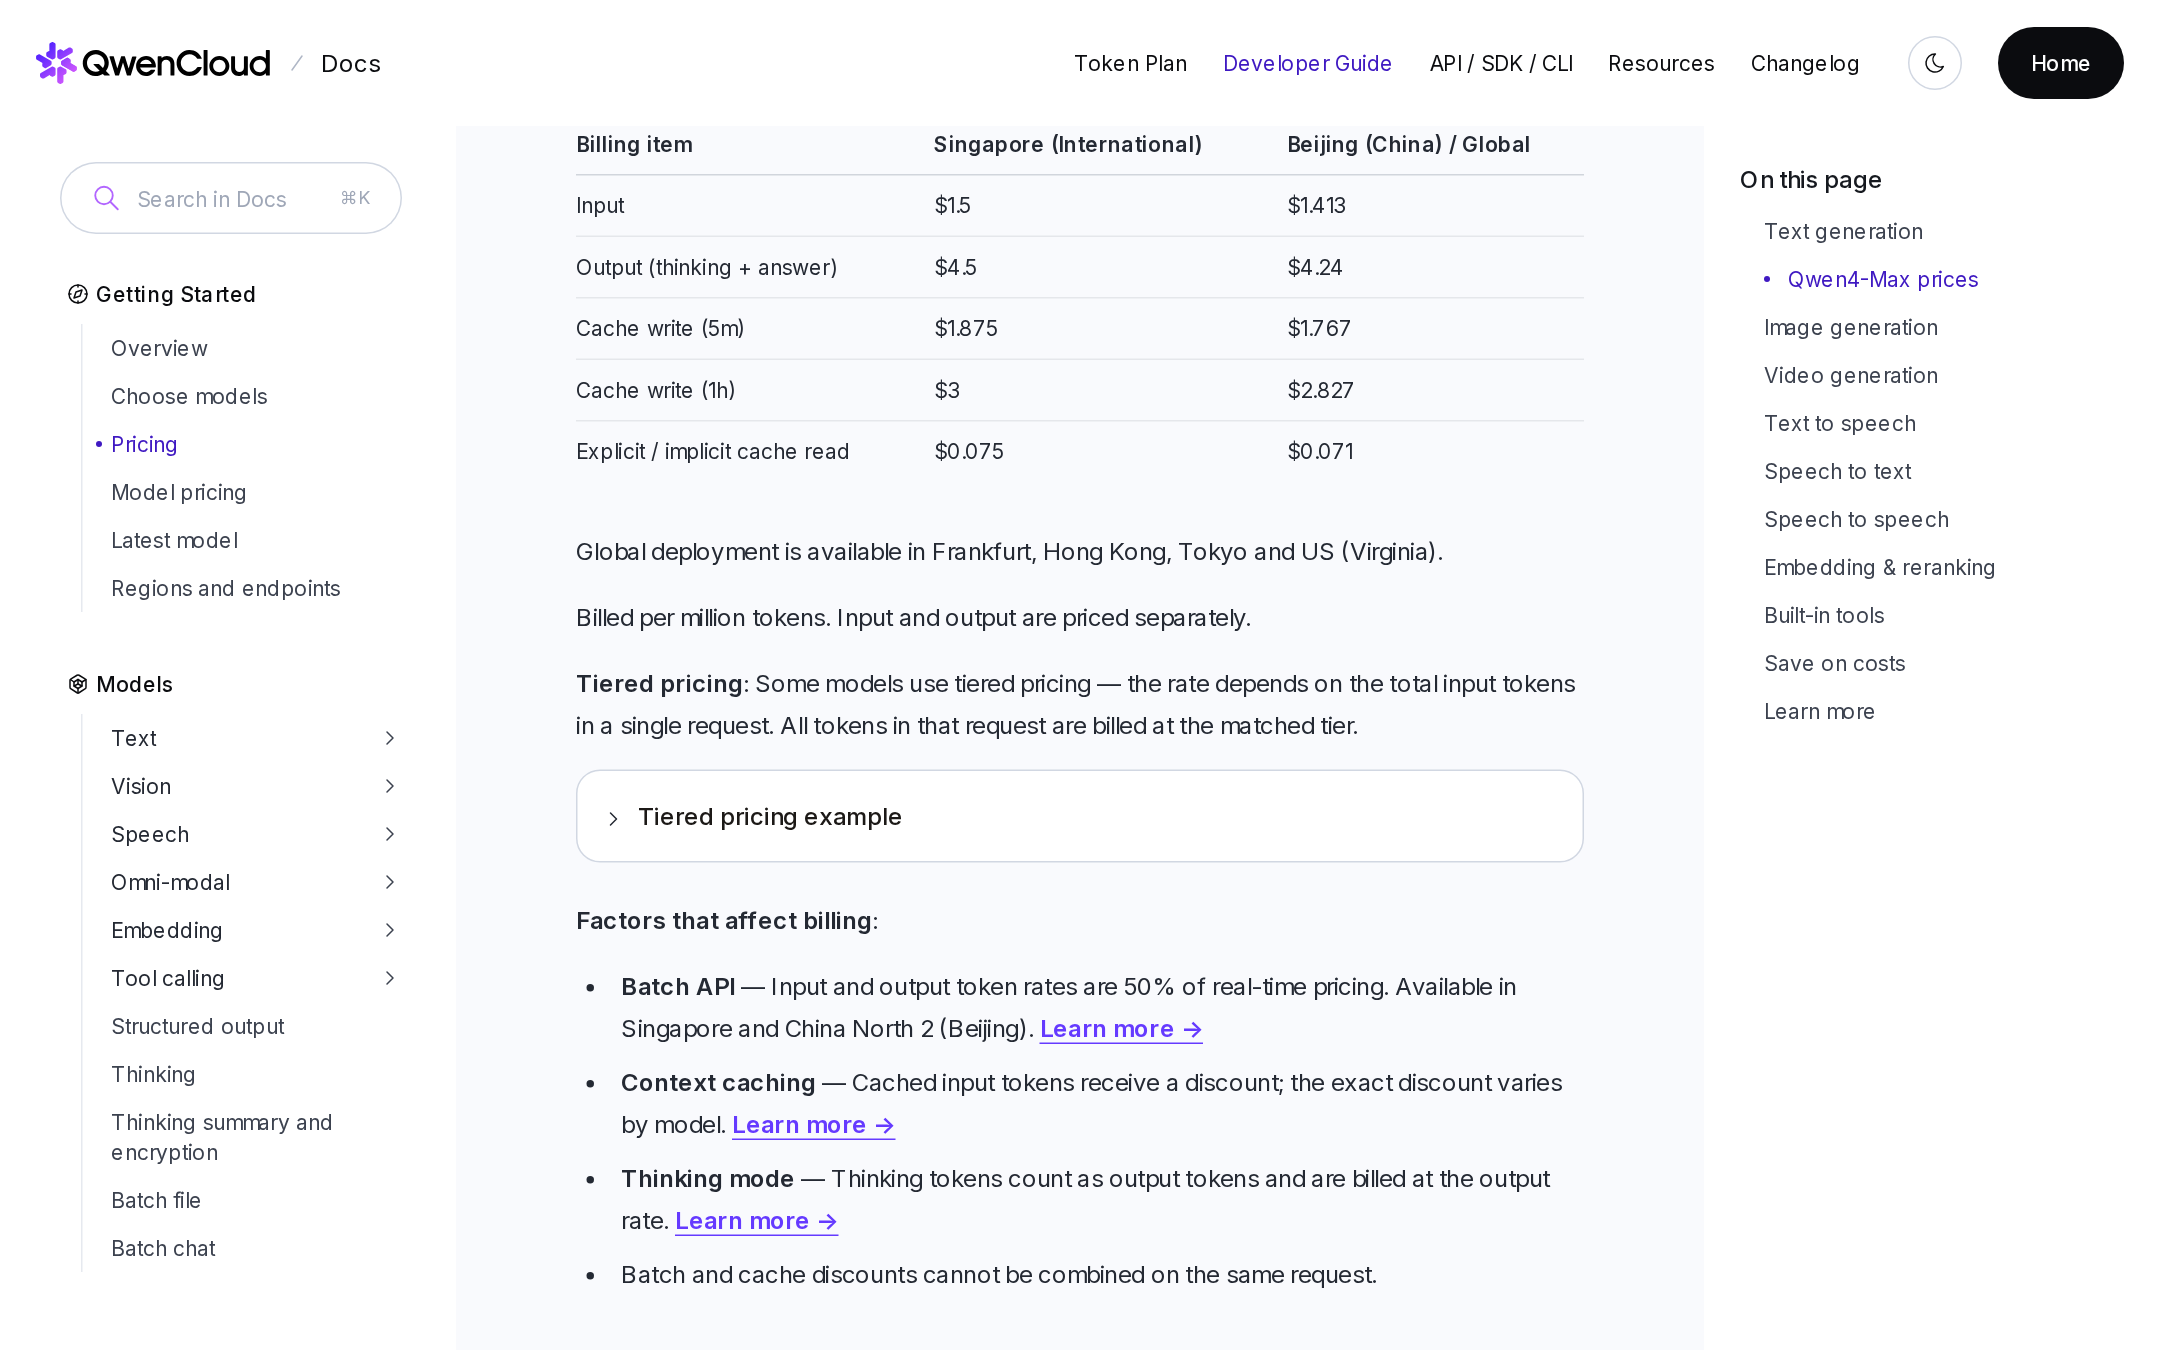
Official QwenCloud pricing page, captured 16 Nov 2026, Asia/Shanghai. Singapore (International) list is $1.5 / $4.5 per 1M tokens (the page prints $1.5 / $4.5, equivalent to $1.50 / $4.50), with cache write $1.875 (5m) / $3 (1h) and cache read $0.075. Beijing / Global is $1.413 / $4.24, with cache write $1.767 / $2.827 and cache read $0.071. The page states that thinking tokens are billed at the output rate, and that Qwen4-Max has no input-length tiers. The “Batch API 50%” bullet on this page is a general billing factor — official Qwen4-Max model pages list batch inference as not supported for this model.
| 新加坡(International) | 北京 / Global | SandBase 卡片 | |
|---|---|---|---|
| 输入 / 1M | $1.50 | $1.413 | $1.67 |
| 输出 / 1M | $4.50 | $4.24 | $5.00 |
| 缓存读取 / 1M | $0.075 | $0.071 | $0.08 |
| 缓存写入 / 1M | $1.875(5 分钟),$3(1 小时) | $1.767(5 分钟),$2.827(1 小时) | $2.08(只印一个写入价) |
| 折扣 | — | — | 没有。没有九折标记。 |
SandBase hero 高于两档官方标价,仍低于 SandBase 上的 Qwen3.8 Max($1.80 / $5.40)。qwen3.8-max 的新加坡官方标价在模型价格页上仍是 $2 / $6。不要给 Qwen4-Max 编一个 SandBase 九折,卡片上没有。
官方 QwenCloud 的新加坡按量调用提供 100 万免费 token,和 Token Plan 的额度分开。其他区域没有,最新模型页和价格页的说明都是这么写的。这是 QwenCloud 新加坡的条款。SandBase 卡片没有写免费 token,这里也不编。
有一个数字长得一样,不是一回事。发布文里 Work360 的平均每任务成本从 $4.43 降到 $1.67。那个 $1.67 是厂商在一项指名评测上的每任务成本。SandBase 的 $1.67 是卡片上每百万输入 token 的价格。数字相同,度量不同。博客里的 token 和成本说法,附上评测名字之后,写在 切换那一篇。
预览仍是一条截止日期
qwen4-max-preview 还在。官方 Token Plan 更新仍把预览窗口写成 2026 年 11 月 11 日 10:00 到 11 月 25 日 24:00(UTC+8),之后预览模型下线。SandBase 上的预览卡 Qwen4 Max Preview 在 11 月 16 日仍是 $2.00 / $6.00,缓存读取 $0.25,缓存写入 $2.50。Hero 印的上下文是 N/A,最大输出 131.1K。同一页的 playground 组件还印着 “1M context”。以 hero 为准:上下文是 N/A。不要替 hero 填一个它没印出来的 SandBase 上下文。描述里仍提到 393K 输出。这张预览卡不在 sitemap 里,也不在 llms-full.txt 里。
生产流量走 alibaba/qwen4-max。预览卡是警告,不是新客户端的起点。Token Plan 的历史接法留在 11 月 13 日的接入说明。
仍然未知的部分
官方文档没有把 Qwen4-Plus、Qwen4-Flash 或 Qwen4-27B 列成可用 API。发布文里 “coming to open source” 是将来时。SandBase 上没有这些名字的在售卡片,这篇也不编 URL。Qwen4-Max-Prime 同样不在已交付名单里。
Qwen 目录 返回 HTTP 200,标题仍是 “Qwen API: Alibaba Qwen3.8, 3.7 and Open-Weight Models | SandBase”。Hero 阵容仍是 Qwen3.8 Max、27B、Omni Flash 和 Qwen3.7 各档。页面没有提到 Qwen4。这是过期的目录页,不是模型缺失的证据:单卡在线,sitemap 和 llms-full.txt 都收了它。
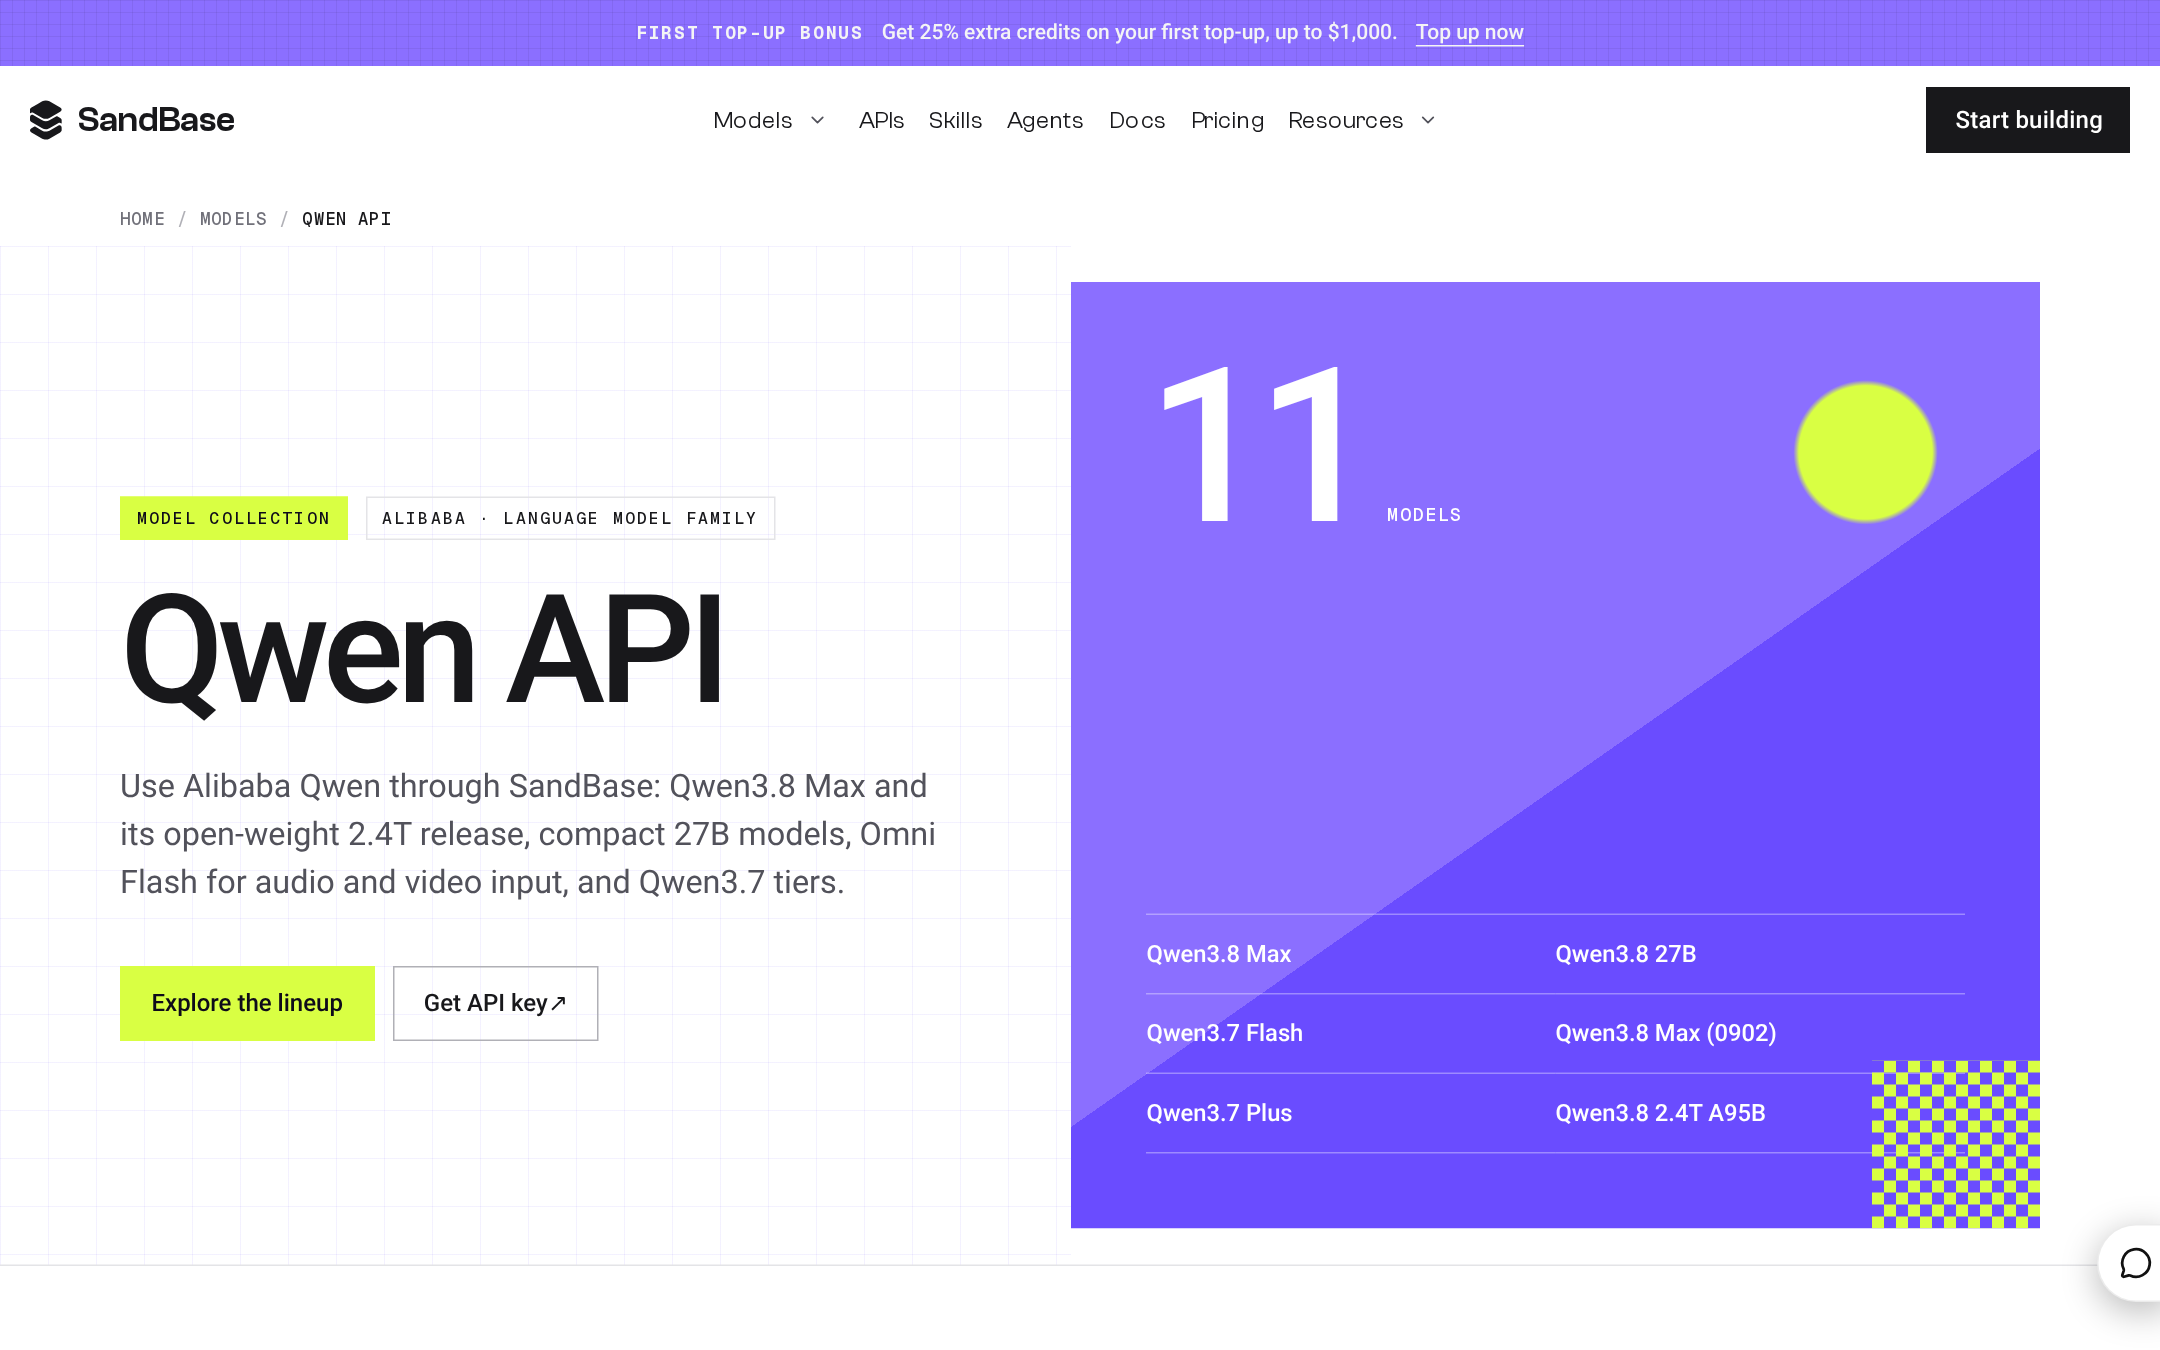
Live SandBase Qwen hub at /models/qwen, captured 16 Nov 2026, Asia/Shanghai. The page title and hero lineup are still Qwen3.8 / Qwen3.7 — they do not yet mention Qwen4-Max, even though the individual Qwen4-Max card is live and listed in the sitemap and llms-full.txt. Use this only to disclose the stale hub, not as a reason to say the model is missing from SandBase.
官方模型页上同样不支持的还有:微调、模型部署、批量推理。官方 Qwen4-Max 没有声称音频输入。任务需要音频时,SandBase 上仍走 Qwen3.8 Omni Flash。
已确认与不要编
| 2026 年 11 月 16 日已确认 | 不要编 |
|---|---|
正式发布日期、官方 ID qwen4-max、按量已开 | 给 Qwen4-Max 编一个 SandBase 九折 |
| 官方上限 1,000,000 / 131,072 / 262,144 | 把 393,216 当成正式上限 |
| 新加坡 $1.50 / $4.50;北京与 Global $1.413 / $4.24 | 把通用 Batch API 50% 套到这个模型上 |
思考默认开;reasoning_effort 默认 high | 已上线的 Qwen4-Plus、Qwen4-Flash、Qwen4-27B 或 Qwen4-Max-Prime 卡片 |
SandBase alibaba/qwen4-max 为 $1.67 / $5.00,缓存 $0.08 / $2.08 | SandBase 免费 token,或给写着 N/A 的预览 hero 编一个上下文 |
| 预览保留到 2026 年 11 月 25 日 24:00(UTC+8) | 把参数量写成 API 文档里的数字 |
Work360 和 Terminal-Bench 的数字,只能作为官方发布文上的说法引用,并且带上评测名字。它们不是 SandBase 的测量。
常见问题
SandBase 上发哪个 ID?
alibaba/qwen4-max,端点 POST https://api.sandbase.ai/v1/chat/completions。官方 API ID 是 qwen4-max。预览 ID 是 qwen4-max-preview,新的生产不要从那里开始。
最大输出是 131K 还是 262K?
两种模式,两个数。官方非思考最大输出 131,072。思考加最终回答合计 262,144。SandBase hero 印 131.1K,对的是非思考上限。卡片描述和 QwenCloud 市场页上的 393K 是残留冲突,不是正式上限。
为什么 SandBase 价格高于官方标价?
2026 年 11 月 16 日的 hero 是 $1.67 / $5.00,没有折扣标记。新加坡官方标价 $1.50 / $4.50。北京与 Global 官方标价 $1.413 / $4.24。缓存也不一样:卡片只印一个写入价 $2.08,读取 $0.08。报价时写明你实际调用的那一端。
新加坡的 100 万免费 token 在 SandBase 上算数吗?
最新模型页和价格页把这笔额度记在 QwenCloud 新加坡的按量调用上,和 Token Plan 额度分开。SandBase 卡片没有写。不要默认它会跟着走。
能按五折批量调用 qwen4-max 吗?
官方模型页写明这个模型不支持批量推理,北京也包括在内。通用价格页上的 50% 批量说明,不是 qwen4-max 的功能。
现在打开哪一页
新旗舰就是这次要换的对象时,打开 Qwen4 Max,链接旁边同时写上官方标价和卡片价。还想留着九折基线、也还没针对 reasoning_effort=high 和新输出上限重新验证 agent 时,留在 Qwen3.8 Max。先 建密钥,用 第一次调用 对 alibaba/qwen4-max 打一条,再去挪队列。
价格、上限和卡片 hero 核对于 2026 年 11 月 16 日(亚洲/上海)。正式规格和标价来自 QwenCloud 与阿里云 Model Studio。SandBase 上实际计费的标价以 hero 为准。发布文只在句子标明出处时引用。
相关阅读
觉得有用?分享给更多人