AI 生图文字渲染实测:11 个模型做电商海报
AI 生图文字渲染实测:11 个文生图模型、5 张电商海报、110 张图,逐字核对英文标题、中文卖点、小字 SKU 和价格,对比通过率、单张成本和耗时。
第 2 题要一张电饭煲促销海报,图上必须有三段字:「限时五折」「智能电饭煲」「¥199」。FLUX.2 Max、FLUX.2 Pro 和 Ideogram 3 一共 6 张图,主标题和价格全对,可「煲」字每一张都画错了:FLUX 画出来的是带火字旁、但根本不存在的字,Ideogram 则换成了别的字,顾客一眼看过去就是错别字。更麻烦的是,我们用来读图的 OCR 评审模型,有 3 张把它当成了正确的「智能电饭煲」。
这次 AI 生图文字渲染实测 反复出现的就是这个情况。2026-10-03(UTC),我们让 SandBase 上 11 个文生图模型画同样 5 张电商海报,每题 2 张,逐字检查要求的文字。英文标题和价格基本已经不是问题;生僻一点的汉字、小字号、价格排版还会出错,而 LLM 评审偏偏在这些地方需要人来复核。
先说结论
- 11 个模型里有 7 个在全部 10 张海报上一字不差:GPT Image 2、GPT Image 2.5 Flare、Nano Banana Pro、Nano Banana 2、Seedream 5.0 Pro、Qwen Image 3、Wan 2.7 Pro。
- FLUX.2 Max 和 Pro 都是 6/10,Ideogram 3 只有 3/10,中文海报全部栽在字形上;Midjourney v8.1 是 5/10,丢在中英混排列表、SKU 连字符和一处价格标签。
- 10/10 里最便宜的是 Nano Banana 2(实扣 $0.039/张,中位耗时 18.7 秒)和 Qwen Image 3($0.04,52.7 秒)。GPT Image 2 同样 10/10,但要 $0.15、中位 107 秒。
- GPT-6.1 Sol 做 OCR 评审,在 83 张人工复核图上判对 75 张;它误判为通过的 14 个字符串里有 13 个是中文,被它「顺手改对」了。中文必须人工看。
- 范围:5 道题、每模型每题 2 张、默认参数、一天之内。这不是图像质量总排名。
测试怎么做:11 个模型
场景是电商或营销 Agent:文案写好,直接出一张带原文的海报,中间没人修图。所以标准只有一条:要求的每段字都得逐字出现在图上。
11 个模型在 2026-10-03 的 GET https://api.sandbase.ai/v1/models/<id> 里都是 enabled: true(13:54 UTC 我们又查了一次 Qwen Image 3,仍是 enabled: true)。这个接口需要和调用相同的 Authorization: Bearer Key;没有 Key 的话,公开模型页上能看到同样的价格。所有图片都通过同一个 Unified Run 接口 POST https://api.sandbase.ai/v1/run 提交。10 个模型返回 202 和未完成的 run,我们用 GET /v1/run/{id} 轮询;GPT Image 2.5 Flare 直接返回 200 和生成好的图,不需要轮询。除了比例设成 1:1,其他参数一律默认;Qwen Image 3 和 Midjourney v8.1 没有比例参数,默认就是方图。大多数模型输出 1024×1024,Wan 2.7 Pro 是 1328×1328,Seedream 5.0 Pro 是 2048×2048。生成时间为 10:34 到 11:00 左右(UTC)。
| 模型(SandBase id) | 标价 / 张 | 2026-10-03 模型页显示 |
|---|---|---|
openai/gpt-image-2 | $0.20(默认 quality high) | $0.15(25% OFF) |
openai/gpt-image-2.5-flare | $0.20(quality high) | $0.15(25% OFF) |
google/nano-banana-pro | $0.12(1K) | $0.08(35% OFF) |
google/nano-banana-2 | $0.06(1K) | $0.04(35% OFF) |
bytedance/seedream/5.0/pro | $0.0675(设置了 aspect_ratio) | 未截取 |
bfl/flux-2/max | $0.07 | 未截取 |
bfl/flux-2/pro | $0.03 | 未截取 |
alibaba/qwen-image-3/text-to-image | $0.04(1K) | $0.04 |
ideogram-ai/ideogram-v3 | $0.06(默认 BALANCED) | 未截取 |
alibaba/wan/2.7/pro | $0.075 | 未截取 |
midjourney/midjourney-v8.1 | $0.10 / 次请求(出 4 张) | 未截取 |
标价按各模型 model card 里的 price_formula 和我们的参数算出。我们事先定的门槛是每张不超过 $0.30,11 个都在线内,没有剔除。Midjourney 一次请求出 4 张、收 $0.10,我们只评每次请求的第一张,所以它的 $0.10 按一张计。
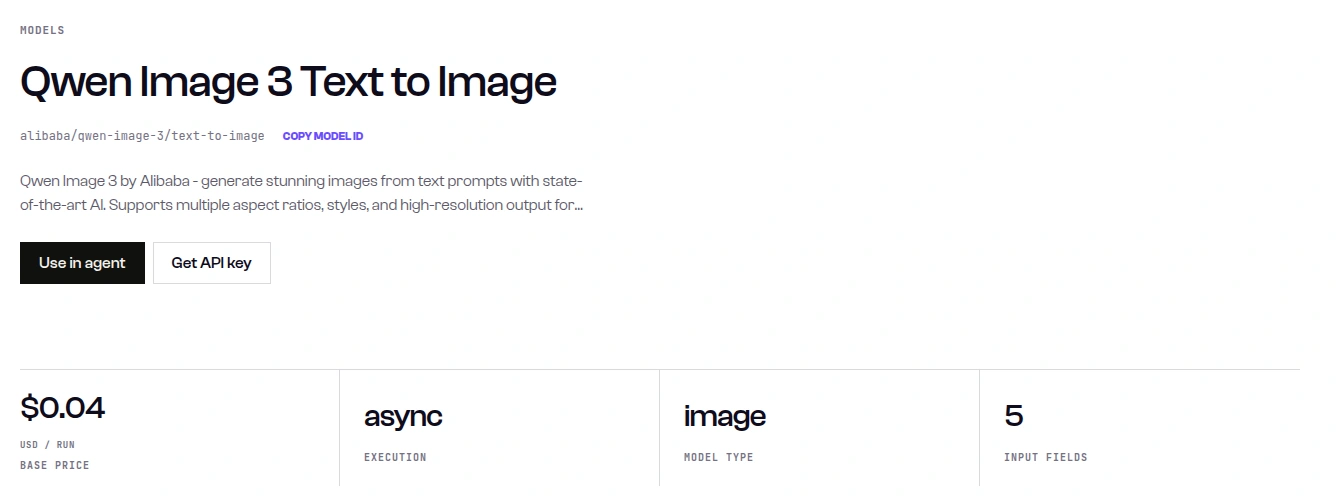
截图:Qwen Image 3 模型页标价 $0.04 / 次、异步执行,和它 10 张测试图每张实扣 $0.04 一致(2026-10-03 截取)。
5 道海报题和评分规则
每道题写明商品、背景和必须出现的原文,结尾都加同一句「严格按原文渲染,图上不要有任何其他文字」。一共 16 个必需字符串:
| 题号 | 类型 | 必需字符串 |
|---|---|---|
| P1 | 英文标题 + 价格 | STAY COLD 24 HOURS、$39.99 |
| P2 | 中文标题 + 价格 | 限时五折、智能电饭煲、¥199 |
| P3 | 中英混排 4 行列表 | AirFlow Pro 降噪耳机、40dB 主动降噪、续航 36 小时、Bluetooth 6.0、IPX5 防水 |
| P4 | 小字 | HYDRA SERUM、SKU: BX-2026-07 |
| P5 | 两个价格 + 日期 | FLASH SALE、Was $129.00、Now $89.00、Ends 2026.10.03 |
5 道题的原文如下(提示词本身是英文),每题都以同一句 “Render the text exactly as written, with no other text anywhere in the image.” 结尾:
P1(英文标题 + 价格):
Square e-commerce product poster for a matte black stainless steel insulated water bottle on a light gray studio background. At the top, a large bold headline that reads exactly: "STAY COLD 24 HOURS". At the bottom right, a price tag that reads exactly: "$39.99". Render the text exactly as written, with no other text anywhere in the image.P2(中文标题 + 价格):
Square e-commerce promotional poster for a white smart rice cooker on a red festive background. A large Chinese headline that reads exactly: "限时五折". Below it, a smaller Chinese subtitle that reads exactly: "智能电饭煲". A price badge that reads exactly: "¥199". Render the text exactly as written, with no other text anywhere in the image.P3(中英混排 4 行列表):
Square product poster for wireless noise-cancelling earbuds on a dark blue gradient background. A headline that reads exactly: "AirFlow Pro 降噪耳机". Below it, a bulleted list of exactly four lines: "40dB 主动降噪", "续航 36 小时", "Bluetooth 6.0", "IPX5 防水". Render the text exactly as written, with no other text anywhere in the image.P4(小字 SKU):
Square product poster for a glass dropper bottle of face serum on a soft beige background. A large headline that reads exactly: "HYDRA SERUM". In small print at the bottom left corner, a product code that reads exactly: "SKU: BX-2026-07". Render the text exactly as written, with no other text anywhere in the image.P5(两个价格 + 日期):
Square flash sale poster for a pair of white running shoes on a bright yellow background. A headline that reads exactly: "FLASH SALE". Show the old price "Was $129.00" with a strikethrough line, and the new price "Now $89.00" larger next to it. At the bottom, a line that reads exactly: "Ends 2026.10.03". Render the text exactly as written, with no other text anywhere in the image.每次请求只传 model、prompt,模型有比例参数时再加 aspect_ratio: "1:1"。逐图标注、原始转写和打分记录留在内部;本文引用的每个数字都能在文中的表格里找到。
评分分两步。第一步,用视觉模型 openai/gpt-6.1-sol(走 POST /v1/chat/completions)把每张图上的字转写出来,提示词要求照图逐字抄写、画错的字照抄、看不清写 ?、不许纠错。第二步,Python 拿转写结果打分:
- 先做 Unicode NFKC,全角 ¥ 会变成 ¥;
- 不区分大小写,但 SKU 除外;
- 去掉空白和行首项目符号,允许一句话折行;
- 保留
$ ¥ . : -,并检查数字边界,¥1999里不算有¥199。
一张海报所有字符串都通过才算通过。另外用 google/gemini-3.8-flash 对 110 张图再评一遍做对照。
然后人工看图。看的是缩小副本和局部放大,由两个人分别完成,重叠的 3 张结论一致。看过的图以人工结论为准;没看的用 Sol 的结果,两个评审对这些图都判通过。
| 题目 | 图片数 | 人工看过 | 只用评审 |
|---|---|---|---|
| P1 | 22 | 6 | 16 |
| P2 | 22 | 22 | 0 |
| P3 | 22 | 22 | 0 |
| P4 | 22 | 11 | 11 |
| P5 | 22 | 22 | 0 |
| 合计 | 110 | 83 | 27 |
结果:11 个模型里 7 个全对
| 模型 | 通过海报(10) | 字符串(32) | P1 英文 | P2 中文 | P3 混排 | P4 SKU | P5 价格 | 实扣 / 张 | 中位耗时 | 每张合格海报成本 |
|---|---|---|---|---|---|---|---|---|---|---|
| GPT Image 2 | 10 | 32 | 2 | 2 | 2 | 2 | 2 | $0.15 | 106.9 秒 | $0.15 |
| GPT Image 2.5 Flare | 10 | 32 | 2 | 2 | 2 | 2 | 2 | $0.15 | 20.0 秒 | $0.15 |
| Nano Banana Pro | 10 | 32 | 2 | 2 | 2 | 2 | 2 | $0.078 | 24.0 秒 | $0.078 |
| Nano Banana 2 | 10 | 32 | 2 | 2 | 2 | 2 | 2 | $0.039 | 18.7 秒 | $0.039 |
| Seedream 5.0 Pro | 10 | 32 | 2 | 2 | 2 | 2 | 2 | $0.0675 | 30.3 秒 | $0.0675 |
| Qwen Image 3 | 10 | 32 | 2 | 2 | 2 | 2 | 2 | $0.04 | 52.7 秒 | $0.04 |
| Wan 2.7 Pro | 10 | 32 | 2 | 2 | 2 | 2 | 2 | $0.075 | 16.2 秒 | $0.075 |
| FLUX.2 Max | 6 | 24 | 2 | 0 | 0 | 2 | 2 | $0.07 | 21.4 秒 | $0.117 |
| FLUX.2 Pro | 6 | 24 | 2 | 0 | 0 | 2 | 2 | $0.03 | 13.5 秒 | $0.05 |
| Midjourney v8.1 | 5 | 25 | 2 | 2 | 0 | 0 | 1 | $0.10 / 次请求 | 44.8 秒 | $0.20 |
| Ideogram 3 | 3 | 19 | 2 | 0 | 0 | 1 | 0 | $0.06 | 16.5 秒 | $0.20 |
「实扣」是该模型所有任务 GET /v1/tasks/<id>/cost 返回的 cost 中位数。耗时从提交算到完成,每 2 秒轮询一次,单机测得。查成本时我们直接把 run id 传给 GET /v1/tasks/<id>/cost;文档里 task id 的来源是响应头 x-task-id,在我们的调用里它和 run id 是同一个值。
按题型看:P1 的 22 张全过,P2 是 16/22,P3 是 14/22,P4 和 P5 都是 19/22。P1 的两段、「限时五折」「¥199」「IPX5 防水」「HYDRA SERUM」「Ends 2026.10.03」,在所有模型的所有图上都对。
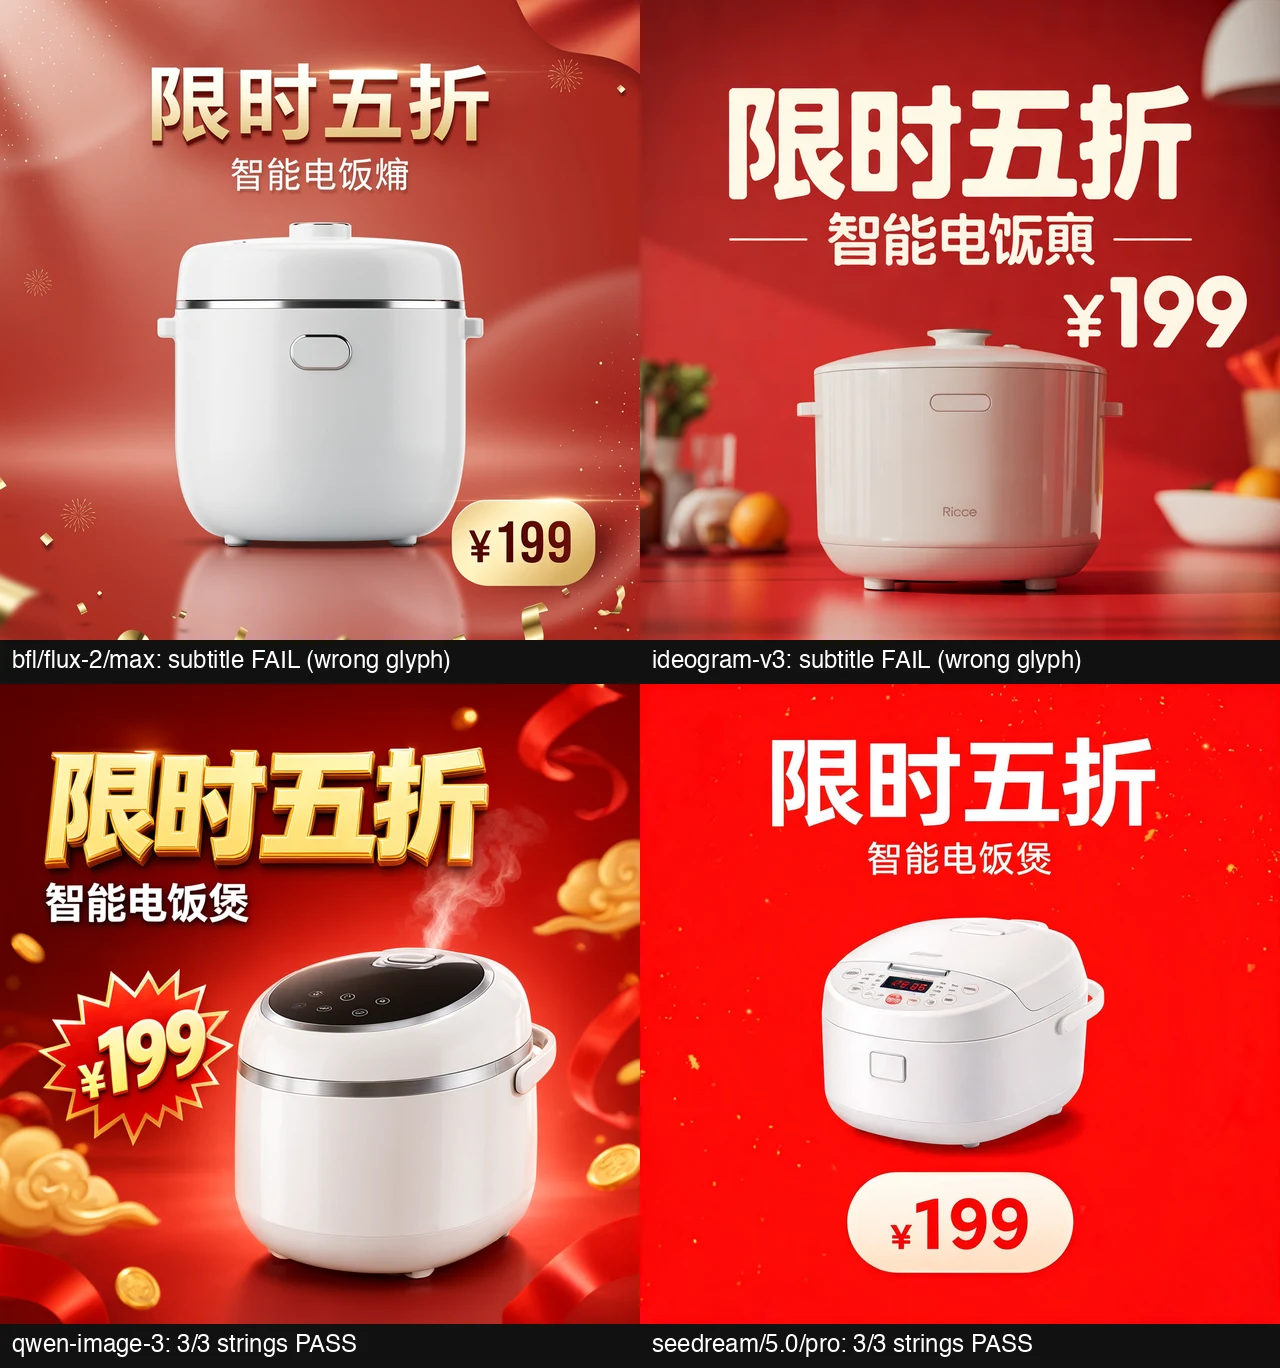
截图:第 2 题输出,2026-10-03 分别由 bfl/flux-2/max、ideogram-ai/ideogram-v3、alibaba/qwen-image-3/text-to-image、bytedance/seedream/5.0/pro 生成(各取第一张);只有下面两张把「智能电饭煲」写对了。
字错在哪
不常用的汉字。 FLUX.2 两款和 Ideogram 3 写常用字没问题,「限时五折」「防水」都对,碰到稍生僻的就画错。「煲」在它们 6 张 P2 图里全错;P3 里的「降噪」在 6 张图上也全错,标题和第一条卖点都没逃过,多数是「噪」画坏了。「续航 36 小时」错了 5 张,「续」「航」「时」都有画错的,还有一张漏了字。Midjourney 第 2 题过了,但 P3 两张的「降噪」都写错,其中一张还把「耳机」画成「毛机」。FLUX.2 Pro 还有一次直接漏掉了 Bluetooth 6.0 这一行。
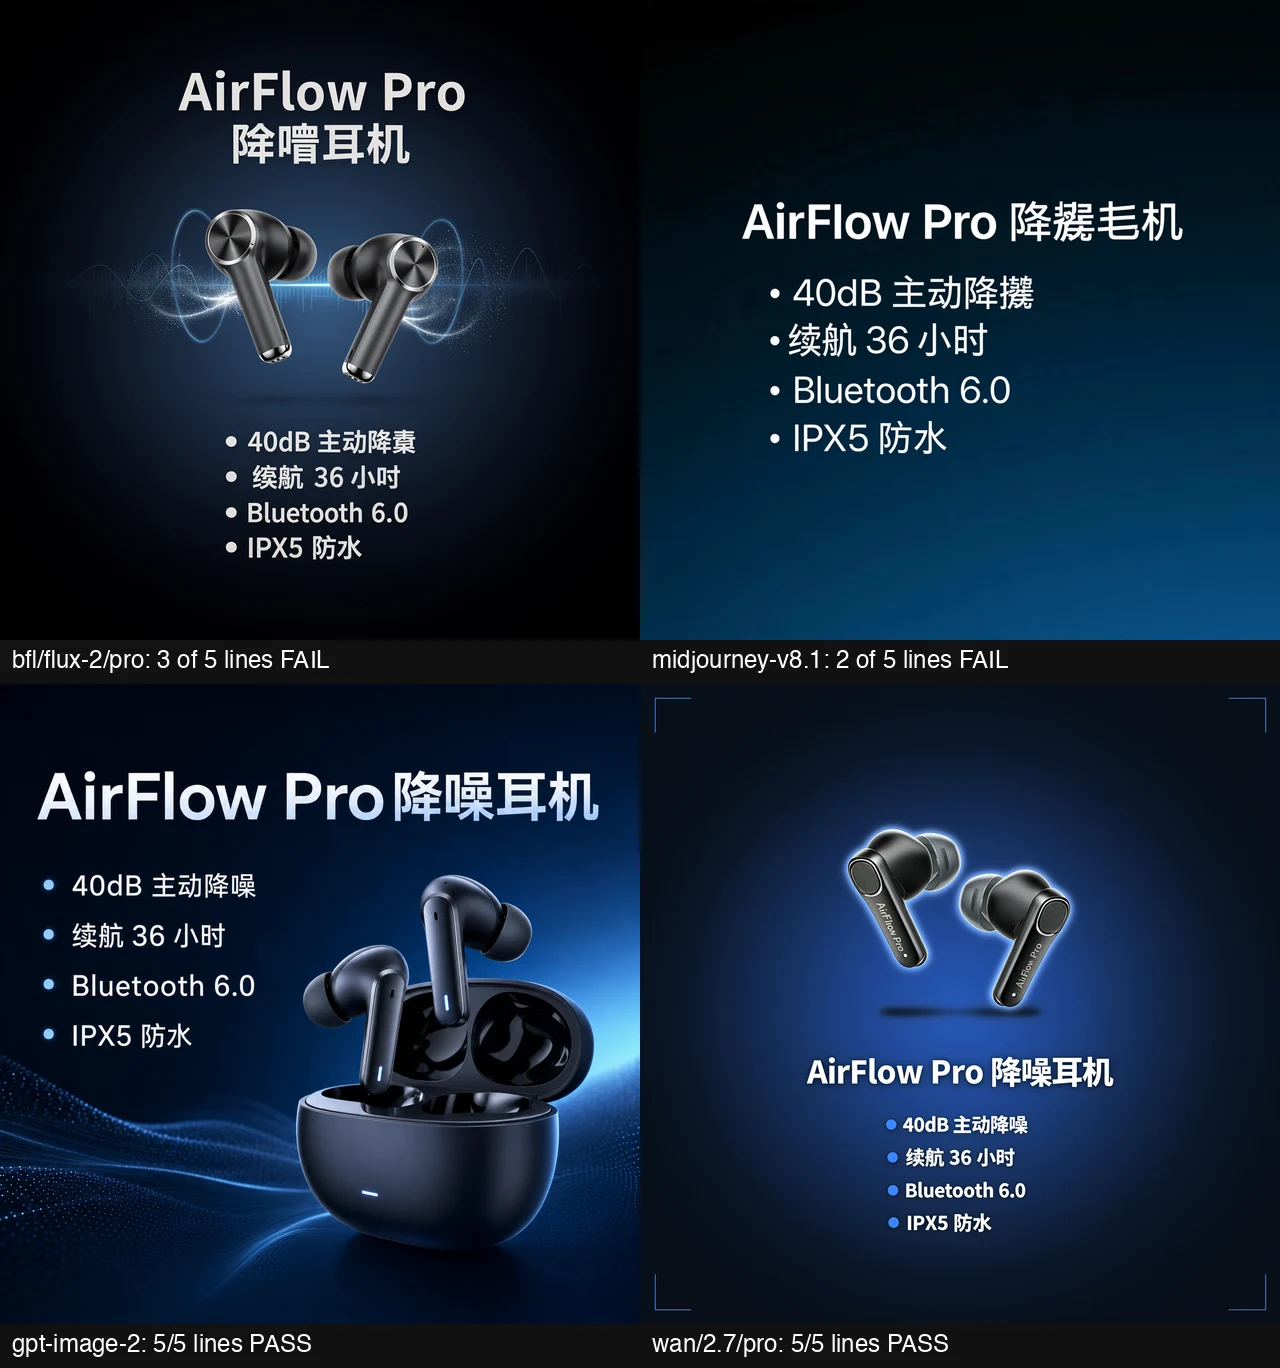
截图:第 3 题输出,2026-10-03 分别由 bfl/flux-2/pro、midjourney/midjourney-v8.1、openai/gpt-image-2、alibaba/wan/2.7/pro 生成(各取第一张);英文部分都没问题,「噪」字过不去。
小字。 Midjourney 两张 P4 都写成 SKU: BX 2026 07,连字符没了;Ideogram 有一张写成 Bx-2026-07,商品编码区分大小写,判不通过。其余模型的 SKU 都完全正确,这 19 张里有 8 张是我们裁出局部、人工确认的。
价格排版。 Ideogram 第二张 P5 让鞋子挡住了 SALE 的 a,还印成 WAS $1299.00 和 $89.0;第一张把 NOW 放在右上角,离 $89.00 很远。后者我们按「标签脱离价格」判了不通过,这一点见仁见智。Midjourney 有一张把 Now 画成了 “Novr Low”。还有模型没画删除线,改成了下划线:在我们看过的图里,Midjourney 两次、Seedream 一次。样式不计分,只计文字。
没要求的字。 每道题都写了「图上不要有任何其他文字」,好几个模型还是加了。放进广告里,下面这些最有风险:
- Wan 2.7 Pro 在一张电饭煲海报上自己加了「包邮」「正品」「7天退换」,这是商家没承诺过的服务。
- Nano Banana Pro 有一张带着淡淡的水印式 logo,Sol 读出来是「千图网」,一个图库网站的名字。
- Ideogram 自己编了品牌:电饭煲上印 “Ricce”,水杯上一个乱码 “D?CL”;Wan 在精华瓶标签上写了 “HYDRA STRUM”。
- Nano Banana 2、Nano Banana Pro 和 Ideogram 的鞋子上出现了类似对勾的 logo。
只有 Qwen Image 3 的 10 份转写里完全没有多余文字。家电面板上的小字和图标大多数模型都会画,我们当作装饰处理。
让 LLM 来判卷靠谱吗
大体靠谱,前提是中文由人复核。拿 83 张人工复核图对照:
| 评审 | 整图判定一致 | 字符串一致 | 评审判过、人工判错 | 评审判错、人工判过 |
|---|---|---|---|---|
| GPT-6.1 Sol | 75/83 | 280/298 | 14 | 4 |
| Gemini 3.8 Flash | 77/83 | 278/298 | 10 | 10 |
两个评审错的方向不一样。Sol 放过的 14 个错误里,13 个是中文:明明要求逐字照抄,它还是把 3 张 FLUX.2 图上画错的「煲」读成「智能电饭煲」,又在 FLUX.2 和 Ideogram 的图上把 8 处「降噪」读对了。它判严的那几次都是阅读顺序问题:模型把 “Now” 叠在 “$89.00” 上方,或者把 “Was""Now” 排成一列放在两个价格上面,Sol 先抄了标签再抄价格,字符串就对不上了。
Gemini 3.8 Flash 放过的少,判严的多;还有两张 P3 图,它没给转写,返回的是自己分析笔画部件的推理过程。
英文上两个评审都稳。我们人工看过的 17 张 P1、P4,两者都和人工一致,Midjourney 和 Ideogram 的 SKU 错误也都抓到了;没看的 27 张它们也都判通过。Sol 在英文上的误判,是 P5 那 4 处阅读顺序问题,加上 Ideogram 那个脱离价格的 NOW。要自动化的话,纯拉丁文字的通过可以直接放行,含中文的通过交给人看。下面的示例程序就是这么做的。
成本:四个模型实扣低于标价
这次一共生成 110 张计分图,另有 4 次重复扣费:我们的客户端断了连接,但上游任务照常完成并计费,我们又重新提交了一次。另有一个 Midjourney 任务卡在 running 900 秒,最后变成 failed,没有扣费。
| 项目 | 依据 | 费用 |
|---|---|---|
| 生图,114 个计费任务 | GET /v1/tasks/<id>/cost 求和 | $8.96 |
| OCR 评审,GPT-6.1 Sol | 输入 192,820、输出 18,384 token,按 $2 / $10 每百万 | $0.57 |
| OCR 评审,Gemini 3.8 Flash | 用量 × $1.50 / $7.50 每百万 | $0.38 |
| 探测请求(3 个模型,按标价) | Qwen Image 3、FLUX.2 Pro、Midjourney 各一次 | $0.17 |
| 示例程序第一次运行 | 2 张 Qwen 图 + 2 次评审 | $0.09 |
| 截图 | 10 次截图调用 | $0.05 |
| 第一天合计 | 约 $10.22 |
修正轮询路径后重跑示例程序(见下文)又花了 $0.09。
有四个模型的实扣低于 model card 里的标价,原因写在模型页上:2026-10-03 两款 GPT Image 都打 75 折(25% OFF),两款 Nano Banana 都打 65 折(35% OFF)。其余七个按标价扣费。折扣会变,「实扣」一栏只代表 2026-10-03 当天。
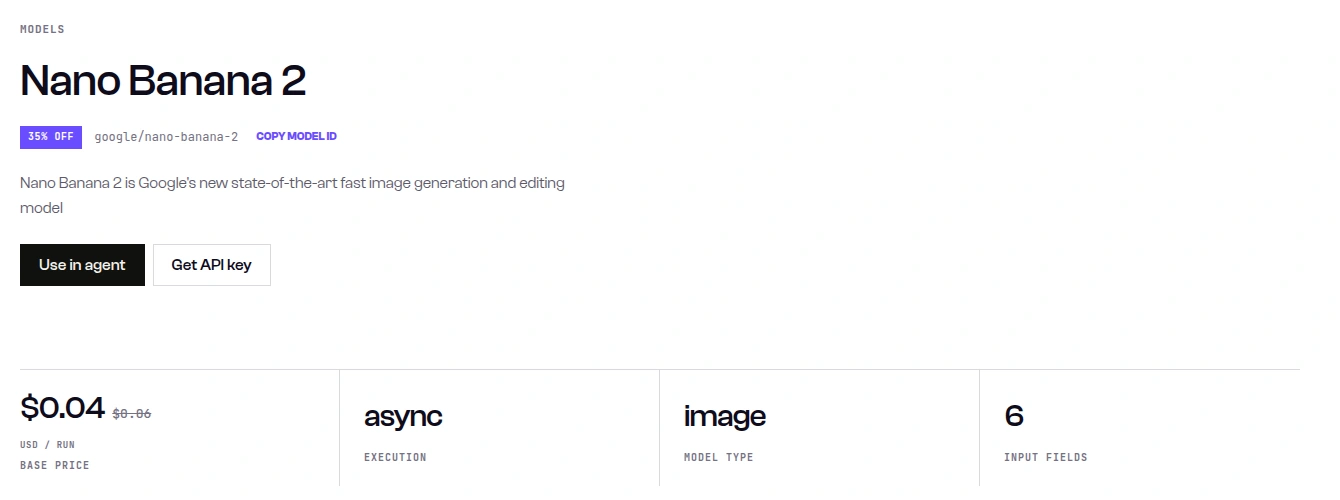
截图:2026-10-03 的 Nano Banana 2 模型页显示 35% OFF,$0.04(原价 $0.06),它的 10 张测试图每张实扣 $0.039(2026-10-03 截取)。
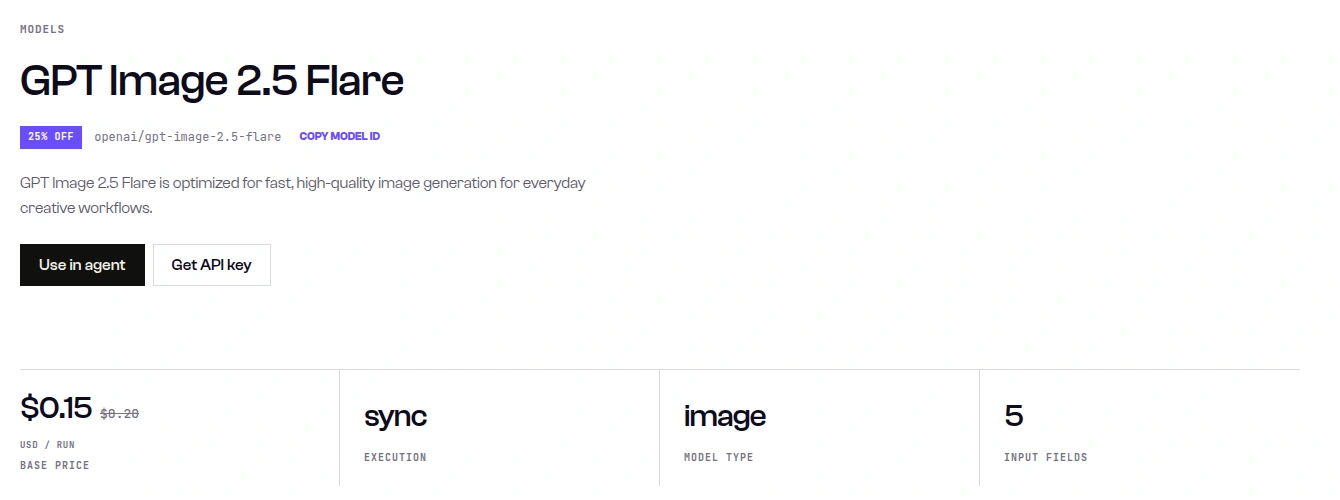
截图:GPT Image 2.5 Flare 模型页显示 25% OFF,$0.15(原价 $0.20),和本次每张实扣 $0.15 一致(2026-10-03 截取)。
真正拉开差距的是「每张合格海报成本」。FLUX.2 Pro 单价最低,只要 $0.03,可 5 道题合起来只有 6/10 合格,折下来 $0.05 一张能用的;只做英文的话它是 6/6,那才真是 $0.03。Ideogram 和 Midjourney 都要 $0.20 一张合格海报。
怎么选
| 你要的是 | 先用 | 注意 |
|---|---|---|
| 中英文都要准,成本最低 | Nano Banana 2:10/10,$0.039,18.7 秒 | 两张 P2 都画成了灰色背景上的装裱样机,不是平面海报;需要的话在提示词里写明「平面海报、铺满画面」 |
| 价格低,还不乱加字 | Qwen Image 3:10/10,$0.04,没有多余文字 | 中位 52.7 秒,倒数第二慢 |
| 10/10 里最快 | Wan 2.7 Pro:16.2 秒,$0.075 | 留意它自己加「包邮」「正品」之类的话 |
| 再要一家 10/10,价格适中 | Seedream 5.0 Pro($0.0675,2048 像素)或 Nano Banana Pro($0.078) | Nano Banana Pro 出过一次水印式 logo |
| 用 OpenAI 体系 | GPT Image 2.5 Flare:10/10,$0.15,20 秒 | GPT Image 2 成绩相同,但中位要 107 秒 |
| 只做英文海报,最便宜 | FLUX.2 Pro:P1/P4/P5 共 6/6,$0.03 | 中文 0/4,别拿它做中文文案 |
放到 Agent 里,比较实用的做法是一个默认模型、一个备用模型,中间加一道检查:默认模型出图,转写,代码比对字符串;有字符串不过就重画或换备用模型;含中文的通过结果在上线前交给人看一眼。
在 SandBase 上跑同样的检查
一个 SandBase API Key 就能同时调用生图模型和 OCR 评审。下面的程序跑单个模型的完整闭环:
- 用
POST /v1/run生成海报; - 如果提交返回未完成的 run(
202),轮询GET /v1/run/{id}直到完成,再下载outputs[0].url; - 通过 OpenAI 兼容的 Chat Completions 接口把图发给 GPT-6.1 Sol,要求逐字转写;
- 在 Python 里核对必需字符串。
任务没完成、或者评审的 finish_reason 不是 stop 时直接报错;含中文的通过结果会标记为需要人工看。只有提交返回未完成的 run 时才轮询,因为有些模型(这次测试里的 GPT Image 2.5 Flare)是同步返回的。评审选 GPT-6.1 Sol,是因为它判严的次数比 Gemini 3.8 Flash 少(4 对 10),而且每次都返回了转写;我们的 Sonnet 5.5 与 GPT-6.1 Sol Agent 实测 里它在短工具任务上也是 30/30。
"""Generate a product poster on SandBase, transcribe its text with a vision LLM, and check the required strings.

Usage: SANDBASE_API_KEY=... python3 poster_text_check.py
"""
import base64
import os
import re
import time
import unicodedata

import requests

BASE = "https://api.sandbase.ai/v1"
HEADERS = {"Authorization": f"Bearer {os.environ['SANDBASE_API_KEY']}"}
IMAGE_MODEL = "alibaba/qwen-image-3/text-to-image"
JUDGE_MODEL = "openai/gpt-6.1-sol"

PROMPT = ('Square e-commerce promotional poster for a white smart rice cooker on a red festive background. '
          'A large Chinese headline that reads exactly: "限时五折". Below it, a smaller Chinese subtitle '
          'that reads exactly: "智能电饭煲". A price badge that reads exactly: "¥199". '
          'Render the text exactly as written, with no other text anywhere in the image.')
REQUIRED = ["限时五折", "智能电饭煲", "¥199"]

OCR_PROMPT = ("Transcribe every piece of visible text in this image exactly as it is rendered, character by "
              "character. Do not correct spelling, do not fix garbled or malformed characters, do not guess what "
              "the text was meant to say, and do not translate. Put each separate text line on its own line. "
              "If a character is unreadable, write ? for it. If there is no text, reply with NO_TEXT.")


def generate(prompt: str, timeout_s: int = 600) -> tuple[str, bytes]:
    """Submit to POST /v1/run, poll GET /v1/run/{id} while the run is not finished, return (run id, image bytes)."""
    resp = requests.post(f"{BASE}/run", headers=HEADERS, json={"model": IMAGE_MODEL, "prompt": prompt}, timeout=120)
    resp.raise_for_status()
    task = resp.json()
    task_id, start = task["id"], time.time()
    while task.get("status") not in ("completed", "failed", "timeout", "cancelled"):
        if time.time() - start > timeout_s:
            raise TimeoutError(f"{task_id} still {task.get('status')} after {timeout_s}s")
        time.sleep(3)
        task = requests.get(f"{BASE}/run/{task_id}", headers=HEADERS, timeout=60).json()
    outputs = task.get("outputs") or []
    if task["status"] != "completed" or not outputs:
        raise RuntimeError(f"{task_id}: {task['status']} {task.get('error')}")
    return task_id, requests.get(outputs[0]["url"], timeout=120).content


def transcribe(image: bytes) -> tuple[str, dict]:
    """Ask the vision model for a verbatim transcription (no correction)."""
    data_url = "data:image/png;base64," + base64.b64encode(image).decode()
    body = {"model": JUDGE_MODEL, "max_tokens": 2000, "messages": [{"role": "user", "content": [
        {"type": "text", "text": OCR_PROMPT},
        {"type": "image_url", "image_url": {"url": data_url}}]}]}
    resp = requests.post(f"{BASE}/chat/completions", headers=HEADERS, json=body, timeout=300)
    resp.raise_for_status()
    out = resp.json()
    choice = out["choices"][0]
    if choice.get("finish_reason") != "stop":
        raise RuntimeError(f"judge stopped with {choice.get('finish_reason')}")
    return choice["message"].get("content") or "", out.get("usage") or {}


def norm(s: str) -> str:
    """NFKC (full-width ¥ -> ¥), casefold, drop whitespace and leading bullets."""
    s = unicodedata.normalize("NFKC", s).casefold()
    return re.sub(r"\s+", "", re.sub(r"^[•·●\-*]+", "", s, flags=re.M))


def check(text: str, required: list[str]) -> dict[str, bool]:
    """A string passes when it appears in the transcription, not glued to another digit (¥199 vs ¥1999)."""
    blob = norm(text)
    hits = {}
    for req in required:
        pat = re.escape(norm(req))
        if req[-1].isdigit():
            pat += r"(?![0-9])"
        hits[req] = re.search(pat, blob) is not None
    return hits


def needs_human_review(required: list[str]) -> bool:
    """In our test the judge silently 'fixed' near-miss Chinese glyphs, so CJK passes get a human look."""
    return any("\u4e00" <= ch <= "\u9fff" for req in required for ch in req)


if __name__ == "__main__":
    rows = []
    for i in range(2):
        t0 = time.time()
        task_id, image = generate(PROMPT)
        seconds = round(time.time() - t0, 1)
        path = f"poster_{i + 1}.png"
        open(path, "wb").write(image)
        text, usage = transcribe(image)
        hits = check(text, REQUIRED)
        rows.append((path, task_id, seconds, hits, usage))
        print(f"--- {path} ({task_id}, {seconds}s)\n{text}\n")
    print(f"{'file':14} {'secs':>5}  " + "  ".join(f"{r:>6}" for r in REQUIRED) + "  verdict")
    for path, task_id, seconds, hits, usage in rows:
        verdict = "PASS" if all(hits.values()) else "FAIL"
        if verdict == "PASS" and needs_human_review(REQUIRED):
            verdict = "PASS (check CJK by eye)"
        print(f"{path:14} {seconds:5}  " + "  ".join(f"{'ok' if hits[r] else 'MISS':>6}" for r in REQUIRED)
              + f"  {verdict}")
        print(f"{'':14} judge tokens in/out: {usage.get('prompt_tokens')}/{usage.get('completion_tokens')}")
实测于 2026-10-03(UTC)。 上面的程序原样跑了一次,13:48:31 到 13:51:02(UTC)。输入就是上面虚构商品的第 2 题,不涉及任何第三方内容。请求:POST https://api.sandbase.ai/v1/run,body 为 {"model": "alibaba/qwen-image-3/text-to-image", "prompt": "<第 2 题>"},返回 202 和 "status": "pending"。程序随后轮询 GET https://api.sandbase.ai/v1/run/{id},第一张海报最后一次轮询返回的完整对象:
{"id": "e863b328-8e22-48ff-bf93-e89c7a614bb3", "status": "completed",
 "model": "alibaba/qwen-image-3/text-to-image",
 "outputs": [{"content_type": "image/png",
   "url": "https://media.sandbase.ai/files/e863b328-8e22-48ff-bf93-e89c7a614bb3/0.png"}]}
程序输出,省略了两段转写。第二段转写多了 5 行 ? 和一个 “10”,是电饭煲面板上的图标和显示屏。
file            secs    限时五折   智能电饭煲    ¥199  verdict
poster_1.png    55.4      ok      ok      ok  PASS (check CJK by eye)
               judge tokens in/out: 1318/128
poster_2.png    55.7      ok      ok      ok  PASS (check CJK by eye)
judge tokens in/out: 1318/222两张图我们都人工看过,标题、副标题和价格全对。GET /v1/tasks/<id>/cost 返回:
| 任务 | Id | 实扣 |
|---|---|---|
| 海报 1,Qwen Image 3 | e863b328-8e22-48ff-bf93-e89c7a614bb3 | $0.040000 |
| 海报 1,GPT-6.1 Sol 评审 | 84164611-91de-4bfa-a402-6958a7558ffd | $0.004574 |
| 海报 2,Qwen Image 3 | a4b2e276-3e8b-4a6e-813c-ccf0cc9324c8 | $0.040000 |
| 海报 2,GPT-6.1 Sol 评审 | c0838a38-8147-4f8a-a715-4ffe8b362d62 | $0.005514 |
用到的字段(id、status、outputs[0].url、usage)和文档里的异步 run 响应一致。请求字段见 Qwen Image 3 模型页,其他生图模型见 SandBase 模型目录。获取 SandBase API Key,拿你自己的商品文案跑一遍同样的检查。
数据范围:所有提示词都是虚构商品,所有图片都是我们自己生成的。提示词、必需字符串、评分规则和全部汇总数据都在本文里;逐图标注、原始转写和打分记录留在内部。想看这些厂商的功能对比,可以读 AI 生图 API 推荐;10/10 里三款模型的深入对比见 Seedream、Qwen Image 与 Nano Banana 对比。
常见问题
2026 年哪个 AI 生图模型写字最准?
在我们这 5 张电商海报上,有 7 个模型 10 张图全部一字不差:GPT Image 2、GPT Image 2.5 Flare、Nano Banana Pro、Nano Banana 2、Seedream 5.0 Pro、Qwen Image 3、Wan 2.7 Pro。每个模型只有 10 张图,把它当作候选名单,别当成这 7 个之间的排名。
海报要写中文,用哪个生图模型?
这 7 个模型的中文海报(P2 和 P3 各 2 张)全对,其中最便宜的是 Nano Banana 2 和 Qwen Image 3,每张 $0.039 和 $0.04。FLUX.2 Max、FLUX.2 Pro 和 Ideogram 3 的中文海报一张没过;Midjourney v8.1 过了简单的中文题,混排列表没过。
FLUX.2 能在图上写字吗?
英文可以:FLUX.2 Pro 和 Max 各自的 6 张纯英文海报(P1、P4、P5)全部通过,连小字 SKU 也对。中文不行:两款各 4 张带「煲」「噪」这类字的海报全错,中文文案别用它。
能用大模型自动检查生成图里的字吗?
英文基本可以。GPT-6.1 Sol 在 83 张人工复核图上判对 75 张,人工看过的 17 张纯英文 P1、P4 图,两个评审的结论都和人工一致。中文不行:评审会自己把画错的字「纠正」过来,含中文的通过结果要交给人看。
一张文字准确的 AI 海报要多少钱?
10 张全过的模型里,2026-10-03 每张实扣从 $0.039(Nano Banana 2)、$0.04(Qwen Image 3)到 $0.15(两款 GPT Image)不等,OCR 检查每张再加约半美分(示例运行实扣 $0.0046 到 $0.0055)。当天有四个模型打 65 到 75 折,用之前看一下模型页。
测试边界
这次只有 5 道题,每个模型每题 2 张,共 110 张图,一天之内完成,默认参数、方图、英文提示词。2 张图分不出 90% 和 100% 通过率的模型,所以 10/10 的意思是「没看到出错」,不是保证。我们只评文字,不评设计、商品还原度或字符串以外的版式;删除线和「不要其他文字」两条要求只做了记录,没有计分。人工复核覆盖 83/110 张,其余 27 张依赖 OCR 评审,在我们的样本里它对英文是可靠的。耗时是单机经 SandBase 网关测得,价格和折扣只代表 2026-10-03。正式定默认模型前,拿接近你自己商品的题目再跑一遍。