Reddit Public Data API: Subreddits, Posts, Users & Search | SandBase
Read public Reddit subreddits, posts, comments, user profiles, and search with one REST API. No Reddit OAuth app, no PRAW — one SandBase key, built for agents.
Reddit is one of the richest public conversation datasets on the internet — millions of subreddits, threaded comments, and karma signals that map directly onto sentiment, community research, and trend detection. Getting at it programmatically usually means registering a Reddit OAuth app, learning PRAW, and managing token refresh and per-app rate limits before you read a single post.
The SandBase Reddit public data API collapses that setup into one REST convention. It reads public subreddits, posts, comments, user profiles, and search results through plain endpoints — one SandBase API key, synchronous JSON, no Reddit OAuth app and no client library. The examples below use the subreddit-info endpoint against r/programming; treat the field names and values as an illustrative structure and confirm the exact schema against a live response.
This is not Reddit’s official Data API. Use Reddit’s official API when you need authenticated member actions, posting, moderation, or a licensed high-volume data agreement. Use SandBase when your workflow needs public, read-only community data for research, monitoring, or enrichment. Ready to try it? Get a SandBase API key and browse the Reddit endpoints.
Key takeaway
- One API reads public subreddits, posts, comments, user profiles, and search.
- The Model API endpoints in this guide are called with
POST /v1/api/reddit/<path>— pass only that endpoint’s params, no client library, oneSANDBASE_API_KEY.- Endpoints key off natural identifiers (
subreddit_name,username,post_id) or a searchkeyword(query).- It returns public, read-only data only. There is no posting, no voting, no Reddit OAuth app, and no moderation actions; authenticate with a SandBase API key.
Which Reddit API do you need?
| Your need | Choose | Why |
|---|---|---|
| Post, vote, moderate, or act as an authenticated member | Reddit official API | OAuth-scoped member and moderation actions. |
| Read public subreddits, posts, comments, users, or search | SandBase Reddit public-data API | Plain REST, one SandBase key, structured JSON for read-only workflows. |
| Licensed bulk data or commercial data agreement | Reddit’s data licensing | Large-scale commercial access is handled through Reddit directly. |
What you can get from the Reddit API
The older examples below use the app surface of single-resource reads and feeds. Grouped by job:
- Subreddits — community info (subscribers, description, type) and subreddit feeds.
- Posts — post details, batch post lookups, and post comments with threading.
- Comments — comment replies and per-post comment threads.
- Users — public user profiles, their posts, comments, trophies, and active subreddits.
- Search & discovery — dynamic search, typeahead, trending searches, and topic/news feeds.
Not every listed capability is enabled for direct calls yet — catalog availability can change — so treat each endpoint’s live API reference as the source of truth before you build.
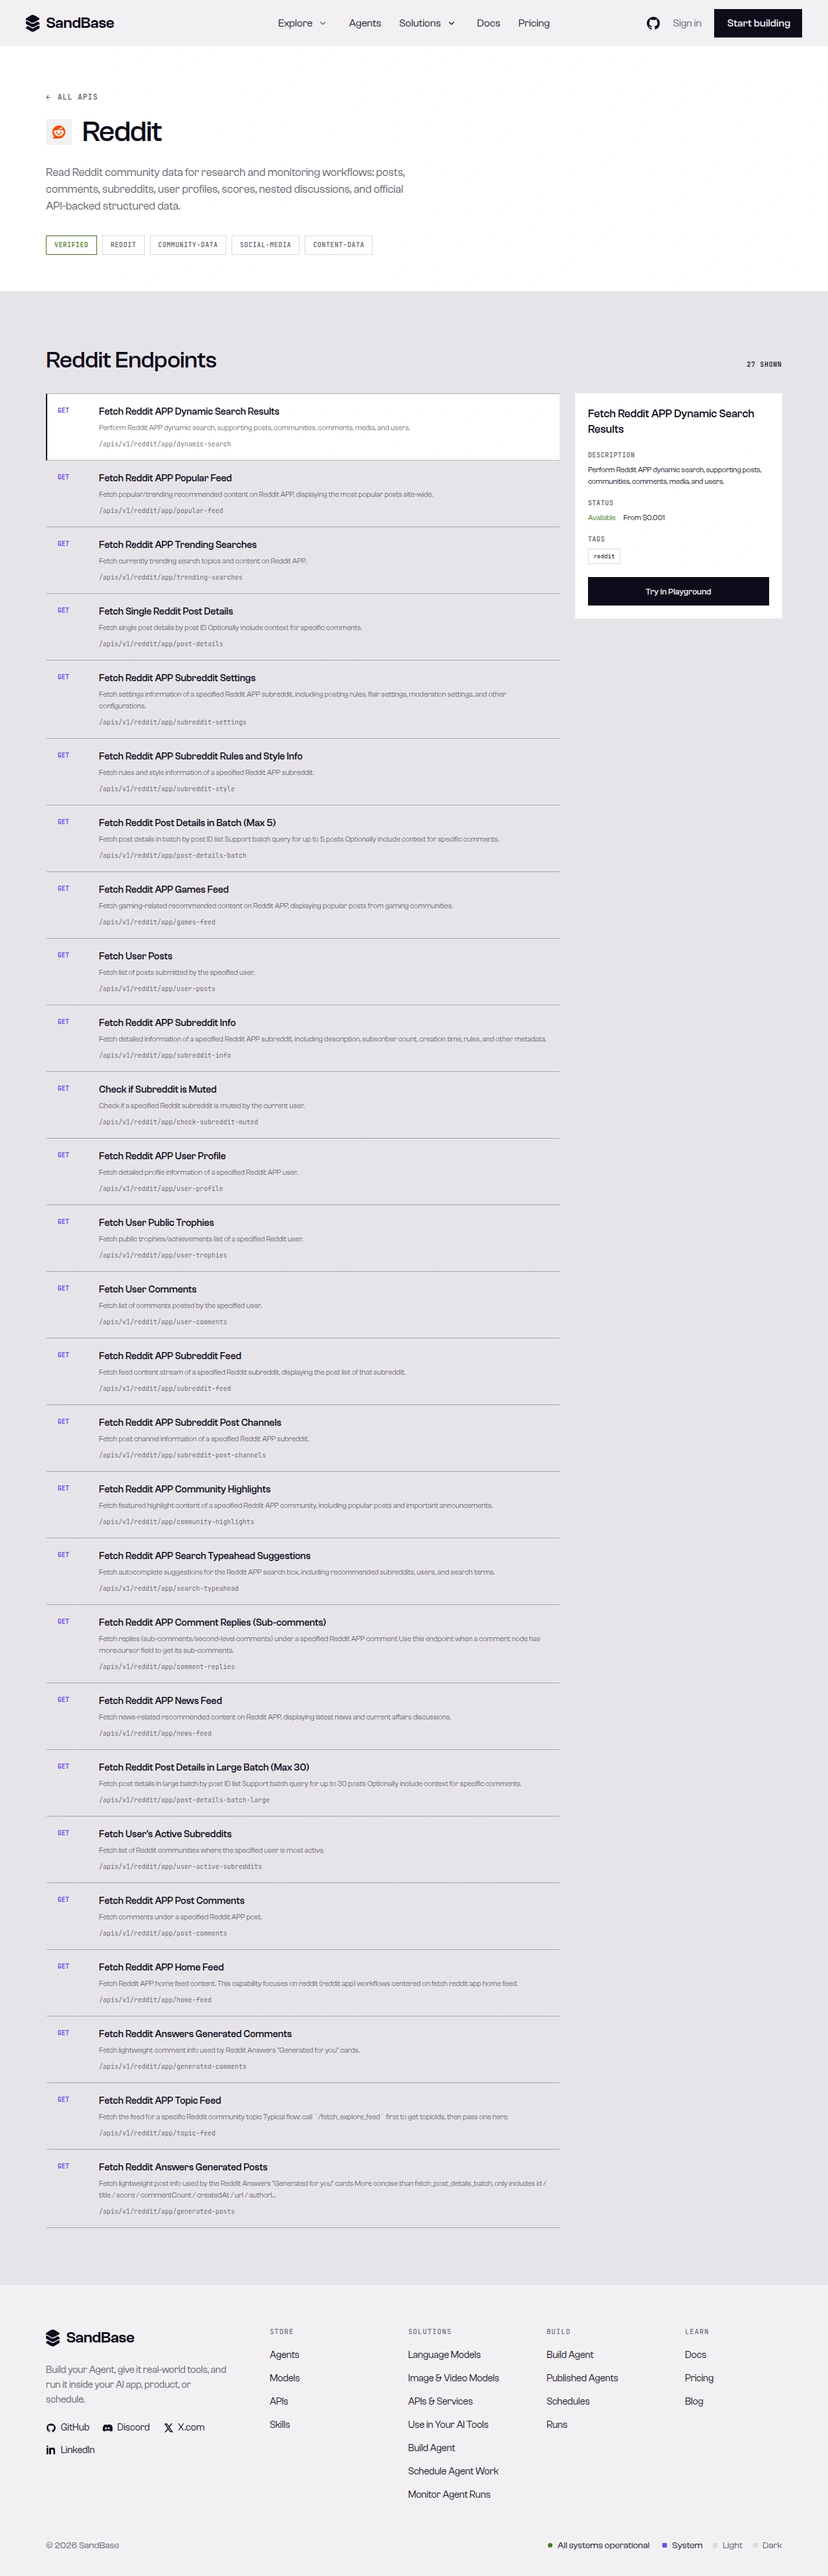 Historical app reference screenshot. Current parameters may differ; verify the linked live reference. The Reddit API page on SandBase — a tagged overview and the endpoint list, each with its path.
What Reddit provides vs. what SandBase adds
Public data comes from Reddit. SandBase does not own or operate Reddit; it provides a uniform API layer for eligible public-data workflows. Each capability becomes one stable endpoint, auth collapses to a single key, and responses come back as predictable JSON — so an agent can chain “look up a subreddit → read its top posts → pull a thread’s comments” along one convention instead of juggling OAuth scopes and a client library.
Quick start: your first call
SandBase exposes more than one API surface. The catalog may show GET paths under /apis/v1/...; this guide uses the vendor-qualified Model API path on each endpoint’s API reference. Do not swap the HTTP method or URL — follow the reference for the endpoint you choose.
Read a public subreddit by name:
This prospective request checks the platform envelope and prints payload keys only; it does not map business fields or establish a fresh test result.
import os
import requests

BASE = "https://api.sandbase.ai/v1/api/reddit"
API_KEY = os.environ.get("SANDBASE_API_KEY")
if not API_KEY:
    raise RuntimeError("Set SANDBASE_API_KEY before making a request")

HEADERS = {
    "Authorization": f"Bearer {API_KEY}",
    "Content-Type": "application/json",
}


def call(path: str, params: dict) -> dict:
    resp = requests.post(
        f"{BASE}/{path}", headers=HEADERS, json=params, timeout=90
    )
    resp.raise_for_status()
    try:
        body = resp.json()
    except ValueError as exc:
        raise RuntimeError("SandBase response was not valid JSON") from exc

    if not isinstance(body, dict):
        raise RuntimeError("SandBase response was not a JSON object")
    status = body.get("status")
    if status != "completed":
        safe_status = status if isinstance(status, str) and status in {
            "failed", "timeout", "running", "queued"
        } else "unknown"
        error = body.get("error")
        error_kind = "none" if error is None else (
            "object" if isinstance(error, dict) else "non-object"
        )
        raise RuntimeError(
            f"SandBase request did not complete: {safe_status}; error={error_kind}"
        )

    outputs = body.get("outputs")
    if not isinstance(outputs, list) or not outputs:
        raise RuntimeError("SandBase response is missing outputs[0]")
    first = outputs[0]
    if not isinstance(first, dict) or "data" not in first:
        raise RuntimeError("SandBase response is missing outputs[0].data")
    payload = first["data"]
    if not isinstance(payload, dict):
        raise RuntimeError("SandBase outputs[0].data was not a JSON object")
    return payload

payload = call("app/subreddit-info", {"subreddit_name": "programming"})
print("Payload keys:", sorted(payload))curl -X POST https://api.sandbase.ai/v1/api/reddit/app/subreddit-info \
-H "Authorization: Bearer $SANDBASE_API_KEY" \
-H "Content-Type: application/json" \
-d '{"subreddit_name": "programming"}'Data endpoints run in sync mode, so the JSON body is the answer — no polling. Every response uses the same envelope: an id, a status (completed on success), the model name, and an outputs array whose single item carries the payload under data. The block below is an illustrative response shape for a subreddit read — the endpoint reference only guarantees the envelope, so treat the field names and values as an example structure, not a guaranteed schema, and confirm the exact fields against a live response, since payloads vary and change over time:
{
  "id": "72ec0904-e8a3-433d-b776-9f8bf7f8217c",
  "status": "completed",
  "model": "reddit/app/subreddit-info",
  "outputs": [
    {
      "data": {
        "subredditInfoByName": {
          "name": "programming",
          "title": "programming",
          "id": "t5_2fwo",
          "type": "PUBLIC",
          "subscribersCount": 6922588,
          "publicDescriptionText": "Computer Programming"
        }
      }
    }
  ]
}
A failed or timeout run carries error and never outputs, so branch on status before reading outputs[0].data. Response shapes differ by endpoint — inspect one real response and map the exact path per endpoint. Note that Reddit responses often nest the payload under a named key (here, subredditInfoByName).
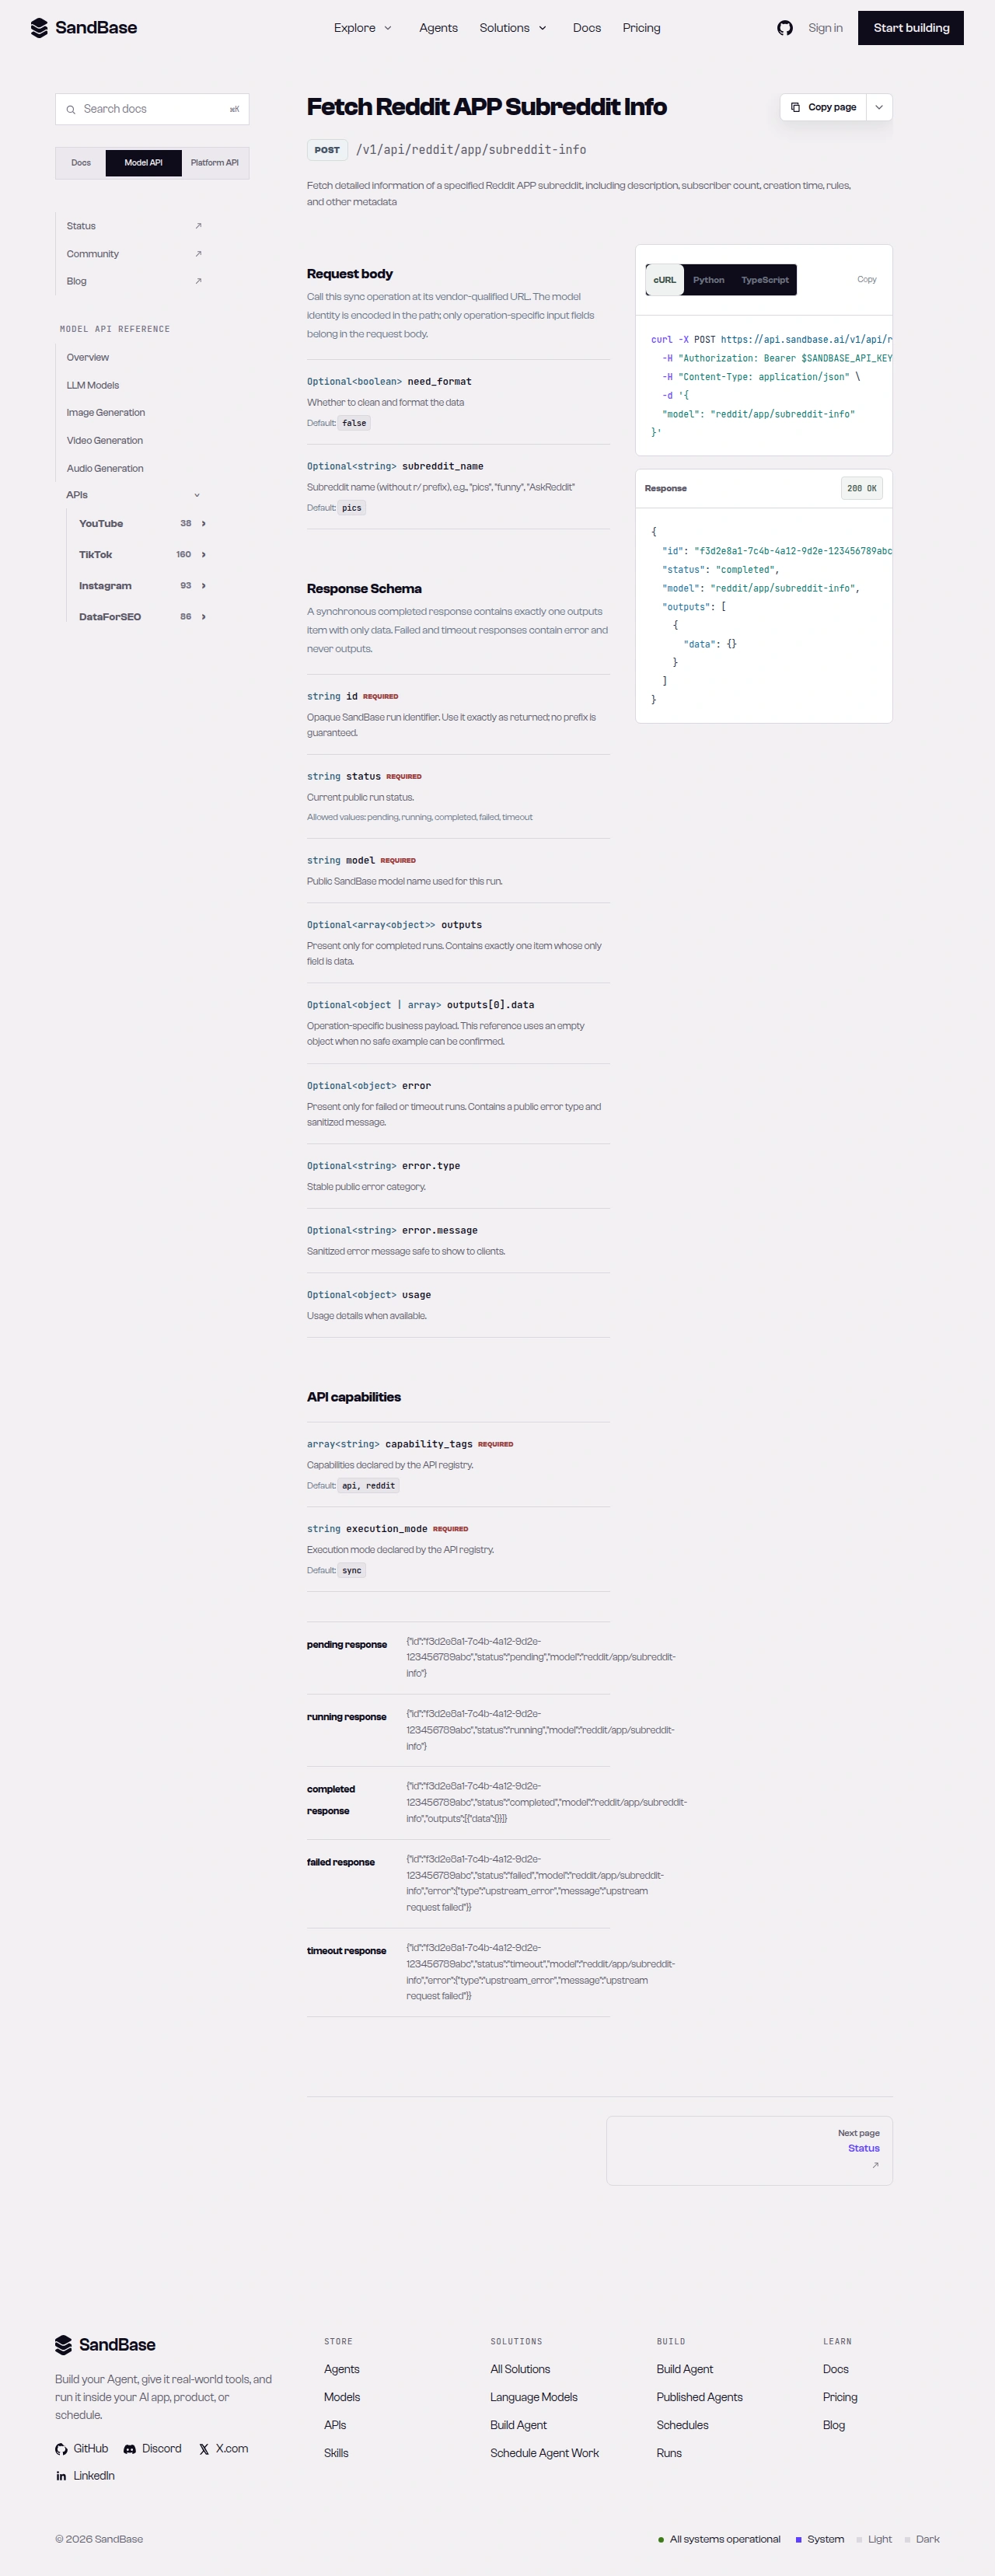 Historical app reference screenshot. Current parameters may differ; verify the linked live reference. The endpoint API reference is the source of truth for each parameter name and response path.
Capability map
| Capability cluster | Representative endpoint | Typical use |
|---|---|---|
| Subreddit info | reddit/app/subreddit-info | Community size and metadata by name |
| User profile | reddit/app/user-profile | Public user karma and account signals |
| Post details | reddit/app/post-details | Read a single post by id |
| Post comments | reddit/app/post-comments | Thread and sentiment analysis |
| Search | reddit/app/dynamic-search | Topic and keyword discovery |
Paging differs by endpoint — many app endpoints use an after cursor as the next-page pointer. On reddit/app/post-comments, after is the next-page cursor and sort_type is a separate, optional sort control (not part of paging). Read each endpoint’s schema.
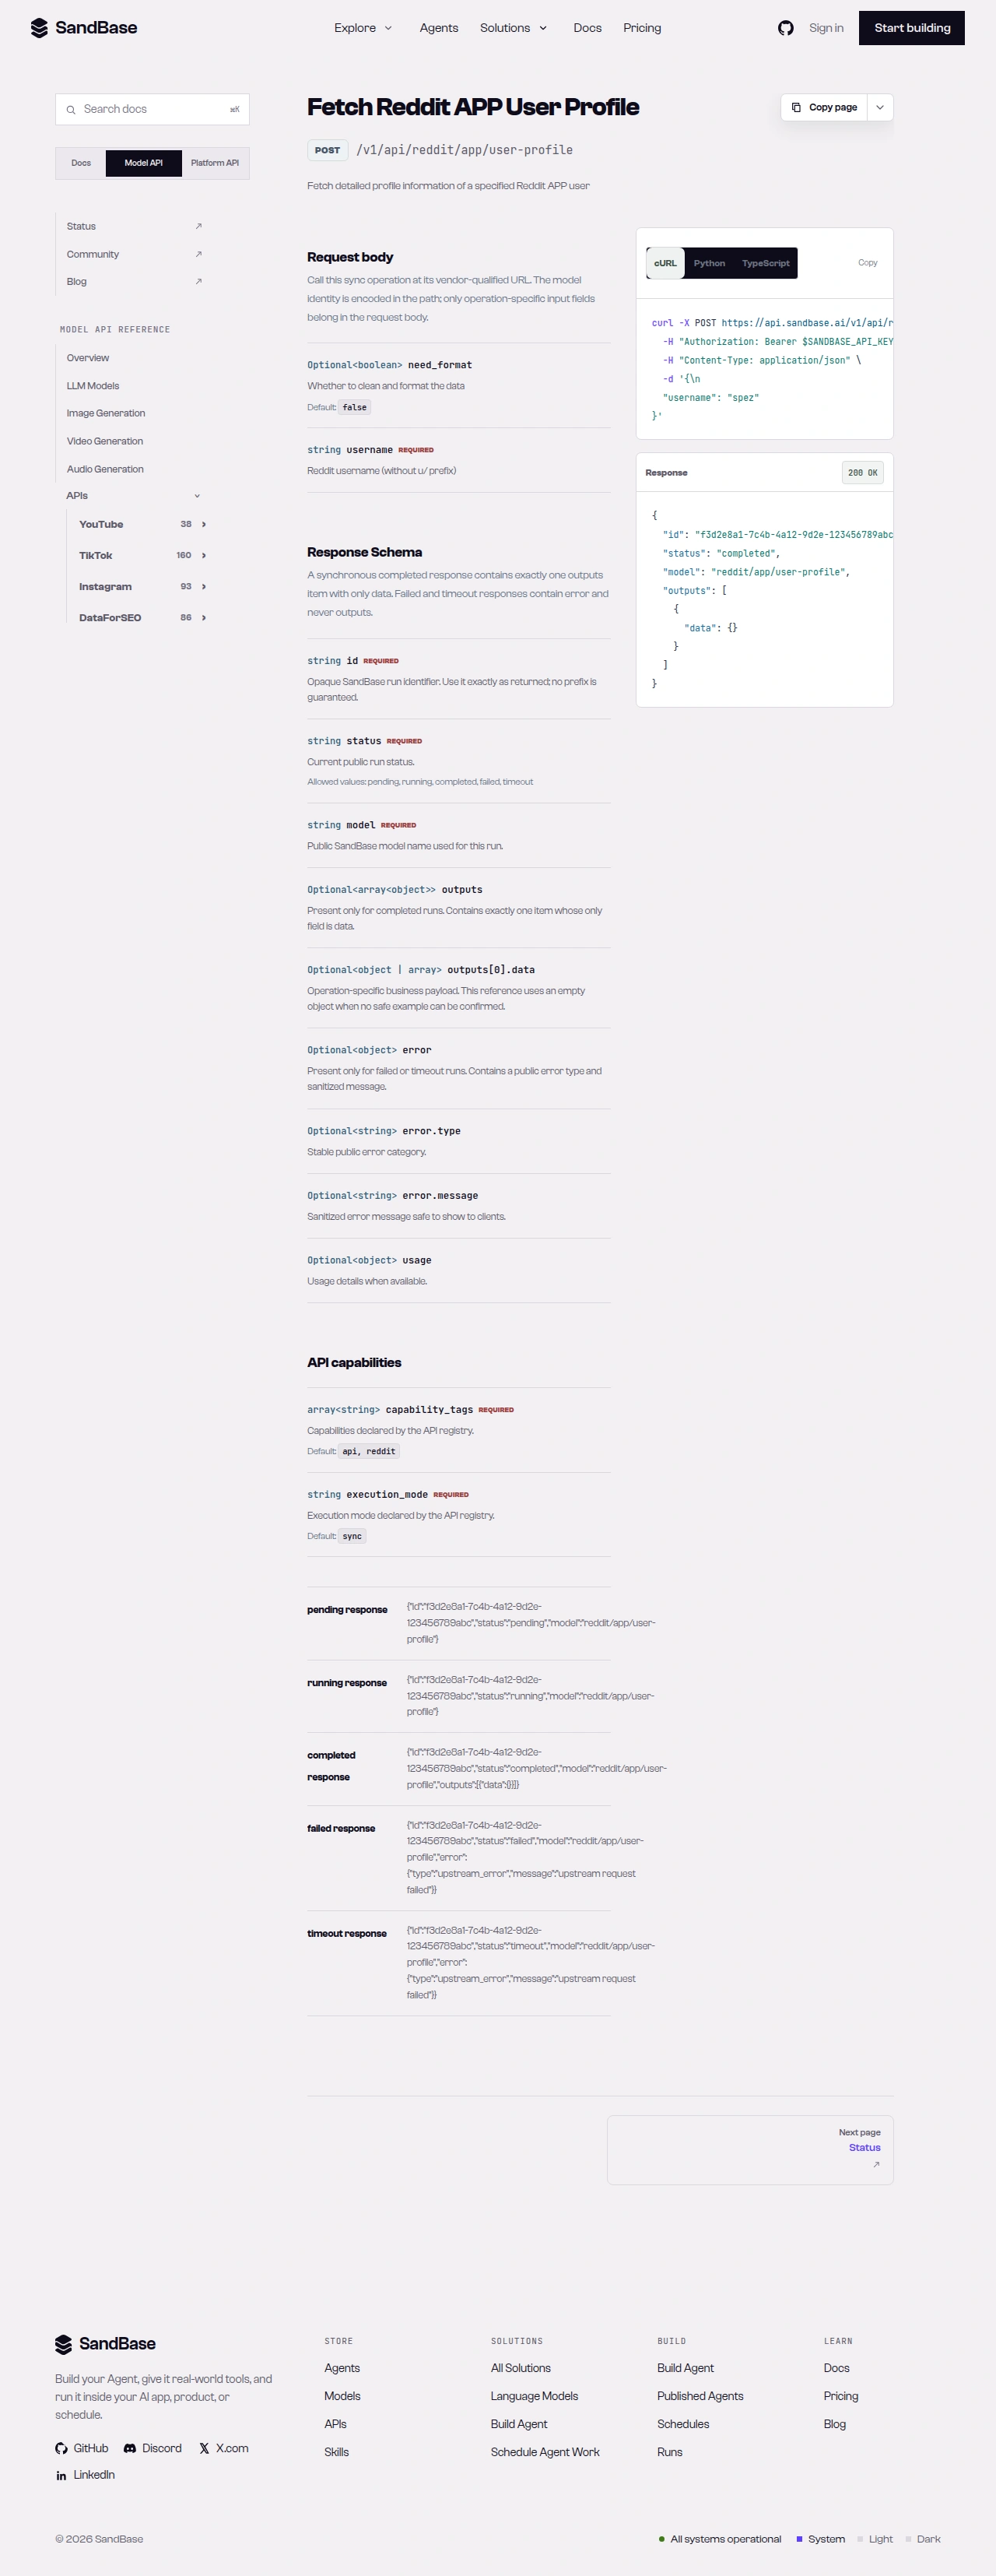 Historical app reference screenshot. Current parameters may differ; verify the linked live reference. The user-profile API reference — the route, the
username parameter, and the response schema.
For a known community, choose Subreddit Search with subreddit and optional query; for a selected post, choose Post Comments by URL with url. These normalized endpoints use cursor, while the older app comments variant uses post_id and after; do not copy app parameters into the normalized calls. See the Python community-research request examples for the two separate first requests.
Chaining calls in an agent workflow
Because every endpoint shares the same auth and the same response envelope, an agent can walk from a community to a thread while checking the inputs and payload of each surface. A common community-research pattern looks like this:
- Resolve the subreddit. Call
reddit/app/subreddit-infowith the community name and readsubscribersCount,type, andid— the community baseline. - Read the thread. Call
reddit/app/post-detailswith apost_id, thenreddit/app/post-commentsto pull the comment tree, paging with theaftercursor. - Enrich the author. Call
reddit/app/user-profilewith ausernameto attach karma and account context.
Each step returns the same { id, status, model, outputs } shape, so validate each response separately and map the business fields for its endpoint; shared envelope handling does not make the payloads interchangeable.
Common use cases
Reddit subreddit API for community sizing
Resolve a subreddit with reddit/app/subreddit-info and read subscribersCount, type, and publicDescriptionText to size and classify a community. Input: a subreddit name. Output: a structured community record. Endpoint: subreddit-info.
Reddit user API for author research
Read a public user with reddit/app/user-profile for karma breakdown and account flags. Input: a username. Output: a structured user record. Endpoint: user-profile.
Reddit search API for topic discovery
Run reddit/app/dynamic-search with a query — a search keyword, not a resource identifier — to surface posts and communities around a topic, then page results. Input: a search keyword. Output: matching posts and communities. Endpoint: dynamic-search. For separate request components, see the Reddit community-research tutorial.
Limitations and boundaries
- Public, read-only data only. No posting, voting, moderation, or member-authorized actions.
- Rate and volume. Treat responses as best-effort reads; handle HTTP 429 with backoff.
- Parameters and shapes follow the upstream surface. Payloads often nest under a named key (e.g.
subredditInfoByName,redditorInfoByName). Inspect a real response and read the schema first. - Not every listed endpoint is callable yet. Catalog availability can change; verify against the live API reference before building on a specific endpoint.
- This is not an official Reddit partnership. SandBase provides uniform access to public data; respect Reddit’s terms and applicable rules for your use case, including any commercial-use restrictions.
FAQ
Do I need a Reddit developer app or OAuth?
No. You authenticate to SandBase with your SANDBASE_API_KEY. You do not register a Reddit app, manage OAuth tokens, or install PRAW for these read endpoints.
What identifies a subreddit, user, or post?
Natural identifiers: subreddit_name, username, and post_id. Search takes a query.
How does pagination work?
Most app endpoints use an after cursor returned in the response to fetch the next page. On reddit/app/post-comments, after is the next-page cursor and sort_type is a separate, optional sort control (not paging). Read each endpoint’s schema.
Can I read private subreddits or member-only data? No. The API returns public data only. Private communities, direct messages, and member-authorized data are out of scope.
Start with one subreddit request
Create a SandBase API key, run subreddit-info against a public community, and inspect the returned schema before you expand to posts, comments, users, or search. When you are ready:
Found this useful? Share it