Reddit Community Monitoring API Workflow | SandBase
A Reddit community monitoring API workflow: size a subreddit, discover topic conversations, and profile authors — one SandBase key, no OAuth app.
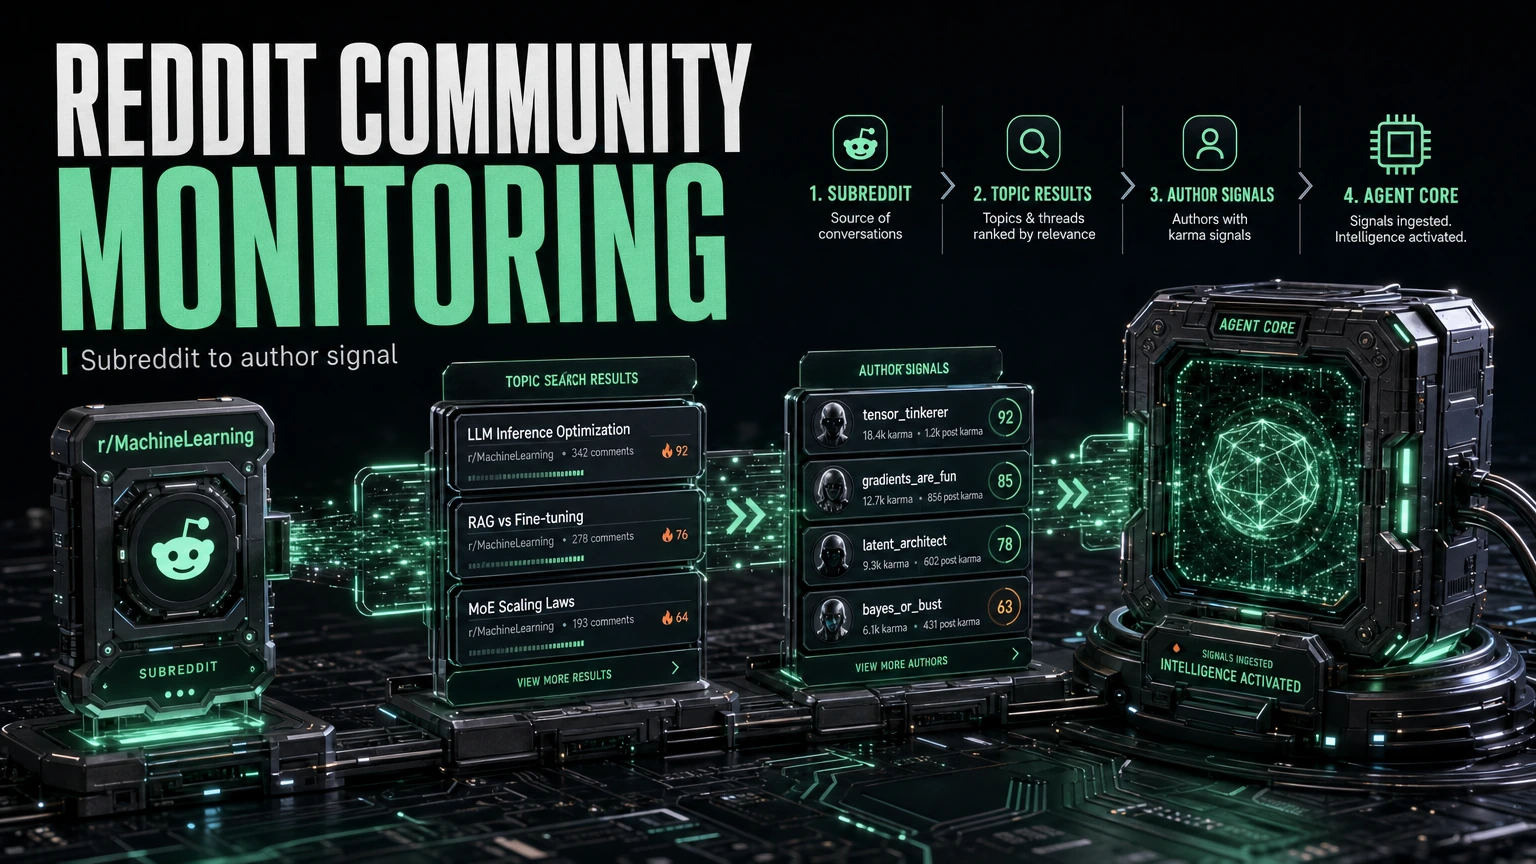
Community monitoring on Reddit boils down to three questions: how big is this community, what are people saying about my topic, and who is saying it? This tutorial outlines request components for those three questions using the SandBase Reddit API — no Reddit OAuth app of your own and no PRAW, though you still need a SandBase API key. The endpoint reference only guarantees the response envelope (id, status, model, outputs[0].data); the business fields shown below are an illustrative structure, not a guaranteed schema, so treat both the field names and the values as examples and confirm them against a live response.
If you want the full endpoint tour first, start with the Reddit public data API hub. This piece shows request components and explicitly illustrative field mappings.
Key takeaway
- Three steps:
subreddit-info(baseline) →dynamic-search(discovery) →user-profile(author signal).- Every call is
POST /v1/api/reddit/<path>with oneSANDBASE_API_KEY; responses share the{ id, status, model, outputs }envelope.- In the illustrative shapes, Reddit payloads nest under named keys (
subredditInfoByName,redditorInfoByName) — read the exact path and confirm it against a live response.- Only the envelope (
id,status,model,outputs[0].data) is guaranteed; the business fields are illustrative — confirm them against a live response.- Public, read-only data only; no Reddit OAuth app of your own and no posting or voting, but you do need a SandBase API key.
The workflow at a glance
| Step | Endpoint | Input | You get |
|---|---|---|---|
| 1. Size the community | reddit/app/subreddit-info | subreddit_name | subscribers, type, description |
| 2. Discover conversations | reddit/app/dynamic-search | query | search results for a topic |
| 3. Profile the author | reddit/app/user-profile | username | karma breakdown, account flags |
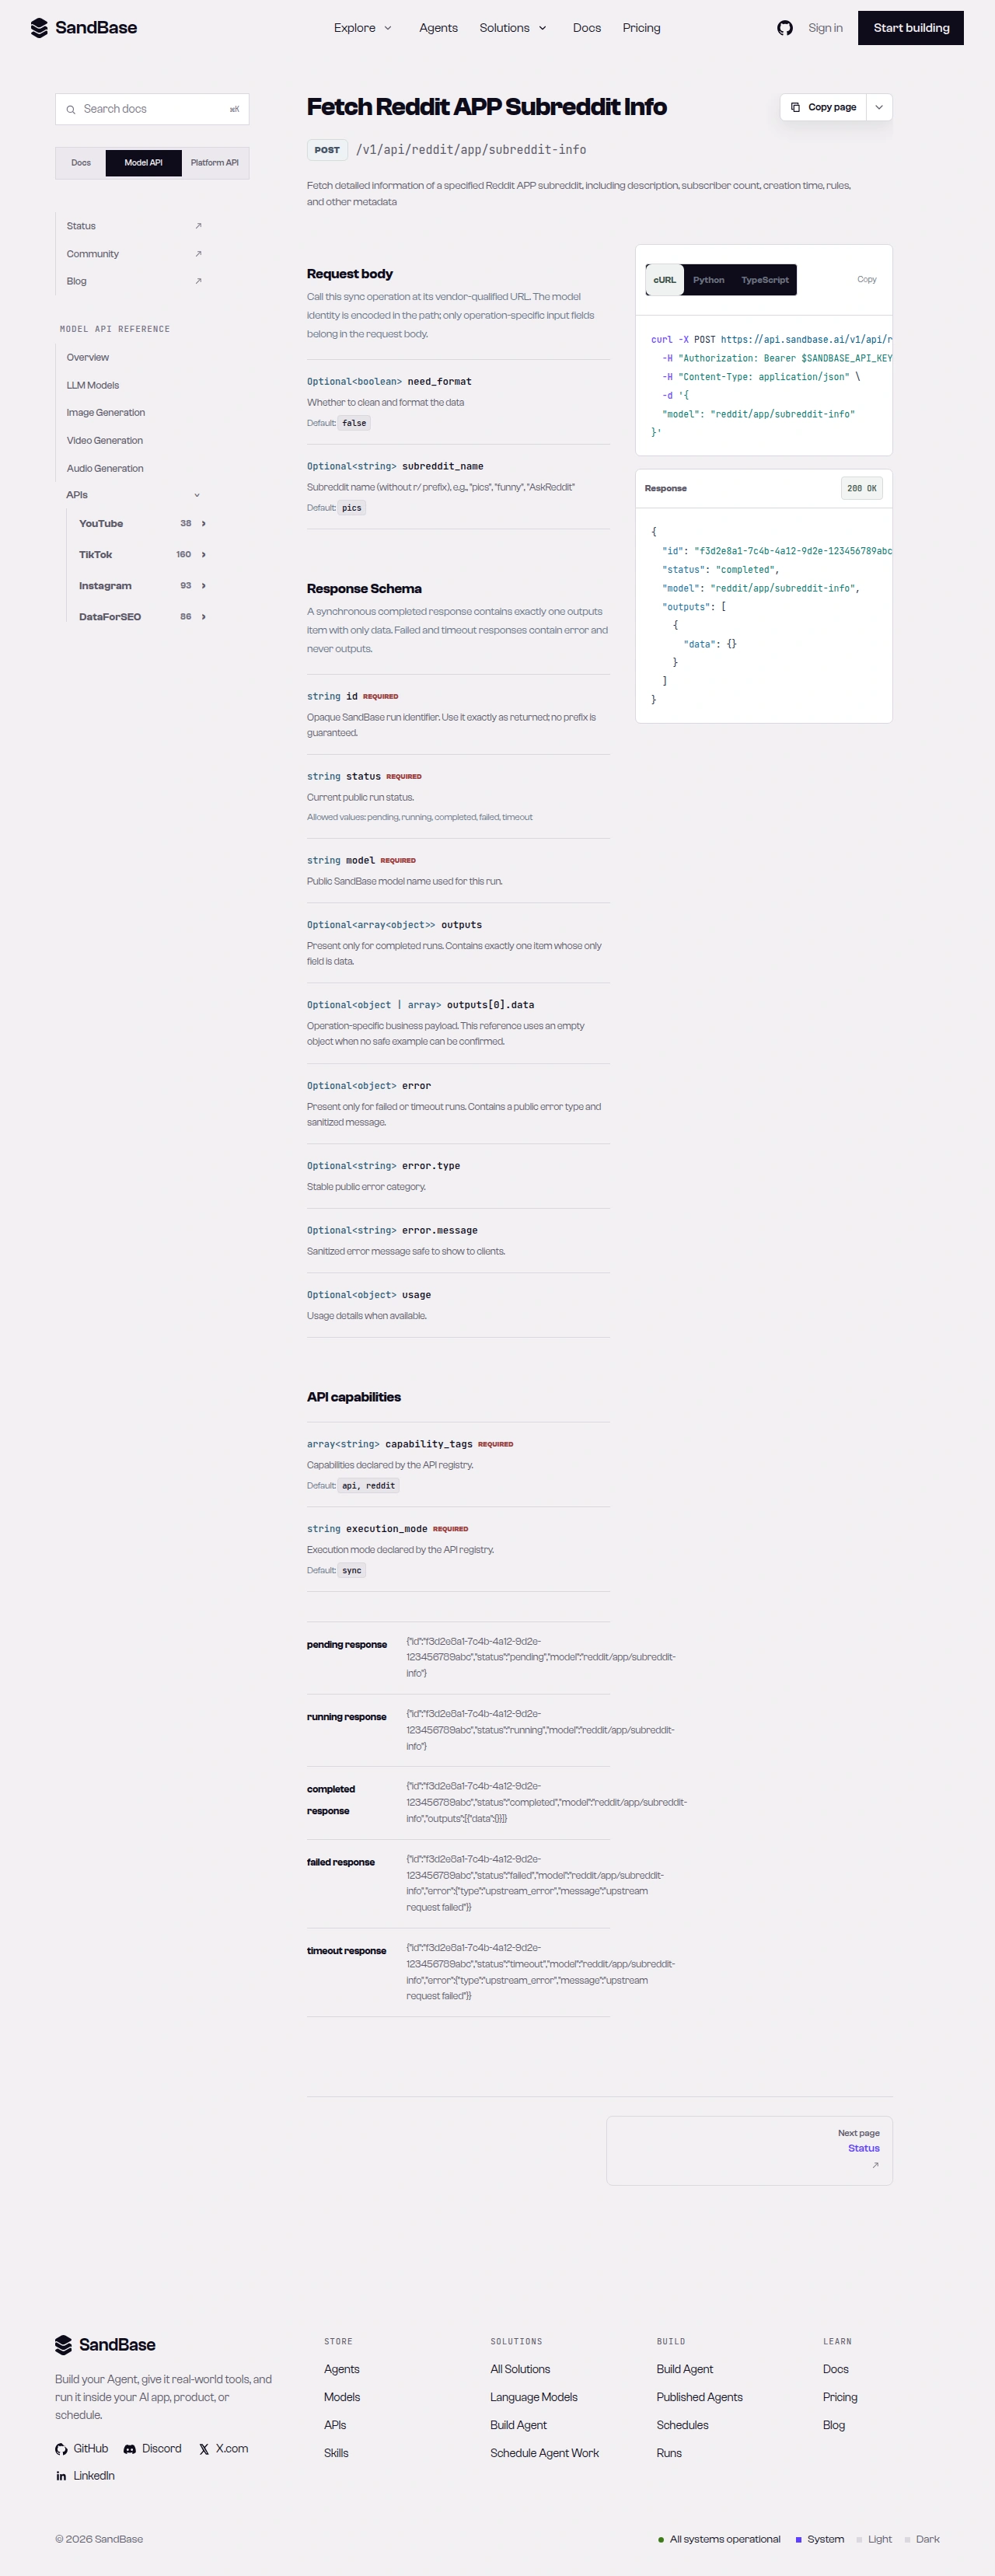 Historical app reference screenshot. Current parameters may differ; verify the linked live reference. The endpoint API reference is the source of truth for each parameter name and response path.
Step 1 — Size the community
Before you monitor a community, establish a baseline: how large and active is it? Resolve the subreddit by name:
These are prospective request examples, not fresh test results. Load the helper definitions once, then run only the request you want.
import os
import requests

BASE = "https://api.sandbase.ai/v1/api/reddit"
API_KEY = os.environ.get("SANDBASE_API_KEY")
if not API_KEY:
    raise RuntimeError("Set SANDBASE_API_KEY before making a request")

HEADERS = {
    "Authorization": f"Bearer {API_KEY}",
    "Content-Type": "application/json",
}


def call(path: str, params: dict) -> dict:
    resp = requests.post(
        f"{BASE}/{path}", headers=HEADERS, json=params, timeout=90
    )
    resp.raise_for_status()
    try:
        body = resp.json()
    except ValueError as exc:
        raise RuntimeError("SandBase response was not valid JSON") from exc

    if not isinstance(body, dict):
        raise RuntimeError("SandBase response was not a JSON object")
    status = body.get("status")
    if status != "completed":
        safe_status = status if isinstance(status, str) and status in {
            "failed", "timeout", "running", "queued"
        } else "unknown"
        error = body.get("error")
        error_kind = "none" if error is None else (
            "object" if isinstance(error, dict) else "non-object"
        )
        raise RuntimeError(
            f"SandBase request did not complete: {safe_status}; error={error_kind}"
        )

    outputs = body.get("outputs")
    if not isinstance(outputs, list) or not outputs:
        raise RuntimeError("SandBase response is missing outputs[0]")
    first = outputs[0]
    if not isinstance(first, dict) or "data" not in first:
        raise RuntimeError("SandBase response is missing outputs[0].data")
    payload = first["data"]
    if not isinstance(payload, dict):
        raise RuntimeError("SandBase outputs[0].data was not a JSON object")
    return payload
The older app field mapping below is illustrative Python-like pseudocode; inspect a real payload before implementing it.
info = call("app/subreddit-info", {"subreddit_name": "programming"}).get("subredditInfoByName", {})
print(info.get("name"), info.get("subscribersCount"), info.get("type"))
# example output: programming 6922588 PUBLIC
Note the nesting in this illustrative shape: the payload sits under subredditInfoByName, with fields such as name, subscribersCount, and type. Only the envelope is guaranteed, the field mapping below is illustrative and needs type checks before use. The values above are illustrative — a subreddit read can surface a subscriber count, a type, and a community id, but confirm the exact field names and values against a live response, since the business fields are not a guaranteed schema. Store that baseline so later runs can track subscriber growth over time.
Step 2 — Discover topic conversations
With a baseline set, search for conversations about your topic. dynamic-search takes a query (your search keyword) plus, per the reference, independent optional parameters: a sort to order supported result types, time_range for post/media time filtering, and an after cursor that you carry over from the previous response to fetch the next page:
results = call("app/dynamic-search", {"query": "machine learning"})
# results is a structured search layout — read the schema and inspect
# a real response to map the exact field paths before iterating;
# to page, pass the `after` cursor from the previous response
The dynamic-search response is a structured layout rather than a flat list, and the current reference documents a nested layout. Run one real request with the query and any optional sort you need, inspect the response, and map the field paths you actually use — do not assume a single call returns both posts and communities.
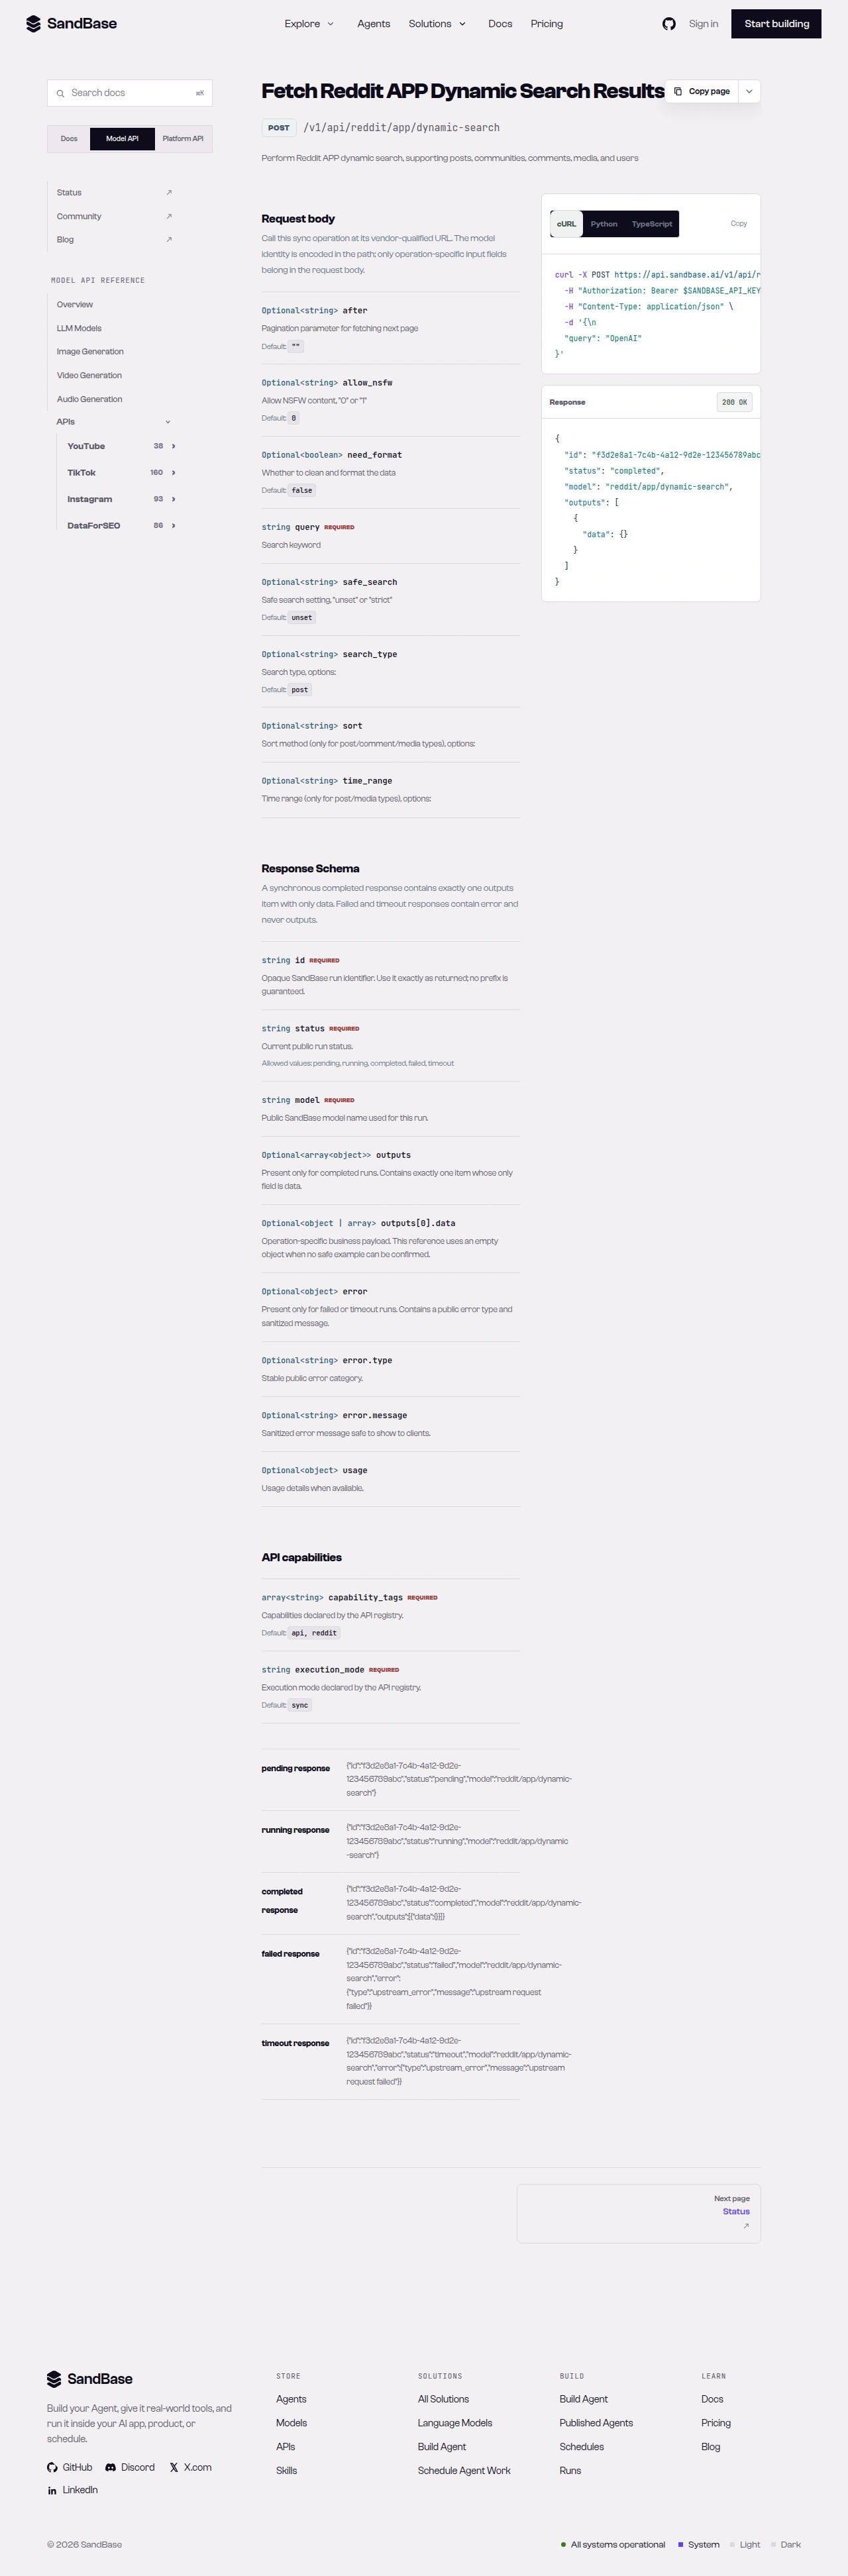 Historical app reference screenshot. Current parameters may differ; verify the linked live reference. dynamic-search returns a structured layout under the search key — read the schema before iterating.
Step 3 — Profile the authors
Once you have surfaced conversations, profile the accounts behind them to weight their signal. user-profile takes a username:
user = call("app/user-profile", {"username": "spez"}).get("redditorInfoByName", {})
karma = user.get("karma", {})
print(user.get("name"), karma.get("total"), "total karma")
# example output: spez 940980 total karma
print("employee:", user.get("isEmployee"))
# example output: employee: True
Again note the nesting under redditorInfoByName in this illustrative shape. A user read can surface a karma object with fields such as fromPosts, fromComments, and total, plus account flags like isEmployee. Only the envelope is guaranteed, the mapping is pseudocode, not a tested parser. Treat karma and account age as optional ranking or filtering signals — they are context, not a verified measure of credibility or expertise. The block below is an illustrative response shape: the business fields are not a guaranteed schema, so treat both the field names and the values as examples and confirm the exact fields against a live response, since payloads vary and change over time.
{
"id": "a98dfb8b-afa5-4471-9f91-33cadaca5d99",
"status": "completed",
"model": "reddit/app/user-profile",
"outputs": [
{
"data": {
"redditorInfoByName": {
"name": "spez",
"id": "t2_1w72",
"isEmployee": true,
"karma": { "fromPosts": 184487, "fromComments": 756493, "total": 940980 }
}
}
}
]
}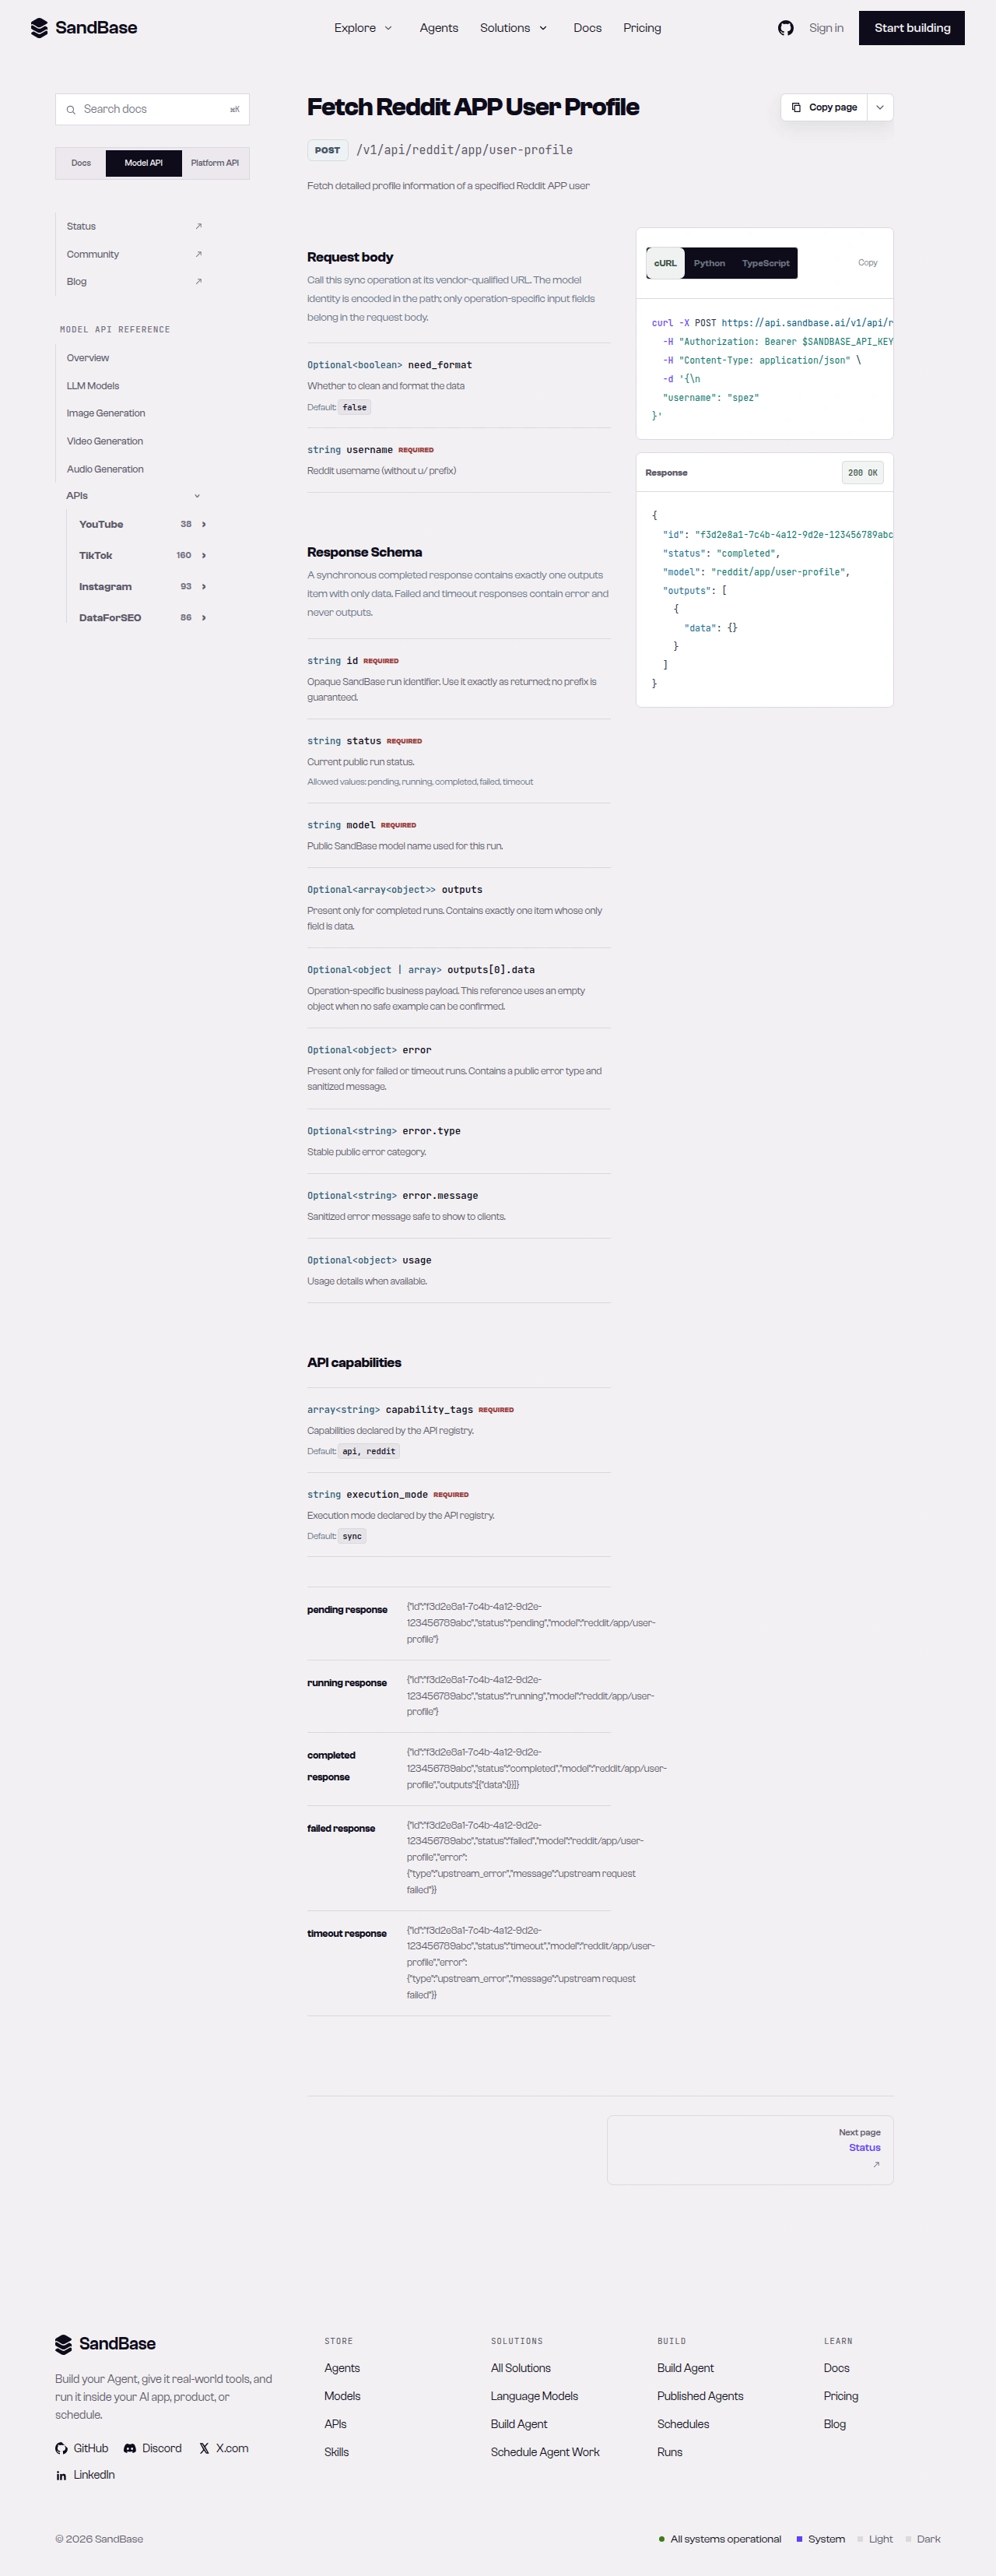 Historical app reference screenshot. Current parameters may differ; verify the linked live reference. user-profile returns karma and account flags under redditorInfoByName.
Putting it together
The older three-component workflow is illustrated below as Python-like pseudocode, not a runnable monitoring pass. Inspect a response before mapping business fields or choosing an author; the article does not implement that extraction, storage or scheduling.
# 1. Request a community baseline.
baseline_payload = call("app/subreddit-info", {"subreddit_name": "programming"})
# Inspect the payload and locate the community object before storing fields.
# If a subscriber count is absent, preserve it as unknown, not zero.

# 2. Request topic discovery on the older app surface.
hits = call("app/dynamic-search", {"query": "machine learning"})
# Inspect its layout and manually choose a verified public author username.

# 3. Optionally request that author's public profile.
# Call app/user-profile with the verified username, then inspect its payload.
# Store karma only if present. Keep a missing/null isEmployee value unknown;
# only an explicit false is false. No author-extraction function is supplied.
The helper centralizes envelope validation. Retries, rate-limit backoff, business-field mapping and persistence still require separate implementation and verification.
Search one subreddit, then inspect a selected thread
For a narrower starting point, use the Reddit Subreddit Search API to search posts by keyword within one known community. This request uses programming without r/, the keyword agent, sort: "new" and timeframe: "month". It is a request example, not a tested result or a full monitoring program.
Reuse the helper above and run this first request on its own:
search_payload = call("subreddit-search", {
    "subreddit": "programming",
    "query": "agent",
    "sort": "new",
    "timeframe": "month",
})
print("Search payload keys:", sorted(search_payload))
The helper reads outputs[0].data. Inspect that business payload separately: the documentation shows found and a nested data.posts list, not posts at the platform response’s top level. This sample only prints keys; it does not parse results. Post text may be absent or truncated.
Choose a post manually and open it on Reddit to verify its full, public post URL. Set that complete URL in REDDIT_POST_URL, then run this separate first request with the Reddit Post Comments API:
POST_URL = os.environ["REDDIT_POST_URL"]
comments_payload = call("post-comments", {"url": POST_URL})
print("Comments payload keys:", sorted(comments_payload))
The comments reference shows business-level found and data.comments. Comments are a flat array with parentId links; one page does not establish a complete thread. These examples do not select a search result automatically or rebuild a comment tree.
Neither default request includes a cursor or requireFields. If you later need search pagination and approve the possible higher quote, add "requireFields": ["nextCursor"] to the first search request. A required field can change the source and price; unsupported combinations can be rejected, genuinely absent fields may still be absent, and later pages retain the first-page source. Do not assume a fixed price or a returned token. Only after inspecting a real response should you pass its complete, valid data.nextCursor as cursor; keep the same search parameters, or the same url for comments. Never reuse a shortened documentation token.
Read the current search routing and pagination reference.
Handling the rough edges
- Mind the nesting. In these illustrative shapes, Reddit payloads sit under named keys (
subredditInfoByName,redditorInfoByName). Only the envelope is guaranteed, so read the exact path defensively rather than assuming top-level fields. - Inspect
reddit/app/dynamic-searchbefore iterating. Its layout is structured, not a flat list, and field availability can vary — map the field paths from a real response, page via theaftercursor, and setsortif you need a specific order. - Check HTTP, JSON and the envelope. The helper raises on HTTP errors, invalid JSON, non-completed status and missing or malformed
outputs[0].data. Anerrorvalue may be null or a different type, so it is not assumed to be an object. Business fields still need inspection; no automatic retry or backoff is implemented. - Respect rate limits. Handle HTTP 429 with backoff and pace your polling.
- Public data only. No Reddit OAuth app of your own, no voting or posting, and no private-community access — though you do authenticate every call with a SandBase API key.
Why run monitoring at the API layer
Public API reads can become inputs to a monitoring system once you have verified the fields you use and implemented storage, deduplication and error handling. This article shows request components and an illustrative older app workflow; it does not implement a scheduled monitor or establish subscriber trends, full discussion coverage or sentiment analysis.
The shared helper can validate the platform envelope for different endpoints, but each endpoint still has its own inputs and business payload. Start with one request, inspect it, then choose the next public resource manually. Adding comments by URL does not by itself implement a complete search-to-thread pipeline.
FAQ
Do I need a Reddit OAuth app or account?
No. You authenticate to SandBase with your SANDBASE_API_KEY. These read endpoints need no Reddit OAuth app, no PRAW, and no account on your side.
How do I page through results and comments?
The older reddit/app/dynamic-search and reddit/app/post-comments variants use after; app comments also have a separate sort_type. The normalized reddit/subreddit-search and URL-based reddit/post-comments use cursor. Inspect the selected endpoint and a real response before continuing; do not copy pagination parameters across variants.
Can I read private or account-only data? No. The workflow is public, read-only data — subreddit stats, search results, and public profile fields. There is no voting, posting, or access to private communities.
Next steps
You now have request components to inspect and an illustrative workflow to adapt—not a fully operational community monitor. Verify the responses and implement the missing parsing, storage and reliability work before treating them as a repeatable system.
For a separate next step, explore the Personal Agent API. These HTTP examples do not create or run a hosted Agent.
- Read the Reddit public data API hub
- Get a SandBase API key
- API references for each step: subreddit-info, dynamic-search, and user-profile
Found this useful? Share it