Exa Search API | SandBase
Use the Exa search API in Python with SandBase to find official documentation with domain filters and highlights. Optionally request a separate cited answer.
To find official documentation with the Exa search API in Python through SandBase, start with a focused query, restrict the source domains, and request highlights. The example below searches for OpenAI agent tools documentation on openai.com. Highlights help identify relevant pages before reading them in full.
Search retrieves sources; Answer is a separate query-based request for a cited answer. These are API components, not a complete hosted agent. The current request and field descriptions follow SandBase’s public references; the September 27 capture later in this guide remains historical evidence, not a new test. 3 4
Key takeaway
- Use Search with
includeDomainsandcontents.highlightsto narrow sources and inspect matching snippets. 3- Call the exact Model API POST route with a server-side
SANDBASE_API_KEY. 1 2- Both current READMEs document the result at
outputs[0].data; do not add a top-leveloutputfallback. 3 4- Answer is optional and independent: Search filters and returned pages do not automatically carry into it. 4
Read the documented response wrapper
For Search and Answer, the current README places the result in outputs[0].data. The helper below checks completion and this wrapper only. It does not validate Search results or Answer citations, and a present, non-null payload is not proof of useful application data. A missing or null payload is an error, not an empty successful result. 3 4
Which Exa endpoint do you need?
| Your task | Endpoint | Request used here |
|---|---|---|
| Find official documentation and matching snippets | exa/search | query, includeDomains, numResults, contents.highlights |
| Optionally ask for a separate cited answer | exa/answer | query; optional text |
The Search README also points to Exa Contents for reading known URLs. It is a separate content-extraction capability, not an implemented third step in this example. 3
SandBase vs. the direct Exa API
| Your situation | Use |
|---|---|
| You want one key and one convention across many providers | SandBase Exa API (this guide) |
| You need Exa-specific features or billing directly | Exa’s own API and dashboard |
SandBase provides a uniform Model API layer over Exa’s capabilities; when you need vendor-specific controls or a direct contract, use Exa’s own API.
What you can get from the Exa API
- Search: the current README describes
results[], with pageurl,titleand requestedhighlights[]. A title can be empty. Its trimmed sample is reference material, not the response to the request below. 3 - Answer: the README describes
answerandcitations[]. Citation fields includetitle,url,publishedDate,author, and pagetextwhen requested. These descriptions are not a complete schema or a guarantee that every call supplies every field. 4
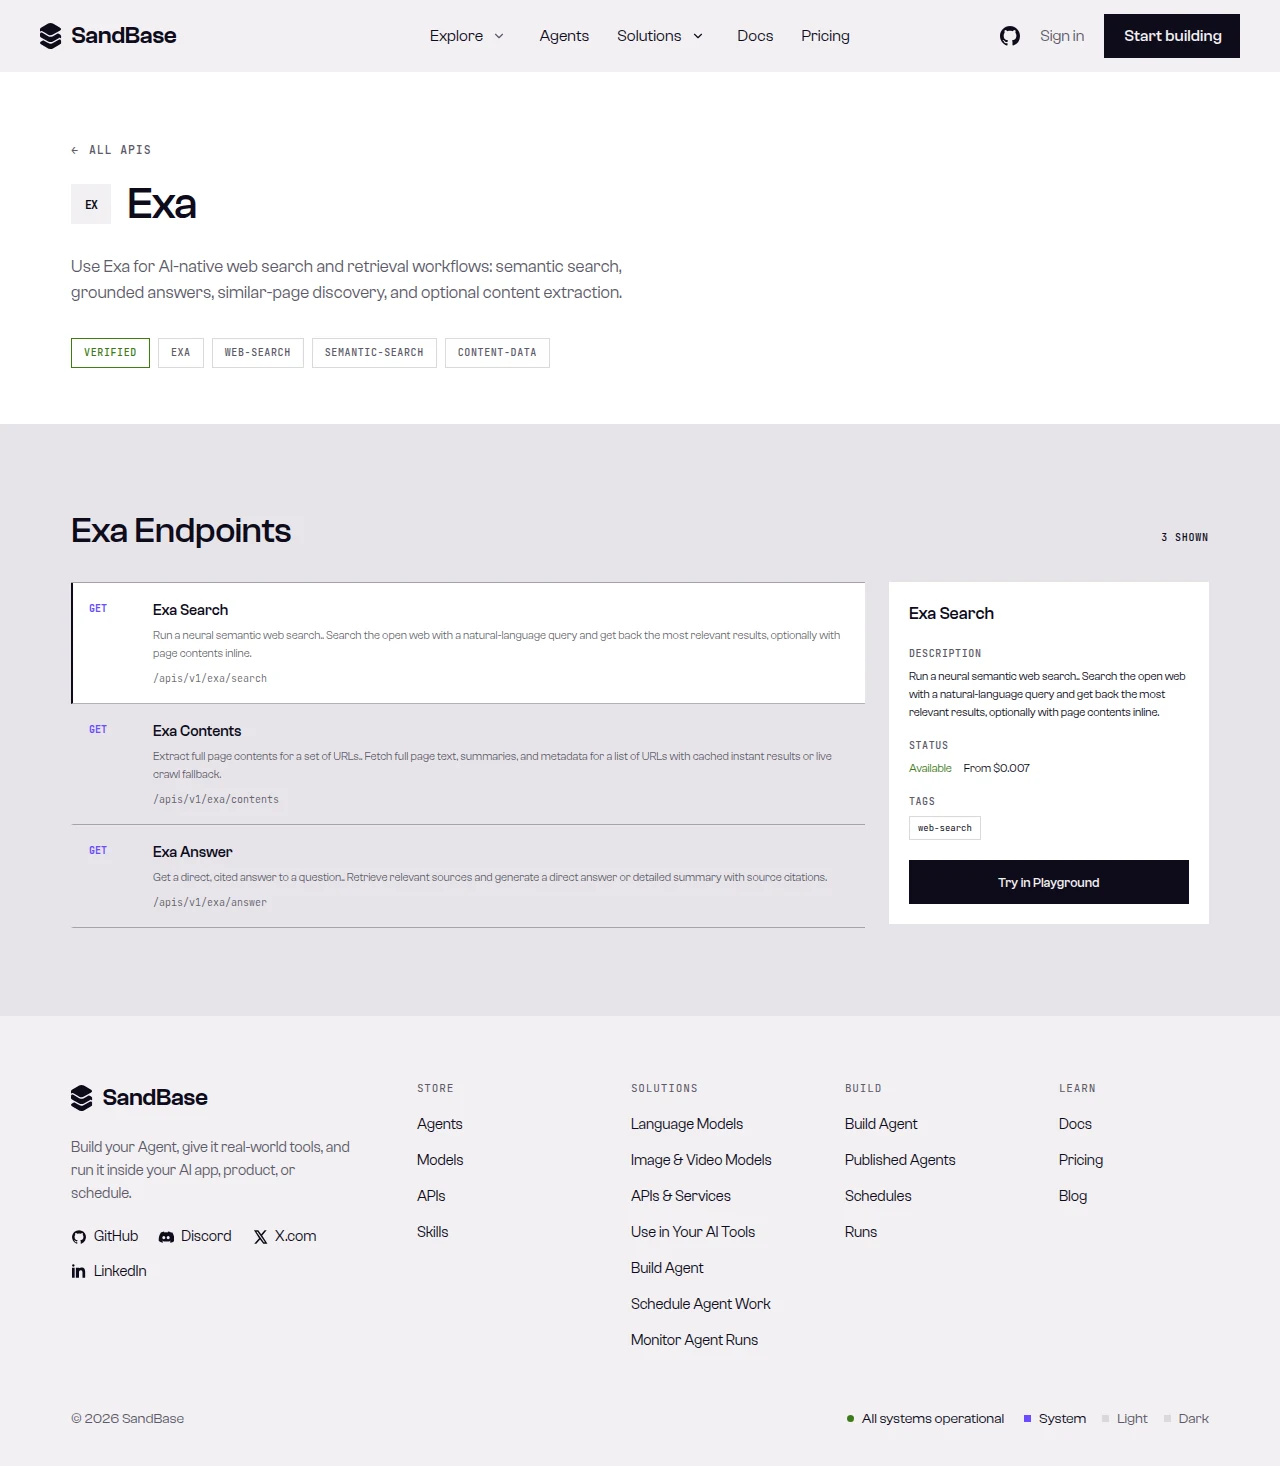 Historical screenshot retained from the original article: the Exa catalog overview and endpoint list; not a new request result.
How to use the Exa search API in Python with SandBase
This uses the Model API POST route, not a catalog GET route. Install requests in your server environment and set SANDBASE_API_KEY there; never put the key in browser code. The query matches the restricted domain, and the request omits optional search modes and category/date combinations. It is a documentation-based example, not a tested run. Exa Search request reference
import os
import requests

SEARCH_URL = "https://api.sandbase.ai/v1/api/exa/search"
ANSWER_URL = "https://api.sandbase.ai/v1/api/exa/answer"


def read_documented_data(body):
    # Wrapper checks only; no application-data parsing or fallback.
    if not isinstance(body, dict):
        raise RuntimeError("SandBase response must be a JSON object")

    status = body.get("status")
    error = body.get("error")
    if status != "completed" or error is not None:
        # Never echo provider messages, raw payloads or arbitrary status text.
        status_label = status if status in (
            "completed", "failed", "timeout", "pending", "running"
        ) else "missing_or_unexpected"
        error_kind = "none" if error is None else type(error).__name__
        raise RuntimeError(
            f"SandBase response rejected: status={status_label}; "
            f"error_kind={error_kind}"
        )

    outputs = body.get("outputs")
    if not isinstance(outputs, list) or not outputs:
        raise RuntimeError("SandBase response is missing documented outputs")
    first = outputs[0]
    if not isinstance(first, dict):
        raise RuntimeError("SandBase outputs[0] must be an object")
    if "data" not in first or first["data"] is None:
        raise RuntimeError("SandBase outputs[0].data is missing or null")
    return first["data"]  # Preserve {}, [], 0, False and other non-null values.


def post_exa_model(url, payload):
    # Scope this helper to these two documented Model API routes.
    if url not in (SEARCH_URL, ANSWER_URL):
        raise ValueError("Unsupported Exa Model API route")
    key = os.environ.get("SANDBASE_API_KEY")
    if not key or not key.strip():
        raise RuntimeError("Set SANDBASE_API_KEY in the server environment")

    try:
        response = requests.post(
            url,
            headers={
                "Authorization": f"Bearer {key}",
                "Content-Type": "application/json",
            },
            json=payload,
            timeout=(10, 60),
        )
        response.raise_for_status()
    except requests.HTTPError:
        raise RuntimeError(
            f"SandBase HTTP request failed: status={response.status_code}"
        ) from None
    except requests.RequestException:
        raise RuntimeError("SandBase network request failed") from None

    try:
        body = response.json()
    except ValueError:
        raise RuntimeError("SandBase response was not valid JSON") from None
    return read_documented_data(body)


if __name__ == "__main__":
    search_data = post_exa_model(
        SEARCH_URL,
        {
            "query": "OpenAI agent tools documentation",
            "includeDomains": ["openai.com"],
            "numResults": 5,
            "contents": {"highlights": True},
        },
    )
    # Keep data for caller-side inspection; do not print raw provider payloads.
    print("Search response passed documented-wrapper checks only.")
Optional: request a separate cited answer
For an optional cited answer, send a separate query to Answer. Its documented parameters are query, type, text and outputSchema; this example sends only query. Add text: true if you want each citation’s page text. Search’s contents.text requests content with search results; Answer’s text requests content with citations. They are different settings on different endpoints. Exa Answer request reference 4
# Optional separate request; uses the definitions above.
answer_data = post_exa_model(
    ANSWER_URL,
    {"query": "OpenAI agent tools documentation"},
)
print("Answer response passed documented-wrapper checks only.")
Historical capture: September 27, 2026
The following block is one capture from my search call (search run id 67700c0e-9398-4f89-954d-42a434ed2706, tested on 2026-09-27, UTC), preserved from the original article by Sophie Lin. It is historical and illustrative, not the current response contract or the result of the new request above. Its top-level output must not be copied into current client code.
{
  "id": "67700c0e-9398-4f89-954d-42a434ed2706",
  "model": "exa/search",
  "status": "completed",
  "output": {
    "results": [ { "id": "…", "title": "…", "url": "…", "publishedDate": "…" } ],
    "searchTime": 0.0,
    "resolvedSearchType": "…"
  }
}
For current integration, use outputs[0].data. The current Search and Answer READMEs now include field descriptions and trimmed reference samples; they are not new runs performed for this update, and neither a historical capture nor a saved sample proves continuing availability. 3 4
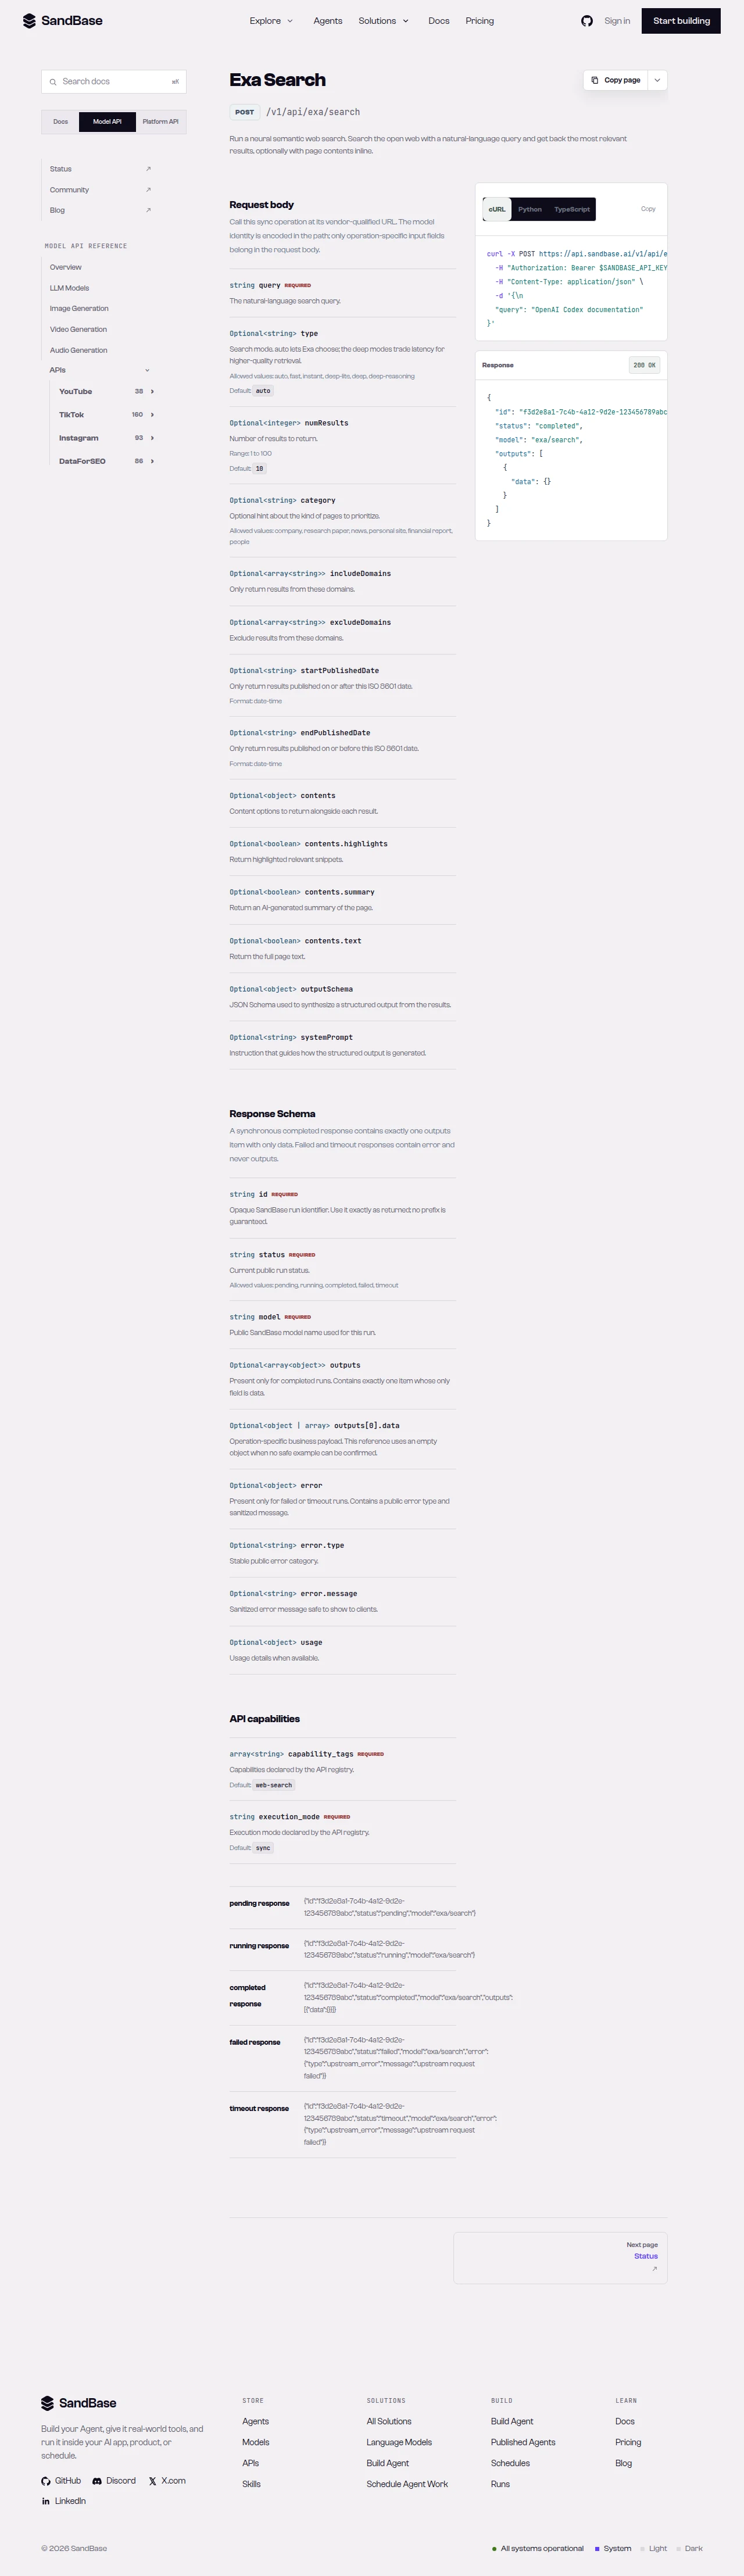 Historical API-reference screenshot retained from the original article. Use the current linked reference for request parameters and response handling.
Search and Answer are independent research components
Search finds pages within the requested domains and can return matching highlights. Answer accepts its own query; its documented inputs do not include a prior Search result list or Search’s domain filter. Do not assume that the same query makes Answer use only the earlier pages. 3 4
An analyst still needs to inspect source URLs, publication dates where available, and whether the cited passages support each claim. Building a source-controlled RAG workflow requires application logic and a separately validated generation step; this guide does not implement that workflow.
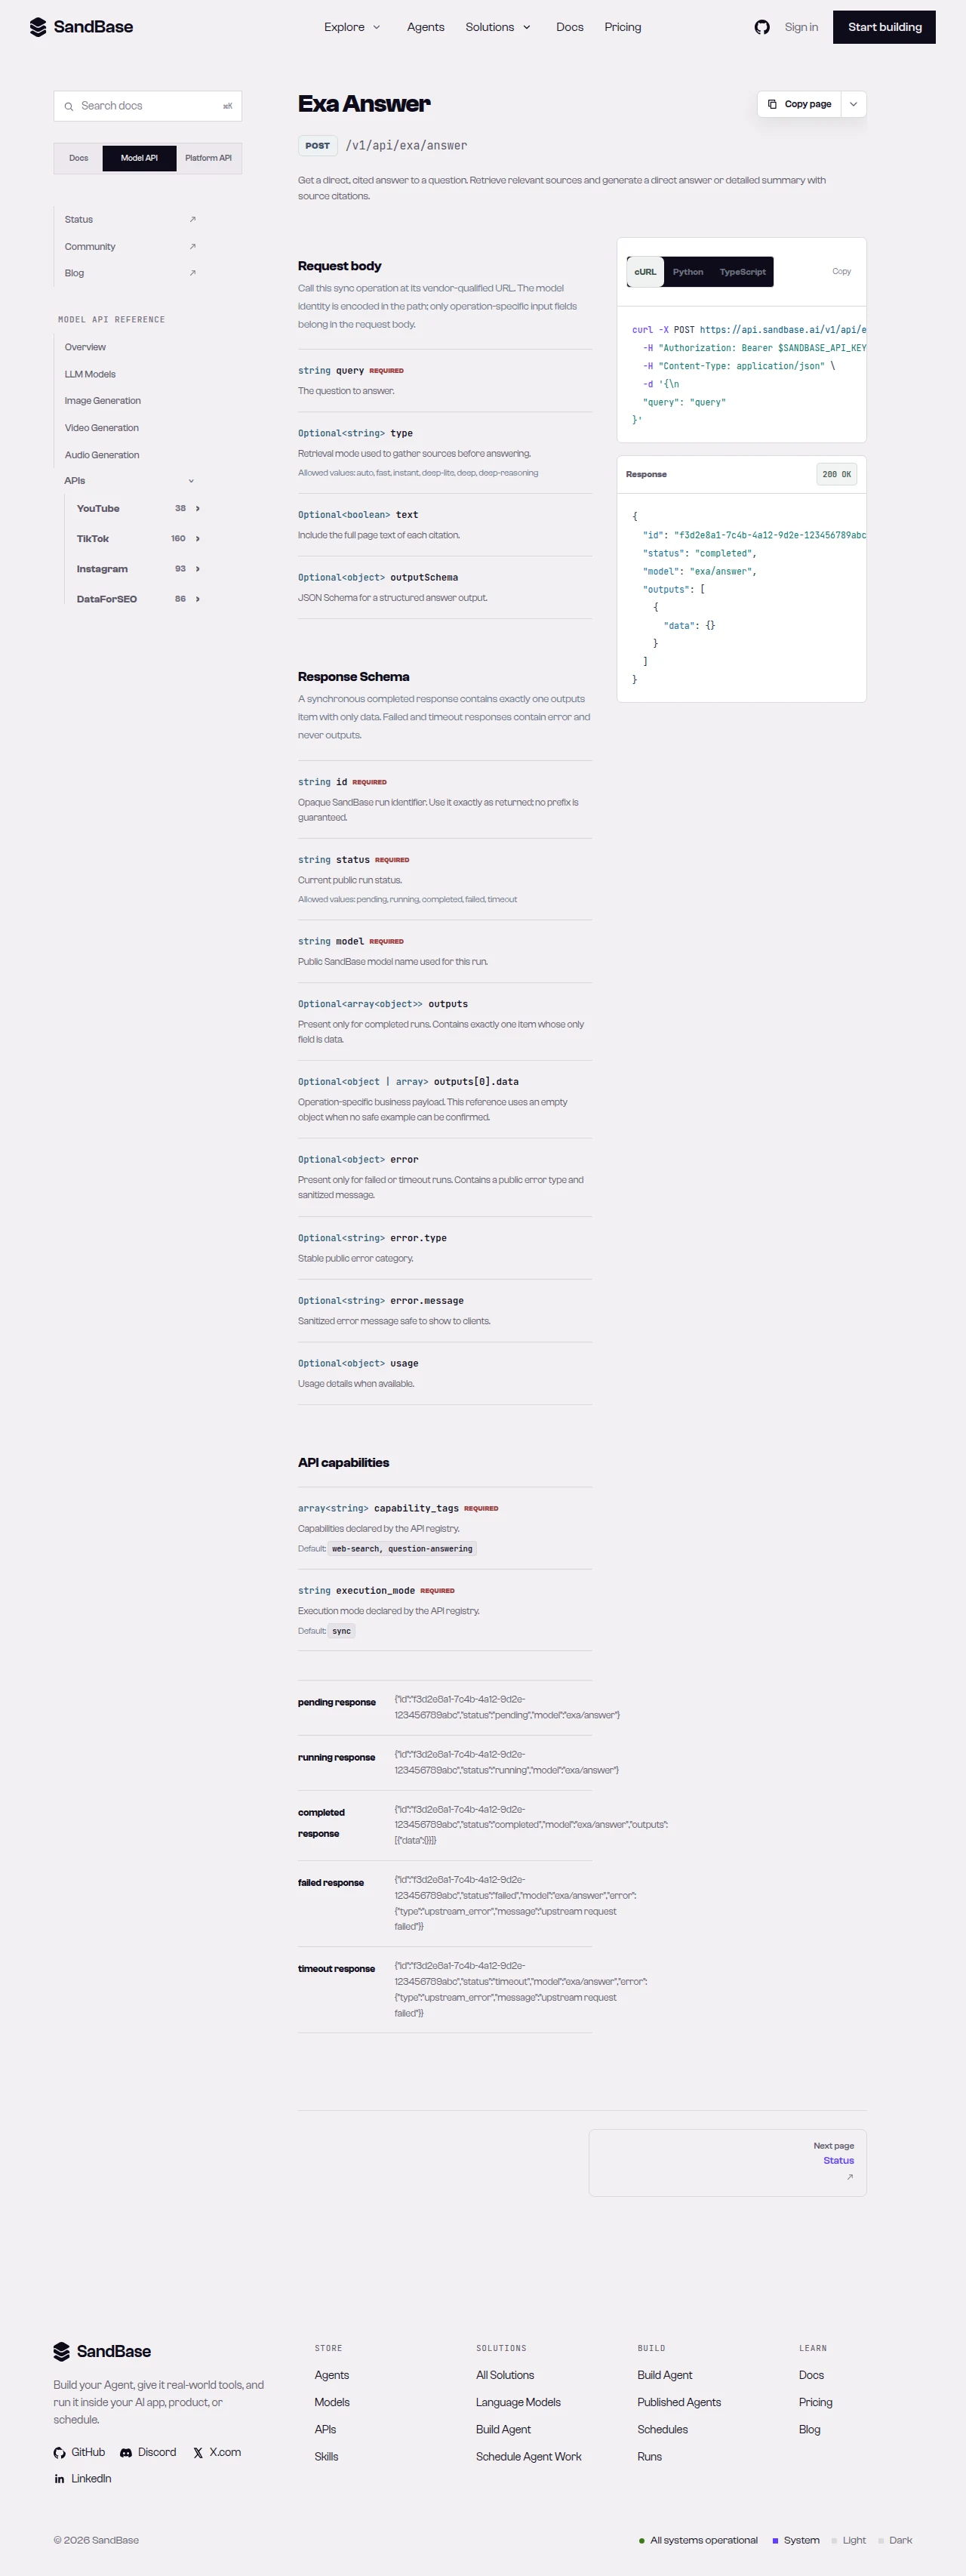 Historical Exa Answer API-reference screenshot retained from the original article, showing the POST route, parameters and response schema; it does not show a new Answer run or a completed chain.
Common use cases
Official-documentation retrieval
Use Search domain filters and highlights to find candidate documentation pages. Review the pages before selecting evidence for your application. 3
A separate cited answer
Use Answer when a query-based answer is useful. Check its citation URLs and the underlying claims; citations alone do not establish correctness. 4
Reading known URLs
The Search README points to Exa Contents for known-URL extraction. That auxiliary capability is not called or chained in this example. 3
Why run this at the API layer
Plain REST keeps authentication and HTTP handling in the application without a separate Exa SDK. For the two calls shown here, wrapper checks can be shared; requests and business-data validation remain endpoint-specific. This is an integration building block, not agent hosting, and it does not establish a reusable contract for every SandBase endpoint. 1 2 3 4
Limitations and boundaries
- Wrapper only: missing, null, incomplete or error responses are rejected. A valid wrapper still requires application-data validation. 3 4
- Documented, not newly tested: the README field tables and trimmed samples are reference material, not a full schema or a live-availability promise. 3 4
- No inherited source filter: Answer does not document Search’s domain/content settings or a custom-results input. 4
- Verify sources: inspect URLs, dates where available and claim support before relying on a result or answer.
FAQ
Do I need a separate Exa key or SDK?
No separate Exa key or SDK is needed for these SandBase routes. Keep SANDBASE_API_KEY in the server environment. 1 2
Where should Python read the result?
The current Search and Answer READMEs specify outputs[0].data. Reject a missing or null payload instead of falling back to top-level output. The September capture above is historical only. 3 4
How do I search official documentation with highlights?
Use a query matching the chosen domain, set includeDomains, and request contents.highlights: true on Search. This guide’s request is documentation-based, not a tested response. 3
Does Answer use my earlier Search results? Do not assume so. Answer has its own query and does not document a custom-results input or Search’s domain filter. A source-controlled RAG pipeline needs separate application logic and validation. 4
Start with a search
Start with the Search request above, validate its documented wrapper, then inspect the returned sources before using them. Keep any Answer request separate. For broader tool selection, see the existing Exa search API comparison. When ready, create a SandBase API key.
Found this useful? Share it