WeChat Search Public Data API | SandBase
Search one page of WeChat article candidates or inspect a known article URL. Python setup, simplified response checks, cursor limits and clear evidence boundaries.
A keyword search and an article lookup answer different questions. Search helps you discover candidate links; an article lookup starts from a complete link you have deliberately selected. Automatically opening the first search result can turn a simple discovery task into a larger reading and analysis workflow before you have checked relevance or the returned data.
This 2026-11-08 repair covers one article-search page through WeChat Search, or one independent article-detail request through WeChat MP. It checks free inspect and public reference material without making a new business call. The original 2026-09-27 UTC search excerpt remains unchanged below. No new article text, pagination or video-search result was retrieved for this revision.
Key takeaway
- Search uses
wechat-search/v2/searchwith keyword, business_type article, raw false and offset zero for the first page.- A known complete article URL uses the separate vendor route
wechat-mp/v2/article-detail, with url and raw false.- Read the documented outputs[0].data. Simplified search has an items array; the article reference has content and url, but its trimmed sample does not show the article body.
- Offset alone repeats the first search page. Continuation needs the returned cursor, but this example does not request another page or open a result automatically.
The retained cover is conceptual artwork. Cards, counts and the search/video pipeline are illustrative, not newly measured results or an executed article-reading workflow. Displayed brands, badges and category labels do not establish verified account identities, endorsement or current capability coverage.
Choose the input you already have
| Your task | Exact endpoint | Example input | Reference shape |
|---|---|---|---|
| Discover article candidates for a keyword | WeChat Search | keyword, business_type article, raw false, offset 0 | items array |
| Inspect a selected article response | WeChat MP article detail | complete url, raw false | content object and url |
These are two vendor namespaces behind the same SandBase authentication. Do not send a keyword to article-detail or a search result ID as its url. Search’s keyword accepts 1–100 characters. Article-detail accepts an mp.weixin.qq.com article link, including a short /s/… path or a long /s?__biz=… form. Preserve the complete query string; truncated README links and ellipses are not usable inputs.
Search defaults business_type to all and raw to true. The new example explicitly chooses article and raw false so its parser matches the simplified reference. A numeric business_type such as 2 in a response does not change the request’s documented string value article. Switching raw back to true is not a harmless formatting change: do not assume the same business parser still applies.
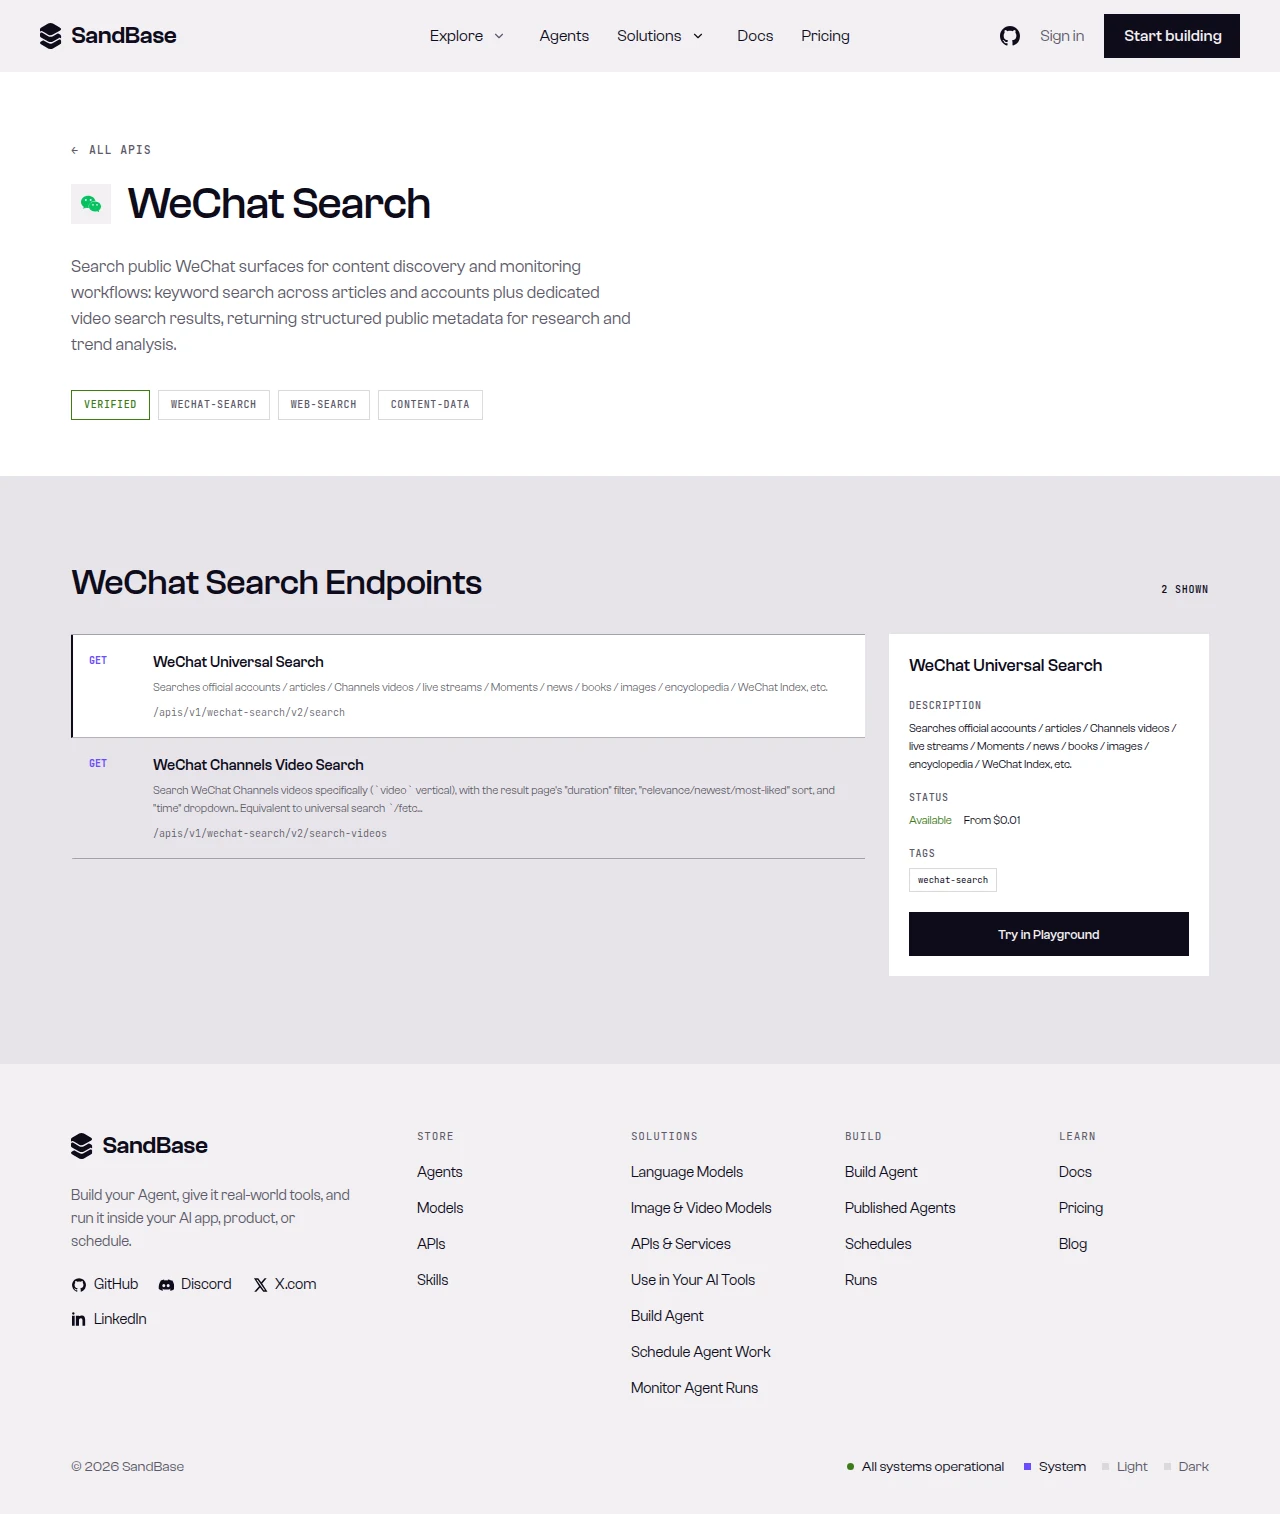 Historical WeChat Search catalog screenshot. Its search/video navigation does not cover the separately selected WeChat MP article endpoint; old counts and catalog GET labels are not a new availability or execution check.
Reuse your setup and stop after one response
Already have a SandBase key? Keep SANDBASE_API_KEY in your runtime or secret manager. A connected agent should reuse that setup and receive one task: article discovery or inspection of a known link. It should not call both silently, download every thumbnail or start a summary chain. The selected reads do not require your WeChat login; that does not provide account authority or access to private chats.
A new project can use SKILL.md, quickstart.md and the human quickstart. For example: “Search once for OpenAI articles, show the returned field names and keep missing values unknown. Do not open the candidate links yet.” Keep the key outside the chat and decide on additional retrieval after inspecting the first result.
Python for either selected first request
Install requests in your Python environment. The helper validates input before network access, sends one request with connect/read timeouts and rejects redirects. Errors omit upstream response bodies and credentials. It does not retry, paginate, fetch media, follow album links or call an LLM.
import os
from urllib.parse import urlsplit
import requests


def first_request(task, value):
    if task not in ("search", "article"):
        raise ValueError("Choose search or article")
    if not isinstance(value, str) or not value.strip():
        raise ValueError("Supply a nonempty keyword or full article URL")
    if task == "search":
        if len(value) > 100:
            raise ValueError("Keyword must contain 1 to 100 characters")
        route = "wechat-search/v2/search"
        params = {"keyword": value, "business_type": "article", "raw": False, "offset": 0}
    else:
        try:
            parts = urlsplit(value)
            valid = (
                len(value) <= 2048 and not any(c.isspace() for c in value)
                and "…" not in value and "..." not in value
                and parts.scheme in ("http", "https")
                and parts.netloc == "mp.weixin.qq.com"
                and not parts.fragment
                and ((parts.path.startswith("/s/") and len(parts.path) > 3)
                     or (parts.path == "/s" and bool(parts.query)))
            )
        except ValueError:
            valid = False
        if not valid:
            raise ValueError("Supply a complete mp.weixin.qq.com article URL")
        route = "wechat-mp/v2/article-detail"
        params = {"url": value, "raw": False}
    key = os.environ.get("SANDBASE_API_KEY", "").strip()
    if not key:
        raise ValueError("Set SANDBASE_API_KEY in the local environment")
    try:
        response = requests.post(
            f"https://api.sandbase.ai/v1/api/{route}",
            headers={"Authorization": f"Bearer {key}", "Content-Type": "application/json"},
            json=params, timeout=(10, 90), allow_redirects=False,
        )
        if not 200 <= response.status_code < 300:
            raise RuntimeError(f"HTTP {response.status_code}; request stopped")
        body = response.json()
    except ValueError:
        raise RuntimeError("Response was not valid JSON") from None
    except requests.RequestException:
        raise RuntimeError("Network request failed or timed out") from None
    if not isinstance(body, dict) or body.get("status") != "completed":
        raise RuntimeError("SandBase request did not complete")
    outputs = body.get("outputs")
    if not isinstance(outputs, list) or not outputs or not isinstance(outputs[0], dict):
        raise RuntimeError("Missing documented output")
    payload = outputs[0].get("data")
    if not isinstance(payload, dict):
        raise RuntimeError("Missing business object")
    if task == "search":
        items = payload.get("items")
        if not isinstance(items, list) or any(not isinstance(item, dict) for item in items):
            raise RuntimeError("Missing simplified article items array")
    else:
        if not isinstance(payload.get("content"), dict):
            raise RuntimeError("Missing reference content object")
        if not isinstance(payload.get("url"), str) or not payload["url"]:
            raise RuntimeError("Missing reference article URL")
    # A valid content object does not prove the full article body is present.
    return payload


if __name__ == "__main__":
    result = first_request("search", "OpenAI")
    print("Business fields:", sorted(result))
For an independent article inspection, replace the final assignment with result = first_request("article", "https://mp.weixin.qq.com/s/TSNQKkRpN1qbKsT7BvzqIw") and keep the print statement. That is the schema’s example URL, not a link executed for this repair. Do not append it after search unless you deliberately choose two requests. The local URL guard rejects incomplete or visibly truncated input; it does not prove that an article is available.
The parser accepts an empty items array, but not a missing array or non-object members. Article mode requires a content object and a returned URL string. Those are reference-shape checks, not proof that the article text is present. It returns the original payload without replacing absent title, body, account or statistics fields with invented values. Neither selected reference justifies borrowing a status_code-zero convention from a different platform.
What the original search record can prove
The original prose attributed its 2026-09-27 UTC capture to b4252b59-a208-404e-a2f8-2e6a9e2e9d37, while the JSON itself carries 677def62-bd58-48fb-bb31-ec694c49f80f. Both identifiers are preserved. That mismatch is an unresolved attribution issue in the historical record, not evidence of two confirmed runs or a reason to invent a replacement ID.
{
  "id": "677def62-bd58-48fb-bb31-ec694c49f80f",
  "status": "completed",
  "model": "wechat-search/v2/search",
  "outputs": [
    {
      "data": {
        "keyword": "人工智能",
        "offset": 18,
        "continue_flag": 1,
        "no_more": null,
        "categories": [],
        "results": {}
      }
    }
  ]
}
The old excerpt has empty categories and results. It must not become the parser for today’s explicitly selected article/raw-false task. The current public reference uses items, and categories can be null. A missing or null categories field does not mean there are no article candidates when items is present.
The full saved search example is dated 2026-10-07T17:37:38.159Z and uses a university-admissions keyword, not the OpenAI keyword in the short README example. The saved input explicitly includes business_type article, raw false, offset 0, sort default and publish_time all. Its response supports the simplified items shape. Keep those sources separate; this repair did not run either query and does not present their counts as a new comparison.
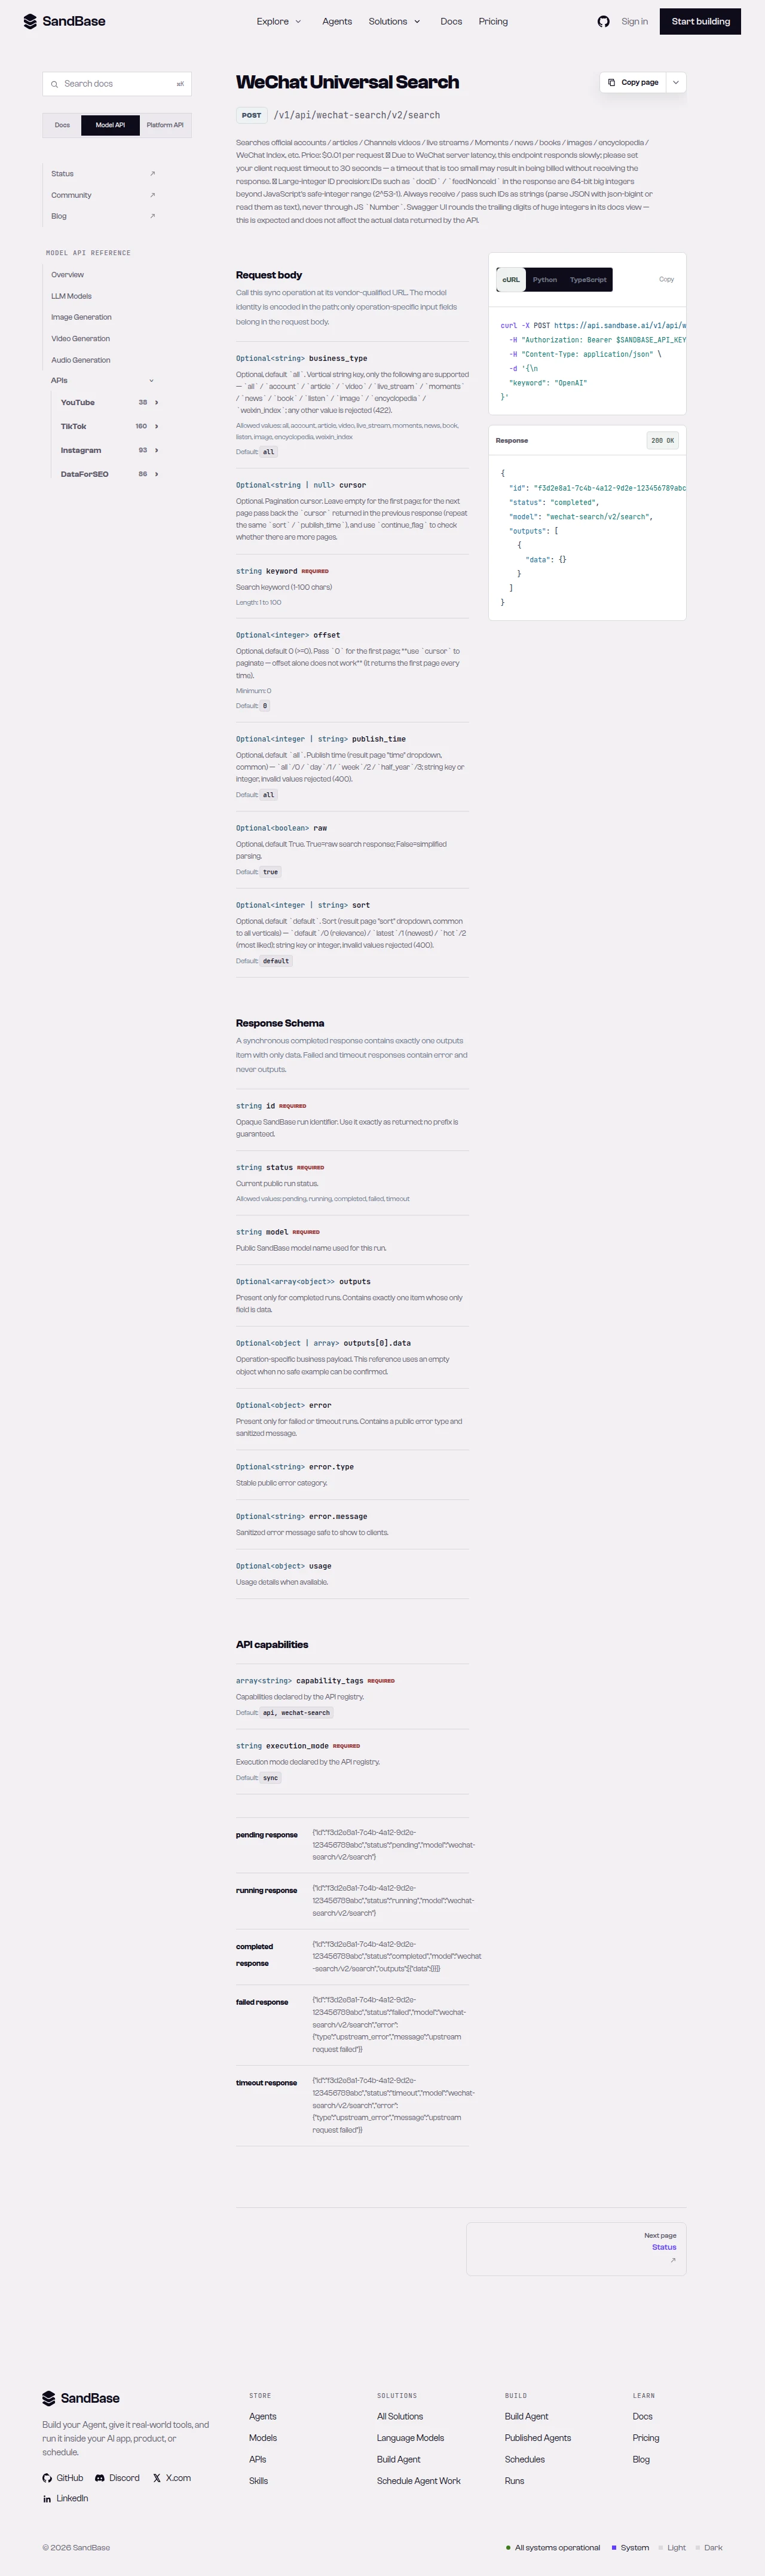 Historical WeChat Search parameter and envelope reference. The current example explicitly selects the article vertical and simplified output; the old empty business example does not establish that missing items is a valid result.
Read candidate fields without promoting snippets to facts
The public search reference shows items with title, desc, doc_url, source, timestamps and docID. Titles and snippets can contain <em class="highlight"> markup around search matches. Preserve or handle that markup deliberately; it is not plain text ready for unexamined HTML insertion. A snippet is not the full article, and its claims are not verified merely because they appeared in a search response.
A source title is the displayed account name, not proof of account identity or authority. The source’s dateTime can be relative text, while timestamp/date are separate numeric fields in the reference. Keep their provenance and capture time instead of turning “51 minutes ago” from a saved example into a fresh publication timestamp. Document IDs should remain the strings returned; they are not article URL substitutes.
Count and total describe values reported by the search, not proof of exhaustive coverage. The README trims arrays to one item while retaining page-level counts, so that displayed array length cannot be used to reconstruct a full page. The example preserves optional values and makes no ranking, market-share or “all articles” claim. Debug fields are not required for the reader’s task and are not copied into new examples or public logs.
Article-detail evidence stops before verified body text
The article-detail public model has no full saved example. Its short README shows a url, bizUin and a content object containing metadata and configuration fields, but no visible article body or title in the trimmed JSON. The response-field table describes possible title, author and HTML locations; that documentation is different from observing those fields in the available sample.
Consequently, this helper checks the content object without claiming it has read a full article. A structurally valid object may still lack the text needed for indexing or summarization. A downstream task must inspect the actual returned fields and explicitly handle missing body content. It must not feed an empty string to a model and call the resulting answer an article summary.
The reference also describes album navigation and says read/like statistics are separate from this endpoint. This repair neither follows previous/next article links nor requests statistics. Returned HTML and media URLs are data, not permission to execute markup, download assets or republish content. The complete chosen URL remains the input; a search result should be reviewed before a separate article request.
Cursor pagination is not offset arithmetic
The current search contract says to leave cursor empty for the first page. For continuation, return the previous response’s cursor while keeping the keyword and filters consistent; sort and publish_time must be repeated. Continue_flag indicates whether further pages are reported. Offset alone does not paginate and returns the first page again.
The new example sends offset 0 and omits cursor. It does not increment offset, reuse the README’s truncated cursor, or automatically continue while a flag is set. Continuation was not tested in this revision. A successful first page does not prove deduplication, complete coverage or stable ordering across repeated searches, and an empty historical category array does not resolve those questions.
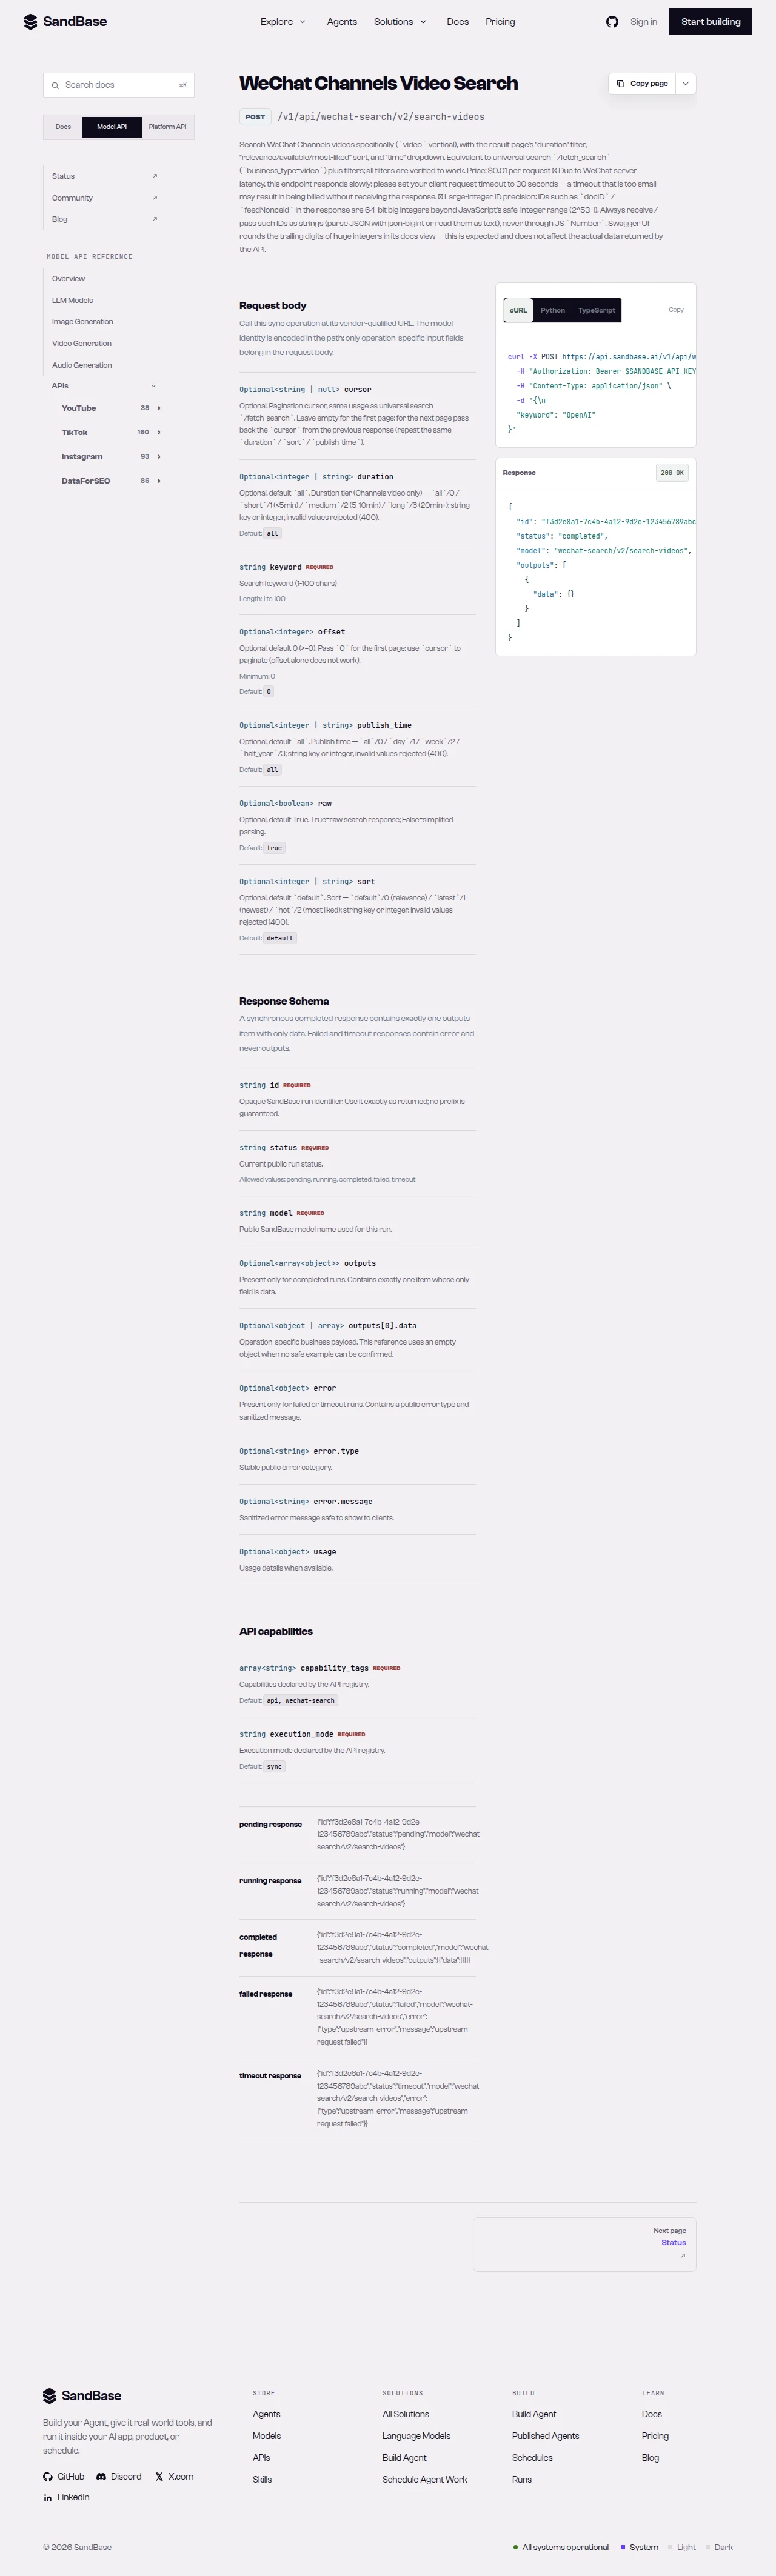 Historical video-search parameter reference, not an endpoint-list screenshot. Video search remains outside this article-focused repair; its parameters and paging behavior were not revalidated here.
Price and the next decision
Free inspect on 2026-11-08 lists both selected endpoints at $0.01, eligible for the organization’s 100 daily calls shared across eligible APIs, resetting at 00:00 UTC. Eligibility does not reveal remaining allowance, balance or actual charges. No business request was made, and free successful execution is not promised.
One selected request lists at $0.01; independently choosing search and article inspection lists at $0.02 before quota effects. Opening every candidate, paging, retries, statistics and model analysis would add work. This first-request helper stops so the next question and its budget can be chosen explicitly.
Historical code and wider navigation
The original Python is preserved verbatim with hashes in the historical archive. Its categories-based example and earlier generalized search/video workflow are historical, not instructions for the selected simplified article response. The canonical page and original evidence remain intact rather than creating a second near-duplicate tutorial.
Use the WeChat Search catalog for a separately defined discovery task. A broader comparison of public-data workflows is available in the Telegram API hub, but shared authentication does not mean those APIs share inputs or business fields. SandBase supplies the access layer; it does not own WeChat or grant account-authorized operations.
FAQ
Can I use offset to get the next page? No. The current contract says offset alone repeats the first page. This example reads only the initial page; a later task must use an actual returned cursor and consistent filters.
Does raw false guarantee a complete article? No. It selects simplified output. The available article reference shows a content object but not visible full text, and this repair did not execute a new article request.
Can search and article detail be one automatic chain? They can be separate decisions in a larger application, but this example does not select a first result or open it. Inspect relevance, complete URL and returned fields before expanding the task.
Is WeChat login required? The selected public reads use a SandBase key. Private chats, member actions and account-authorized data are outside this workflow.
Found this useful? Share it