Lemon8 内容发现 API 教程 | SandBase
搭一套 Lemon8 内容发现工作流:搜关键词、打开帖子、给作者建档——一个 SandBase 密钥,无需 Lemon8 登录、无需 SDK。
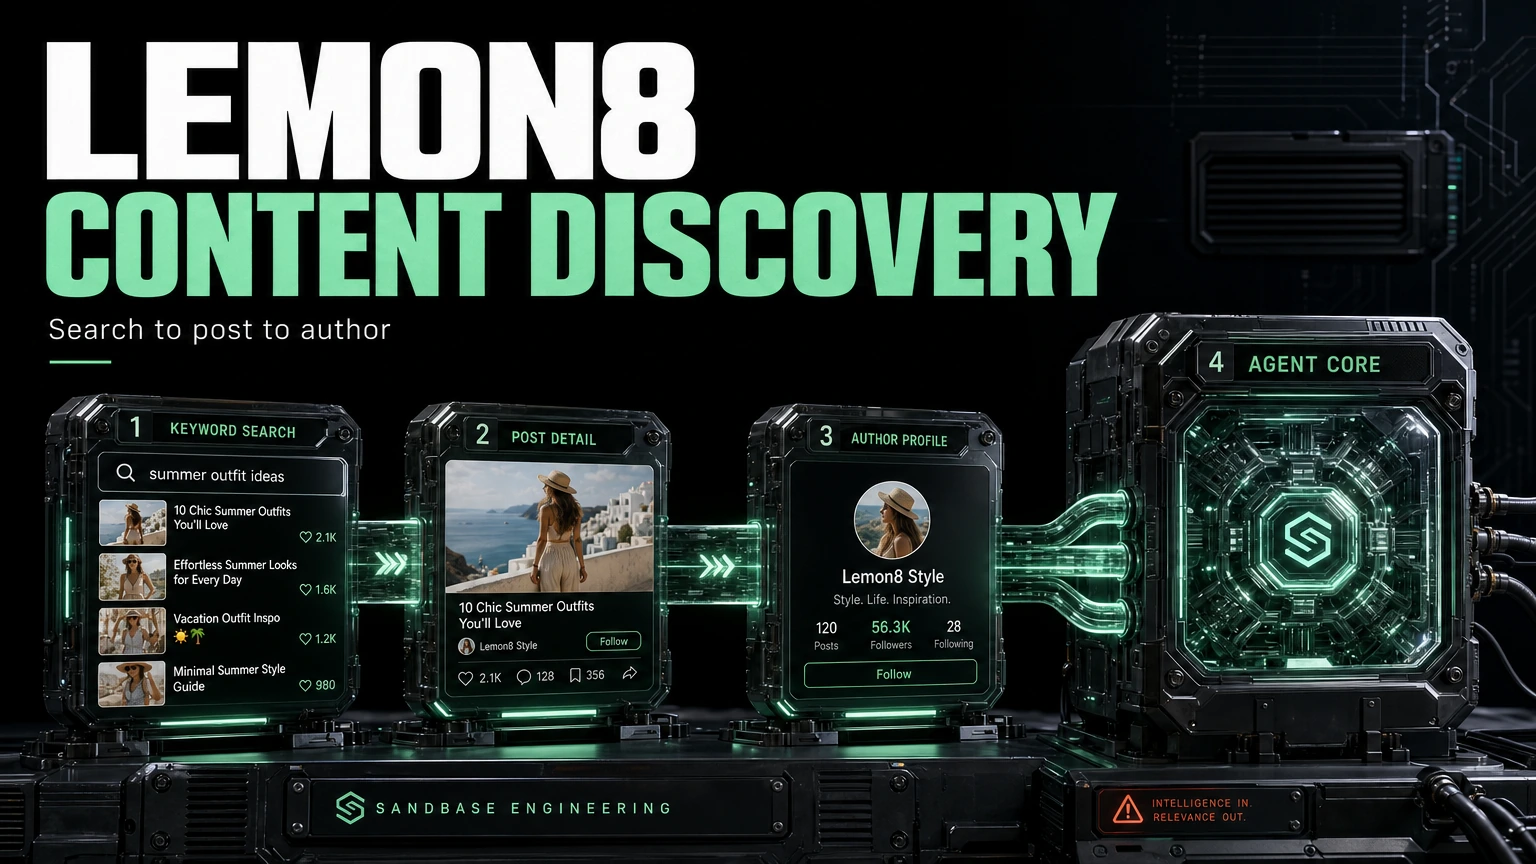
如果你在 Lemon8——字节跳动的美妆、美食和生活方式 App——上做消费趋势研究,你多半想要一个可复用的循环:围绕某个主题找到帖子、打开重要的那些、并搞清楚背后是谁。本教程用三个 SandBase 端点把这个循环串起来,让 Agent 能端到端跑完。它建立在 Lemon8 公开数据 API 汇总页之上;建议先读那篇了解全局。
这里的一切都是公开、只读数据。不需要登录 Lemon8、不需要 SDK——但仍需要一个 SandBase API 密钥来鉴权。端点 API 参考是参数和响应信封的权威来源;下面的载荷字段名来自我实际跑的调用(测试于 2026-09-27,UTC),仅作为一次观测到的结构展示——请以真实响应为准核对,因为负载会随时间变化。
先说结论
- 三个端点构成一个发现循环:
search→post-detail→user-profile。- 每次调用都是
POST /v1/api/lemon8/<path>,只传该端点的参数,一个SANDBASE_API_KEY。- 以自然标识链式串联:搜索浮现出
item_id和author_id;把它们喂给后两个调用。- 只按
status分支判断一次,并在三步中复用同一段读 JSON 的辅助函数。
工作流一览
- 用
lemon8/app/search搜关键词拿到匹配帖子。 - 用从搜索里取到的
item_id调用lemon8/app/post-detail打开一条帖子。 - 用帖子上携带的
author_id调用lemon8/app/user-profile给作者建档。
每个端点返回相同信封——一个 id、一个 status、model,以及在 completed 运行上一个 outputs 数组、其唯一元素在 data 下承载数据。failed 或 timeout 的运行带 error 而无 outputs。把 status 检查写一次、处处复用。
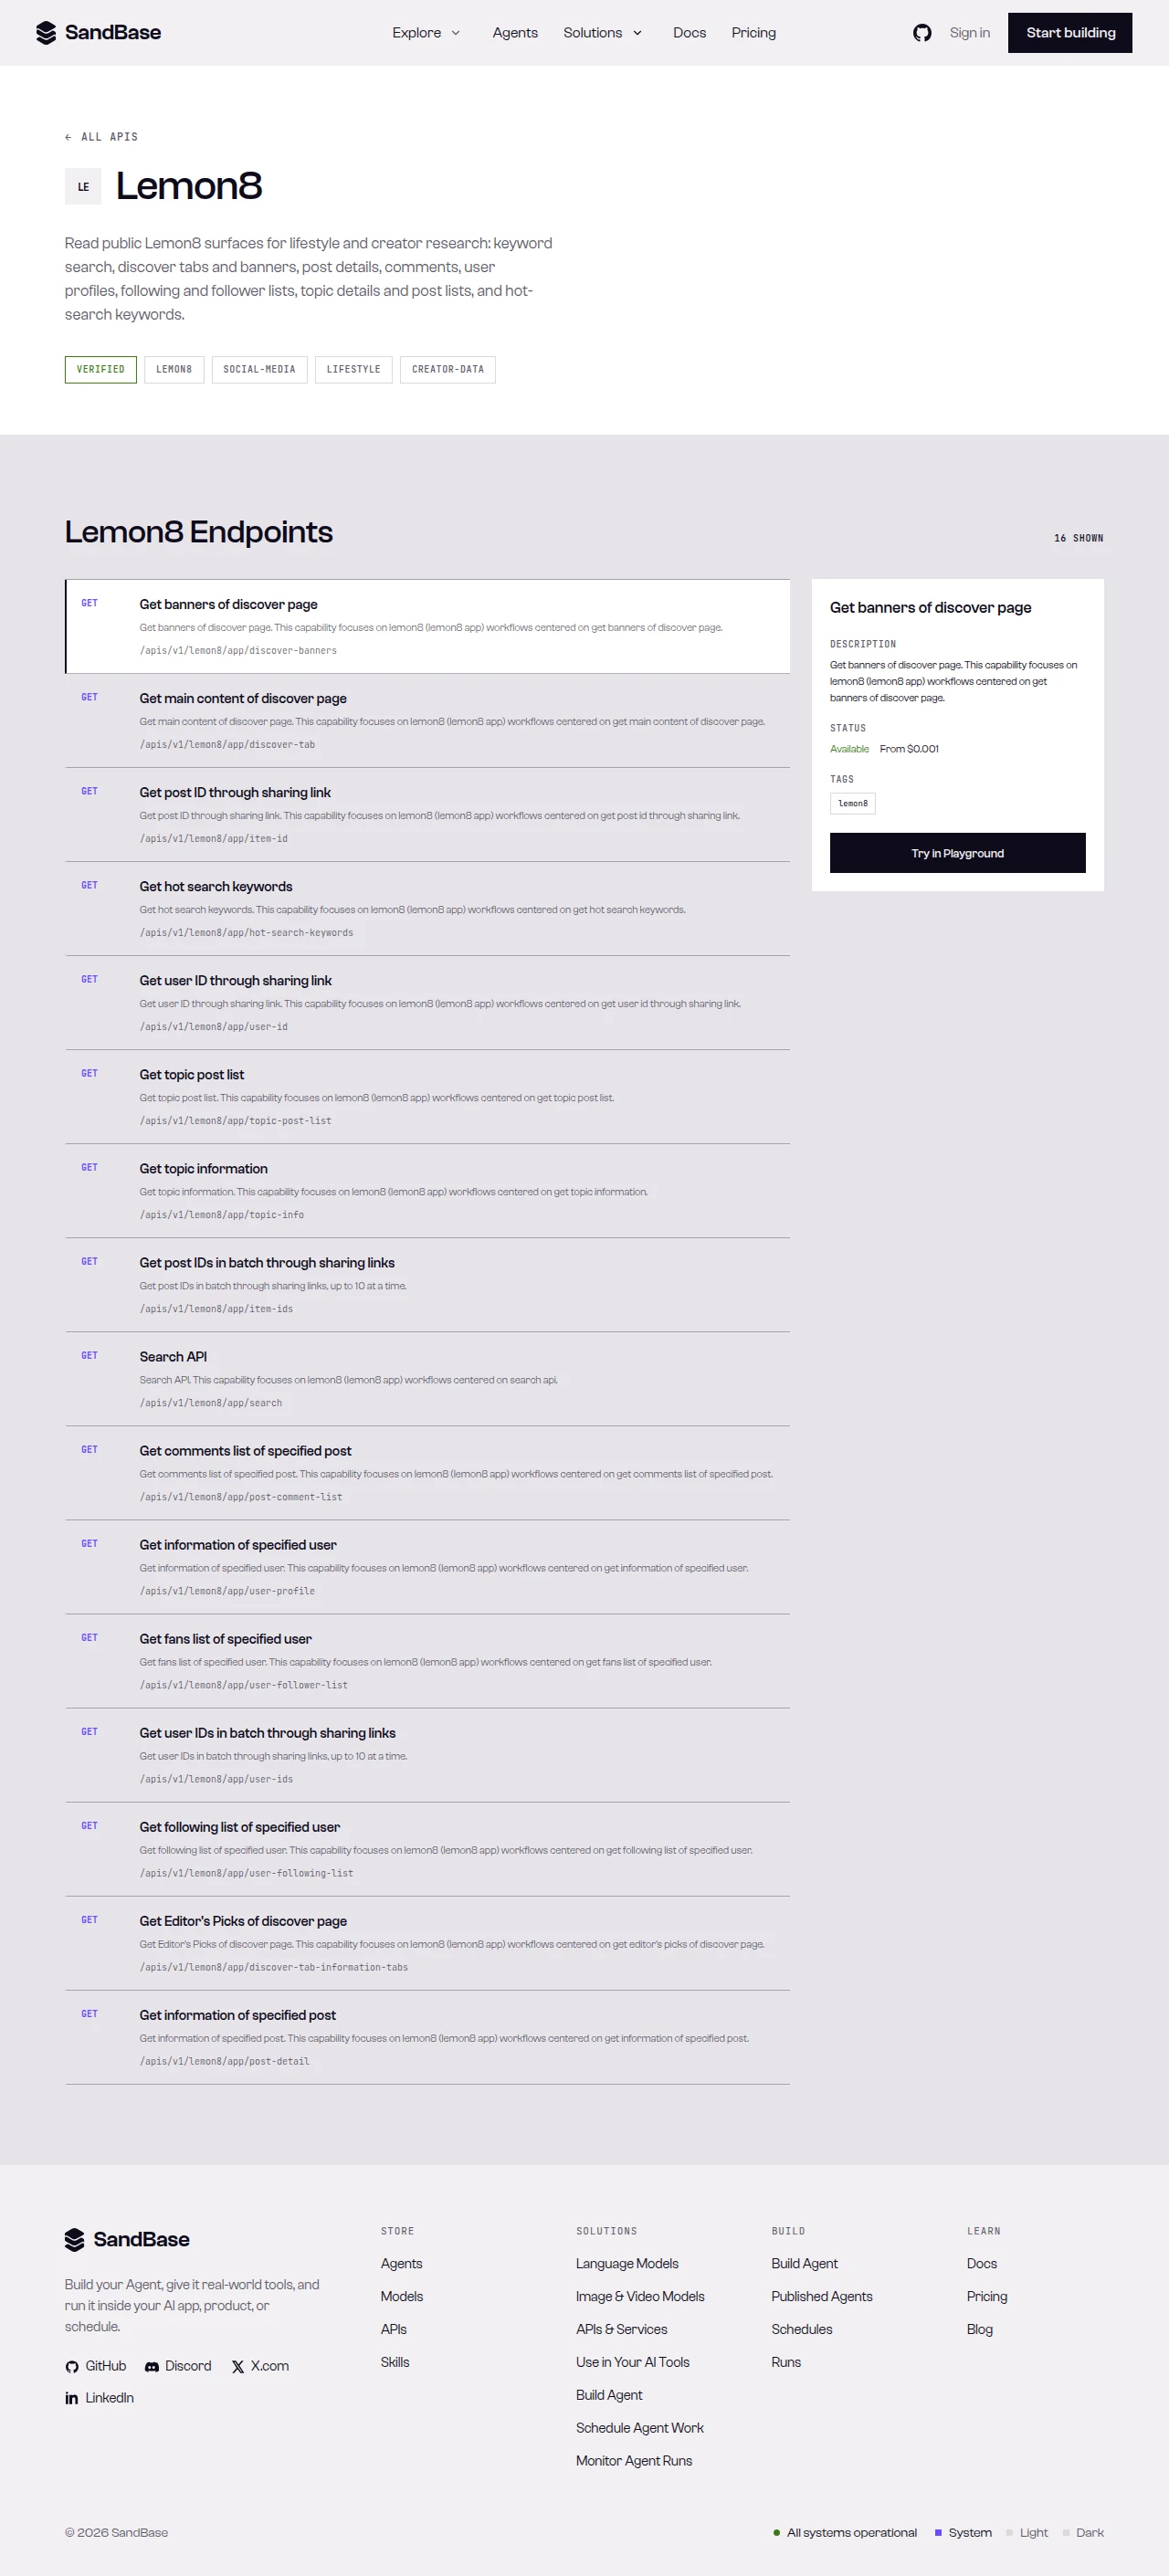 SandBase 上的 Lemon8 端点——search、post-detail 和 user-profile 驱动这个循环。
第 0 步:一个辅助函数管所有调用
import os
import requests

API = "https://api.sandbase.ai/v1/api"
HEADERS = {
    "Authorization": f"Bearer {os.environ['SANDBASE_API_KEY']}",
    "Content-Type": "application/json",
}

def call(path: str, payload: dict) -> dict:
    resp = requests.post(f"{API}/{path}", headers=HEADERS, json=payload, timeout=60)
    resp.raise_for_status()
    body = resp.json()
    if body.get("status") != "completed":
        error = body.get("error", {})
        raise RuntimeError(error.get("message", f"{path} 未完成"))
    return body["outputs"][0]["data"]
下面每一步都调用 call(...),并用 .get() 防御式读取有名字的字段。
第 1 步:搜关键词
blocks = call("lemon8/app/search", {"query": "coffee"})

# 搜索返回一个块列表;code == 0 的块承载 items。
items = []
for block in blocks if isinstance(blocks, list) else []:
    data = block.get("data", {})
    if block.get("code") == 0 and isinstance(data.get("items"), list):
        items = data["items"]
        break

print(len(items), "条帖子")
在我抓到的响应里(搜索 run id 4bac9e8a-eeec-49ec-ba84-49feff8e1928,测试于 2026-09-27,UTC),每条帖子带一个 item_id 和一个含 author_id 的 author 对象。该块还暴露了 has_more 加 max_cursor/min_cursor 用于翻页。字段名会随时间变化——把它们当作观测到的,并对照真实响应核对。
first = next((it for it in items if isinstance(it, dict) and it.get("item_id")), None)
item_id = first.get("item_id") if first else None
author_id = first.get("author", {}).get("author_id") if first else None
第 2 步:打开帖子
detail = call("lemon8/app/post-detail", {"item_id": str(item_id)})
post = detail.get("data", {})  # 以真实响应核对确切路径
在我这次运行里(post-detail run id 814a5872-8dae-4fb9-b7be-c3990afd8da6),负载是一个含 data、message、server_time 的对象,帖子主体在 data 下。防御式读取——它的结构和搜索不同,所以先对照一次真实响应确定路径。
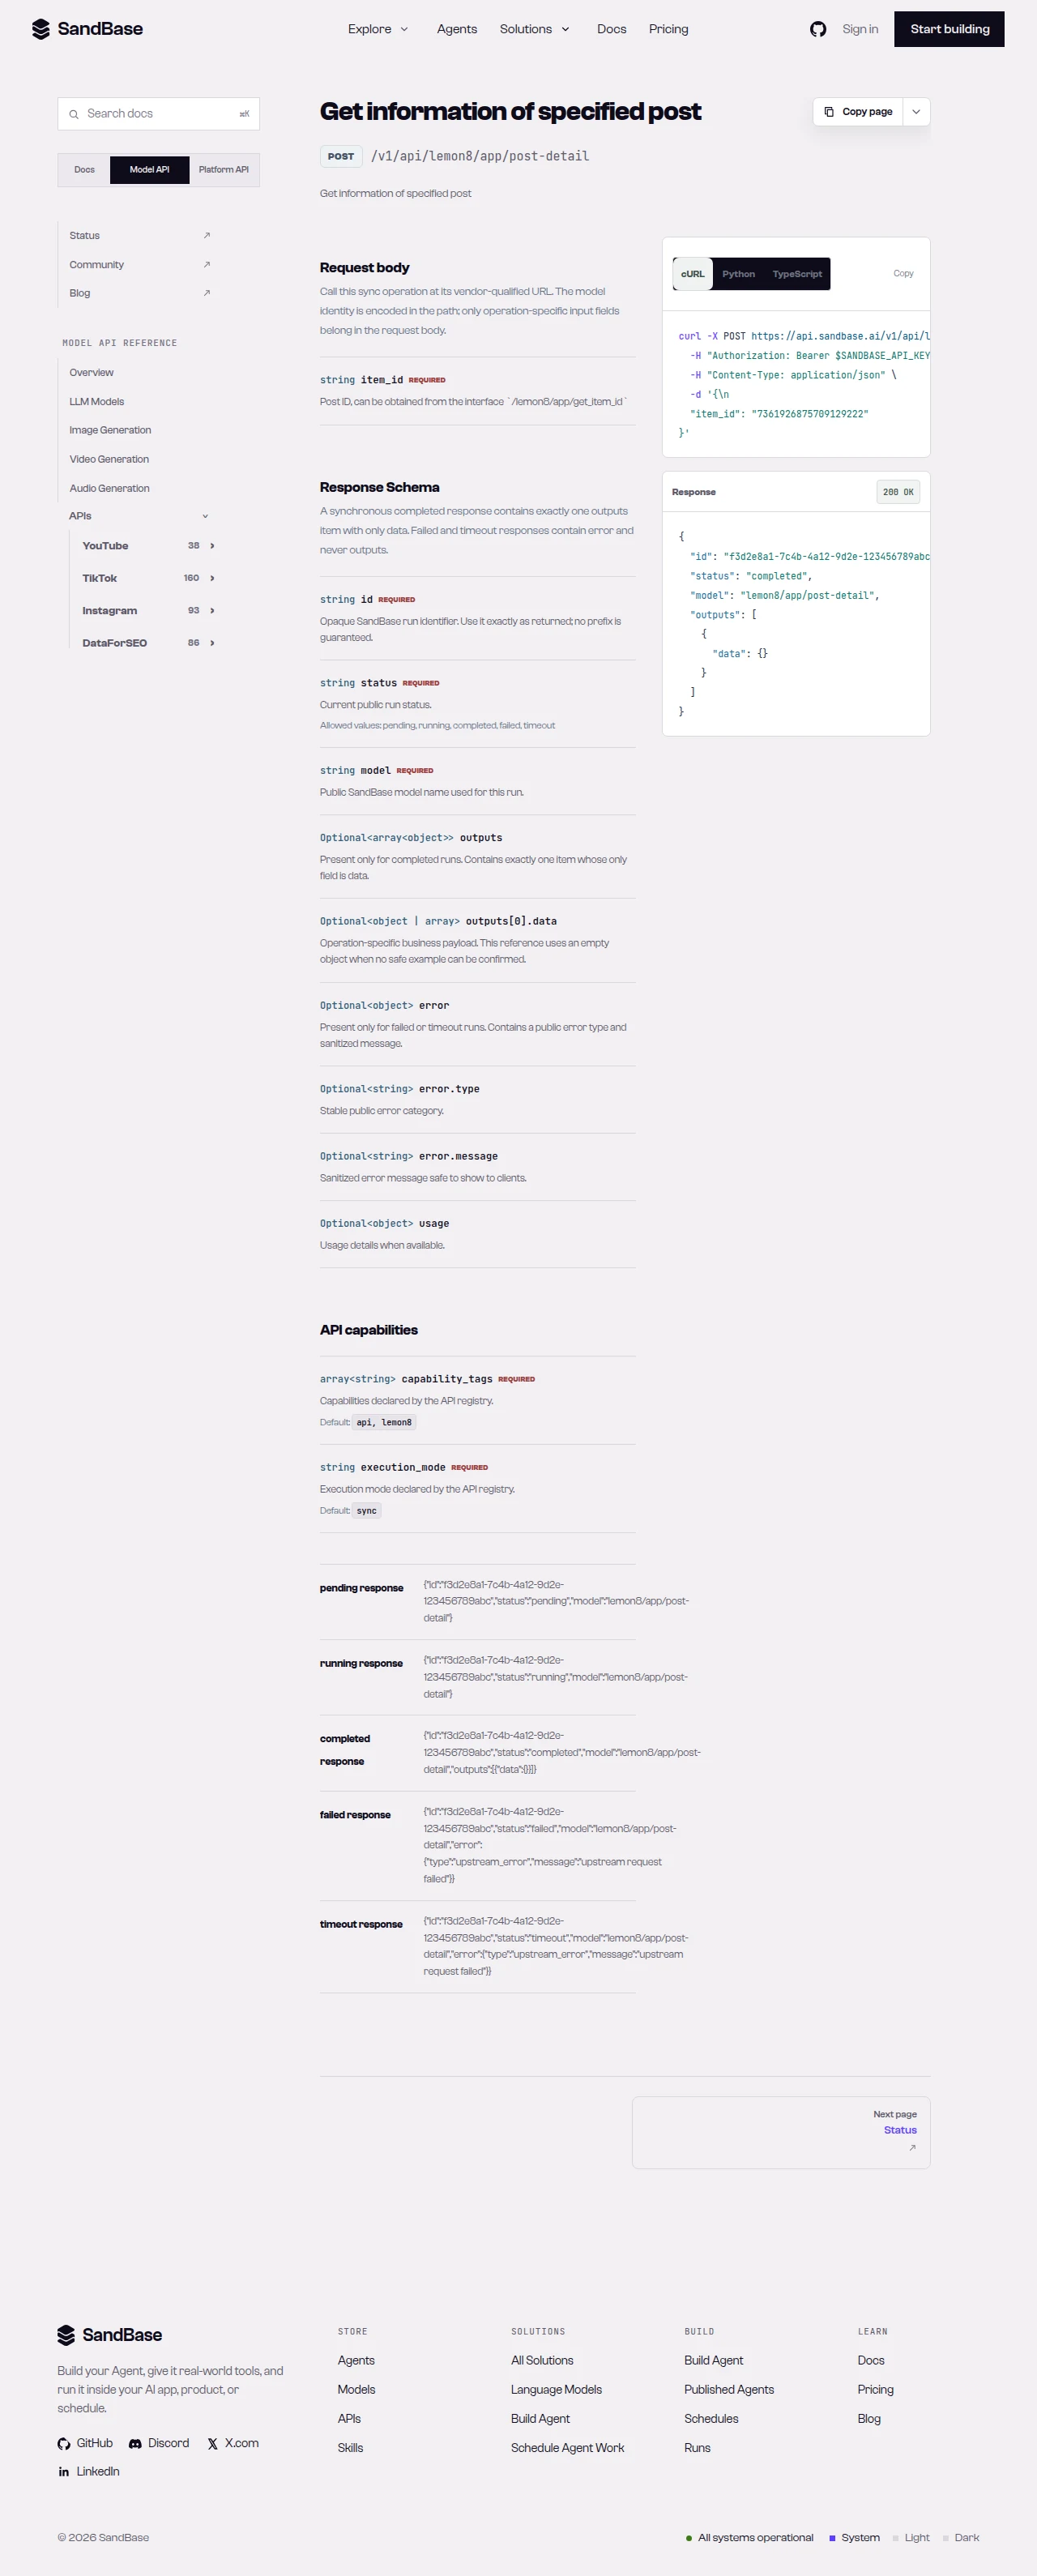 post-detail 参考——
item_id 参数和响应路径的事实来源。
第 3 步:给作者建档
profile = call("lemon8/app/user-profile", {"user_id": str(author_id)})
data = profile.get("data", {})  # 以真实响应核对路径

signals = {
    "followers": data.get("followers_count"),
    "following": data.get("following_count"),
    "likes": data.get("digg_count"),
    "comments": data.get("comment_count"),
    "bio": data.get("description"),
}
print(signals)
user-profile 端点接受一个 user_id;搜索结果里的 author_id 可作为该标识。在我这次运行里(user-profile run id a3cf09c5-c08c-4ef7-a898-6a22eeb722ef),负载带 data(含 followers_count、following_count、digg_count、comment_count、description 等),外加 error_code 和 message。用 .get() 读每个字段——可用性各异,请对照真实响应核对。
串起来
def discover(query: str):
    blocks = call("lemon8/app/search", {"query": query})
    items = []
    for block in blocks if isinstance(blocks, list) else []:
        d = block.get("data", {})
        if block.get("code") == 0 and isinstance(d.get("items"), list):
            items = d["items"]
            break

    results = []
    for it in items:
        if not isinstance(it, dict) or not it.get("item_id"):
            continue
        item_id = it["item_id"]
        author_id = it.get("author", {}).get("author_id")
        detail = call("lemon8/app/post-detail", {"item_id": str(item_id)})
        profile = (
            call("lemon8/app/user-profile", {"user_id": str(author_id)})
            if author_id else {}
        )
        results.append({
            "item_id": item_id,
            "post": detail.get("data", {}),
            "author": profile.get("data", {}),
        })
return results因为三个端点共享同一个信封,循环保持扁平:call(...) 里一次 status 检查、处处同一套 .get() 模式,标识从一步流向下一步。翻页时,在 has_more 为真期间用块里的游标重发 search。
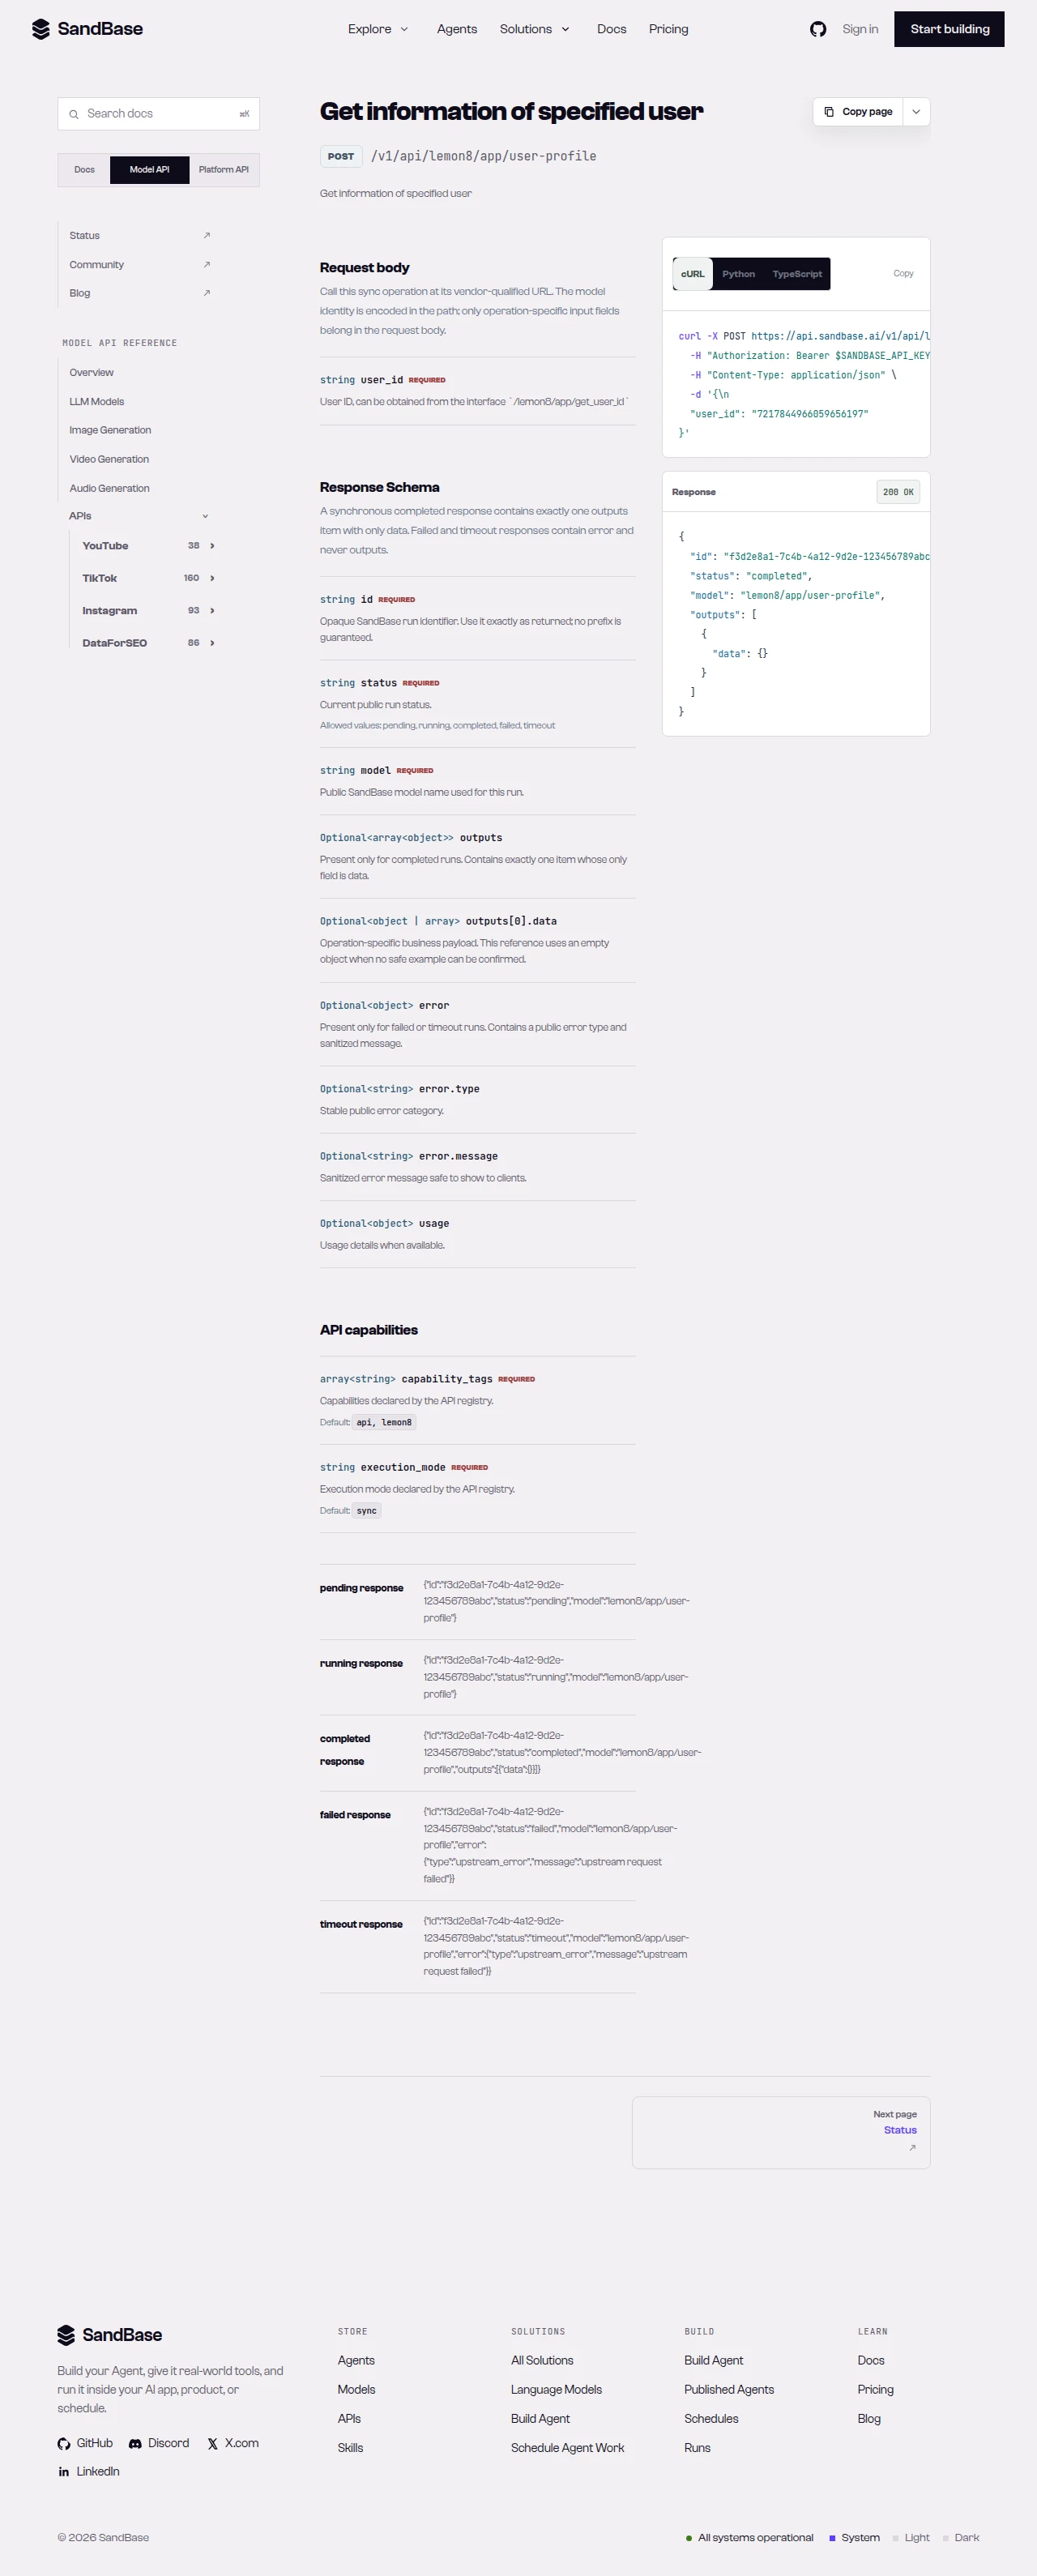 user-profile 参考——传一个
user_id;搜索结果的 author_id 可作为该标识。
实操要点
- 搜索返回的是块、不是扁平列表。 找到
code == 0的块、读它的items。每个元素都用isinstance(..., dict)兜底。 - 标识是字符串。 稳妥起见把
item_id和user_id当字符串传。 - 结构因端点而异。 search、post-detail 和 user-profile 各自以不同方式嵌套负载——每条路径先对照一次真实响应确定。
- 仅公开、只读数据。 不发帖、不涉及私有或仅账号可见数据。用 SandBase API 密钥鉴权。
- 做个好客户端。 遇到 HTTP 429 等瞬时错误按退避重试;用游标翻页而不是猛打。
常见问题
我需要 Lemon8 登录或 SDK 吗?
不需要。你用自己的 SANDBASE_API_KEY 向 SandBase 鉴权。这些读取端点不需要你这边有 Lemon8 账号或 OAuth。
我怎么拿到 item_id 和作者 id?
从 search。每条帖子带一个 item_id,它的 author 对象带一个 author_id,后者可作为 user-profile 的 user_id。
为什么搜索返回一个块列表?
Lemon8 的搜索把结果分组成块,每块带一个上游 code;code == 0 的块承载 items。防御式读取,并以真实响应核对路径。
怎么翻更多结果?
块里暴露了 has_more 加游标字段(max_cursor/min_cursor)。在 has_more 为真期间用游标重发 search。确切参数名请对照参考核对。
小结
三个端点、一个信封、标识在步骤间流动——这就是整个发现循环。完整端点目录和响应细节见 Lemon8 公开数据 API 汇总页。准备好后: