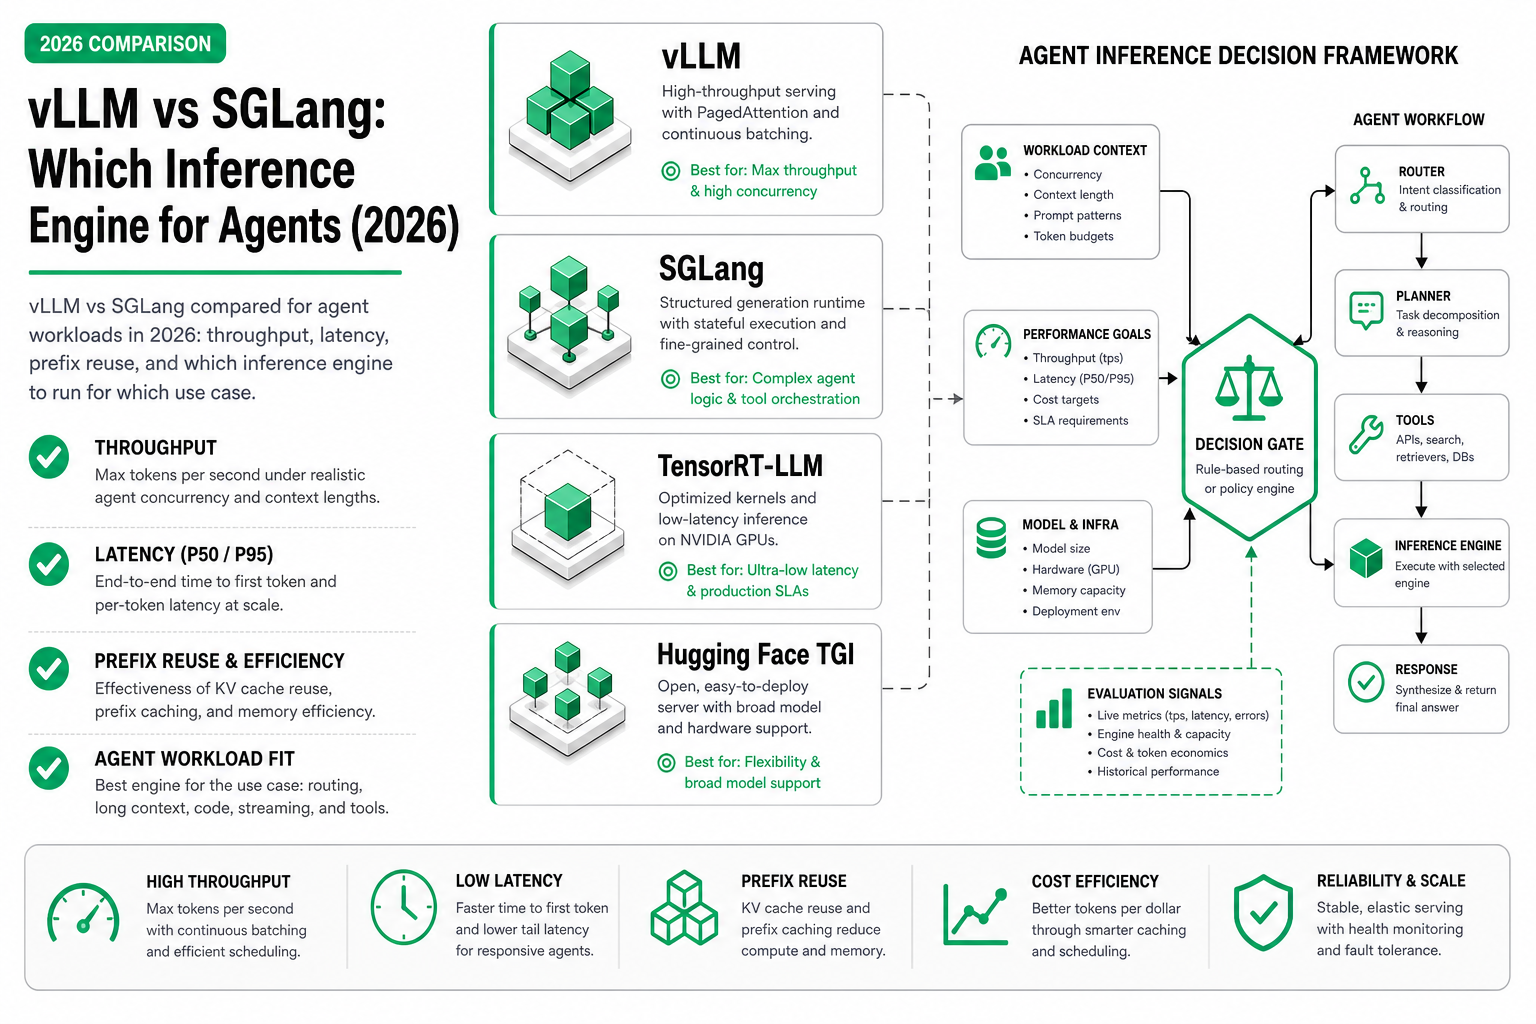
vLLM vs SGLang (2026): Which Inference Engine Is Better?
vLLM vs SGLang (2026) comparison for LLM serving and AI agents: which is better for throughput, latency, prefix caching, OpenAI API compatibility, and deployment fit?
vLLM vs SGLang (2026) comparison for LLM serving and AI agents: which is better for throughput, latency, prefix caching, OpenAI API compatibility, and deployment fit?
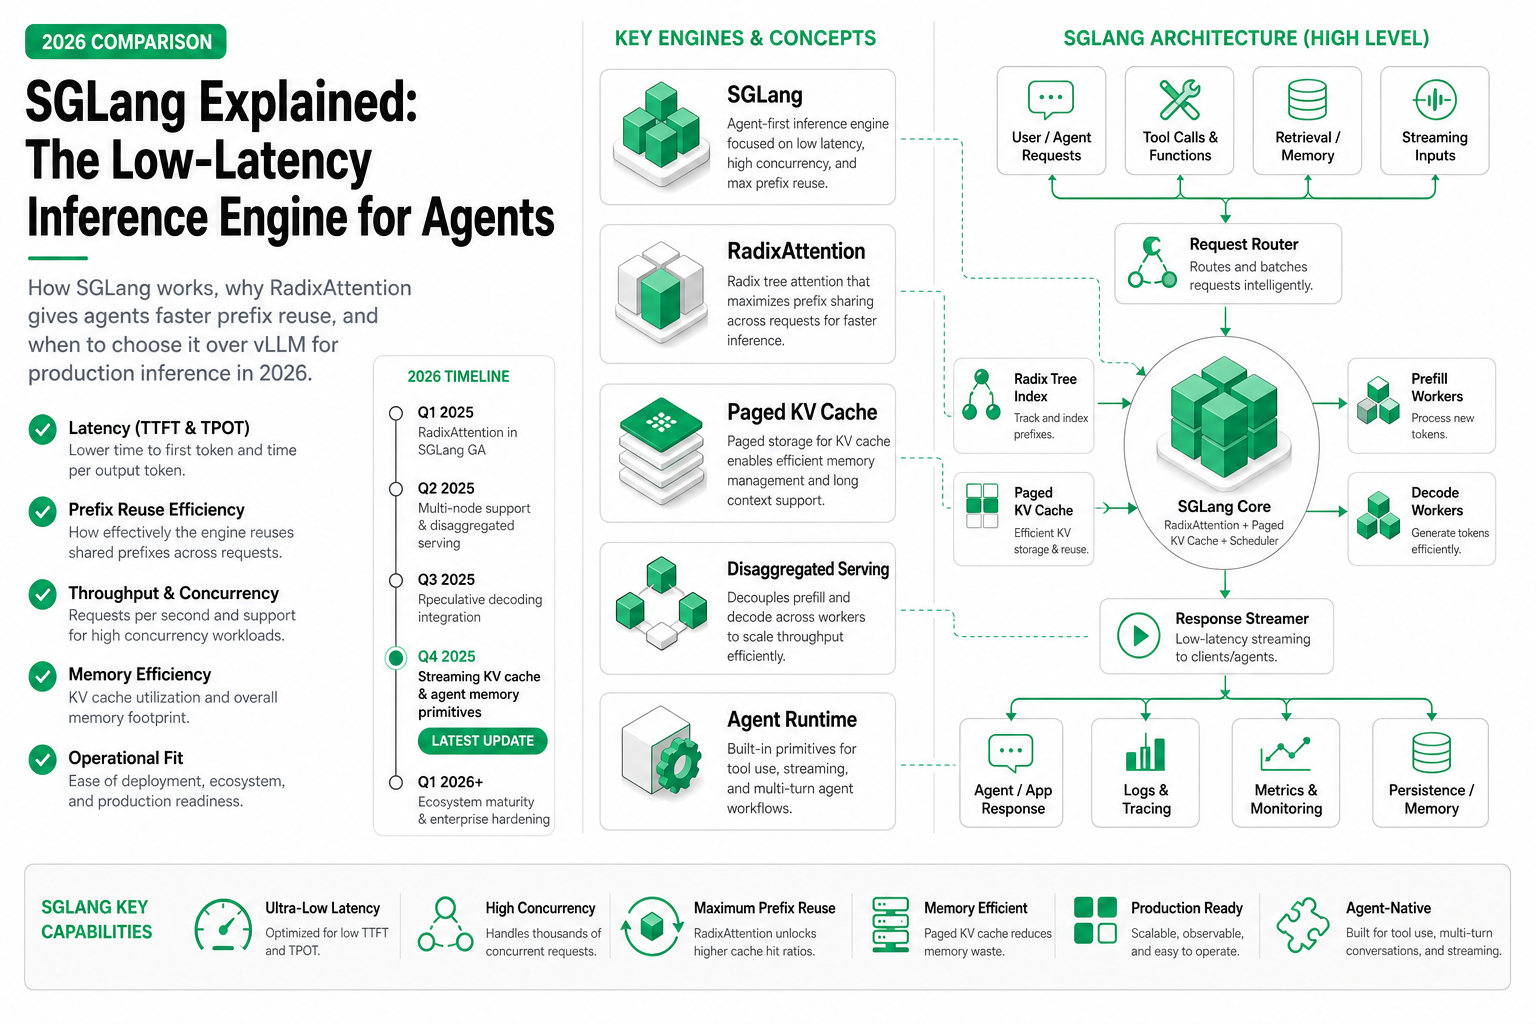
How SGLang works, why RadixAttention gives agents faster prefix reuse, and when to choose it over vLLM for production inference in 2026.