openPangu-2.0-Pro: Huawei's 505B Ascend-Native LLM
Huawei releases openPangu-2.0-Pro — a 505B parameter open-weight MoE model trained entirely on Ascend 910B NPUs. Architecture breakdown, hardware sovereignty implications, and honest assessment.
Huawei releases openPangu-2.0-Pro — a 505B parameter open-weight MoE model trained entirely on Ascend 910B NPUs. Architecture breakdown, hardware sovereignty implications, and honest assessment.
DeepSeek V4 Flash 0731 exits preview with 82.7 Terminal-Bench and 54.4 DeepSWE. 284B/13B MoE, 1M context, MIT license, at $0.14/$0.28 per million tokens. Agent benchmarks beat V4-Pro-Preview.
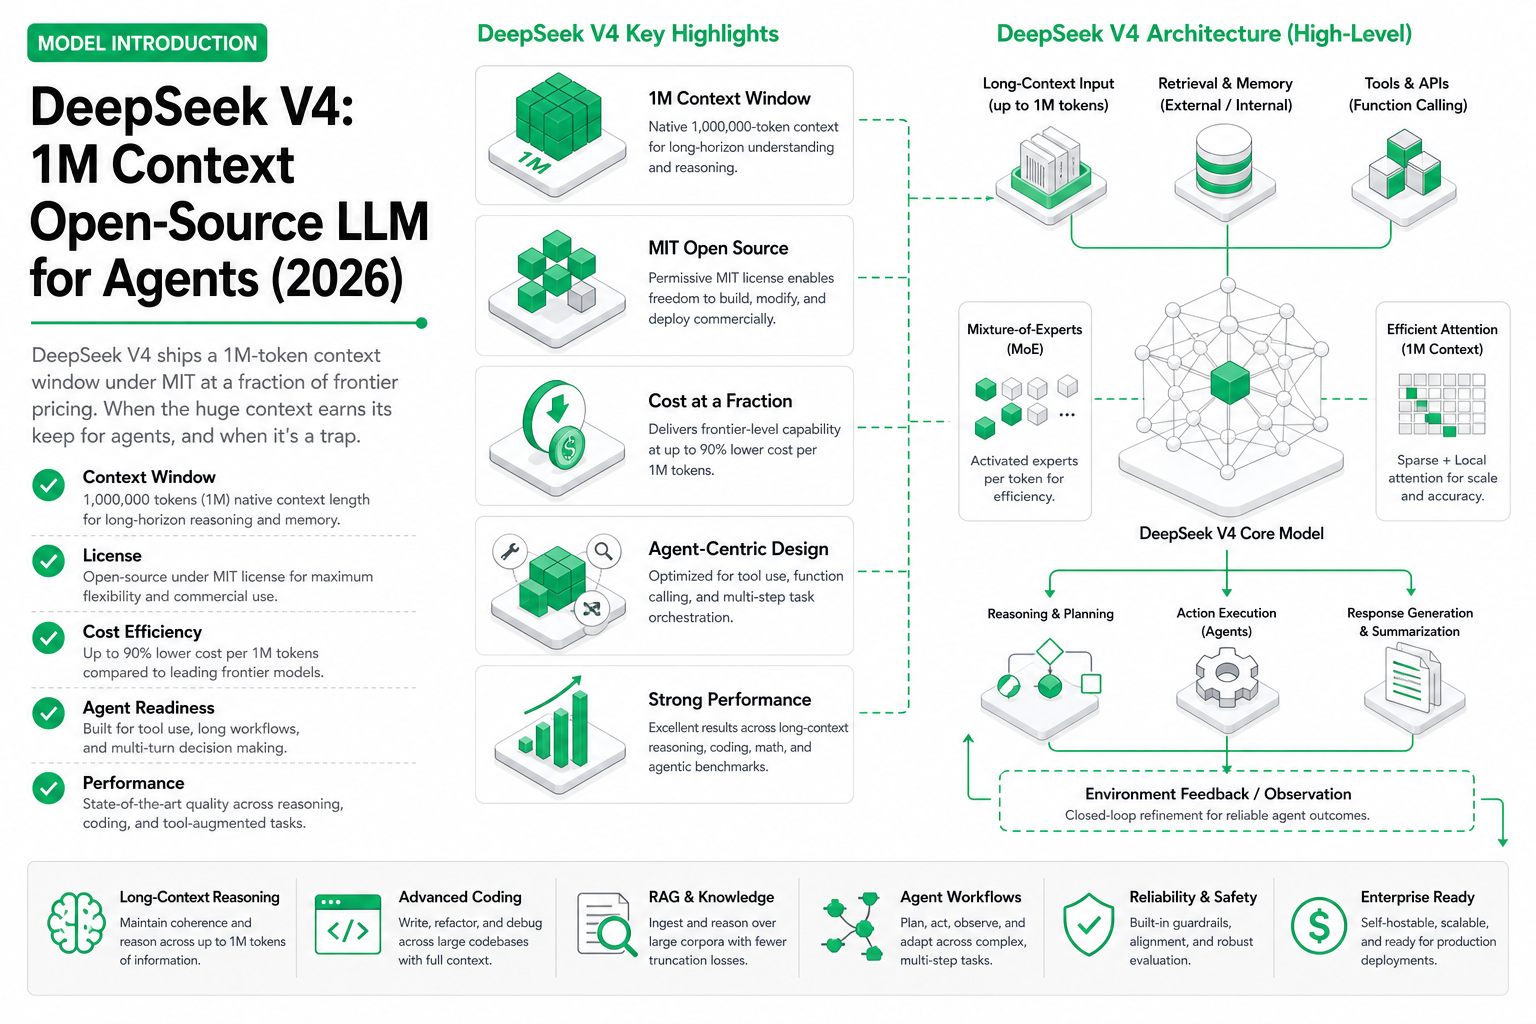
DeepSeek V4 ships a 1M-token context window under MIT at a fraction of frontier pricing. When the huge context earns its keep for agents, and when it's a trap.
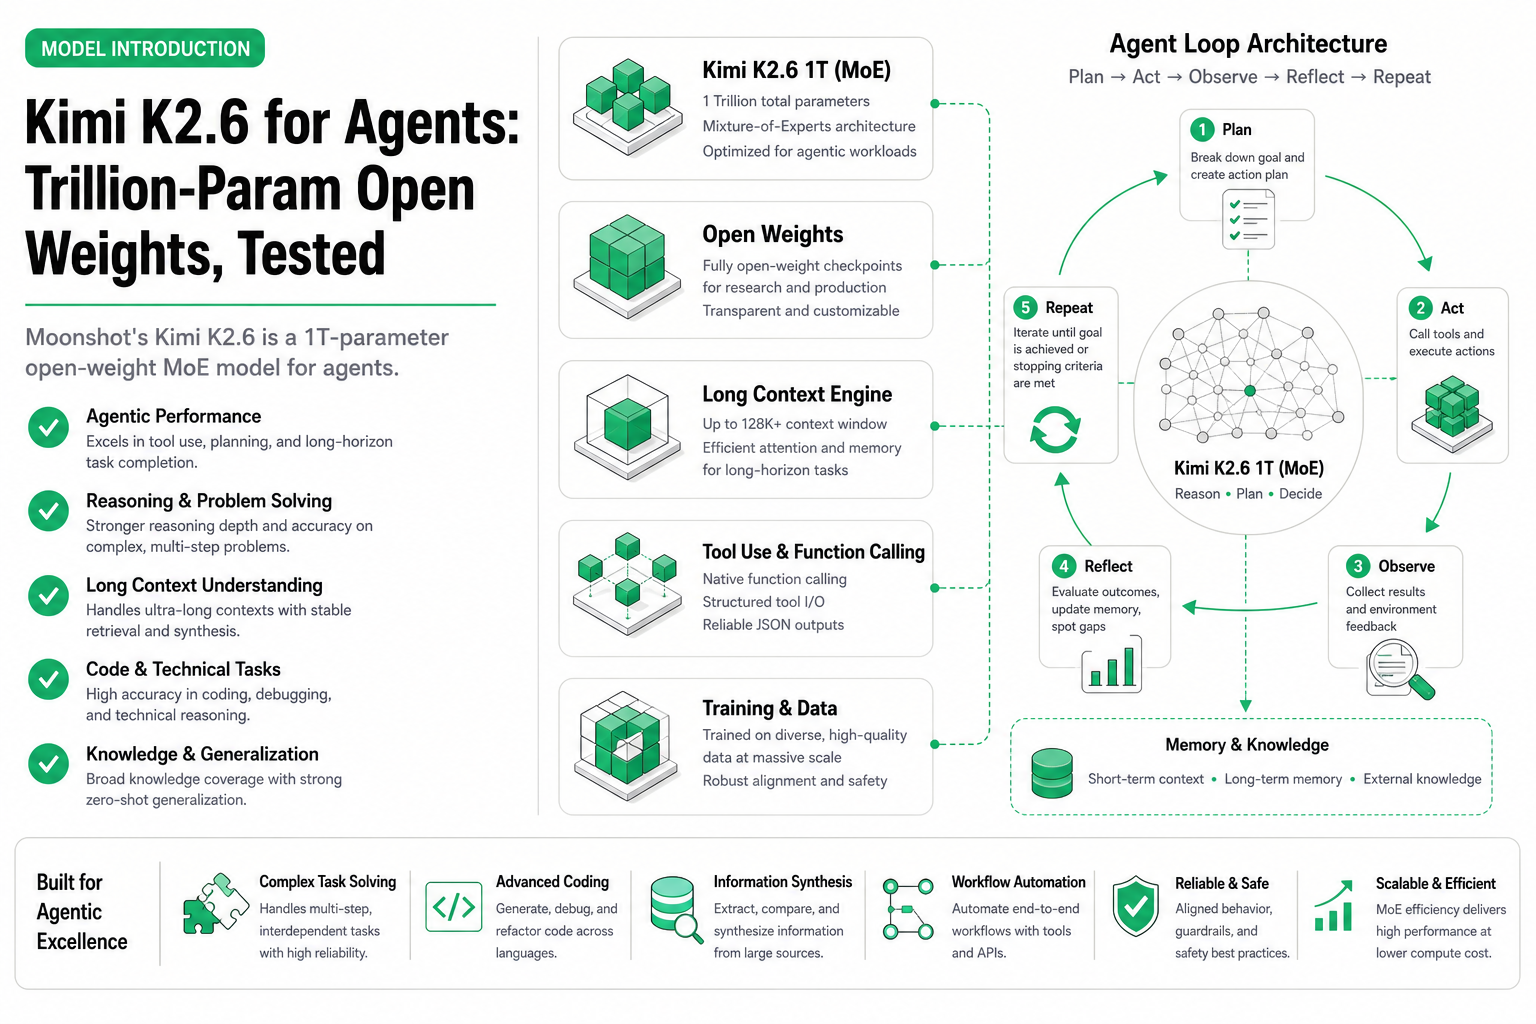
Moonshot's Kimi K2.6 is a 1T-parameter open-weight MoE model for agents. What it's good at, where the params help, and how to wire it into a loop.
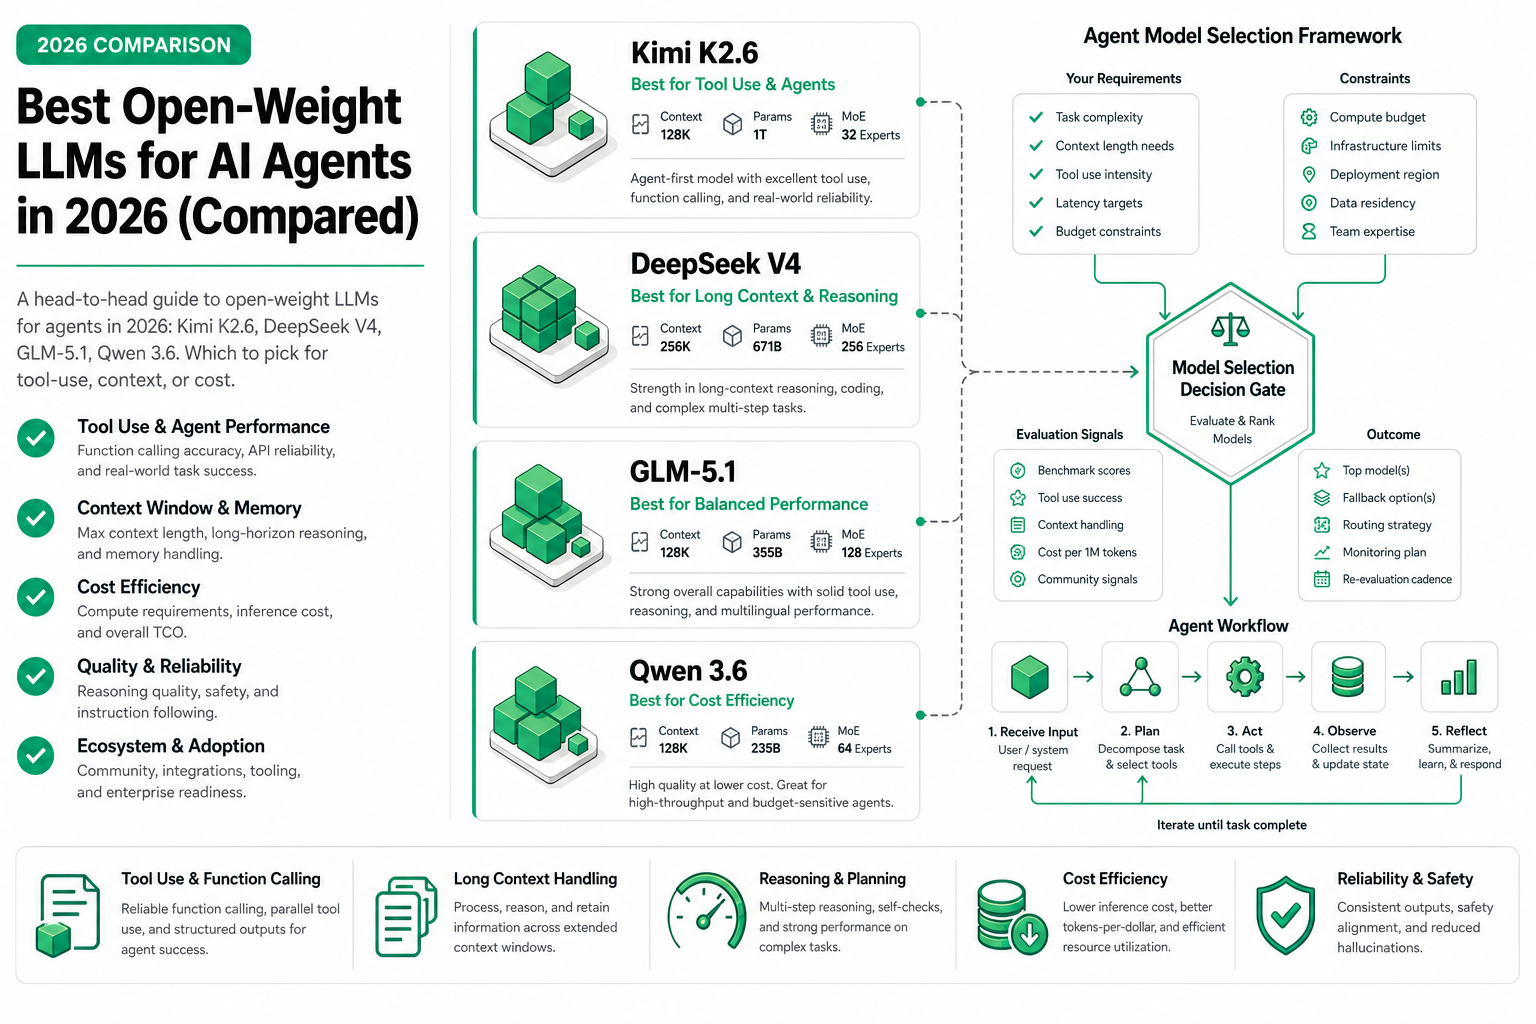
A head-to-head guide to open-weight LLMs for agents in 2026: Kimi K2.6, DeepSeek V4, GLM-5.1, Qwen 3.6. Which to pick for tool-use, context, or cost.
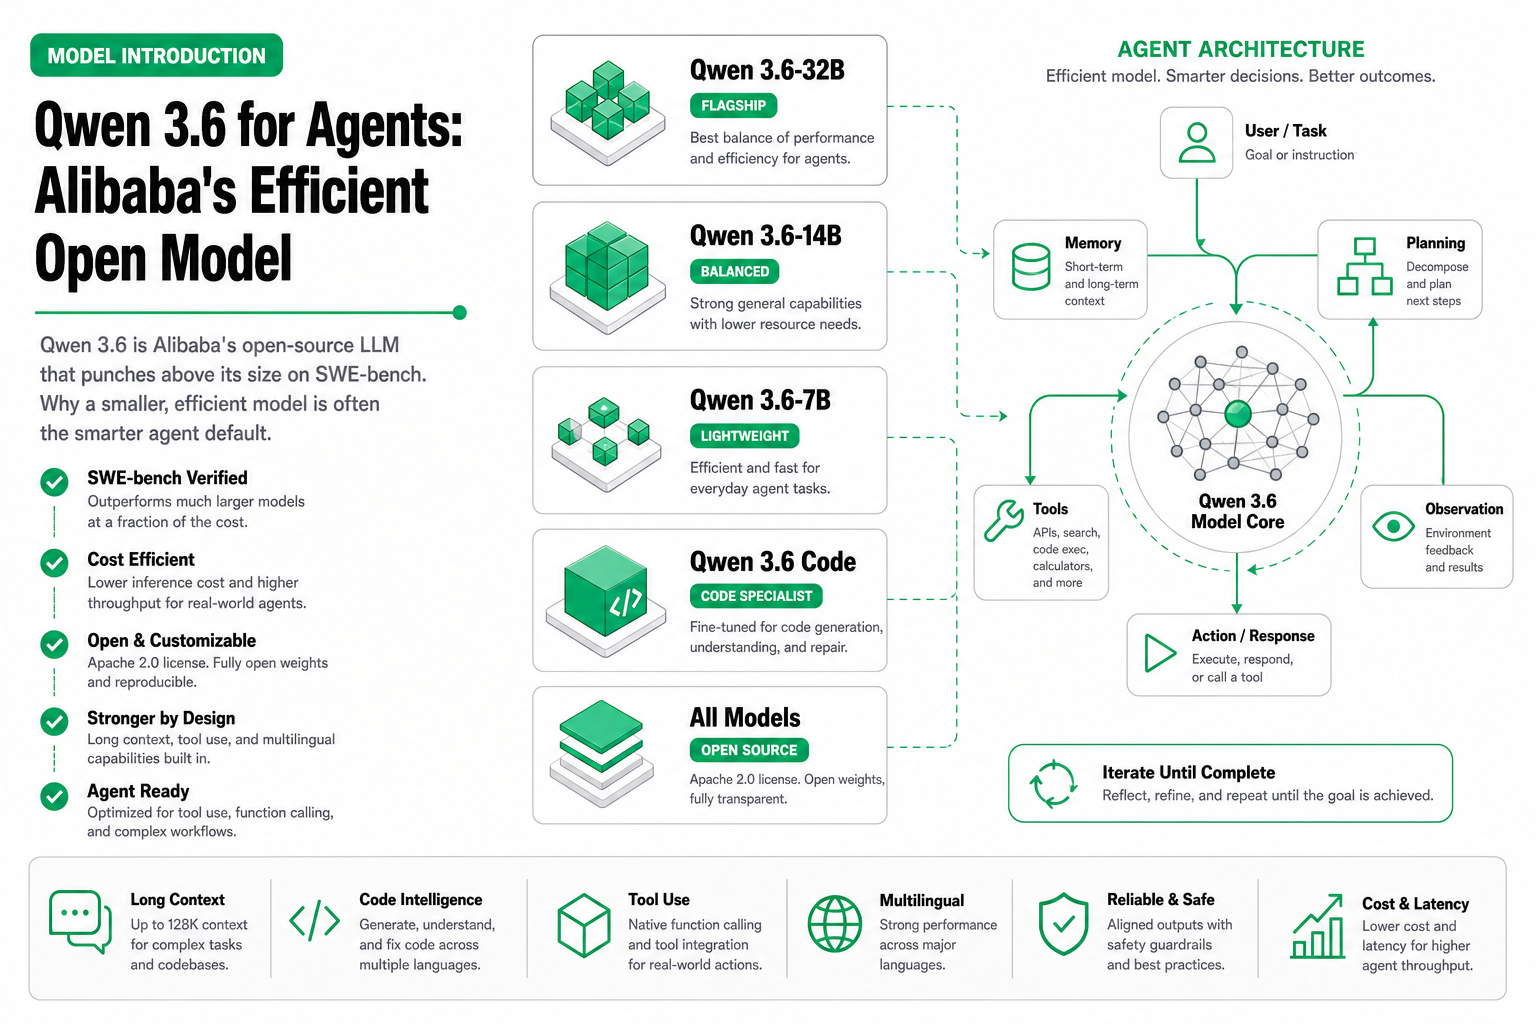
Qwen 3.6 is Alibaba's open-source LLM that punches above its size on SWE-bench. Why a smaller, efficient model is often the smarter agent default.